


Stop Hardcoding Metrics in BI Dashboards: The 4-Step Semantic Layer Checklist for Modern Data Teams
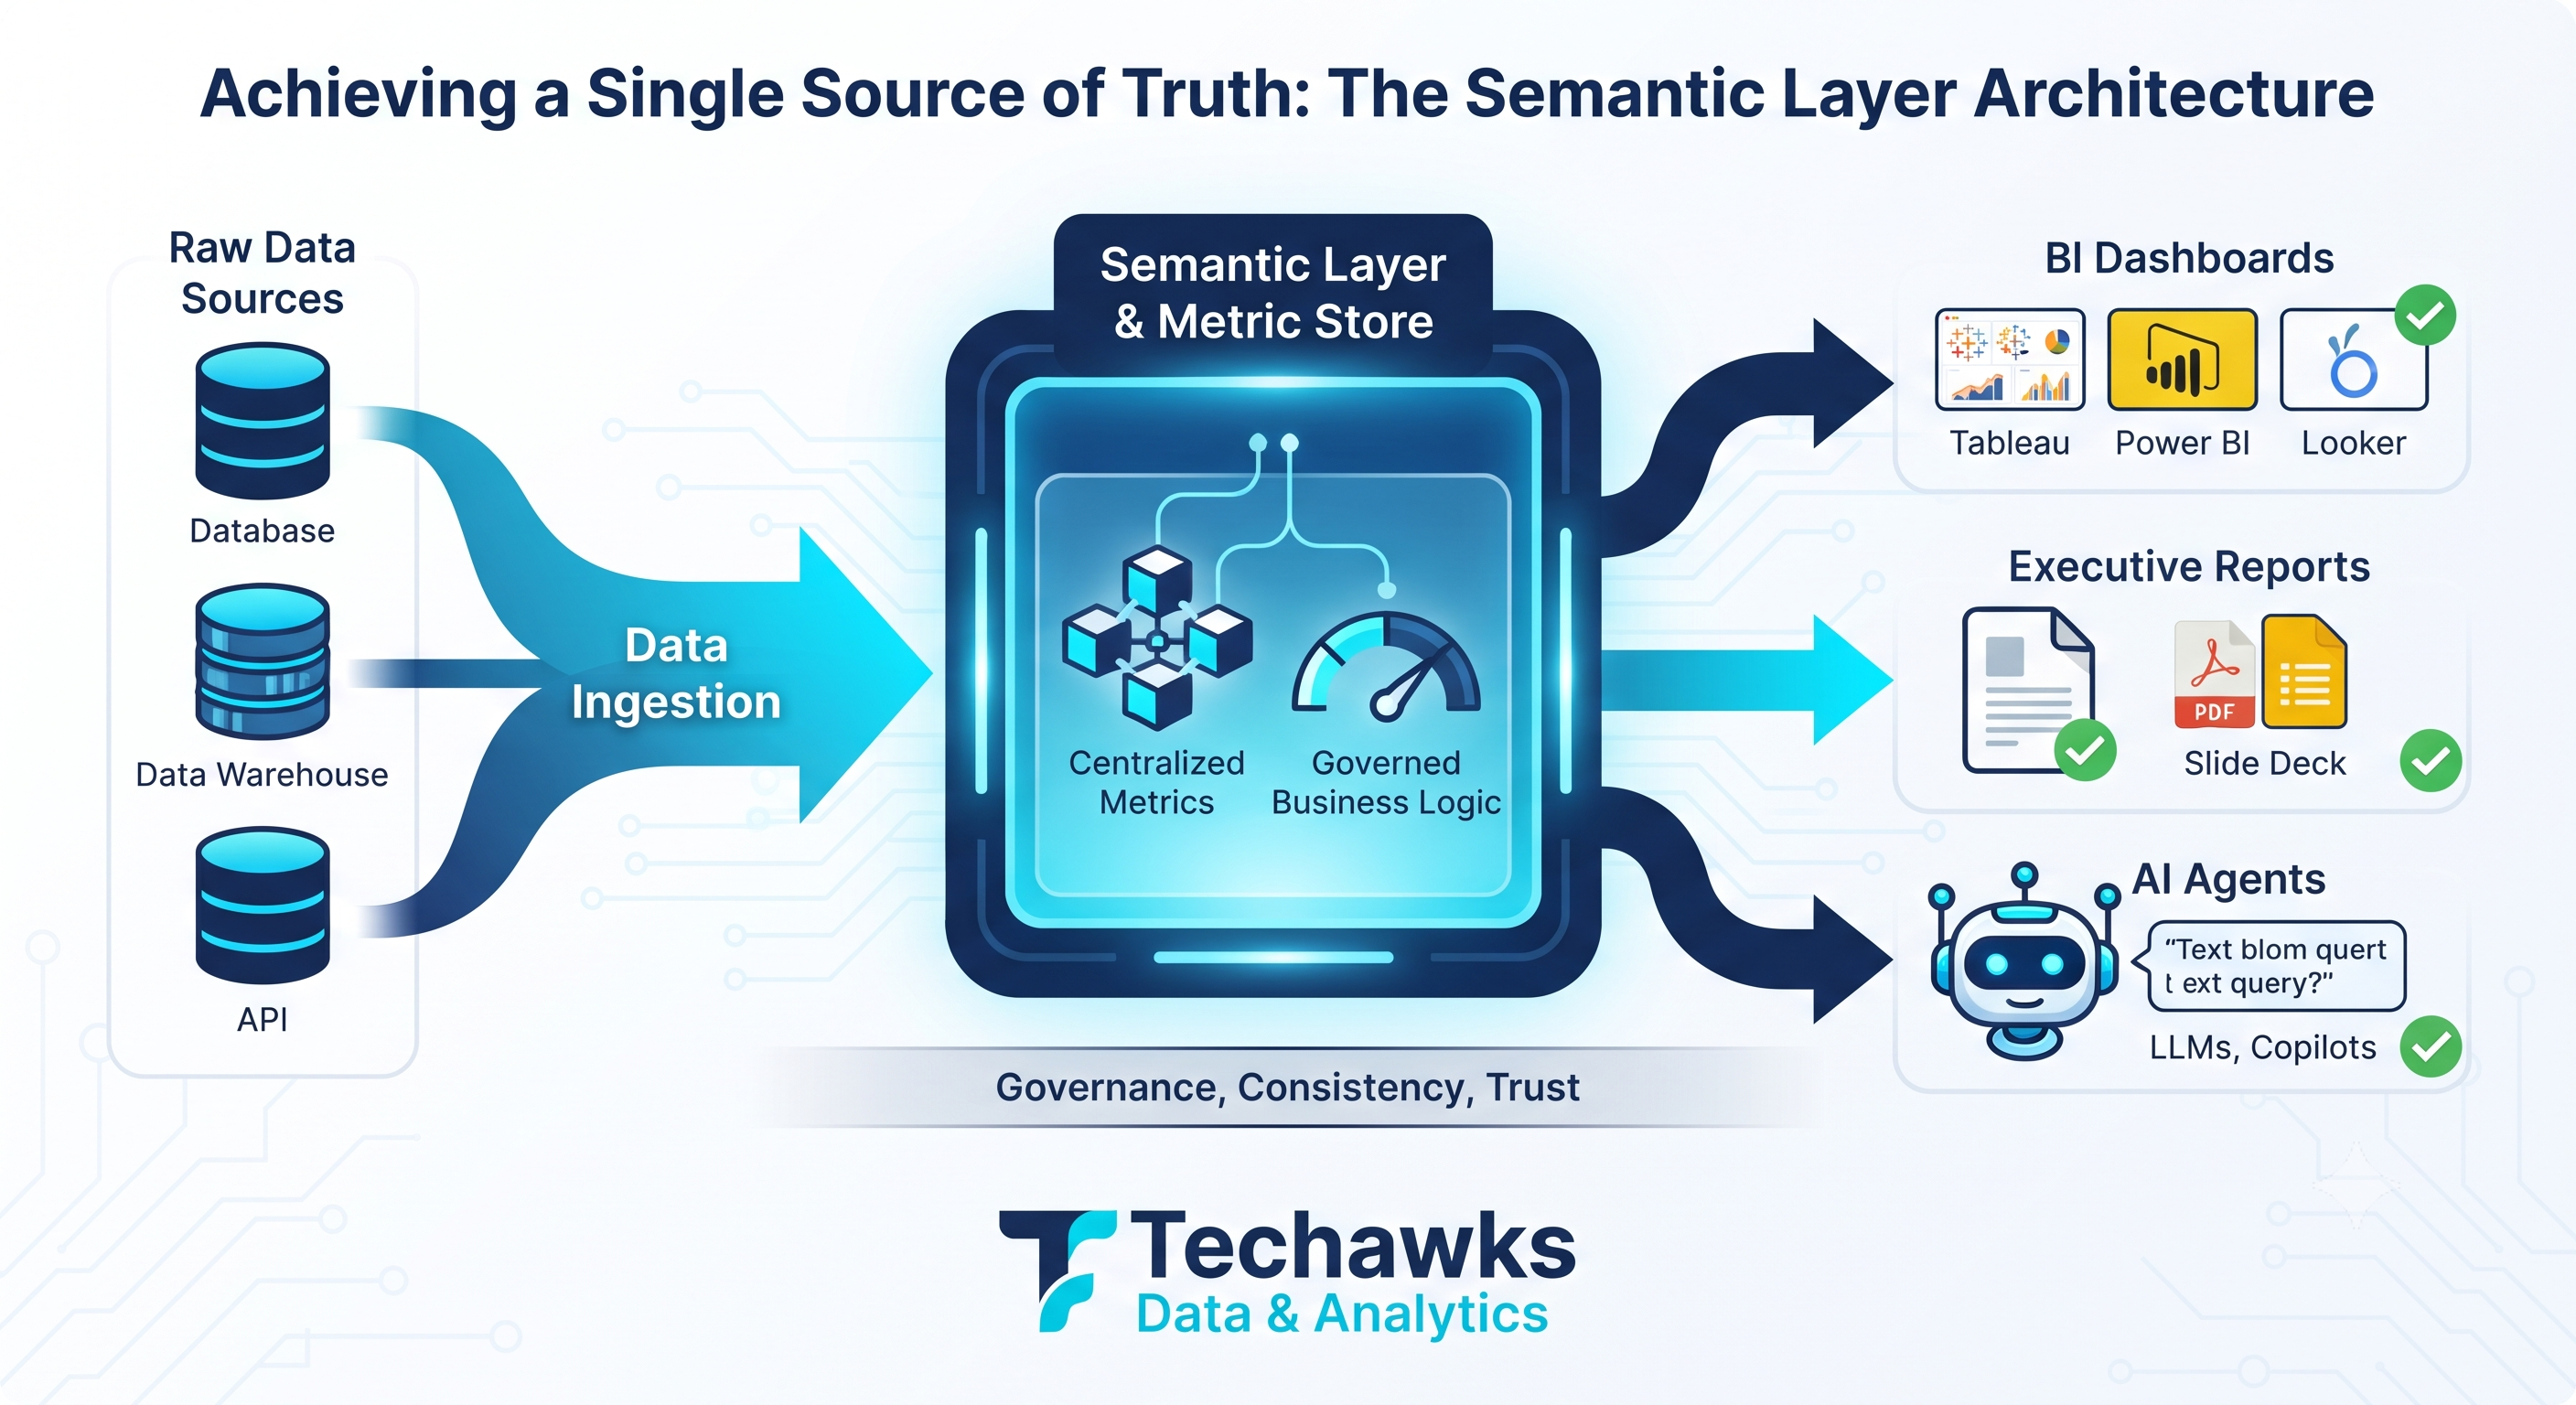
As organizations adopt multi-cloud data warehouses and generative AI agents, relying on fragmented, tool-specific metric definitions leads to widespread data drift and conflicting business logic. To establish a single source of truth, modern data teams are shifting away from siloed reporting toward centralized, version-controlled semantic layers (such as dbt Semantic Layer, Cube, or native warehouse metadata catalogs).
To eliminate metric discrepancies and build an architecture that both humans and AI applications can trust, use this actionable semantic modeling checklist:
Centralize Metric Definitions: Move business logic—like Monthly Recurring Revenue (MRR) or Churn Rate—out of individual BI workbooks and define them as code in a single, version-controlled repository.
Standardize Dimensions and Entities: Ensure consistent primary keys and dimensional joins across all datasets so that cross-functional reporting across sales, product, and finance always joins cleanly.
Incorporate Automated Data Observability: Implement continuous validation checks and data contracts to catch upstream schema changes or pipeline breaks before they corrupt downstream metrics.
Expose Governed APIs for AI Consumption: Equip your LLMs and text-to-SQL agents with a standardized semantic API so autonomous systems query approved business metrics instead of guessing raw table structures.
Discussion Question: What is your team's biggest bottleneck when standardizing metrics—disagreements across departments on what definitions mean, or technical friction when syncing the semantic layer across multiple BI tools? Drop your insights below!
CTA (Join Data Science & Analytics): Ready to build scalable, production-grade data systems? Join Data Science & Analytics to access advanced architecture breakdowns, peer discussions, and top-tier career opportunities.
As organizations adopt multi-cloud data warehouses and generative AI agents, relying on fragmented, tool-specific metric definitions leads to widespread data drift and conflicting business logic. To establish a single source of truth, modern data teams are shifting away from siloed reporting toward centralized, version-controlled semantic layers (such as dbt Semantic Layer, Cube, or native warehouse metadata catalogs).
To eliminate metric discrepancies and build an architecture that both humans and AI applications can trust, use this actionable semantic modeling checklist:
Centralize Metric Definitions: Move business logic—like Monthly Recurring Revenue (MRR) or Churn Rate—out of individual BI workbooks and define them as code in a single, version-controlled repository.
Standardize Dimensions and Entities: Ensure consistent primary keys and dimensional joins across all datasets so that cross-functional reporting across sales, product, and finance always joins cleanly.
Incorporate Automated Data Observability: Implement continuous validation checks and data contracts to catch upstream schema changes or pipeline breaks before they corrupt downstream metrics.
Expose Governed APIs for AI Consumption: Equip your LLMs and text-to-SQL agents with a standardized semantic API so autonomous systems query approved business metrics instead of guessing raw table structures.
Discussion Question: What is your team's biggest bottleneck when standardizing metrics—disagreements across departments on what definitions mean, or technical friction when syncing the semantic layer across multiple BI tools? Drop your insights below!
CTA (Join Data Science & Analytics): Ready to build scalable, production-grade data systems? Join Data Science & Analytics to access advanced architecture breakdowns, peer discussions, and top-tier career opportunities.
Stop Hardcoding Metrics in BI Dashboards: The 4-Step Semantic Layer Checklist for Modern Data Teams
As organizations adopt multi-cloud data warehouses and generative AI agents, relying on fragmented, tool-specific metric definitions leads to widespread data drift and conflicting business logic. To establish a single source of truth, modern data teams are shifting away from siloed reporting toward centralized, version-controlled semantic layers (such as dbt Semantic Layer, Cube, or native warehouse metadata catalogs).
To eliminate metric discrepancies and build an architecture that both humans and AI applications can trust, use this actionable semantic modeling checklist:
Centralize Metric Definitions: Move business logic—like Monthly Recurring Revenue (MRR) or Churn Rate—out of individual BI workbooks and define them as code in a single, version-controlled repository.
Standardize Dimensions and Entities: Ensure consistent primary keys and dimensional joins across all datasets so that cross-functional reporting across sales, product, and finance always joins cleanly.
Incorporate Automated Data Observability: Implement continuous validation checks and data contracts to catch upstream schema changes or pipeline breaks before they corrupt downstream metrics.
Expose Governed APIs for AI Consumption: Equip your LLMs and text-to-SQL agents with a standardized semantic API so autonomous systems query approved business metrics instead of guessing raw table structures.
Discussion Question: What is your team's biggest bottleneck when standardizing metrics—disagreements across departments on what definitions mean, or technical friction when syncing the semantic layer across multiple BI tools? Drop your insights below!
CTA (Join Data Science & Analytics): Ready to build scalable, production-grade data systems? Join Data Science & Analytics to access advanced architecture breakdowns, peer discussions, and top-tier career opportunities.

 English
 Arabic
 French
 Spanish
 Portuguese
 Deutsch
 Turkish
 Dutch
 Russian
 Romaian
 Portuguese (Brazil)
 Greek