The Production RAG Engineering Checklist: 5 Crucial Guardrails for Context Retrieval and Accuracy
As AI builders scaling production systems quickly discover, naive vector search isn't enough to guarantee deterministic, enterprise-grade accuracy. If your RAG pipeline is spitting out irrelevant answers or missing nuanced user intent, it's time to audit your workflow.
Optimize and bulletproof your retrieval pipeline with this production engineering checklist:
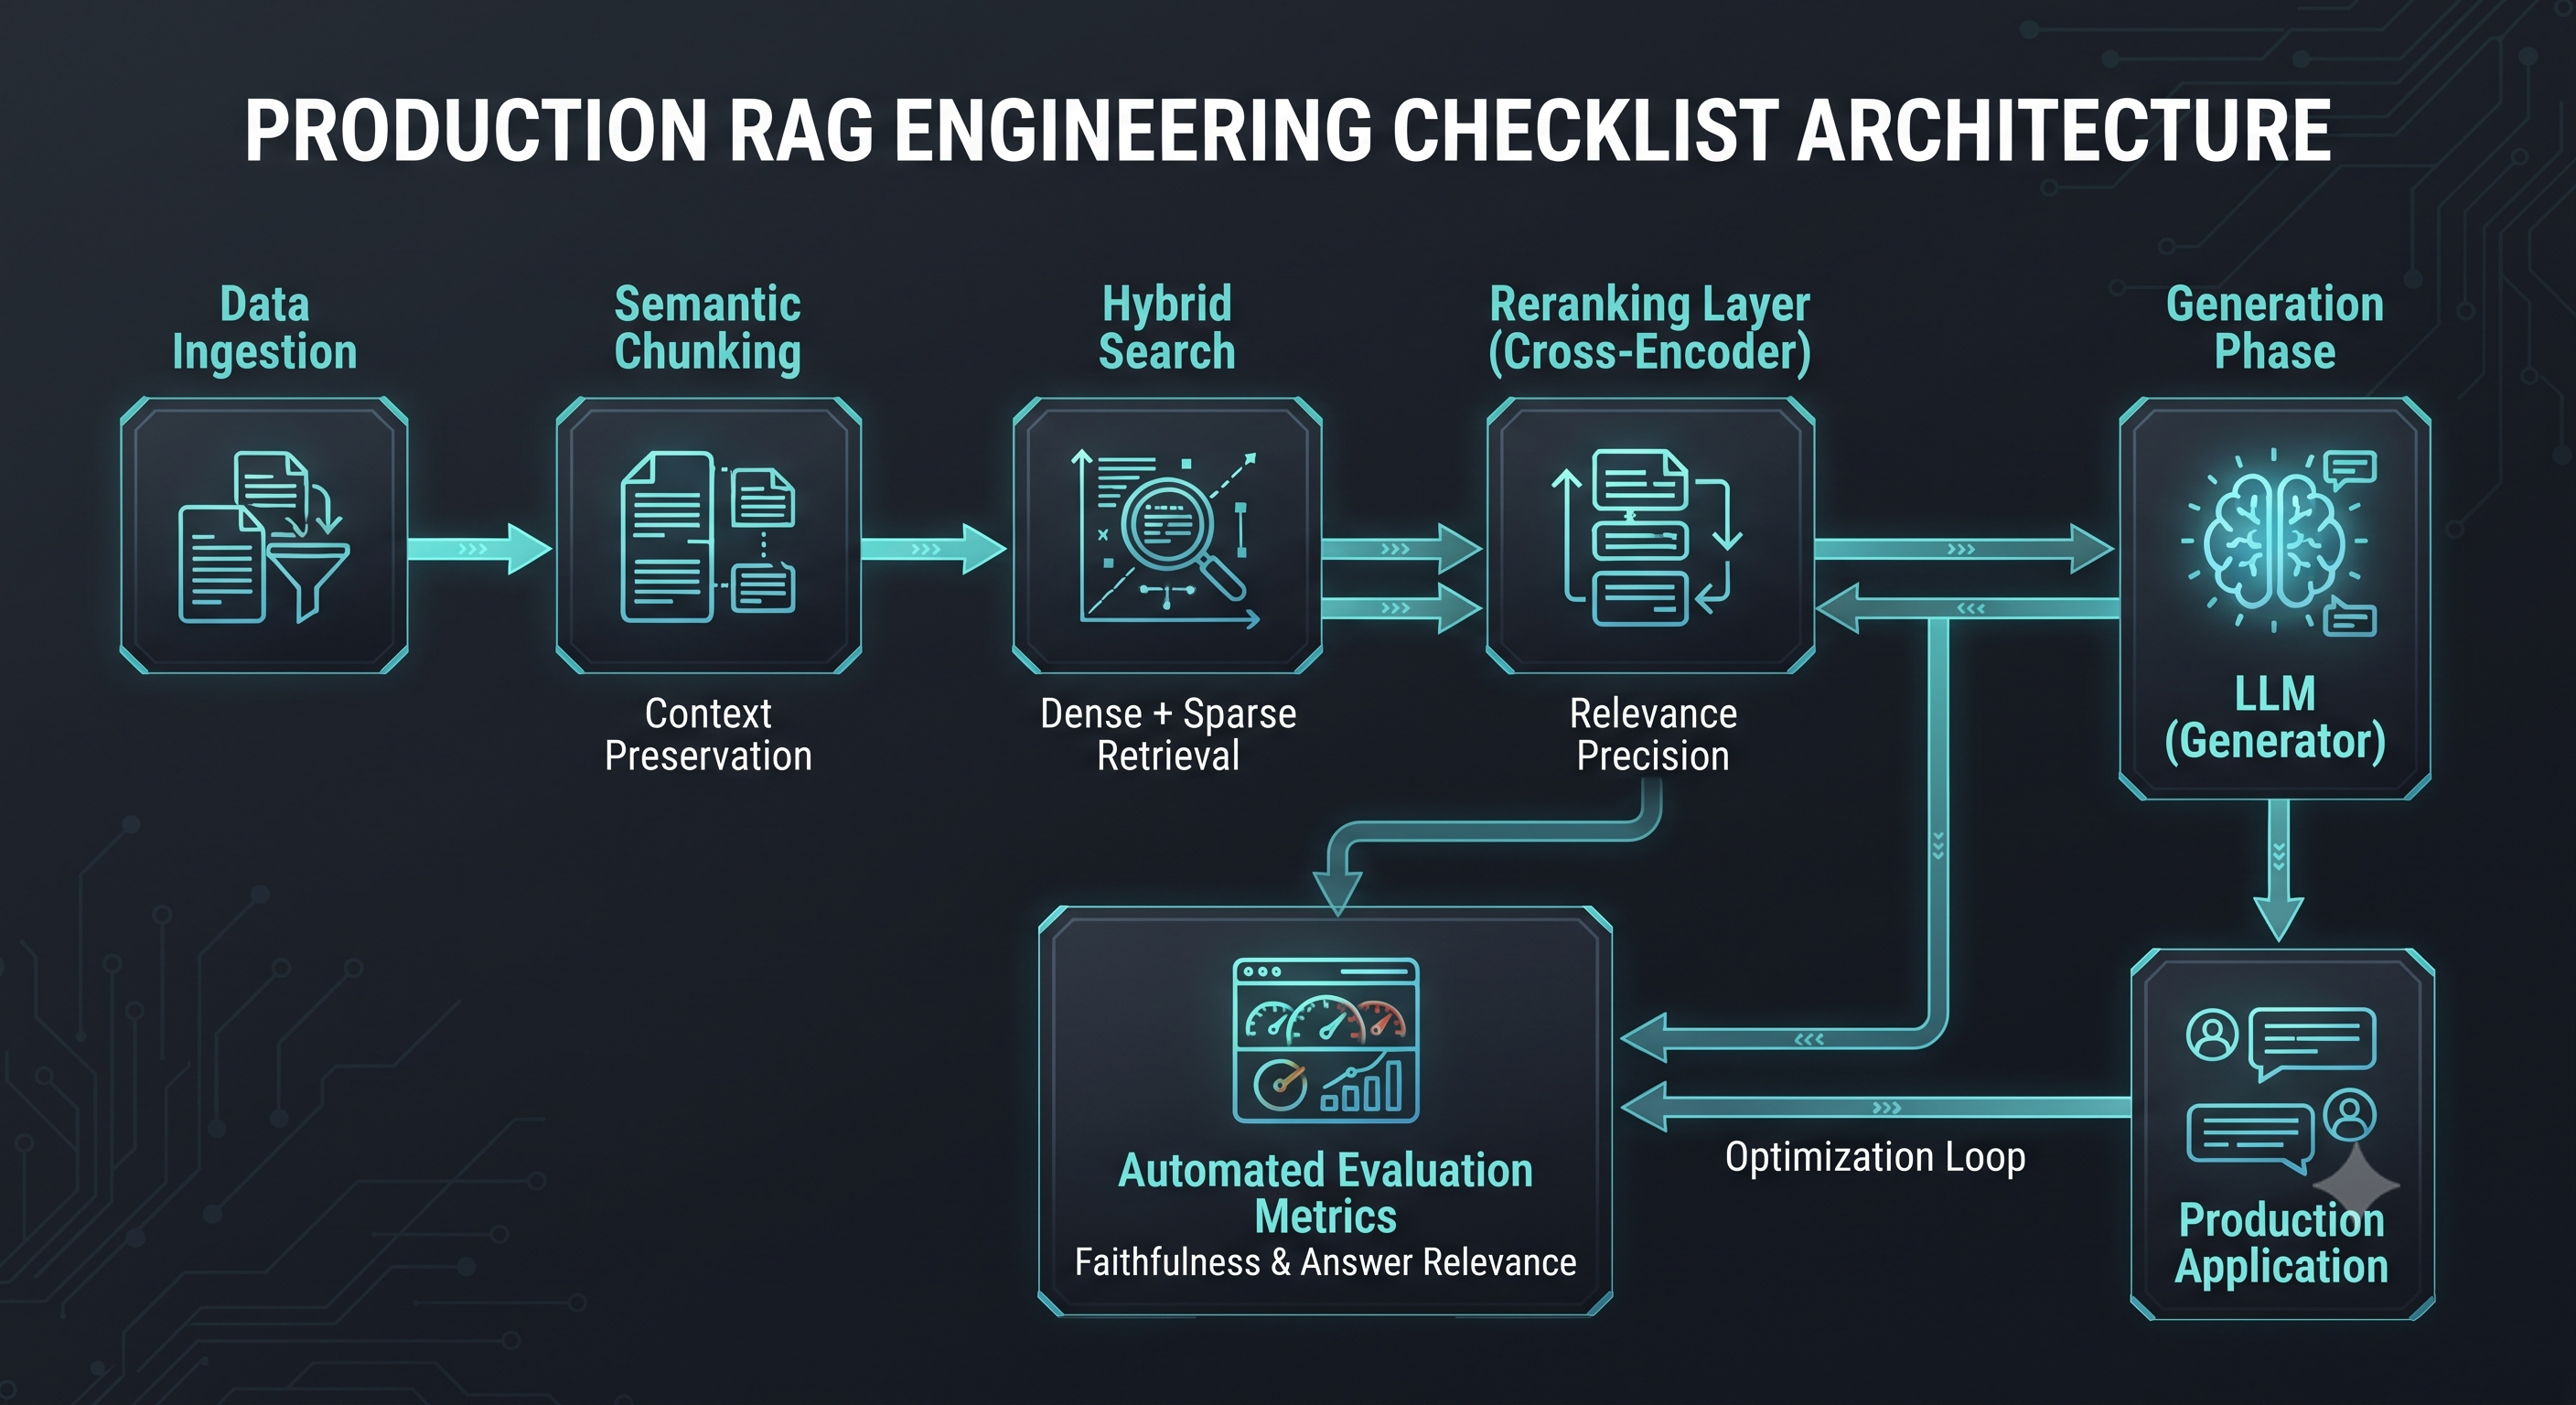
[ ] Hybrid Search Integration: Combine dense vector embeddings with sparse keyword search (BM25) to ensure semantic depth doesn't compromise exact keyword and ID matching.
[ ] Reranking Layers (Cross-Encoders): Implement a reranker (like Cohere Rerank or BGE-Reranker) to evaluate top-k initial retrieval results and pass only the highest-precision chunks to the generator.
[ ] Semantic Chunking Strategies: Move away from fixed-token splitting; use semantic chunking to keep logical paragraphs, code blocks, and markdown headers intact.
[ ] Dynamic Context Window Management: Set strict token budget caps and token pruning logic to prevent prompt dilution and control API inference costs.
[ ] Automated Hallucination Evaluation: Integrate automated evaluation frameworks (like RAGAS or TruLens) into your CI/CD pipeline to continuously measure faithfulness, answer relevance, and context precision.
Why It Matters
Users don't care how sleek your vector database is; they care if the AI gives the correct, verifiable answer. Implementing these architectural layers transforms a brittle prototype into a robust production system that scales reliably under heavy real-world traffic.
Discussion Question
What is your go-to strategy for tackling latency bottlenecks when adding a cross-encoder reranking step to a high-throughput RAG pipeline? Let’s share notes below! 👇
CTA (Join AI Builders & Enthusiasts)
Ready to build better AI systems? Join the AI Builders & Enthusiasts community to connect with fellow developers, share production patterns, and master modern AI engineering.
The Production RAG Engineering Checklist: 5 Crucial Guardrails for Context Retrieval and Accuracy
As AI builders scaling production systems quickly discover, naive vector search isn't enough to guarantee deterministic, enterprise-grade accuracy. If your RAG pipeline is spitting out irrelevant answers or missing nuanced user intent, it's time to audit your workflow.
Optimize and bulletproof your retrieval pipeline with this production engineering checklist:
[ ] Hybrid Search Integration: Combine dense vector embeddings with sparse keyword search (BM25) to ensure semantic depth doesn't compromise exact keyword and ID matching.
[ ] Reranking Layers (Cross-Encoders): Implement a reranker (like Cohere Rerank or BGE-Reranker) to evaluate top-k initial retrieval results and pass only the highest-precision chunks to the generator.
[ ] Semantic Chunking Strategies: Move away from fixed-token splitting; use semantic chunking to keep logical paragraphs, code blocks, and markdown headers intact.
[ ] Dynamic Context Window Management: Set strict token budget caps and token pruning logic to prevent prompt dilution and control API inference costs.
[ ] Automated Hallucination Evaluation: Integrate automated evaluation frameworks (like RAGAS or TruLens) into your CI/CD pipeline to continuously measure faithfulness, answer relevance, and context precision.
Why It Matters
Users don't care how sleek your vector database is; they care if the AI gives the correct, verifiable answer. Implementing these architectural layers transforms a brittle prototype into a robust production system that scales reliably under heavy real-world traffic.
Discussion Question
What is your go-to strategy for tackling latency bottlenecks when adding a cross-encoder reranking step to a high-throughput RAG pipeline? Let’s share notes below! 👇
CTA (Join AI Builders & Enthusiasts)
Ready to build better AI systems? Join the AI Builders & Enthusiasts community to connect with fellow developers, share production patterns, and master modern AI engineering.

 English
 Arabic
 French
 Spanish
 Portuguese
 Deutsch
 Turkish
 Dutch
 Italiano
 Russian
 Portuguese (Brazil)
 Greek