


-
Myth vs. Fact: “Because Federal AI Legislation Stalled, Canadian AI Products Don’t Require Automated Decision Guardrails”
A common architectural fallacy inside Canadian tech hubs—from the Waterloo-Toronto corridor to Vancouver and Montreal—is that Canada remains a relaxed regulatory sandbox for automated systems while federal bills get debated.
Engineering leads keep confusing legislative delay on Parliament Hill with an absence of binding law.
Here is the production reality:
❌ The Myth:
“Since Bill C-27 and AIDA died on the order paper and federal privacy overhauls are still making their way through committee, we don't need automated decision-making (ADM) transparency or explainability hooks in production.”
✅ The Reality:
Canada already has an active, GDPR-grade enforcement regime with statutory teeth: Quebec’s Law 25. It has no minimum size threshold, applies extraterritorially across Canada if you process data from a single Quebec resident, and enforces strict algorithmic transparency.
If your microservices or predictive ML models make decisions that directly impact users (e.g., credit approvals, hiring screening, dynamic pricing, or risk tiering), relying on black-box inference triggers clear operational failures:
Mandatory Point-of-Decision Notice
Under Law 25, you cannot bury AI usage in a generic privacy policy. The moment an automated process makes a decision without human intervention, the system must explicitly inform the user no later than when the decision is communicated.
The "Right to Factor Explainability" Endpoint
Individuals have a statutory right to request:
The specific personal data points consumed by the model.
The primary parameters, weights, and factors that generated the decision.
A direct mechanism to rectify incorrect source data.
If your architecture treats inference as a one-way POST request without persisting the deterministic feature vector and SHAP/attribution weights, fulfilling this audit request within statutory timelines is nearly impossible.
Statutory Human-in-the-Loop Remediation
Compliance requires giving users the ability to submit observations and request a manual review by an authorized team member who can overturn the decision. With Commission d'accès à l'information (CAI) penalities scaling up to $25 million CAD or 4% of worldwide turnover, along with a statutory private right of action, algorithmic unaccountability carries immediate financial risk.
The Production Blueprint for Canadian Tech:
Decouple your feature extraction pipeline and log the exact input snapshot into an auditable telemetry store alongside the model version.
Build an asynchronous explainability worker that computes feature importance at inference time, ready to serve transparent plain-text rationales.
Provide an automated escalation queue routing contested decisions directly to internal human operators.
Discussion Question
How is your team handling automated decision logging: Are you instrumenting feature importance and explainability traces directly into your inference pipelines, or relying on ad-hoc post-mortems?
CTA (Join Techawks Canada)
Build robust, legally sound engineering systems that scale across provincial and international borders. Join Techawks Canada to connect with technical architects, software engineers, and engineering leaders building production-grade software across Canada.Myth vs. Fact: “Because Federal AI Legislation Stalled, Canadian AI Products Don’t Require Automated Decision Guardrails” A common architectural fallacy inside Canadian tech hubs—from the Waterloo-Toronto corridor to Vancouver and Montreal—is that Canada remains a relaxed regulatory sandbox for automated systems while federal bills get debated. Engineering leads keep confusing legislative delay on Parliament Hill with an absence of binding law. Here is the production reality: ❌ The Myth: “Since Bill C-27 and AIDA died on the order paper and federal privacy overhauls are still making their way through committee, we don't need automated decision-making (ADM) transparency or explainability hooks in production.” ✅ The Reality: Canada already has an active, GDPR-grade enforcement regime with statutory teeth: Quebec’s Law 25. It has no minimum size threshold, applies extraterritorially across Canada if you process data from a single Quebec resident, and enforces strict algorithmic transparency. If your microservices or predictive ML models make decisions that directly impact users (e.g., credit approvals, hiring screening, dynamic pricing, or risk tiering), relying on black-box inference triggers clear operational failures: Mandatory Point-of-Decision Notice Under Law 25, you cannot bury AI usage in a generic privacy policy. The moment an automated process makes a decision without human intervention, the system must explicitly inform the user no later than when the decision is communicated. The "Right to Factor Explainability" Endpoint Individuals have a statutory right to request: The specific personal data points consumed by the model. The primary parameters, weights, and factors that generated the decision. A direct mechanism to rectify incorrect source data. If your architecture treats inference as a one-way POST request without persisting the deterministic feature vector and SHAP/attribution weights, fulfilling this audit request within statutory timelines is nearly impossible. Statutory Human-in-the-Loop Remediation Compliance requires giving users the ability to submit observations and request a manual review by an authorized team member who can overturn the decision. With Commission d'accès à l'information (CAI) penalities scaling up to $25 million CAD or 4% of worldwide turnover, along with a statutory private right of action, algorithmic unaccountability carries immediate financial risk. The Production Blueprint for Canadian Tech: Decouple your feature extraction pipeline and log the exact input snapshot into an auditable telemetry store alongside the model version. Build an asynchronous explainability worker that computes feature importance at inference time, ready to serve transparent plain-text rationales. Provide an automated escalation queue routing contested decisions directly to internal human operators. Discussion Question How is your team handling automated decision logging: Are you instrumenting feature importance and explainability traces directly into your inference pipelines, or relying on ad-hoc post-mortems? CTA (Join Techawks Canada) Build robust, legally sound engineering systems that scale across provincial and international borders. Join Techawks Canada to connect with technical architects, software engineers, and engineering leaders building production-grade software across Canada.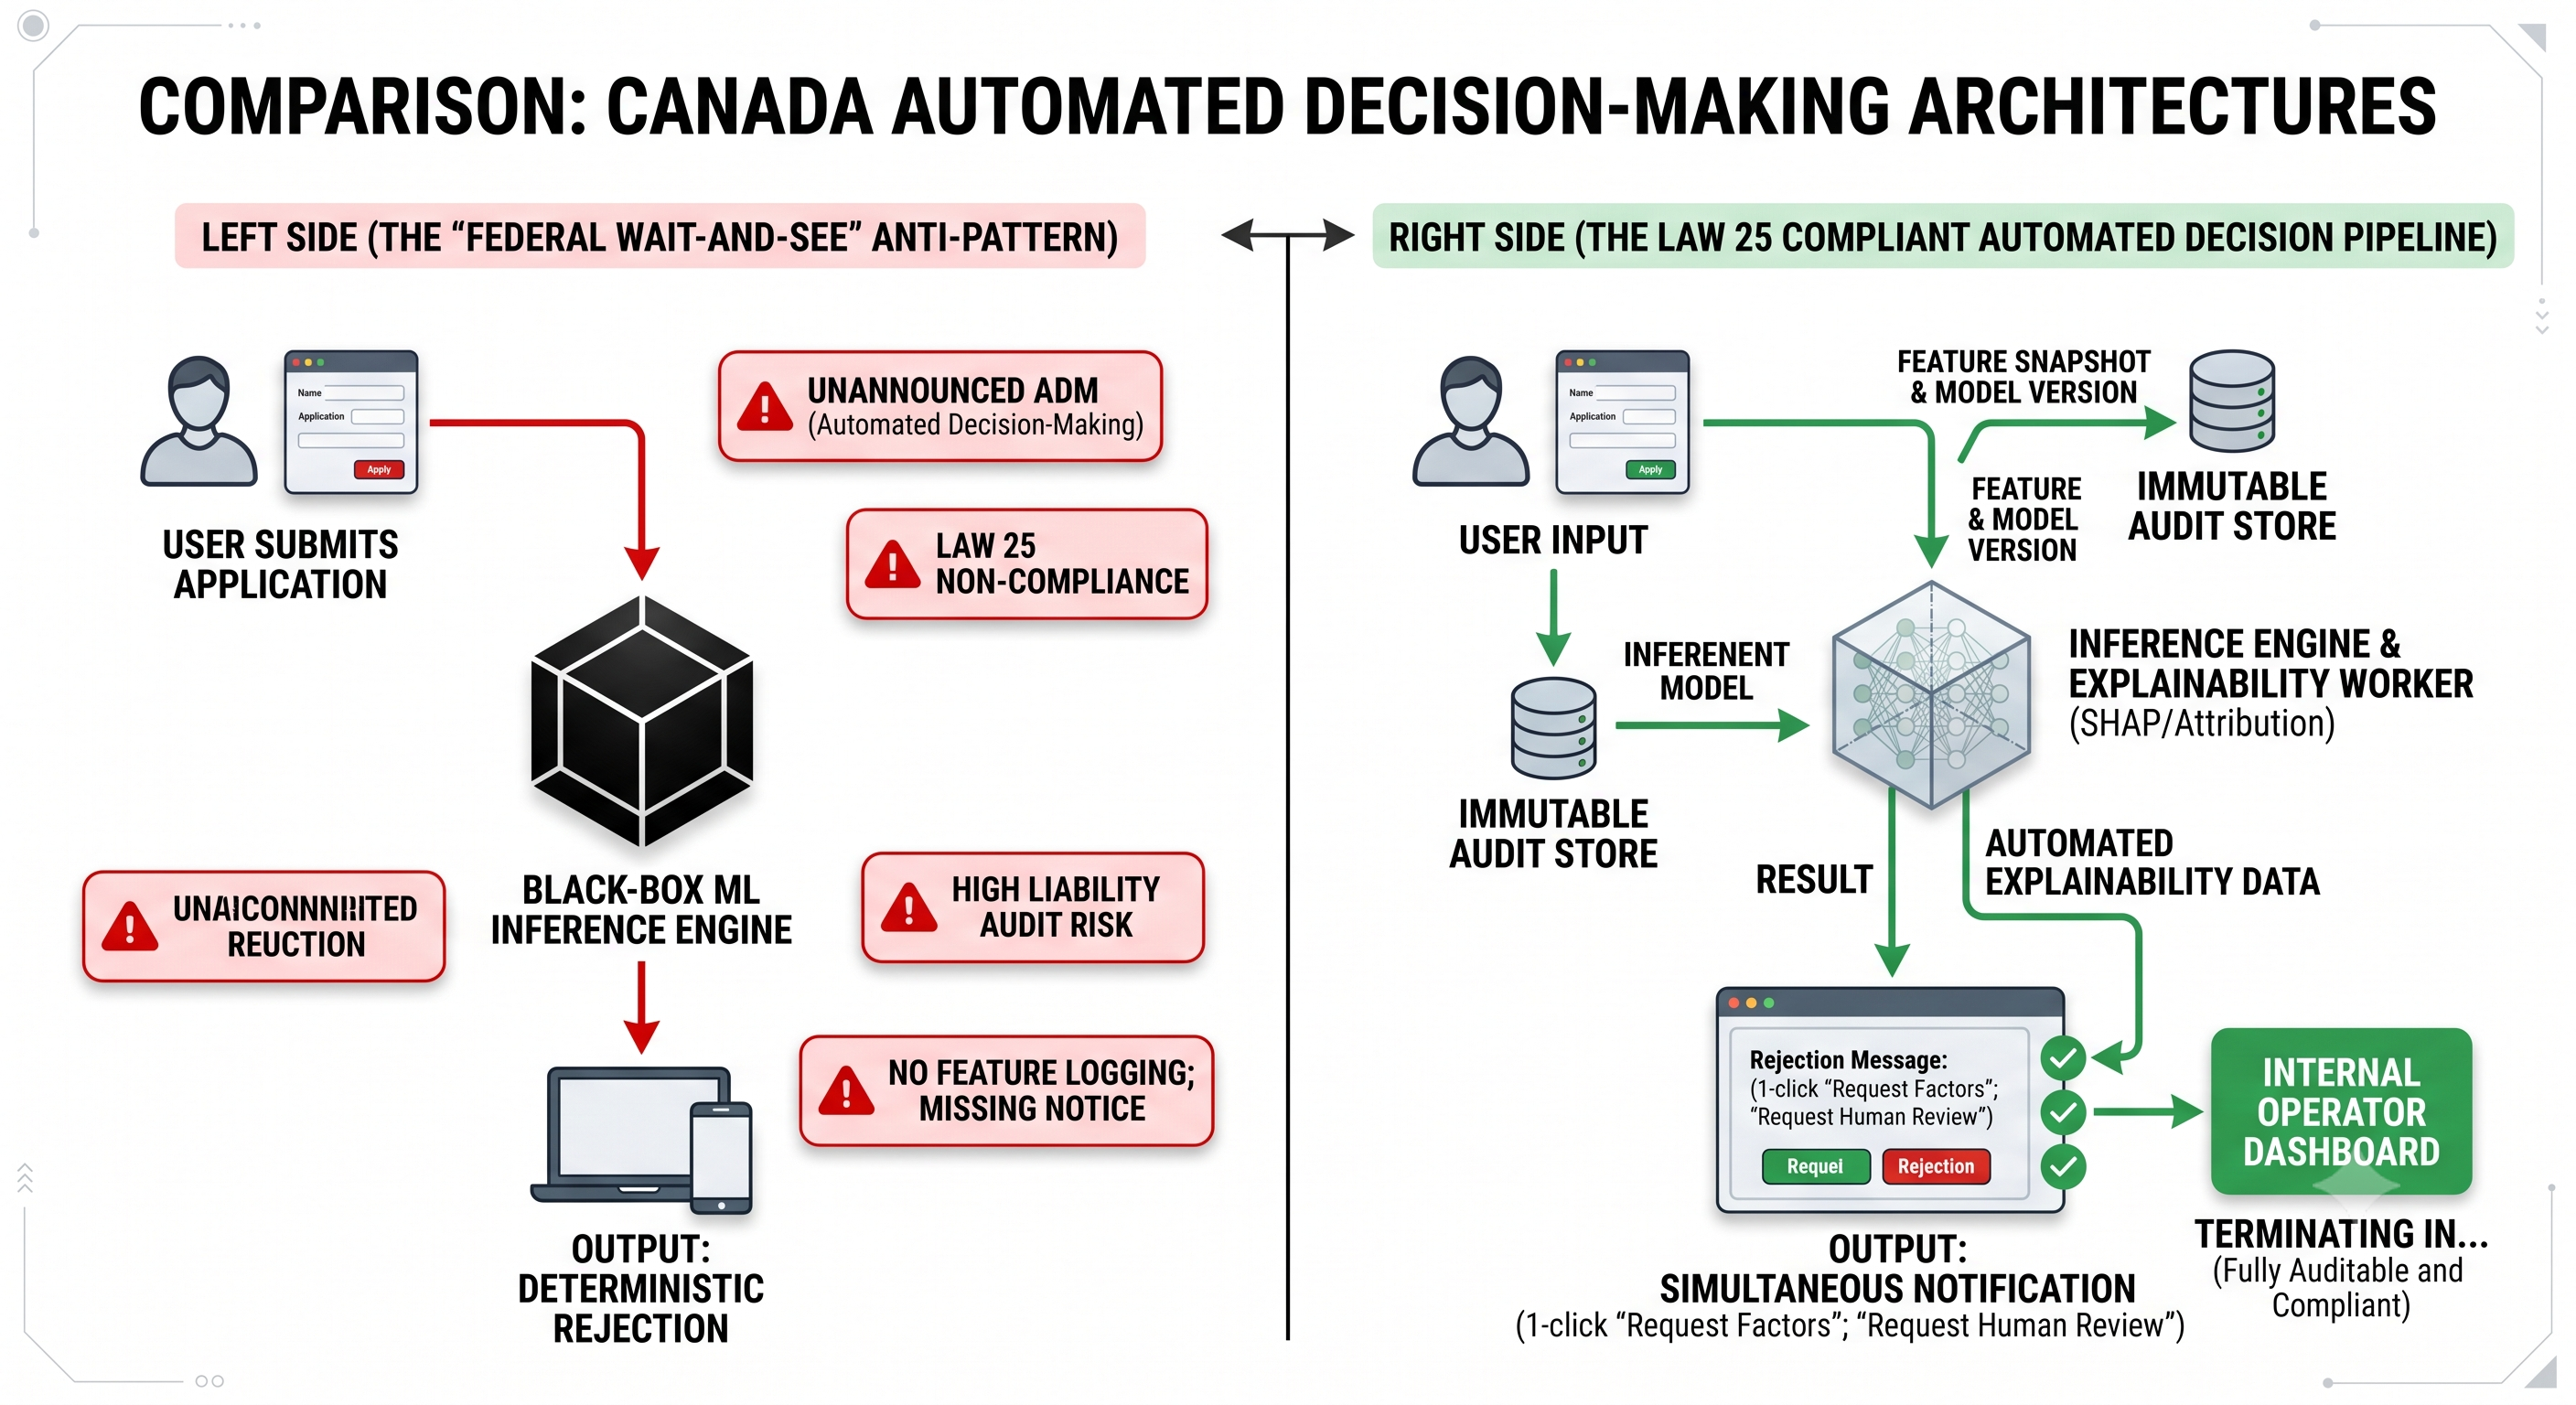 0 Comments 0 Shares 97 Views 0 Reviews
-
Myth vs. Fact: “Hosting in a UAE Cloud Region Automatically Satisfies Data Sovereignty”
With massive data center infrastructure investments expanding across Abu Dhabi and Dubai, tech teams across the Emirates are rapidly migrating enterprise workloads locally.
However, engineering leads and cloud architects regularly conflate two fundamentally different concepts: Data Residency (physical bytes at rest) vs. Data Sovereignty (legal jurisdiction, telemetry, and access boundaries).
Here is what UAE regulatory frameworks actually require:
❌ The Myth:
“We deployed our databases, LLM inference endpoints, and microservices in a UAE cloud region (AWS UAE / Azure UAE / Core42), so our data is sovereign and compliant with UAE PDPL, DIFC, and ADGM requirements.”
✅ The Reality:
Physical data location is just the first tier. Under UAE Federal Decree-Law No. 45 of 2021 (PDPL), DIFC Law No. 5 of 2020 (plus Regulation 10 on AI systems), and ADGM Data Protection Regulations, a workload hosted in the UAE can still trigger cross-border compliance violations through several common architectural blind spots:
The Telemetry & Observability Leak
Your database might sit in Dubai, but where do your application performance logs, APM agent metrics (e.g., Datadog, Dynatrace), and Sentry exception stack traces get routed? If unredacted customer PII or raw user prompts leak into observability collectors outside the country without an approved adequacy mechanism or standard contractual clauses, you have triggered a cross-border transfer.
Cross-Jurisdictional Inter-UAE Transfers (Mainland vs. Free Zones)
Many engineering teams do not realize that the UAE is a multi-jurisdictional landscape. Moving personal data between a mainland UAE entity and a DIFC or ADGM financial entity is legally an independent cross-border data transfer between distinct legal regimes, each enforcing its own adequacy determinations and transfer safeguards.
Global Control Planes & Support Access
If a cloud provider’s remote global site reliability engineer (SRE) can access production payloads via IAM break-glass procedures from an overseas operations center, that access is legally treated as an extraterritorial export. Data residency without Customer Managed Keys (CMK) and Client-Side Field-Level Encryption (CSFLE) fails zero-trust data sovereignty standards.
Autonomous AI & Algorithmic Processing
If you are deploying LLMs or automated decision-making engines (particularly under DIFC's Regulation 10), data processing requires explicit algorithmic auditability, bias mitigation, and purpose limitation—hosting the weights on local compute does not bypass these governance requirements.
The Architectural Fix for UAE Tech Teams:
Implement strict egress-filtering policies (VPC endpoints) to prevent third-party SaaS SDKs from sending logs to foreign clusters.
Enforce envelope encryption using HSMs located within the UAE, ensuring your organization exclusively holds the root keys.
Map data flows between Mainland, DIFC, and ADGM nodes as distinct jurisdictional boundaries with explicit lawful transfer bases.
Discussion Question
When conducting cloud architectural reviews, how is your engineering team isolating third-party observability telemetry to prevent unintended cross-border data egress?
CTA (Join Techawks UAE)
Build robust, compliant enterprise architectures designed for the Middle East’s leading digital economy. Join Techawks UAE to connect with technical architects, engineering leads, and CTOs scaling production-grade infrastructure across Dubai, Abu Dhabi, and the wider region.Myth vs. Fact: “Hosting in a UAE Cloud Region Automatically Satisfies Data Sovereignty” With massive data center infrastructure investments expanding across Abu Dhabi and Dubai, tech teams across the Emirates are rapidly migrating enterprise workloads locally. However, engineering leads and cloud architects regularly conflate two fundamentally different concepts: Data Residency (physical bytes at rest) vs. Data Sovereignty (legal jurisdiction, telemetry, and access boundaries). Here is what UAE regulatory frameworks actually require: ❌ The Myth: “We deployed our databases, LLM inference endpoints, and microservices in a UAE cloud region (AWS UAE / Azure UAE / Core42), so our data is sovereign and compliant with UAE PDPL, DIFC, and ADGM requirements.” ✅ The Reality: Physical data location is just the first tier. Under UAE Federal Decree-Law No. 45 of 2021 (PDPL), DIFC Law No. 5 of 2020 (plus Regulation 10 on AI systems), and ADGM Data Protection Regulations, a workload hosted in the UAE can still trigger cross-border compliance violations through several common architectural blind spots: The Telemetry & Observability Leak Your database might sit in Dubai, but where do your application performance logs, APM agent metrics (e.g., Datadog, Dynatrace), and Sentry exception stack traces get routed? If unredacted customer PII or raw user prompts leak into observability collectors outside the country without an approved adequacy mechanism or standard contractual clauses, you have triggered a cross-border transfer. Cross-Jurisdictional Inter-UAE Transfers (Mainland vs. Free Zones) Many engineering teams do not realize that the UAE is a multi-jurisdictional landscape. Moving personal data between a mainland UAE entity and a DIFC or ADGM financial entity is legally an independent cross-border data transfer between distinct legal regimes, each enforcing its own adequacy determinations and transfer safeguards. Global Control Planes & Support Access If a cloud provider’s remote global site reliability engineer (SRE) can access production payloads via IAM break-glass procedures from an overseas operations center, that access is legally treated as an extraterritorial export. Data residency without Customer Managed Keys (CMK) and Client-Side Field-Level Encryption (CSFLE) fails zero-trust data sovereignty standards. Autonomous AI & Algorithmic Processing If you are deploying LLMs or automated decision-making engines (particularly under DIFC's Regulation 10), data processing requires explicit algorithmic auditability, bias mitigation, and purpose limitation—hosting the weights on local compute does not bypass these governance requirements. The Architectural Fix for UAE Tech Teams: Implement strict egress-filtering policies (VPC endpoints) to prevent third-party SaaS SDKs from sending logs to foreign clusters. Enforce envelope encryption using HSMs located within the UAE, ensuring your organization exclusively holds the root keys. Map data flows between Mainland, DIFC, and ADGM nodes as distinct jurisdictional boundaries with explicit lawful transfer bases. Discussion Question When conducting cloud architectural reviews, how is your engineering team isolating third-party observability telemetry to prevent unintended cross-border data egress? CTA (Join Techawks UAE) Build robust, compliant enterprise architectures designed for the Middle East’s leading digital economy. Join Techawks UAE to connect with technical architects, engineering leads, and CTOs scaling production-grade infrastructure across Dubai, Abu Dhabi, and the wider region.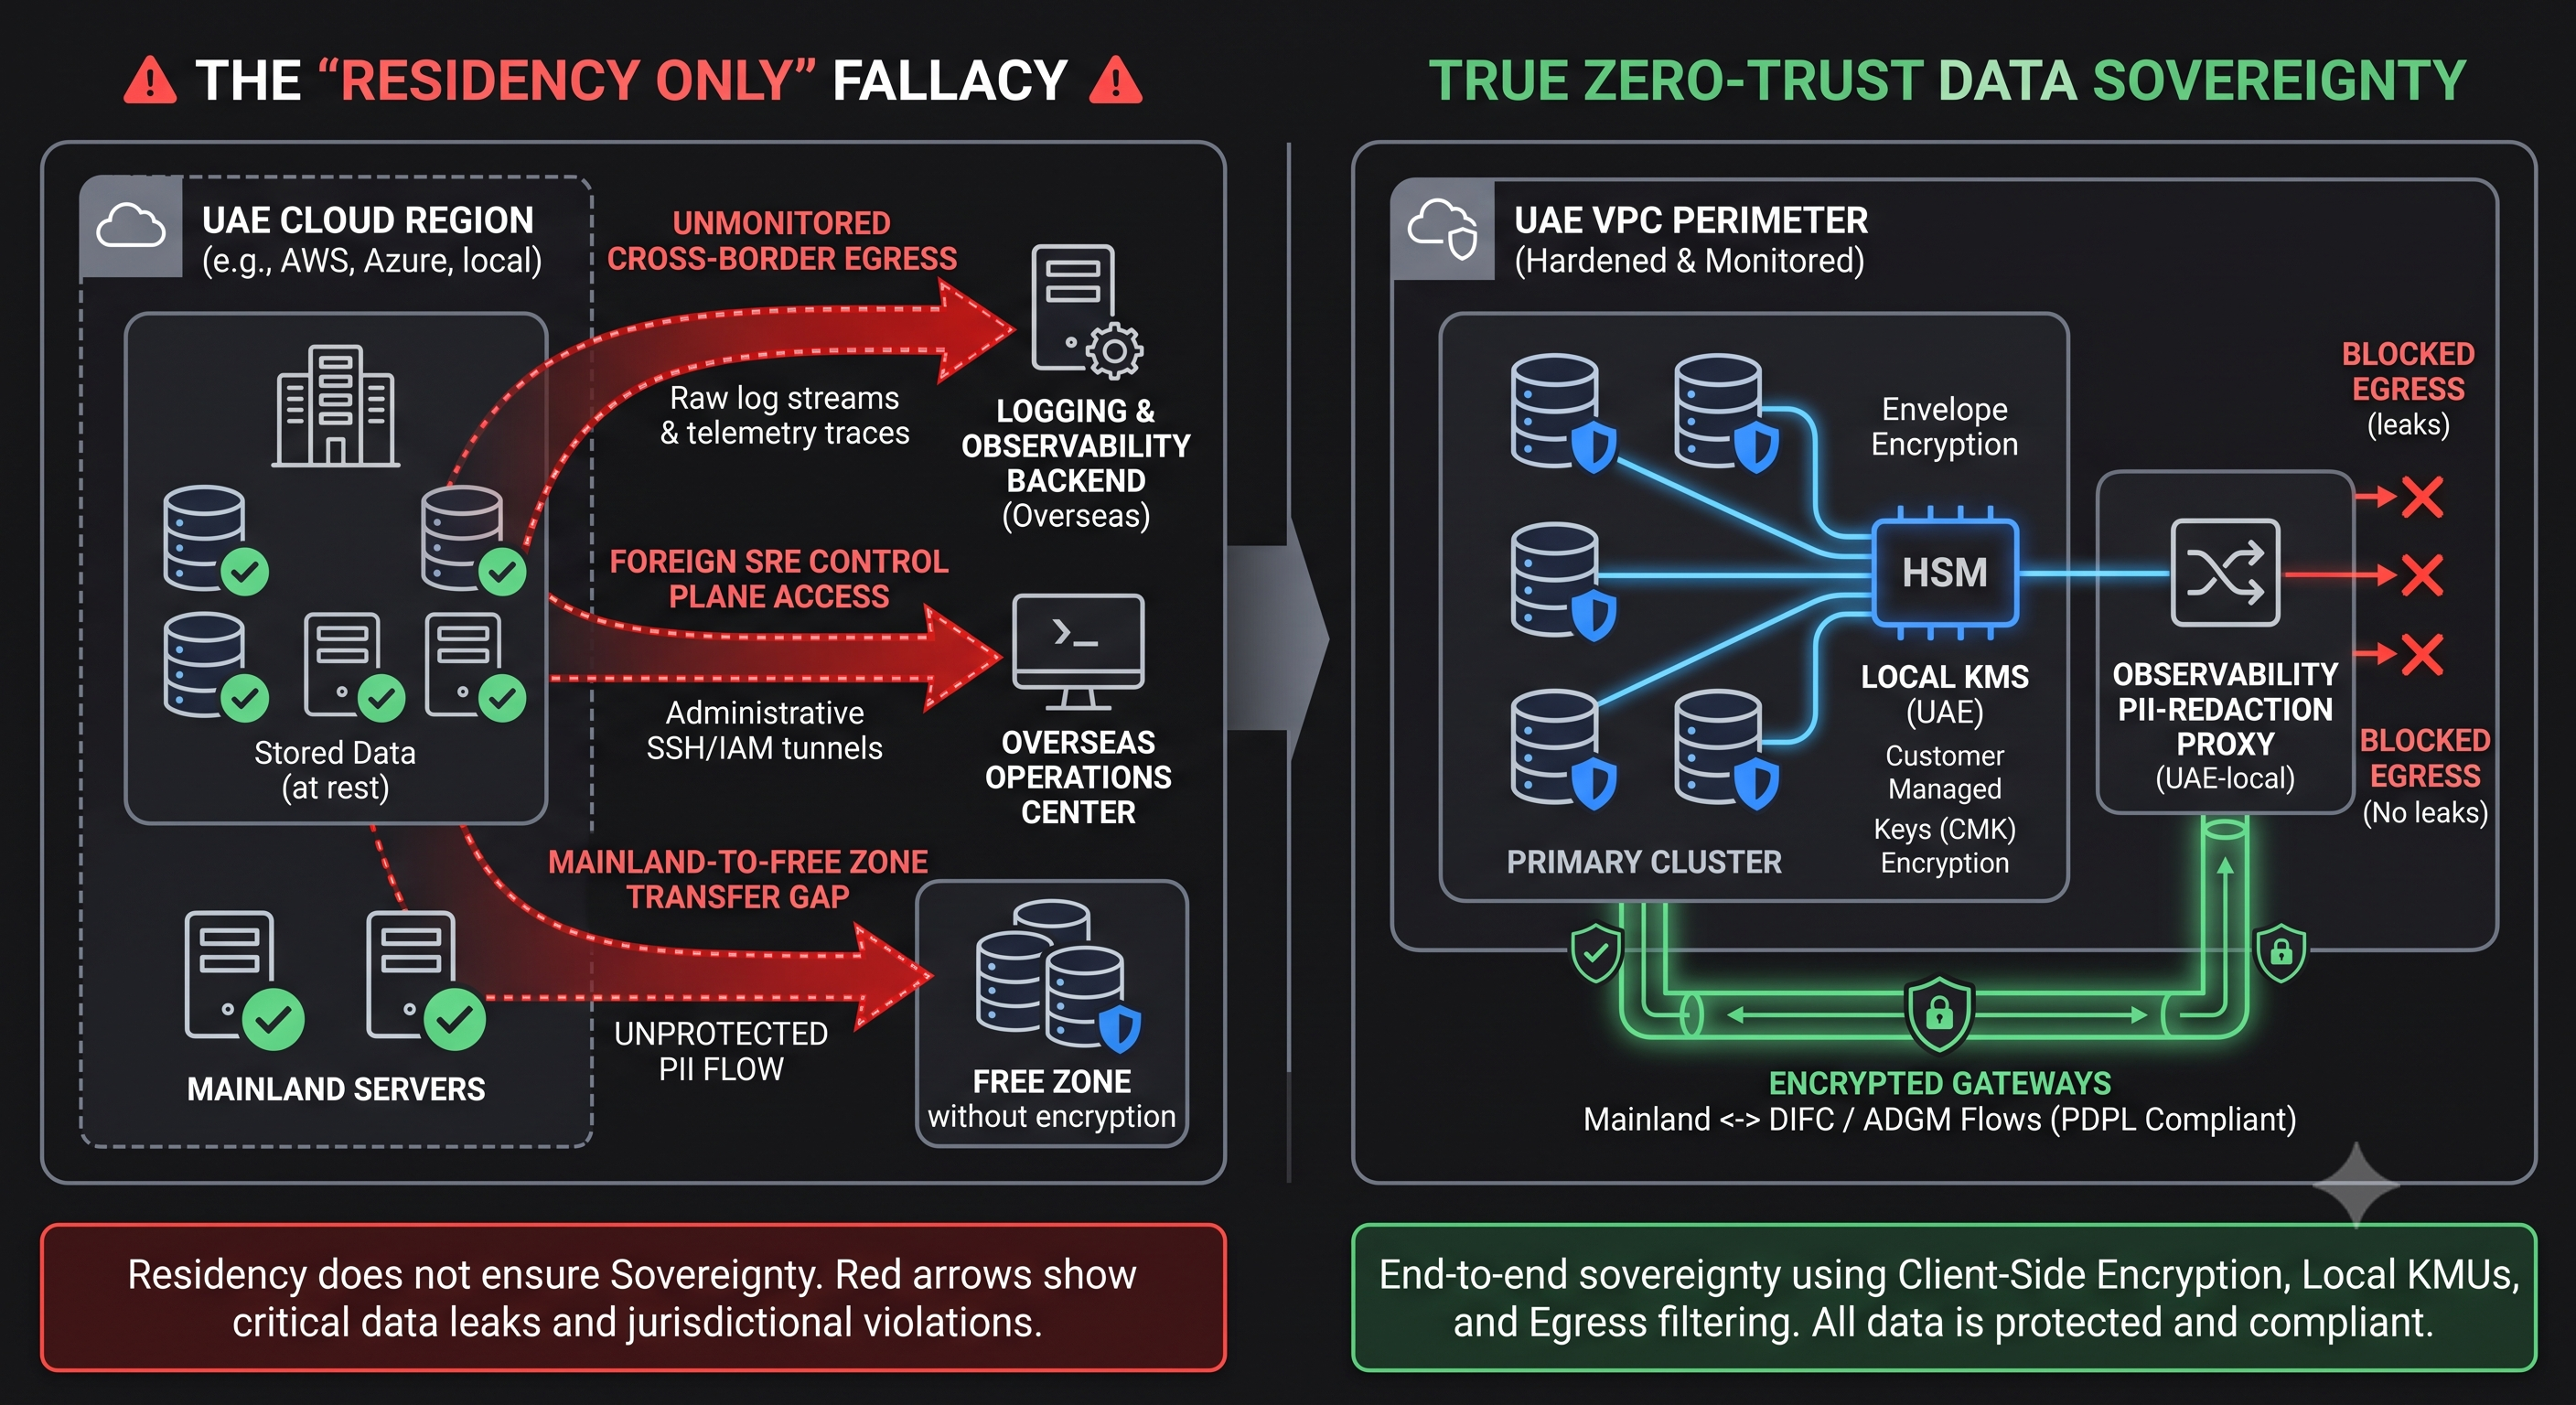 0 Comments 0 Shares 126 Views 0 Reviews
-
Myth vs. Fact: “Because the UK Has No AI Act, Your Deployment Has No Legal Guardrails”
A pervasive misconception in the UK tech ecosystem is that because Westminster rejected the EU’s horizontal, monolithic AI Act in favour of a “pro-innovation” strategy, building AI products in the UK is essentially an unregulated greenfield.
Engineers and founders keep confusing the absence of a single codified statute with an absence of statutory enforcement.
Here is the architectural reality:
❌ The Myth:
“The UK operates on voluntary AI safety pledges and light-touch principles. We don’t need formal AI compliance pipelines unless we sell directly into the EU.”
✅ The Reality:
The UK’s decentralised, sector-led regime is often harder to navigate than a unified framework. Instead of a single omnibus checklist, UK engineering teams are subject to overlapping enforcement from multiple regulators, each turning existing statutory powers into binding AI mandates.
If you deploy models, automated decision-making (ADM), or algorithmic pipelines in the UK, your architecture is currently governed across three active fronts:
The ICO’s Statutory AI Code of Practice & UK GDPR
Under statutory duty, the Information Commissioner’s Office (ICO) enforces strict data protection rules around AI. Under the Data (Use and Access) framework, deploying automated decisions with legal or significant effects requires auditable safeguards: mandatory human-in-the-loop remediation, explainability traces, and pre-deployment Data Protection Impact Assessments (DPIAs).
Sector Regulators with Real Teeth (FCA, MHRA, CMA)
The UK doesn't have an "AI Police"—it has existing statutory bodies that have weaponised their core remits against algorithmic drift. If you deploy AI in fintech, the FCA’s Consumer Duty and Senior Managers Regime (SM&CR) holds individual executives directly accountable for discriminatory or hallucinated AI outputs. In healthcare, the MHRA treats diagnostic ML as medical software with strict lifecycle surveillance.
The Extraterritorial Spillover
If your UK-built API serves European users or processes downstream outputs used in the EU, your architecture falls directly under the EU AI Act’s extraterritorial scope anyway—including conformity assessments and post-market tracking for high-risk domains.
The Engineering Takeaway for UK Builders:
Stop treating AI governance as legal documentation after deployment. Implement an Immutable AI Asset Register and telemetry logs today: trace training datasets, log model inference checkpoints, and ensure every automated decision produces an auditable rationale.
Discussion Question
Is your UK engineering team maintaining a centralized AI model and tool register, or are departments quietly adopting black-box APIs without a documented DPIA?
CTA (Join Techawks UK)
Cut through policy confusion with practical, production-ready engineering standards. Join Techawks UK to connect with tech founders, systems architects, and engineering leaders building compliant, world-class technology across the UK.Myth vs. Fact: “Because the UK Has No AI Act, Your Deployment Has No Legal Guardrails” A pervasive misconception in the UK tech ecosystem is that because Westminster rejected the EU’s horizontal, monolithic AI Act in favour of a “pro-innovation” strategy, building AI products in the UK is essentially an unregulated greenfield. Engineers and founders keep confusing the absence of a single codified statute with an absence of statutory enforcement. Here is the architectural reality: ❌ The Myth: “The UK operates on voluntary AI safety pledges and light-touch principles. We don’t need formal AI compliance pipelines unless we sell directly into the EU.” ✅ The Reality: The UK’s decentralised, sector-led regime is often harder to navigate than a unified framework. Instead of a single omnibus checklist, UK engineering teams are subject to overlapping enforcement from multiple regulators, each turning existing statutory powers into binding AI mandates. If you deploy models, automated decision-making (ADM), or algorithmic pipelines in the UK, your architecture is currently governed across three active fronts: The ICO’s Statutory AI Code of Practice & UK GDPR Under statutory duty, the Information Commissioner’s Office (ICO) enforces strict data protection rules around AI. Under the Data (Use and Access) framework, deploying automated decisions with legal or significant effects requires auditable safeguards: mandatory human-in-the-loop remediation, explainability traces, and pre-deployment Data Protection Impact Assessments (DPIAs). Sector Regulators with Real Teeth (FCA, MHRA, CMA) The UK doesn't have an "AI Police"—it has existing statutory bodies that have weaponised their core remits against algorithmic drift. If you deploy AI in fintech, the FCA’s Consumer Duty and Senior Managers Regime (SM&CR) holds individual executives directly accountable for discriminatory or hallucinated AI outputs. In healthcare, the MHRA treats diagnostic ML as medical software with strict lifecycle surveillance. The Extraterritorial Spillover If your UK-built API serves European users or processes downstream outputs used in the EU, your architecture falls directly under the EU AI Act’s extraterritorial scope anyway—including conformity assessments and post-market tracking for high-risk domains. The Engineering Takeaway for UK Builders: Stop treating AI governance as legal documentation after deployment. Implement an Immutable AI Asset Register and telemetry logs today: trace training datasets, log model inference checkpoints, and ensure every automated decision produces an auditable rationale. Discussion Question Is your UK engineering team maintaining a centralized AI model and tool register, or are departments quietly adopting black-box APIs without a documented DPIA? CTA (Join Techawks UK) Cut through policy confusion with practical, production-ready engineering standards. Join Techawks UK to connect with tech founders, systems architects, and engineering leaders building compliant, world-class technology across the UK.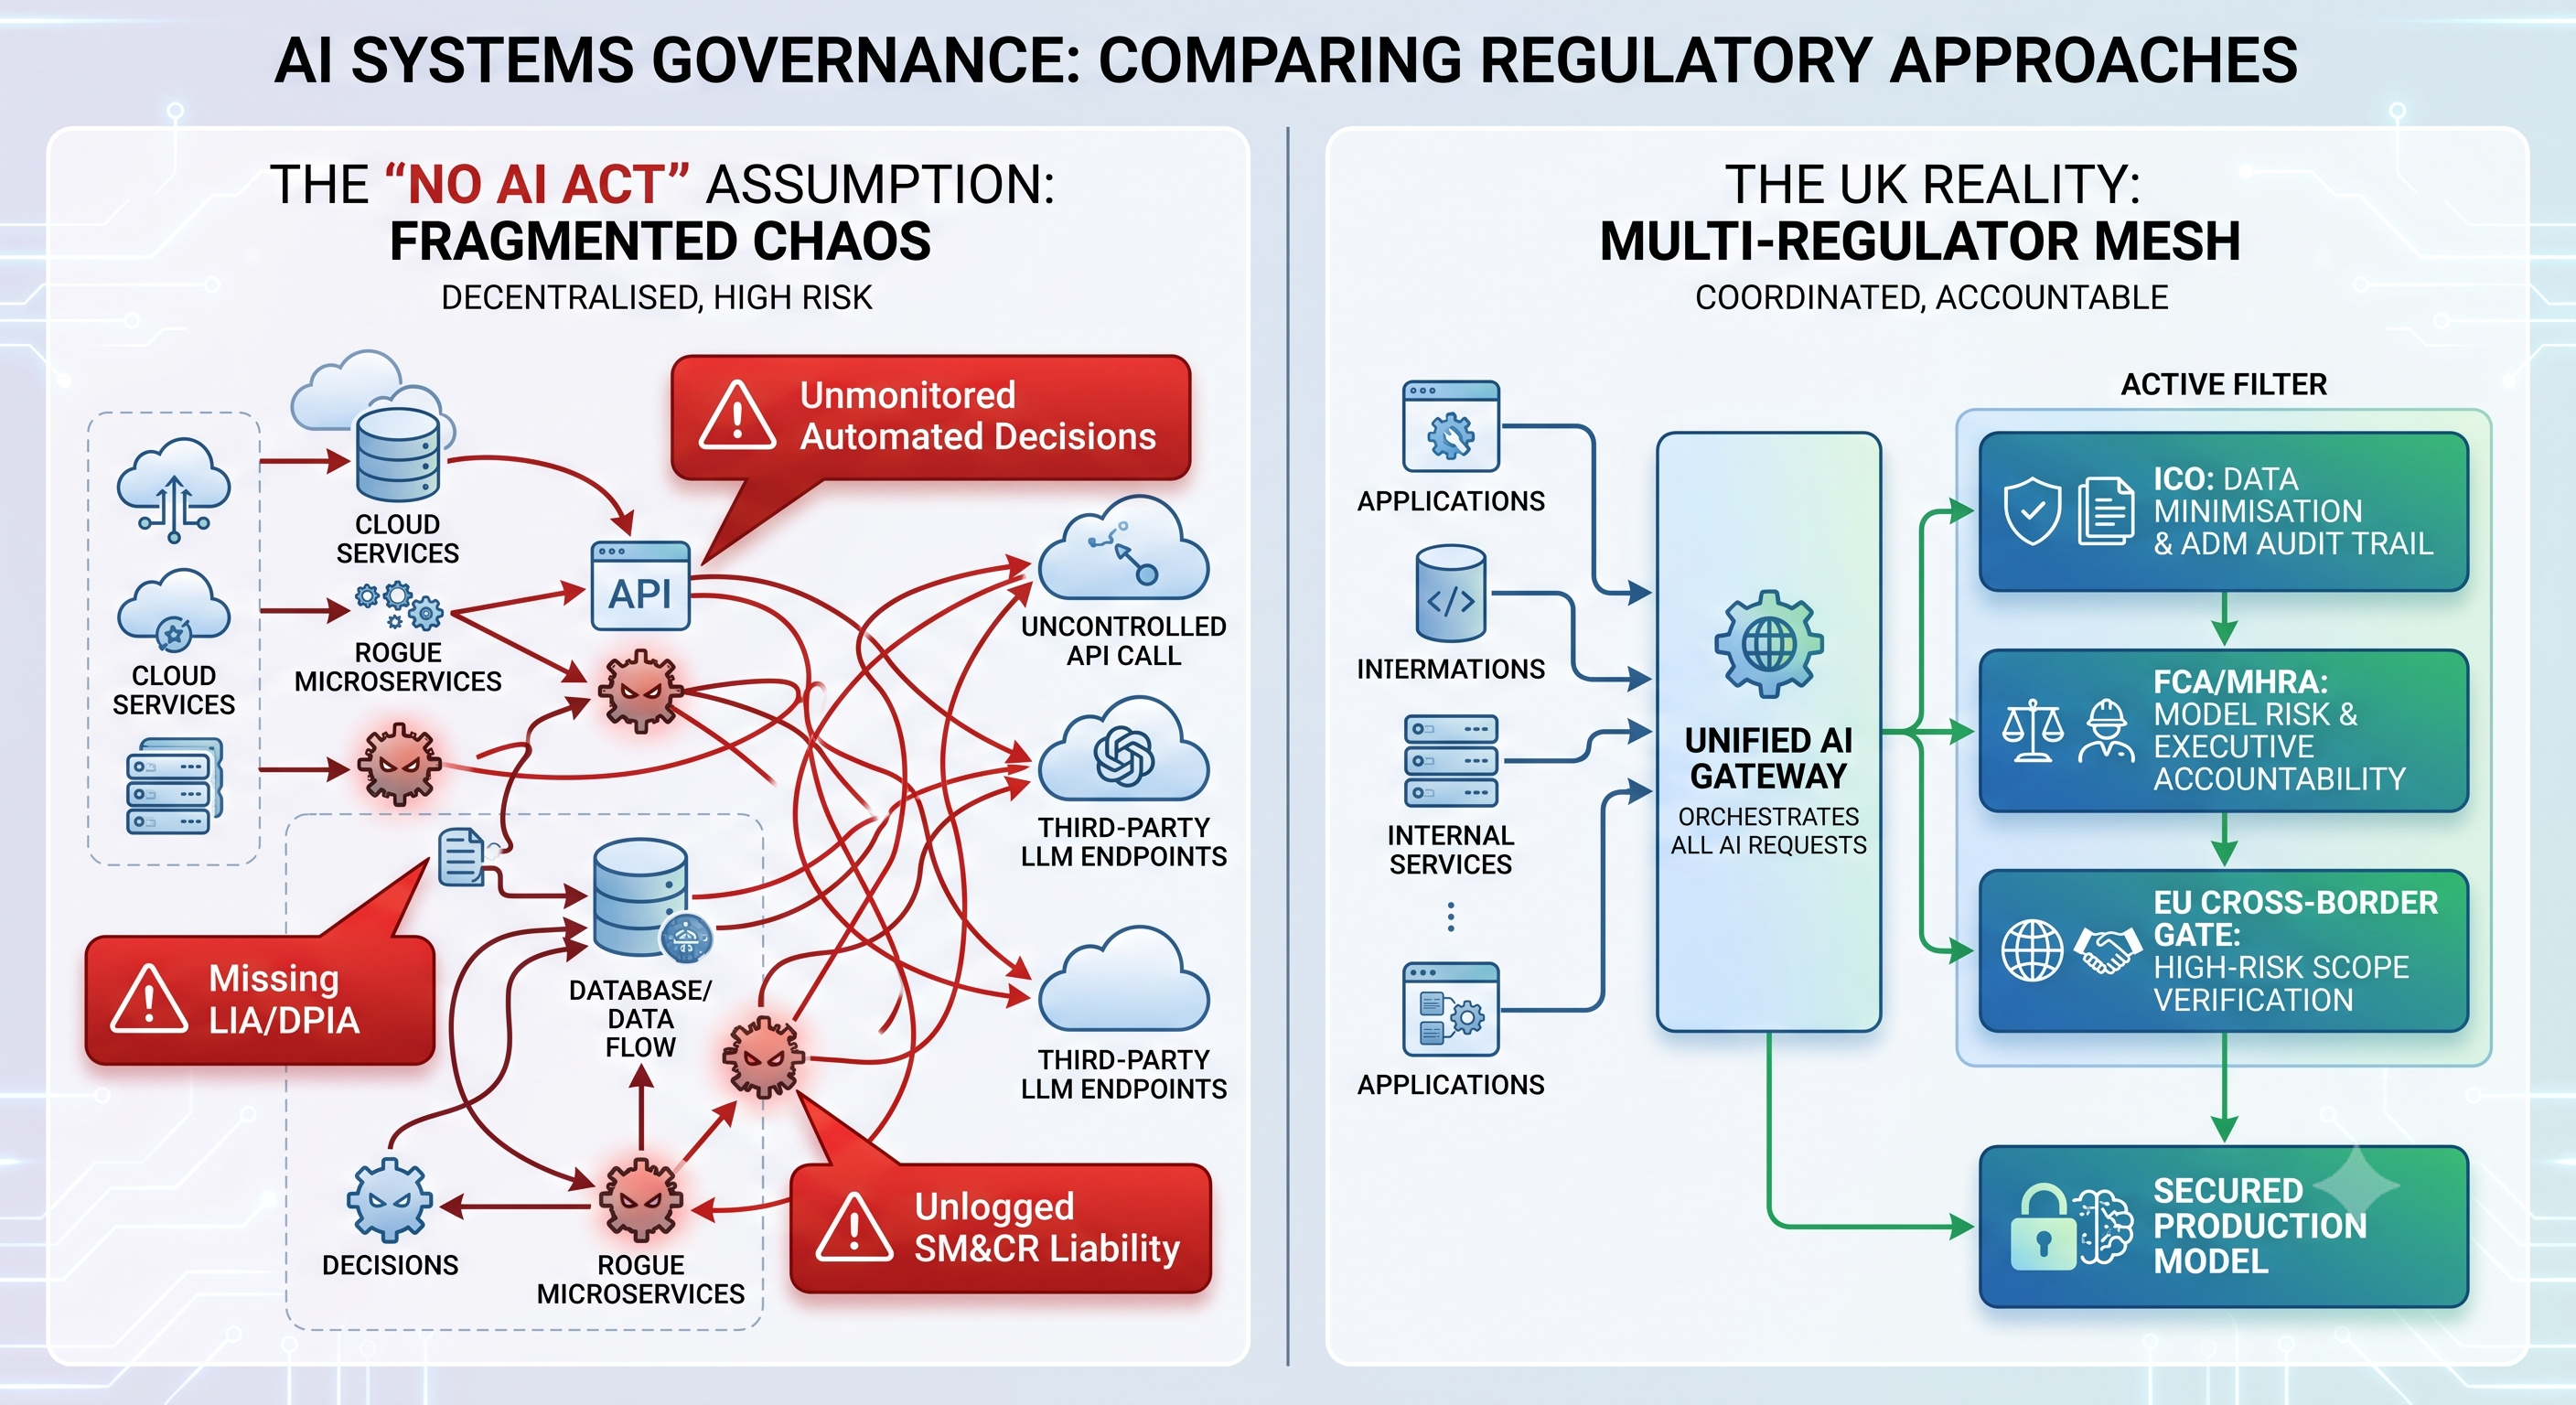 0 Comments 0 Shares 106 Views 0 Reviews
-
Myth vs. Fact: “1M+ Context Windows Make Fine-Tuning Obsolete”
A persistent assumption circulating across US engineering slack channels and architecture reviews is that massive context windows have effectively killed parameter-efficient fine-tuning (PEFT/LoRA).
Here is what the benchmarks—and enterprise cloud bills—actually show:
❌ The Myth:
“Since frontier models can ingest hundreds of thousands of tokens of reference docs in a single request, fine-tuning is legacy architecture.”
✅ The Reality:
Long-context retrieval and fine-tuning solve two fundamentally different engineering problems: Context is for Working Memory; Fine-Tuning is for Behavioral Conditioning.
Here is why relying exclusively on mega-context prompts fails in production:
The “Lost in the Middle” & Latency Tax
While needle-in-a-haystack retrieval has improved, attention mechanisms still suffer from degraded recall when reasoning across disparate segments of a massive prompt. Worse, Time-to-First-Token (TTFT) scales aggressively with input prompt length, making real-time interactive apps sluggish.
O(N²) KV Cache & Financial Drain
Prefix-caching helps, but repeatedly passing 200k tokens of company-specific domain logic, schema definitions, and style rules across millions of daily agent calls burns compute budgets exponentially faster than hosting an optimized, quantized LoRA adapter on an open-weight base model.
Style, Structure, and Constraint Compliance
Context windows can provide facts; fine-tuning teaches form and discipline. If you need an LLM to reliably output deterministic JSON schemas, adhere strictly to a proprietary compiler dialect, or follow rigorous internal safety boundaries without prompt drift, few-shot prompt injection will occasionally fail. Behavioral weight adaptation will not.
The Rule of Thumb for 2026 Architectures:
Use RAG / Context Windows when data changes dynamically by the minute (customer account data, live inventory, ephemeral logs).
Use Fine-Tuning / Post-Training when the syntax, task style, domain nomenclature, or output constraints are invariant across calls.
Discussion Question
Where has your team drawn the line in production: Are you leaning harder into dynamic context caching/RAG, or shifting deterministic workflows into fine-tuned internal models?
CTA (Join Techawks USA)
Cut through AI hype with field-tested architecture patterns. Join Techawks USA to connect with engineers, founders, and technical leaders building production-grade infrastructure across the nation.Myth vs. Fact: “1M+ Context Windows Make Fine-Tuning Obsolete” A persistent assumption circulating across US engineering slack channels and architecture reviews is that massive context windows have effectively killed parameter-efficient fine-tuning (PEFT/LoRA). Here is what the benchmarks—and enterprise cloud bills—actually show: ❌ The Myth: “Since frontier models can ingest hundreds of thousands of tokens of reference docs in a single request, fine-tuning is legacy architecture.” ✅ The Reality: Long-context retrieval and fine-tuning solve two fundamentally different engineering problems: Context is for Working Memory; Fine-Tuning is for Behavioral Conditioning. Here is why relying exclusively on mega-context prompts fails in production: The “Lost in the Middle” & Latency Tax While needle-in-a-haystack retrieval has improved, attention mechanisms still suffer from degraded recall when reasoning across disparate segments of a massive prompt. Worse, Time-to-First-Token (TTFT) scales aggressively with input prompt length, making real-time interactive apps sluggish. O(N²) KV Cache & Financial Drain Prefix-caching helps, but repeatedly passing 200k tokens of company-specific domain logic, schema definitions, and style rules across millions of daily agent calls burns compute budgets exponentially faster than hosting an optimized, quantized LoRA adapter on an open-weight base model. Style, Structure, and Constraint Compliance Context windows can provide facts; fine-tuning teaches form and discipline. If you need an LLM to reliably output deterministic JSON schemas, adhere strictly to a proprietary compiler dialect, or follow rigorous internal safety boundaries without prompt drift, few-shot prompt injection will occasionally fail. Behavioral weight adaptation will not. The Rule of Thumb for 2026 Architectures: Use RAG / Context Windows when data changes dynamically by the minute (customer account data, live inventory, ephemeral logs). Use Fine-Tuning / Post-Training when the syntax, task style, domain nomenclature, or output constraints are invariant across calls. Discussion Question Where has your team drawn the line in production: Are you leaning harder into dynamic context caching/RAG, or shifting deterministic workflows into fine-tuned internal models? CTA (Join Techawks USA) Cut through AI hype with field-tested architecture patterns. Join Techawks USA to connect with engineers, founders, and technical leaders building production-grade infrastructure across the nation.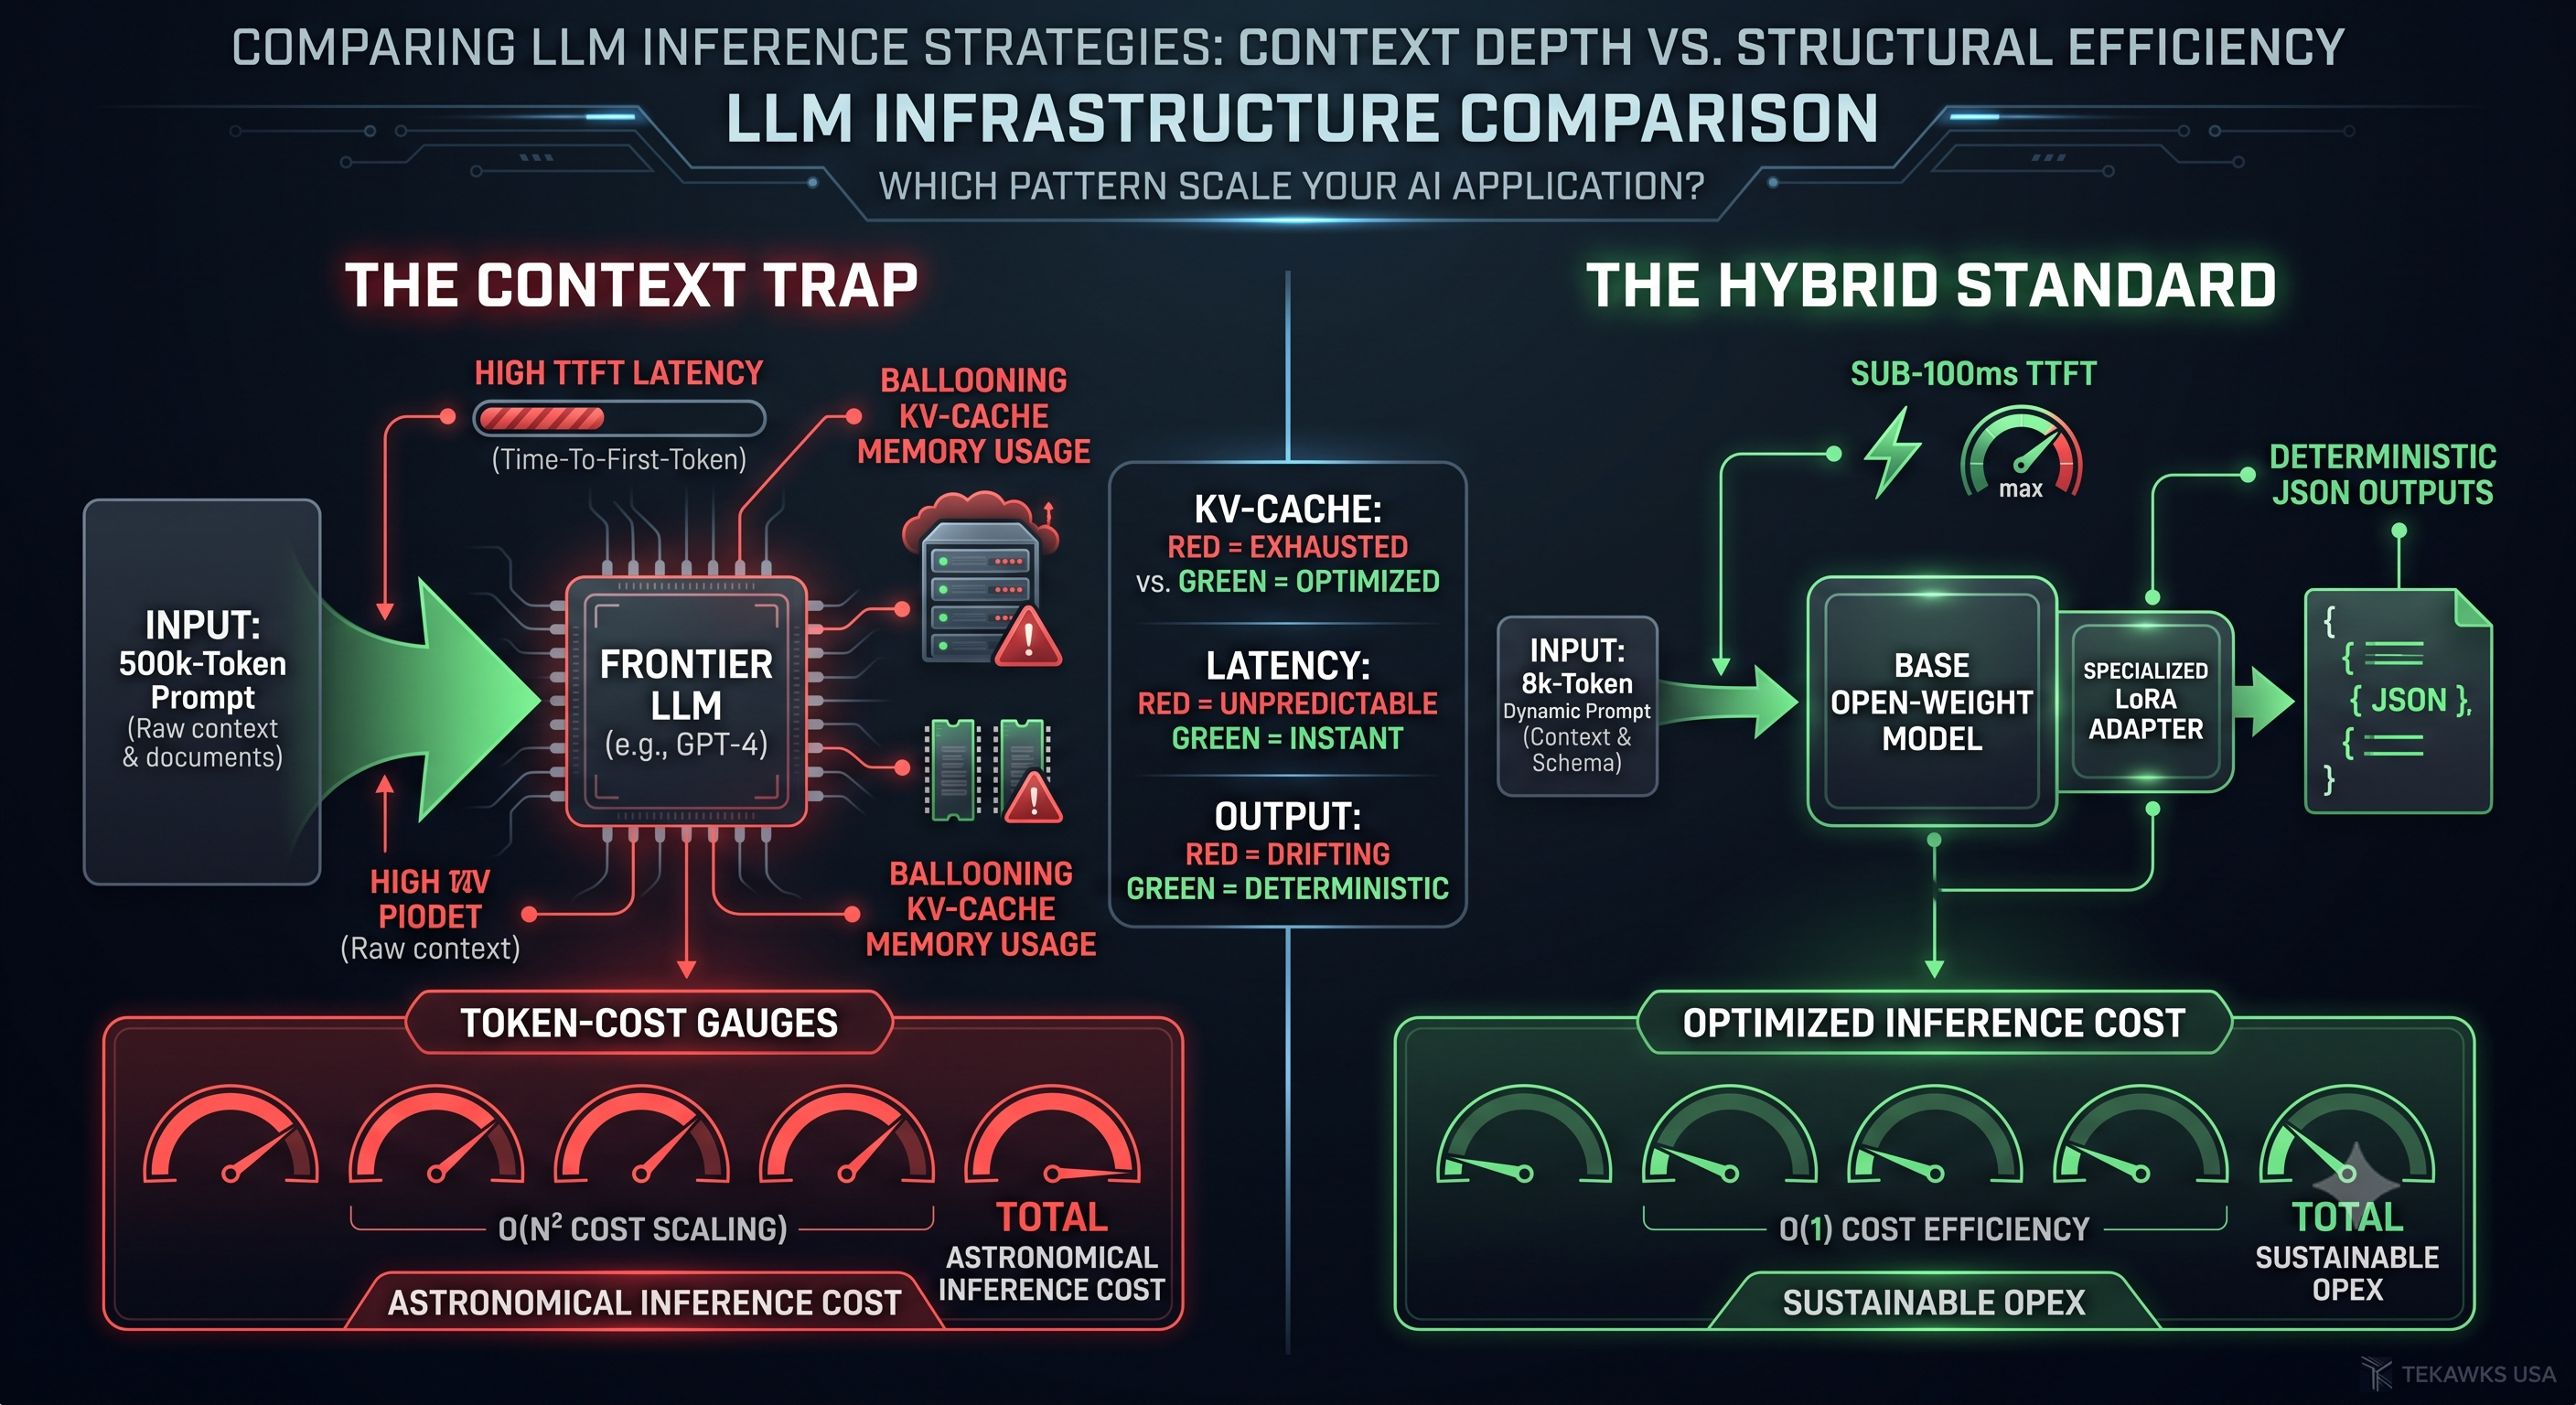 0 Comments 0 Shares 118 Views 0 Reviews
-
The DPDP Compliance Mirage: Why a Privacy Policy Update Won’t Save Indian Startups from ₹250 Crore Penalties
Across the Indian tech ecosystem—from Bengaluru SaaS ventures to Mumbai fintechs—a dangerous misconception has set in:
❌ The Myth: "DPDP compliance is a legal check-the-box exercise. Just update terms, publish a grievance officer email, and show a 'By signing up, you agree' consent banner."
✅ The Reality: India’s Digital Personal Data Protection framework strictly bans bundled consent, pre-ticked checkboxes, and unconditional terms of service. True compliance requires granular consent ledgers, purpose-limited data lifecycles, and automated Right-to-Erasure workflows.
Where Legacy Indian Tech Architectures Will Break:
The Single-Boolean Consent Flaw: Storing is_consent_given = true on your users table will fail compliance scrutiny. The law mandates granular, unbundled consent across specific processing purposes (e.g., core fulfillment vs. promotional analytics vs. third-party SDK sharing). If challenged, you must provide verifiable proof of the exact policy version and granular permissions granted at that timestamp.
The "Soft-Delete" Illusion: In most Indian codebases, user deletion is merely setting is_deleted = true. Under DPDP’s Right to Erasure, holding plaintext personally identifiable information (PII) indefinitely across transaction logs, read replicas, and vector embeddings without an ongoing lawful purpose creates direct legal exposure.
Third-Party Telemetry Leaks: When an app initializes third-party analytics, crash reporting, or advertising SDKs before explicit consent is granted, customer PII and device fingerprints get transmitted externally. Under the Act, the data fiduciary remains strictly liable for processors down the pipeline.
The Engineering Blueprint for DPDP Readiness:
Build an Immutable Consent Ledger: Implement a dedicated event log tracking User_ID, Purpose_Category, Policy_Version_Hash, and Timestamp. Every state change (opt-in or revocation) must publish an event to message brokers.
Implement Dynamic Feature Gating: Decouple third-party trackers and non-essential APIs from initial app boot. Gate non-essential SDK network calls behind dynamic consent flags queried at runtime.
Automate Cascading Erasure Pipelines: Build asynchronous workers (Kafka/SQS) that listen for withdrawal/deletion events to purge or irreversibly cryptographically tokenize customer PII across caching layers, data warehouses, and downstream microservices.
The takeaway: A privacy policy written by a top law firm cannot compensate for an un-auditable database. If your engineering schema cannot programmatically trace and revoke consent per data field, your platform remains exposed.
Discussion Question
Has your team audited third-party analytics and ad SDKs for DPDP compliance, or are trackers still firing before explicit user consent is registered?
CTA (Join Techawks India)
Join Techawks India to discuss local engineering regulations, dissect sovereign tech architectures, and scale resilient products with India’s leading technologists.The DPDP Compliance Mirage: Why a Privacy Policy Update Won’t Save Indian Startups from ₹250 Crore Penalties Across the Indian tech ecosystem—from Bengaluru SaaS ventures to Mumbai fintechs—a dangerous misconception has set in: ❌ The Myth: "DPDP compliance is a legal check-the-box exercise. Just update terms, publish a grievance officer email, and show a 'By signing up, you agree' consent banner." ✅ The Reality: India’s Digital Personal Data Protection framework strictly bans bundled consent, pre-ticked checkboxes, and unconditional terms of service. True compliance requires granular consent ledgers, purpose-limited data lifecycles, and automated Right-to-Erasure workflows. Where Legacy Indian Tech Architectures Will Break: The Single-Boolean Consent Flaw: Storing is_consent_given = true on your users table will fail compliance scrutiny. The law mandates granular, unbundled consent across specific processing purposes (e.g., core fulfillment vs. promotional analytics vs. third-party SDK sharing). If challenged, you must provide verifiable proof of the exact policy version and granular permissions granted at that timestamp. The "Soft-Delete" Illusion: In most Indian codebases, user deletion is merely setting is_deleted = true. Under DPDP’s Right to Erasure, holding plaintext personally identifiable information (PII) indefinitely across transaction logs, read replicas, and vector embeddings without an ongoing lawful purpose creates direct legal exposure. Third-Party Telemetry Leaks: When an app initializes third-party analytics, crash reporting, or advertising SDKs before explicit consent is granted, customer PII and device fingerprints get transmitted externally. Under the Act, the data fiduciary remains strictly liable for processors down the pipeline. The Engineering Blueprint for DPDP Readiness: Build an Immutable Consent Ledger: Implement a dedicated event log tracking User_ID, Purpose_Category, Policy_Version_Hash, and Timestamp. Every state change (opt-in or revocation) must publish an event to message brokers. Implement Dynamic Feature Gating: Decouple third-party trackers and non-essential APIs from initial app boot. Gate non-essential SDK network calls behind dynamic consent flags queried at runtime. Automate Cascading Erasure Pipelines: Build asynchronous workers (Kafka/SQS) that listen for withdrawal/deletion events to purge or irreversibly cryptographically tokenize customer PII across caching layers, data warehouses, and downstream microservices. The takeaway: A privacy policy written by a top law firm cannot compensate for an un-auditable database. If your engineering schema cannot programmatically trace and revoke consent per data field, your platform remains exposed. Discussion Question Has your team audited third-party analytics and ad SDKs for DPDP compliance, or are trackers still firing before explicit user consent is registered? CTA (Join Techawks India) Join Techawks India to discuss local engineering regulations, dissect sovereign tech architectures, and scale resilient products with India’s leading technologists.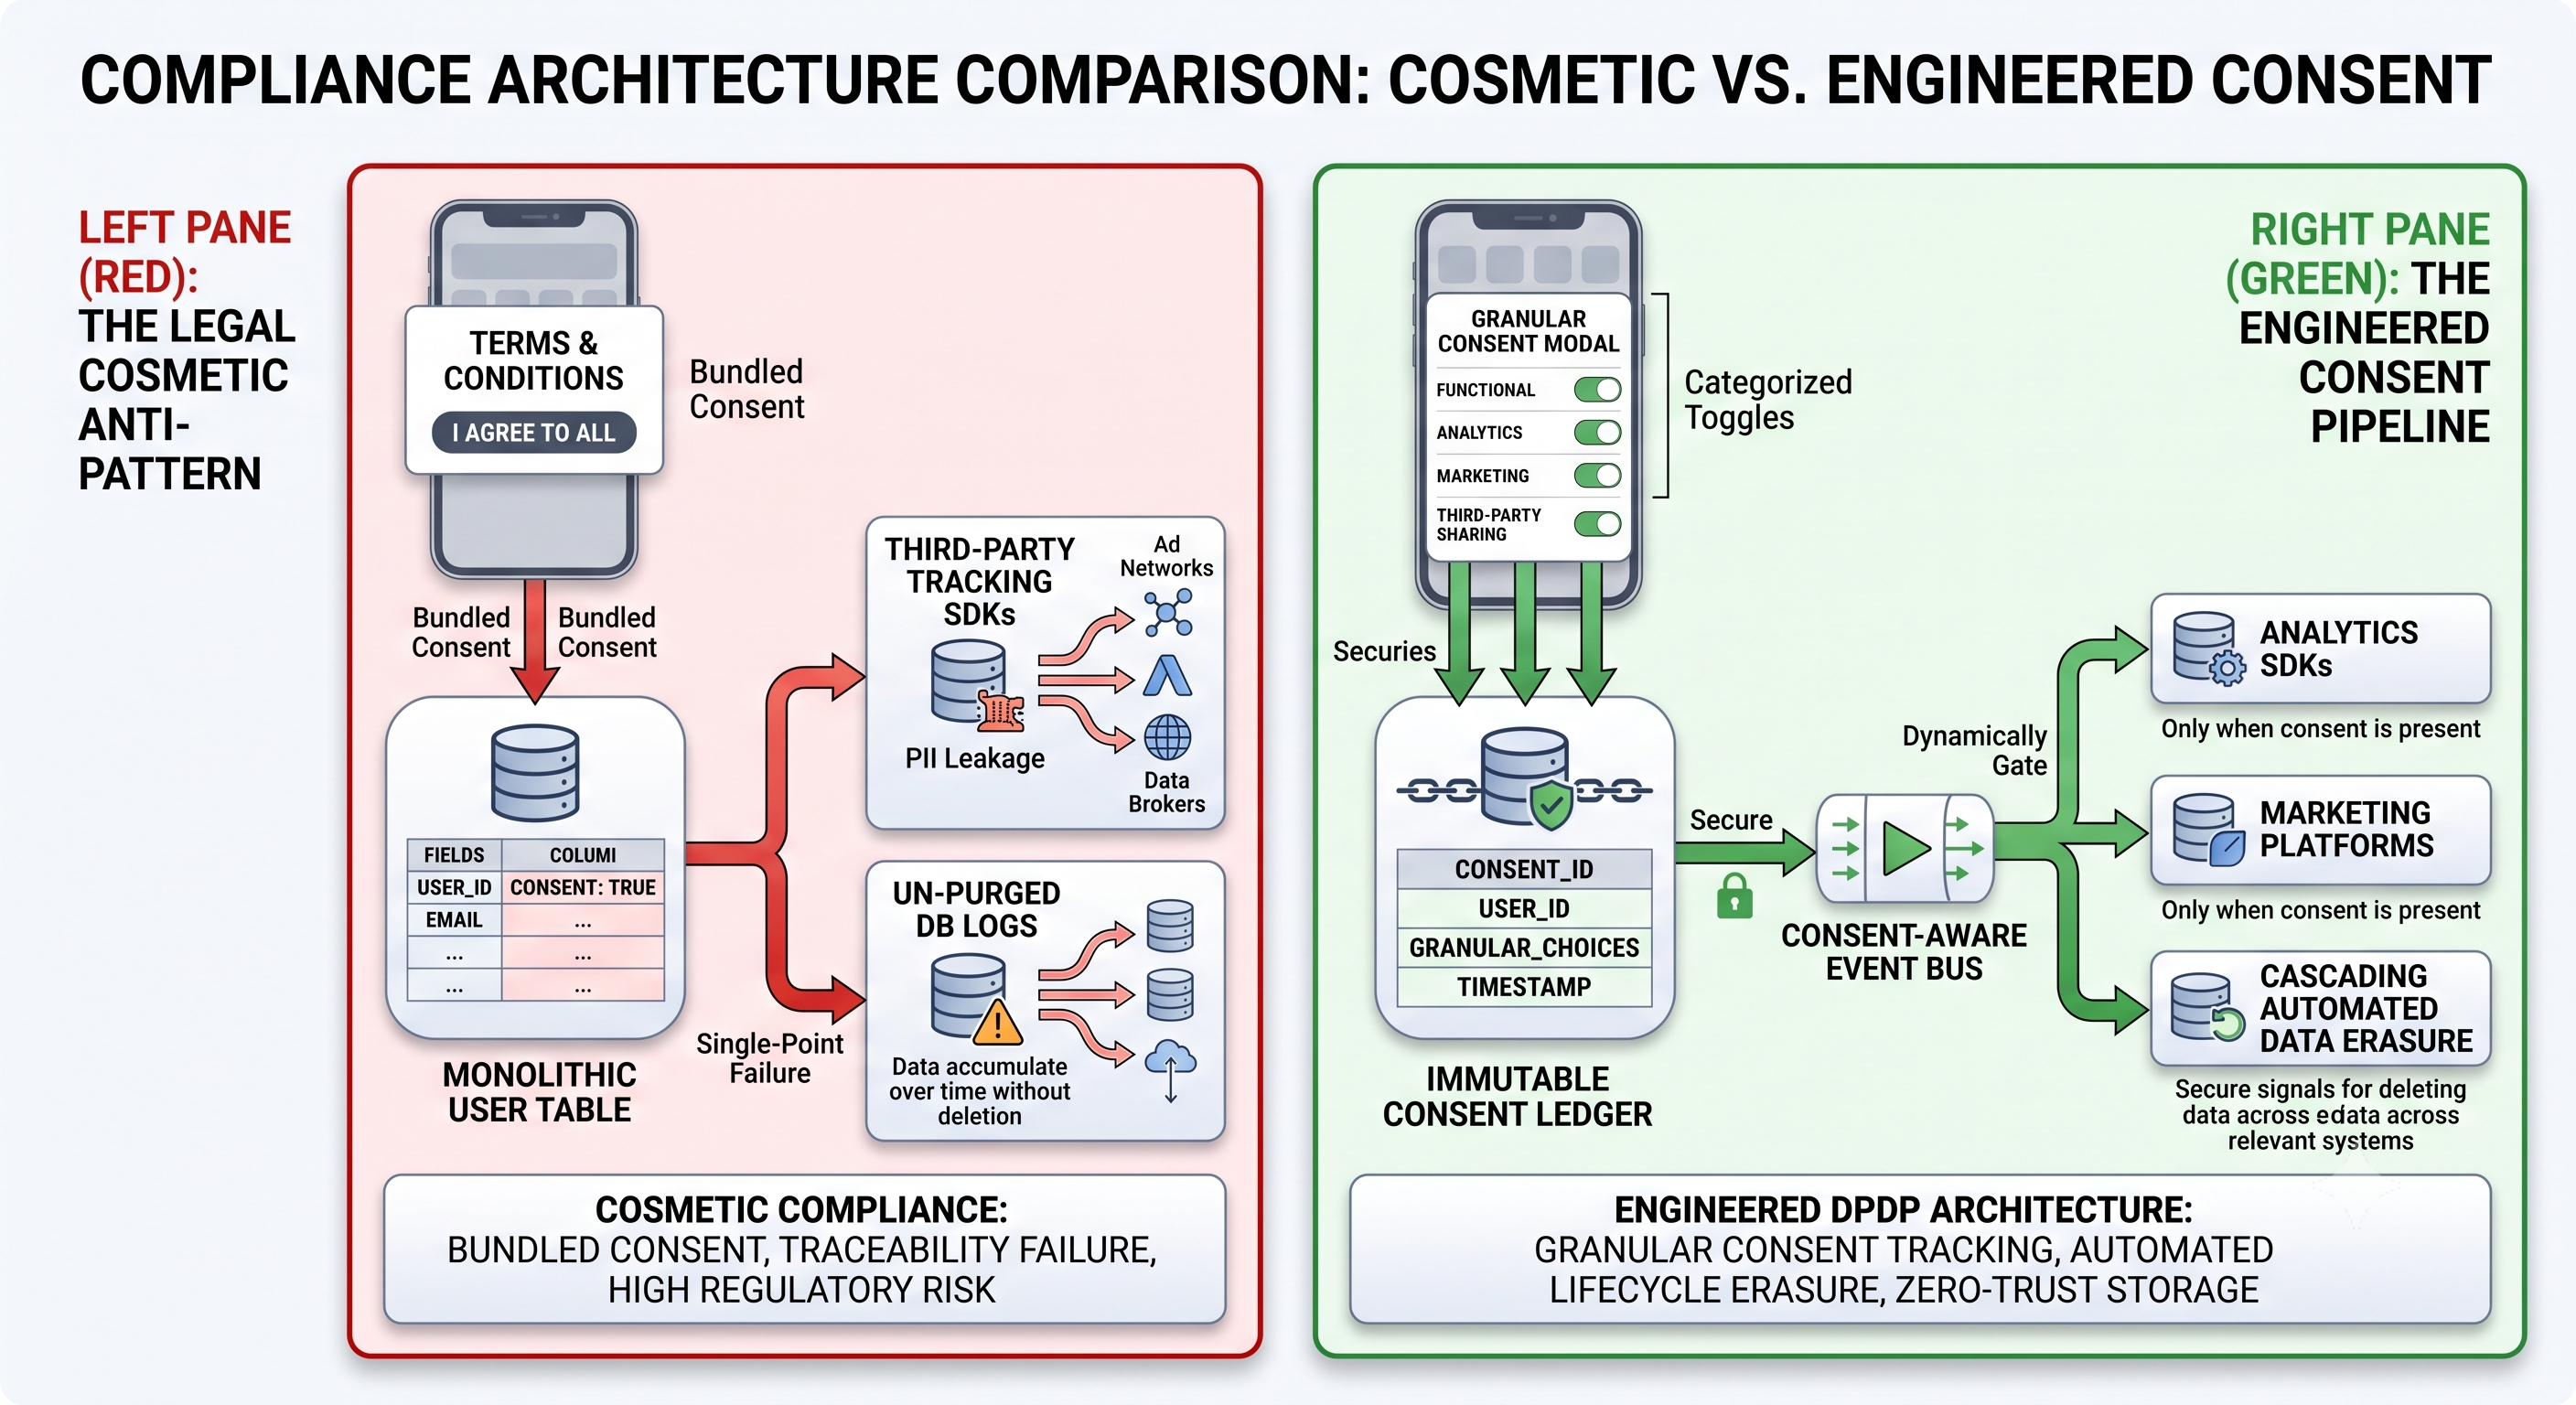 0 Comments 0 Shares 127 Views 0 Reviews
-
The Autoscaling Paradox: Why CPU-Based HPA Is Causing Outages Instead of Preventing Them
Across cloud platforms and Kubernetes clusters, a dangerous operations myth remains standard practice:
❌ The Myth: "Just attach an HPA targeting 60%–70% average CPU utilization to every deployment. If traffic surges, pods scale out, load distributes, and our service remains highly available."
✅ The Reality: HPA solves only one specific problem: throughput degradation in stateless, fast-starting workloads. When applied blindly, it masks underlying memory leaks, creates severe cold-start stampedes, and exhausts downstream database pools.
Why CPU-Driven Autoscaling Fails in Production:
The Out-Of-Memory (OOM) Death Spiral: If your workload bottlenecks on memory allocation or an unoptimized query, CPU usage often stays flat or drops as threads block waiting on I/O. HPA will not trigger because CPU thresholds aren't crossed. The pods then hit their memory limits, get killed by the Linux OOM-killer, drop out of the endpoint pool, and shift remaining load onto surviving replicas—triggering a cluster-wide restart cascade.
Cold-Start Amplification Under Burst Load: New container pods do not handle traffic instantaneously. Between scheduling, image pulling, runtime init (e.g., JVM warm-up or node modules initialization), and readiness checks, a pod can take 45–90 seconds to become healthy. During sudden traffic spikes, HPA aggressively orders 20 new pods, saturating cluster nodes with scheduling contention while the existing pods continue to crash under load.
The Downstream Connection Starvation: Doubling or tripling your pod replicas simultaneously multiplies active connections to downstream stateful components (Postgres pools, Redis clusters, Kafka brokers). Scaling out your compute layer without connection bounding simply pushes the bottleneck downstream, crashing your database.
The Modern Autoscaling Architecture:
Decouple HPA and VPA Roles: Do not let Vertical and Horizontal autoscalers fight over the same resource dimension. Use Vertical Pod Autoscaling (VPA) in recommendation mode to calibrate realistic memory/CPU baseline requests, and use HPA exclusively for dynamic scaling.
Scale on Leading Signals via KEDA: Transition away from generic CPU metrics. Use Kubernetes Event-driven Autoscaling (KEDA) to scale on leading indicators—such as queue lag (Kafka consumer offsets, SQS backlog depth), HTTP request rates, or P99 response latencies.
Configure Defensive Scaling Policies: Define explicit behavior blocks in your HPA manifest. Set stabilization windows (stabilizationWindowSeconds) and rate limits on scale-up/scale-down to avoid pod thrashing, and size minimum replicas (minReplicas) to absorb bursts during cold starts.
The takeaway: Scaling pods is an infrastructure intervention, not application optimization. If your autoscaling trigger doesn't reflect actual user queue saturation or application state, you aren't building elasticity—you're just automating instability.
Discussion Question
What metrics drive your production autoscalers today—generic CPU/memory averages, or custom application signals like queue depth and request latency?
CTA (Join Cloud, DevOps & Open Source)
Join the Cloud, DevOps & Open Source community to debate modern platform engineering patterns, benchmark Kubernetes autoscaling setups, and design resilient cloud architectures.The Autoscaling Paradox: Why CPU-Based HPA Is Causing Outages Instead of Preventing Them Across cloud platforms and Kubernetes clusters, a dangerous operations myth remains standard practice: ❌ The Myth: "Just attach an HPA targeting 60%–70% average CPU utilization to every deployment. If traffic surges, pods scale out, load distributes, and our service remains highly available." ✅ The Reality: HPA solves only one specific problem: throughput degradation in stateless, fast-starting workloads. When applied blindly, it masks underlying memory leaks, creates severe cold-start stampedes, and exhausts downstream database pools. Why CPU-Driven Autoscaling Fails in Production: The Out-Of-Memory (OOM) Death Spiral: If your workload bottlenecks on memory allocation or an unoptimized query, CPU usage often stays flat or drops as threads block waiting on I/O. HPA will not trigger because CPU thresholds aren't crossed. The pods then hit their memory limits, get killed by the Linux OOM-killer, drop out of the endpoint pool, and shift remaining load onto surviving replicas—triggering a cluster-wide restart cascade. Cold-Start Amplification Under Burst Load: New container pods do not handle traffic instantaneously. Between scheduling, image pulling, runtime init (e.g., JVM warm-up or node modules initialization), and readiness checks, a pod can take 45–90 seconds to become healthy. During sudden traffic spikes, HPA aggressively orders 20 new pods, saturating cluster nodes with scheduling contention while the existing pods continue to crash under load. The Downstream Connection Starvation: Doubling or tripling your pod replicas simultaneously multiplies active connections to downstream stateful components (Postgres pools, Redis clusters, Kafka brokers). Scaling out your compute layer without connection bounding simply pushes the bottleneck downstream, crashing your database. The Modern Autoscaling Architecture: Decouple HPA and VPA Roles: Do not let Vertical and Horizontal autoscalers fight over the same resource dimension. Use Vertical Pod Autoscaling (VPA) in recommendation mode to calibrate realistic memory/CPU baseline requests, and use HPA exclusively for dynamic scaling. Scale on Leading Signals via KEDA: Transition away from generic CPU metrics. Use Kubernetes Event-driven Autoscaling (KEDA) to scale on leading indicators—such as queue lag (Kafka consumer offsets, SQS backlog depth), HTTP request rates, or P99 response latencies. Configure Defensive Scaling Policies: Define explicit behavior blocks in your HPA manifest. Set stabilization windows (stabilizationWindowSeconds) and rate limits on scale-up/scale-down to avoid pod thrashing, and size minimum replicas (minReplicas) to absorb bursts during cold starts. The takeaway: Scaling pods is an infrastructure intervention, not application optimization. If your autoscaling trigger doesn't reflect actual user queue saturation or application state, you aren't building elasticity—you're just automating instability. Discussion Question What metrics drive your production autoscalers today—generic CPU/memory averages, or custom application signals like queue depth and request latency? CTA (Join Cloud, DevOps & Open Source) Join the Cloud, DevOps & Open Source community to debate modern platform engineering patterns, benchmark Kubernetes autoscaling setups, and design resilient cloud architectures.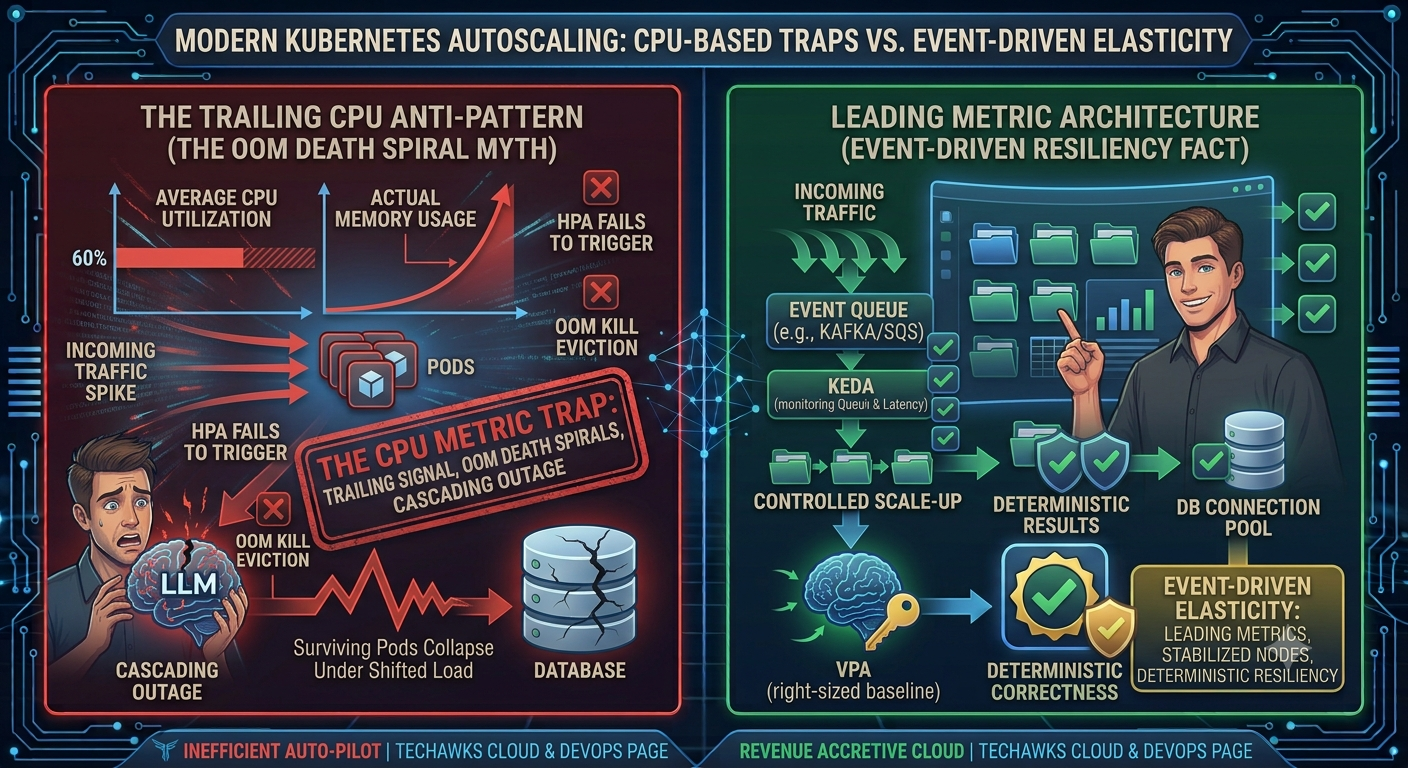 0 Comments 0 Shares 123 Views 0 Reviews
-
The Conversational Crutch: Why Slapping a Chatbox on Your SaaS Is Lazy Product Design
As generative AI toolkits became plug-and-play, product roadmaps fell victim to a massive industry misconception:
❌ The Myth: "Chat is the universal interface of the future. Replacing menus, forms, and control panels with an open prompt box eliminates UI complexity and gives users ultimate flexibility."
✅ The Reality: An empty prompt box forces maximum cognitive load onto the user. It trades clear affordances for a blank-canvas paralysis, slow typing speeds, and non-deterministic UX.
Why the "Everything-as-a-Chat" Pattern Fails:
The Death of Discoverability: Traditional graphical user interfaces (GUIs) communicate what is possible through visible affordances—buttons, sliders, toggles, and filters. A blinking cursor in a chatbox tells the user nothing about system capabilities, boundary limits, or failure states.
The Prompt Tax (Input Friction): Pointing and clicking takes 200 milliseconds. Typing a structured, context-rich prompt takes 30 seconds. Forcing users to articulate routine operations in natural language slows down workflows rather than accelerating them.
Loss of Spatial State & Correction Loops: In a GUI, tweaking a single parameter (like a date range or toggle) is an instant, localized adjustment. In a conversational interface, adjusting one variable requires re-prompting, reading a full response stream, and hoping the model doesn't drift or alter previous variables.
The Better Pattern: Hybrid Contextual Micro-Interactions
World-class AI UX embeds intelligence directly into existing UI paradigms rather than segregating it into a floating chat drawer:
Generative Affordances & Inline Controls: Instead of asking the user to prompt, anticipate their next step. Offer contextual AI suggestions as inline chips, hover-state shortcuts, or dynamic form pre-fills that can be accepted with a single click.
Bi-Directional Canvas UX: Keep the artifact (document, spreadsheet, canvas, or dashboard) front-and-center. Let the AI manipulate the canvas directly while keeping familiar UI levers (sliders, diff reviews, undo buttons) intact for tactile human control.
Scaffolding Over Blank Inputs: Replace the open prompt box with structured scaffolding—pre-built system templates, parameter slot-filling, and guided prompt builders that constrain the solution space.
The takeaway: Great UX is about reducing cognitive overhead, not showcasing model capabilities. The most powerful AI interface isn't a conversation—it's an interface so frictionless that the user barely realizes an AI is doing the heavy lifting.
Discussion Question
Where in your product has conversational AI actually reduced task-completion time, and where did it just add an unnecessary layer of typing?
CTA (Join Product, UX & Design)
Join the Product, UX & Design community to debate emerging interaction patterns, dissect real-world design systems, and build intuitive, human-centered products.The Conversational Crutch: Why Slapping a Chatbox on Your SaaS Is Lazy Product Design As generative AI toolkits became plug-and-play, product roadmaps fell victim to a massive industry misconception: ❌ The Myth: "Chat is the universal interface of the future. Replacing menus, forms, and control panels with an open prompt box eliminates UI complexity and gives users ultimate flexibility." ✅ The Reality: An empty prompt box forces maximum cognitive load onto the user. It trades clear affordances for a blank-canvas paralysis, slow typing speeds, and non-deterministic UX. Why the "Everything-as-a-Chat" Pattern Fails: The Death of Discoverability: Traditional graphical user interfaces (GUIs) communicate what is possible through visible affordances—buttons, sliders, toggles, and filters. A blinking cursor in a chatbox tells the user nothing about system capabilities, boundary limits, or failure states. The Prompt Tax (Input Friction): Pointing and clicking takes 200 milliseconds. Typing a structured, context-rich prompt takes 30 seconds. Forcing users to articulate routine operations in natural language slows down workflows rather than accelerating them. Loss of Spatial State & Correction Loops: In a GUI, tweaking a single parameter (like a date range or toggle) is an instant, localized adjustment. In a conversational interface, adjusting one variable requires re-prompting, reading a full response stream, and hoping the model doesn't drift or alter previous variables. The Better Pattern: Hybrid Contextual Micro-Interactions World-class AI UX embeds intelligence directly into existing UI paradigms rather than segregating it into a floating chat drawer: Generative Affordances & Inline Controls: Instead of asking the user to prompt, anticipate their next step. Offer contextual AI suggestions as inline chips, hover-state shortcuts, or dynamic form pre-fills that can be accepted with a single click. Bi-Directional Canvas UX: Keep the artifact (document, spreadsheet, canvas, or dashboard) front-and-center. Let the AI manipulate the canvas directly while keeping familiar UI levers (sliders, diff reviews, undo buttons) intact for tactile human control. Scaffolding Over Blank Inputs: Replace the open prompt box with structured scaffolding—pre-built system templates, parameter slot-filling, and guided prompt builders that constrain the solution space. The takeaway: Great UX is about reducing cognitive overhead, not showcasing model capabilities. The most powerful AI interface isn't a conversation—it's an interface so frictionless that the user barely realizes an AI is doing the heavy lifting. Discussion Question Where in your product has conversational AI actually reduced task-completion time, and where did it just add an unnecessary layer of typing? CTA (Join Product, UX & Design) Join the Product, UX & Design community to debate emerging interaction patterns, dissect real-world design systems, and build intuitive, human-centered products.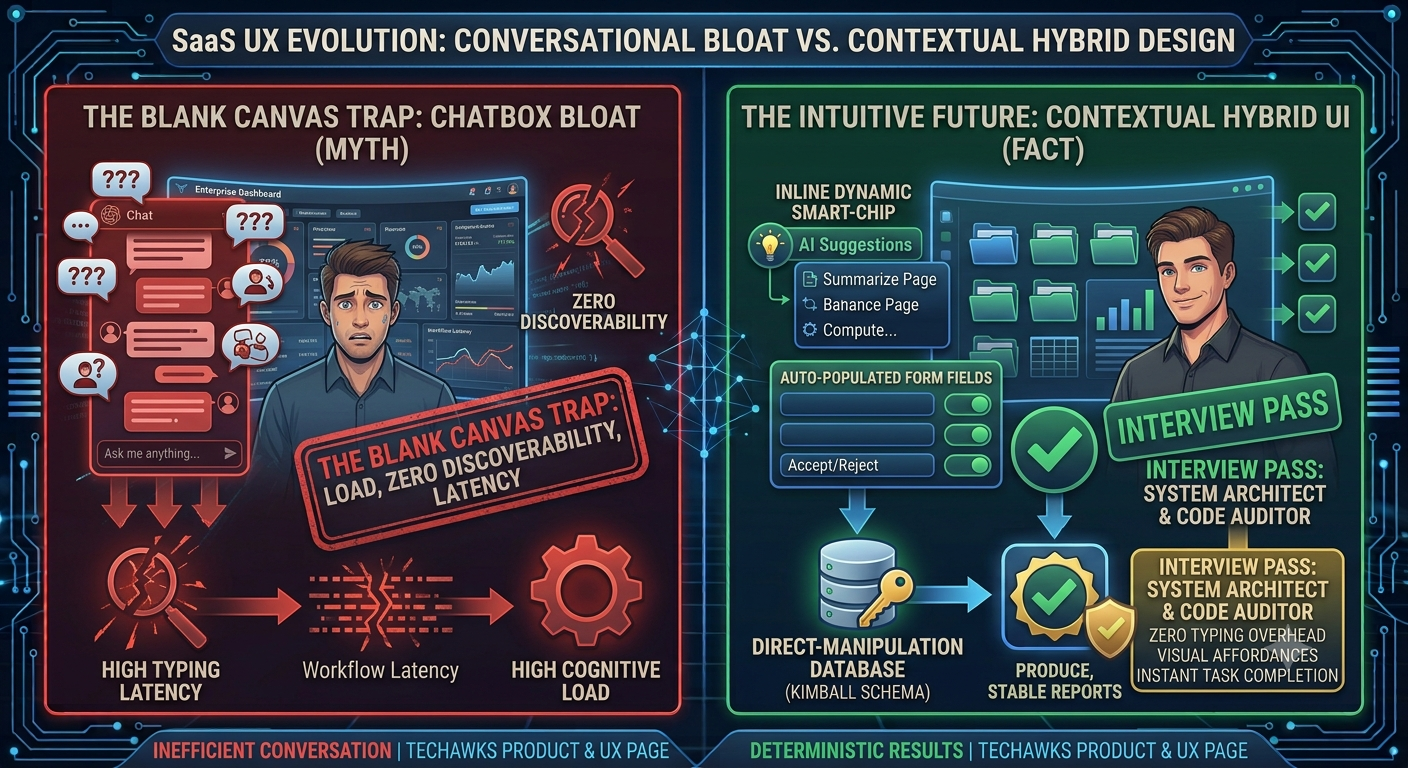 0 Comments 0 Shares 120 Views 0 Reviews
-
The Lakehouse Illusion: Why Open Table Formats Won’t Fix Broken Data Modeling
As open lakehouse architectures become the enterprise standard, a pervasive misconception has spread across analytics teams:
❌ The Myth: "Just dump raw Parquet into an open table format like Apache Iceberg. With ACID transactions, hidden partitioning, and zero-copy engine interoperability, you don't need dimensional modeling or structured semantic layers anymore."
✅ The Reality: Open formats solve file-level coordination and catalog lock-in, but querying unmodeled data lakes creates compute-heavy runtimes, runaway cloud bills, and conflicting business metrics.
Where the "Format Fixes All" Mindset Fails:
The Join Explosion Tax: Open table formats track file manifests and column min/max statistics with high efficiency. However, when analysts run 8-way joins across raw nested event logs to calculate simple churn rates, the underlying compute engine (whether Trino, DuckDB, or Snowflake) still burns through memory and network bandwidth shuffling unindexed petabytes.
Metadata Bloat & Small File Creep: Without disciplined compaction and scheduled snapshot expiration, append-heavy streaming pipelines cause metadata trees to explode. Query engines end up spending more time traversing JSON/Avro manifest lists during scan planning than reading actual Parquet records.
Metric Drift Across Engines: The promise of open formats is engine neutrality (e.g., query the same table via Spark, DuckDB, or a cloud warehouse). But without a standardized semantic layer on top, three different teams will write three variations of the same business metric across those engines—returning conflicting numbers to leadership.
The Analytics Architecture That Actually Scales:
Decouple Storage Standards from Semantic Truth: Use open formats (like Iceberg) to prevent vendor lock-in at the storage layer, but enforce strict Medallion principles (Bronze >>> Silver >>> Gold) with curated dimensional schemas (Kimball star schemas or One Big Table designs) for the presentation layer.
utomate Storage Hygiene: Schedule recurring background compaction (bin-packing small Parquet files into optimal 128MB–512MB chunks) and purge historical snapshots to keep manifest scan planning O(1).
Enforce Upstream Data Contracts: Catch schema drift, null violations, and type mismatches at the ingestion boundary before malformed records pollute downstream silver and gold layers.
The takeaway: A high-performance storage format only changes how data is stored and committed; it doesn't change what questions your business can ask efficiently. Without structured modeling, you haven't built a modern lakehouse—you've just organized your data swamp.
Discussion Question
Is your team managing lakehouse performance at the storage level (file compaction, partitioning) or through upstream data modeling and semantic layers? Where do your bottlenecks hit hardest?
CTA (Join Data Science & Analytics)
Join the Data Science & Analytics community to compare modern lakehouse architectures, master advanced SQL/modeling patterns, and build reliable analytics pipelines alongside global practitioners.The Lakehouse Illusion: Why Open Table Formats Won’t Fix Broken Data Modeling As open lakehouse architectures become the enterprise standard, a pervasive misconception has spread across analytics teams: ❌ The Myth: "Just dump raw Parquet into an open table format like Apache Iceberg. With ACID transactions, hidden partitioning, and zero-copy engine interoperability, you don't need dimensional modeling or structured semantic layers anymore." ✅ The Reality: Open formats solve file-level coordination and catalog lock-in, but querying unmodeled data lakes creates compute-heavy runtimes, runaway cloud bills, and conflicting business metrics. Where the "Format Fixes All" Mindset Fails: The Join Explosion Tax: Open table formats track file manifests and column min/max statistics with high efficiency. However, when analysts run 8-way joins across raw nested event logs to calculate simple churn rates, the underlying compute engine (whether Trino, DuckDB, or Snowflake) still burns through memory and network bandwidth shuffling unindexed petabytes. Metadata Bloat & Small File Creep: Without disciplined compaction and scheduled snapshot expiration, append-heavy streaming pipelines cause metadata trees to explode. Query engines end up spending more time traversing JSON/Avro manifest lists during scan planning than reading actual Parquet records. Metric Drift Across Engines: The promise of open formats is engine neutrality (e.g., query the same table via Spark, DuckDB, or a cloud warehouse). But without a standardized semantic layer on top, three different teams will write three variations of the same business metric across those engines—returning conflicting numbers to leadership. The Analytics Architecture That Actually Scales: Decouple Storage Standards from Semantic Truth: Use open formats (like Iceberg) to prevent vendor lock-in at the storage layer, but enforce strict Medallion principles (Bronze >>> Silver >>> Gold) with curated dimensional schemas (Kimball star schemas or One Big Table designs) for the presentation layer. utomate Storage Hygiene: Schedule recurring background compaction (bin-packing small Parquet files into optimal 128MB–512MB chunks) and purge historical snapshots to keep manifest scan planning O(1). Enforce Upstream Data Contracts: Catch schema drift, null violations, and type mismatches at the ingestion boundary before malformed records pollute downstream silver and gold layers. The takeaway: A high-performance storage format only changes how data is stored and committed; it doesn't change what questions your business can ask efficiently. Without structured modeling, you haven't built a modern lakehouse—you've just organized your data swamp. Discussion Question Is your team managing lakehouse performance at the storage level (file compaction, partitioning) or through upstream data modeling and semantic layers? Where do your bottlenecks hit hardest? CTA (Join Data Science & Analytics) Join the Data Science & Analytics community to compare modern lakehouse architectures, master advanced SQL/modeling patterns, and build reliable analytics pipelines alongside global practitioners.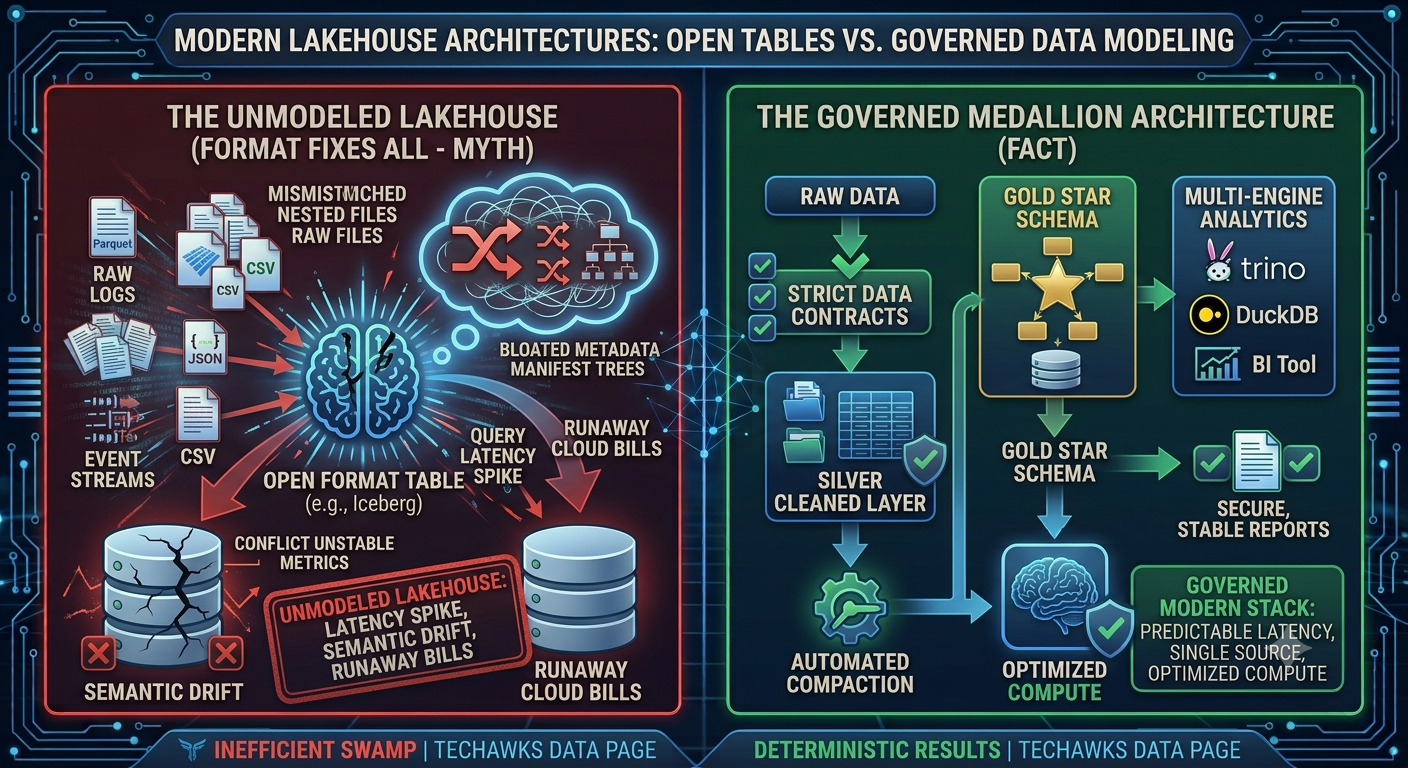 0 Comments 0 Shares 107 Views 0 Reviews
-
The MFA Fallacy: Why Adversary-in-the-Middle (AiTM) Attacks Bypass 2FA Without Guessing a Single Code
Across security operations and everyday engineering, a dangerous sense of false safety remains:
❌ The Myth: "As long as an account has MFA enabled—whether via SMS, an authenticator app, or push approvals—credentials cannot be phished."
✅ The Reality: Standard MFA protects against static credential replay, but it offers zero native defense against Adversary-in-the-Middle (AiTM) proxy phishing and session token theft.
How AiTM Phishing Bypasses MFA in Real Time:
The Reverse Proxy Interception: Instead of serving a static fake page, toolkits (such as Evilginx) sit transparently between the victim and the legitimate authentication server.
Real Authentication Execution: The victim enters their username, password, and real one-time code (OTP). The proxy immediately forwards these inputs to the real service, which validates them and completes authentication.
Session Cookie Exfiltration: Upon successful login, the legitimate platform issues an HTTP session/bearer cookie back to the client. The AiTM proxy intercepts this token, stores it, and sends the user to a benign landing page.
Instant Session Hijacking: The attacker imports the stolen session token directly into their browser. Because the service sees a valid, authenticated session cookie, no password or MFA prompt is ever triggered, giving the attacker immediate access to your inbox, cloud consoles, or internal infrastructure.
Defensive Architecture: How to Protect Sessions
Enforce FIDO2 / Passkeys (WebAuthn): Hardware security keys (e.g., YubiKeys) and platform passkeys use origin-bound cryptographic handshakes. The browser automatically checks the domain name; if the URL points to a proxy rather than the genuine origin, the key simply refuses to sign the authentication challenge.
Cryptographic Token Binding (DPoP): Implement Demonstrating Proof-of-Possession (DPoP) or mTLS token binding for APIs and cloud sessions. This binds the bearer token to a specific client private key, ensuring a stolen cookie is useless on an attacker's machine.
Continuous Conditional Access: Shift evaluation from point-in-time logins to continuous session monitoring. Configure Identity Providers (IdPs) to instantly revoke active sessions when device health, IP subnet, or behavioral risk profiles abruptly drift mid-session.
The takeaway: Authentication isn't a one-time transaction at the door—it's an ongoing state. If your authentication tokens aren't cryptographically bound to the physical hardware, your MFA is only as secure as the cookie in your browser.
Discussion Question
Has your organization made the jump to phishing-resistant WebAuthn/FIDO2 hardware tokens, or are you still relying on time-based one-time passwords (TOTP) and push notifications?
CTA (Join Cybersecurity & Ethical Hacking)
Join the Cybersecurity & Ethical Hacking community to dissect real-world adversary tradecraft, master defensive threat hunting, and elevate your enterprise security architecture.The MFA Fallacy: Why Adversary-in-the-Middle (AiTM) Attacks Bypass 2FA Without Guessing a Single Code Across security operations and everyday engineering, a dangerous sense of false safety remains: ❌ The Myth: "As long as an account has MFA enabled—whether via SMS, an authenticator app, or push approvals—credentials cannot be phished." ✅ The Reality: Standard MFA protects against static credential replay, but it offers zero native defense against Adversary-in-the-Middle (AiTM) proxy phishing and session token theft. How AiTM Phishing Bypasses MFA in Real Time: The Reverse Proxy Interception: Instead of serving a static fake page, toolkits (such as Evilginx) sit transparently between the victim and the legitimate authentication server. Real Authentication Execution: The victim enters their username, password, and real one-time code (OTP). The proxy immediately forwards these inputs to the real service, which validates them and completes authentication. Session Cookie Exfiltration: Upon successful login, the legitimate platform issues an HTTP session/bearer cookie back to the client. The AiTM proxy intercepts this token, stores it, and sends the user to a benign landing page. Instant Session Hijacking: The attacker imports the stolen session token directly into their browser. Because the service sees a valid, authenticated session cookie, no password or MFA prompt is ever triggered, giving the attacker immediate access to your inbox, cloud consoles, or internal infrastructure. Defensive Architecture: How to Protect Sessions Enforce FIDO2 / Passkeys (WebAuthn): Hardware security keys (e.g., YubiKeys) and platform passkeys use origin-bound cryptographic handshakes. The browser automatically checks the domain name; if the URL points to a proxy rather than the genuine origin, the key simply refuses to sign the authentication challenge. Cryptographic Token Binding (DPoP): Implement Demonstrating Proof-of-Possession (DPoP) or mTLS token binding for APIs and cloud sessions. This binds the bearer token to a specific client private key, ensuring a stolen cookie is useless on an attacker's machine. Continuous Conditional Access: Shift evaluation from point-in-time logins to continuous session monitoring. Configure Identity Providers (IdPs) to instantly revoke active sessions when device health, IP subnet, or behavioral risk profiles abruptly drift mid-session. The takeaway: Authentication isn't a one-time transaction at the door—it's an ongoing state. If your authentication tokens aren't cryptographically bound to the physical hardware, your MFA is only as secure as the cookie in your browser. Discussion Question Has your organization made the jump to phishing-resistant WebAuthn/FIDO2 hardware tokens, or are you still relying on time-based one-time passwords (TOTP) and push notifications? CTA (Join Cybersecurity & Ethical Hacking) Join the Cybersecurity & Ethical Hacking community to dissect real-world adversary tradecraft, master defensive threat hunting, and elevate your enterprise security architecture.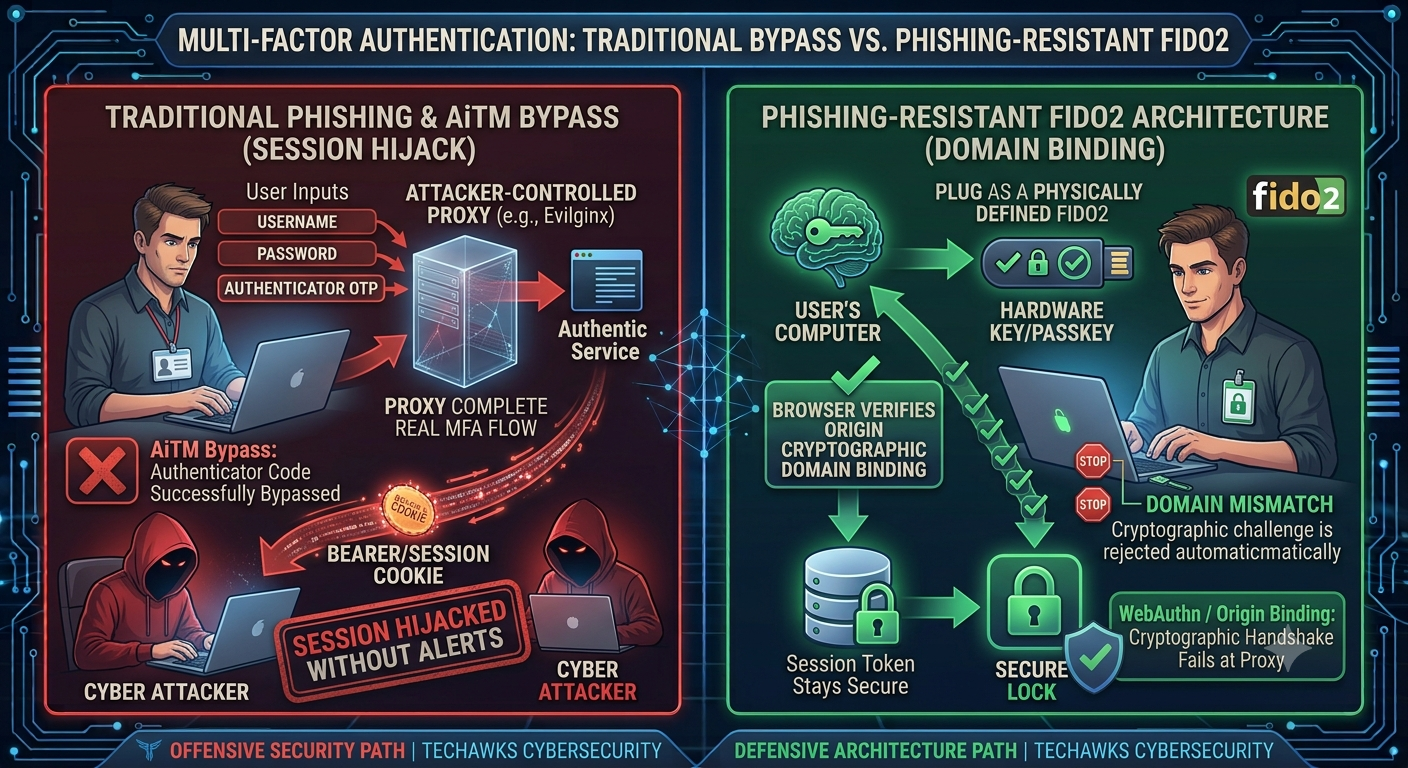 0 Comments 0 Shares 152 Views 0 Reviews
-
The "Autocomplete Trap": Why Passing Your Programming Lab Isn't the Same as Learning to Code
Computer science students and self-taught learners are falling into a deceptive educational trap:
❌ The Myth: "Using an AI assistant to write functions and fix runtime bugs helps me learn faster because I see working code immediately."
✅ The Reality: Completing an assignment quickly is not evidence of learning. Empirical research reveals that heavy AI code generation leads to cognitive offloading—students complete tasks with higher initial scores, but perform up to nearly two letter grades lower on independent conceptual and debugging tests.
Why Copy-Pasting AI Code Blocks Deep Learning
The Short-Circuit of the "Generation Effect": Long-term retention requires your brain to actively retrieve principles from memory. When an AI provides the solution, your brain switches to passive recognition, mistaking ease of reading for genuine comprehension.
Atrophied Debugging Intuition: Research shows the steepest drop in unaided student performance happens in debugging. Stepping through a stack trace, forming hypotheses, and isolating a broken pointer are where core systems knowledge is forged. Offloading debugging to a chatbot eliminates the very feedback loop that makes you an engineer.
The Blind Spot for Architecture: AI defaults to isolated, localized fixes. Relying on it prevents students from grasping how modules interact, how memory is allocated, and how algorithmic complexity scales.
How High-Performing Students Use AI as a Socratic Tutor
Stop treating AI like an oracle that produces the final answer. Turn it into a personal professor:
The "Don't Give Me the Code" Prompt: Before asking a question, explicitly instruct the model: "Explain the concept or bug conceptually using pseudocode and analogies, but do not write any executable code for me."
The Rubber-Duck Inversion: Write the code yourself, then paste it into the AI and prompt: "Critique my time/space complexity and point out potential edge-case failures without fixing them."
The Pen-and-Paper Check: Before typing a single line into your IDE, trace your logic on paper with sample inputs. If you cannot trace your algorithm manually, you are relying on autocomplete rather than understanding.
The takeaway: Anyone can prompt a model to write a binary search. The industry pays engineers who understand memory layouts, race conditions, and edge cases when the AI gets it wrong.
Discussion Question
When you run into a compiler error or logic bug, what is your immediate instinct—step through the debugger manually, or paste the error directly into an AI chat?
CTA (Join Students in Tech)
Join the Students in Tech community to exchange study roadmaps, collaborate on genuine open-source projects, and build rock-solid computer science fundamentals.The "Autocomplete Trap": Why Passing Your Programming Lab Isn't the Same as Learning to Code Computer science students and self-taught learners are falling into a deceptive educational trap: ❌ The Myth: "Using an AI assistant to write functions and fix runtime bugs helps me learn faster because I see working code immediately." ✅ The Reality: Completing an assignment quickly is not evidence of learning. Empirical research reveals that heavy AI code generation leads to cognitive offloading—students complete tasks with higher initial scores, but perform up to nearly two letter grades lower on independent conceptual and debugging tests. Why Copy-Pasting AI Code Blocks Deep Learning The Short-Circuit of the "Generation Effect": Long-term retention requires your brain to actively retrieve principles from memory. When an AI provides the solution, your brain switches to passive recognition, mistaking ease of reading for genuine comprehension. Atrophied Debugging Intuition: Research shows the steepest drop in unaided student performance happens in debugging. Stepping through a stack trace, forming hypotheses, and isolating a broken pointer are where core systems knowledge is forged. Offloading debugging to a chatbot eliminates the very feedback loop that makes you an engineer. The Blind Spot for Architecture: AI defaults to isolated, localized fixes. Relying on it prevents students from grasping how modules interact, how memory is allocated, and how algorithmic complexity scales. How High-Performing Students Use AI as a Socratic Tutor Stop treating AI like an oracle that produces the final answer. Turn it into a personal professor: The "Don't Give Me the Code" Prompt: Before asking a question, explicitly instruct the model: "Explain the concept or bug conceptually using pseudocode and analogies, but do not write any executable code for me." The Rubber-Duck Inversion: Write the code yourself, then paste it into the AI and prompt: "Critique my time/space complexity and point out potential edge-case failures without fixing them." The Pen-and-Paper Check: Before typing a single line into your IDE, trace your logic on paper with sample inputs. If you cannot trace your algorithm manually, you are relying on autocomplete rather than understanding. The takeaway: Anyone can prompt a model to write a binary search. The industry pays engineers who understand memory layouts, race conditions, and edge cases when the AI gets it wrong. Discussion Question When you run into a compiler error or logic bug, what is your immediate instinct—step through the debugger manually, or paste the error directly into an AI chat? CTA (Join Students in Tech) Join the Students in Tech community to exchange study roadmaps, collaborate on genuine open-source projects, and build rock-solid computer science fundamentals.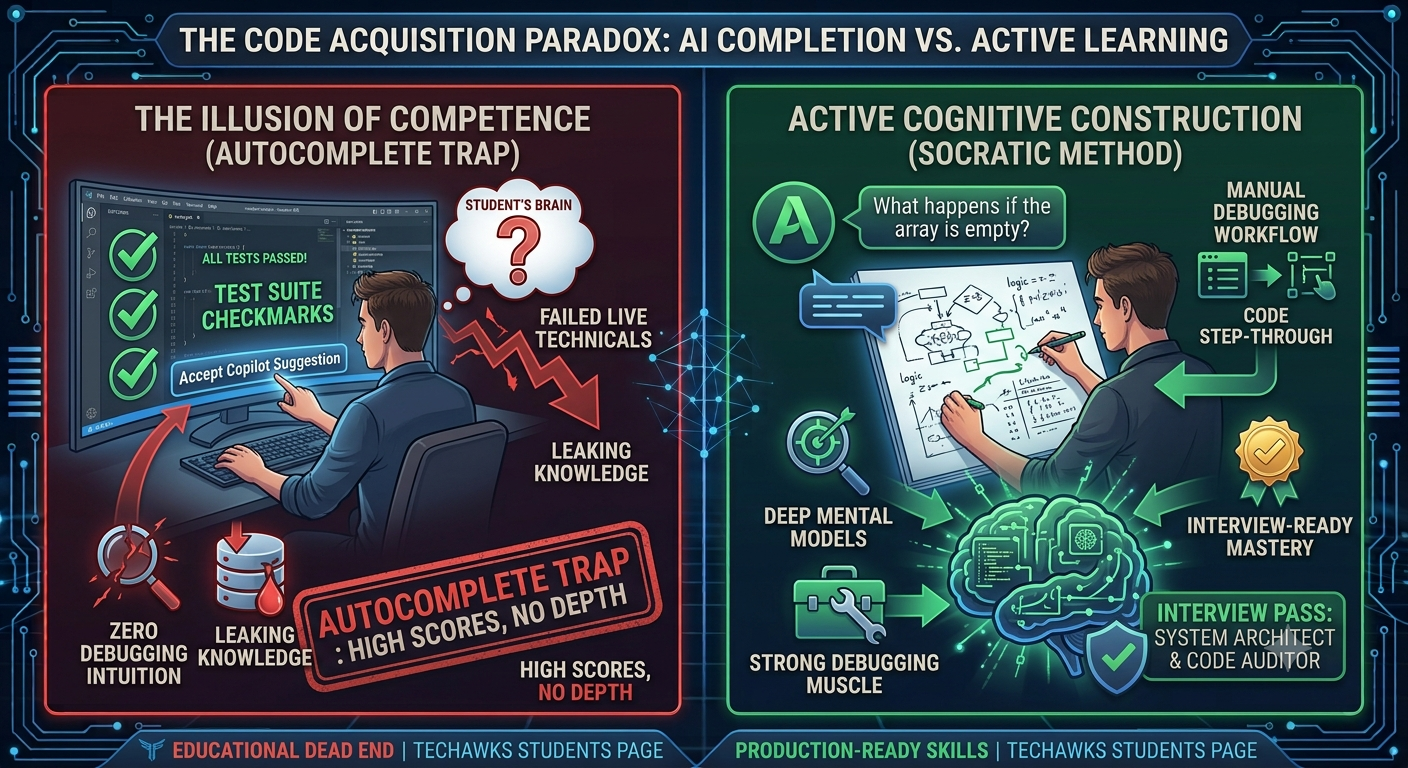 0 Comments 0 Shares 89 Views 0 Reviews
-
The Flat-Rate Trap: Why Classic SaaS Pricing Is Silently Bankrupting AI Startups
Founders raised on the playbook of the 2010s are running into a structural wall:
❌ The Myth: "Charge a flat $30 to $50 per-seat monthly subscription. Software has near-zero marginal cost, so more daily active users automatically equals higher margins and enterprise valuation."
✅ The Reality: In traditional SaaS, the marginal cost of serving user number 10,000 was effectively zero. In AI-native applications, growth without metered unit economics scales cost faster than revenue. Power users don't boost your bottom line—they erode your gross margins.
The Anatomy of the Margin Collapse:
The Variable Cost-of-Goods-Sold (COGS) Reality: In conventional B2B software, hosting and infrastructure make up roughly 10% to 15% of revenue, leaving gross margins of 80% to 85%. In AI-native products, inference compute, token egress, embedding lookups, and multi-agent loops sit directly inside COGS.
The Power-User Inversion: On a flat-rate tier, casual users subsidize power users. But as your core audience matures, a customer running complex multi-step agent workflows can easily cost $60/month in API/GPU compute against a $30/month subscription—turning your most engaged champions into your largest financial liabilities.
The Valuation Penalty: Late-seed and Series A investors evaluate gross margins above all else. Startups posting 40% gross margins get valued like low-margin IT services rather than high-multiple software companies.
How High-Defensibility Founders Price Today:
Decouple Platform Access from Execution Units: Move to a hybrid model. Charge a predictable base subscription for UI, workflow integrations, and seat permissions, paired with credit-based or metered billing for high-compute model invocations.
Price by Outcome, Not Just Per-Seat: Instead of billing per user seat, align pricing with delivered business units (e.g., contracts audited, tickets resolved, database schemas migrated). This anchors price to real ROI rather than raw token usage.
Implement Tiered Inference Routing: Don't route simple queries to high-cost reasoning models. Dynamically downgrade casual extraction and classification to small open-weight models, preserving expensive inference budgets only for complex reasoning tasks.
The takeaway: Building a defensible startup isn't just about owning proprietary data—it's about surviving your own product engagement. If your unit economics can't survive a power user, your business model is a liability disguised as traction.
Discussion Question
What does your gross margin look like after factoring in model inference and GPU compute? Have you shifted to hybrid or credit-based pricing, or are you still relying on flat per-seat subscriptions?
CTA (Join Startup Founders & Entrepreneurs)
Join the Startup Founders & Entrepreneurs community to benchmark unit economics, dissect real AI pricing strategies, and build defensible, capital-efficient businesses.The Flat-Rate Trap: Why Classic SaaS Pricing Is Silently Bankrupting AI Startups Founders raised on the playbook of the 2010s are running into a structural wall: ❌ The Myth: "Charge a flat $30 to $50 per-seat monthly subscription. Software has near-zero marginal cost, so more daily active users automatically equals higher margins and enterprise valuation." ✅ The Reality: In traditional SaaS, the marginal cost of serving user number 10,000 was effectively zero. In AI-native applications, growth without metered unit economics scales cost faster than revenue. Power users don't boost your bottom line—they erode your gross margins. The Anatomy of the Margin Collapse: The Variable Cost-of-Goods-Sold (COGS) Reality: In conventional B2B software, hosting and infrastructure make up roughly 10% to 15% of revenue, leaving gross margins of 80% to 85%. In AI-native products, inference compute, token egress, embedding lookups, and multi-agent loops sit directly inside COGS. The Power-User Inversion: On a flat-rate tier, casual users subsidize power users. But as your core audience matures, a customer running complex multi-step agent workflows can easily cost $60/month in API/GPU compute against a $30/month subscription—turning your most engaged champions into your largest financial liabilities. The Valuation Penalty: Late-seed and Series A investors evaluate gross margins above all else. Startups posting 40% gross margins get valued like low-margin IT services rather than high-multiple software companies. How High-Defensibility Founders Price Today: Decouple Platform Access from Execution Units: Move to a hybrid model. Charge a predictable base subscription for UI, workflow integrations, and seat permissions, paired with credit-based or metered billing for high-compute model invocations. Price by Outcome, Not Just Per-Seat: Instead of billing per user seat, align pricing with delivered business units (e.g., contracts audited, tickets resolved, database schemas migrated). This anchors price to real ROI rather than raw token usage. Implement Tiered Inference Routing: Don't route simple queries to high-cost reasoning models. Dynamically downgrade casual extraction and classification to small open-weight models, preserving expensive inference budgets only for complex reasoning tasks. The takeaway: Building a defensible startup isn't just about owning proprietary data—it's about surviving your own product engagement. If your unit economics can't survive a power user, your business model is a liability disguised as traction. Discussion Question What does your gross margin look like after factoring in model inference and GPU compute? Have you shifted to hybrid or credit-based pricing, or are you still relying on flat per-seat subscriptions? CTA (Join Startup Founders & Entrepreneurs) Join the Startup Founders & Entrepreneurs community to benchmark unit economics, dissect real AI pricing strategies, and build defensible, capital-efficient businesses.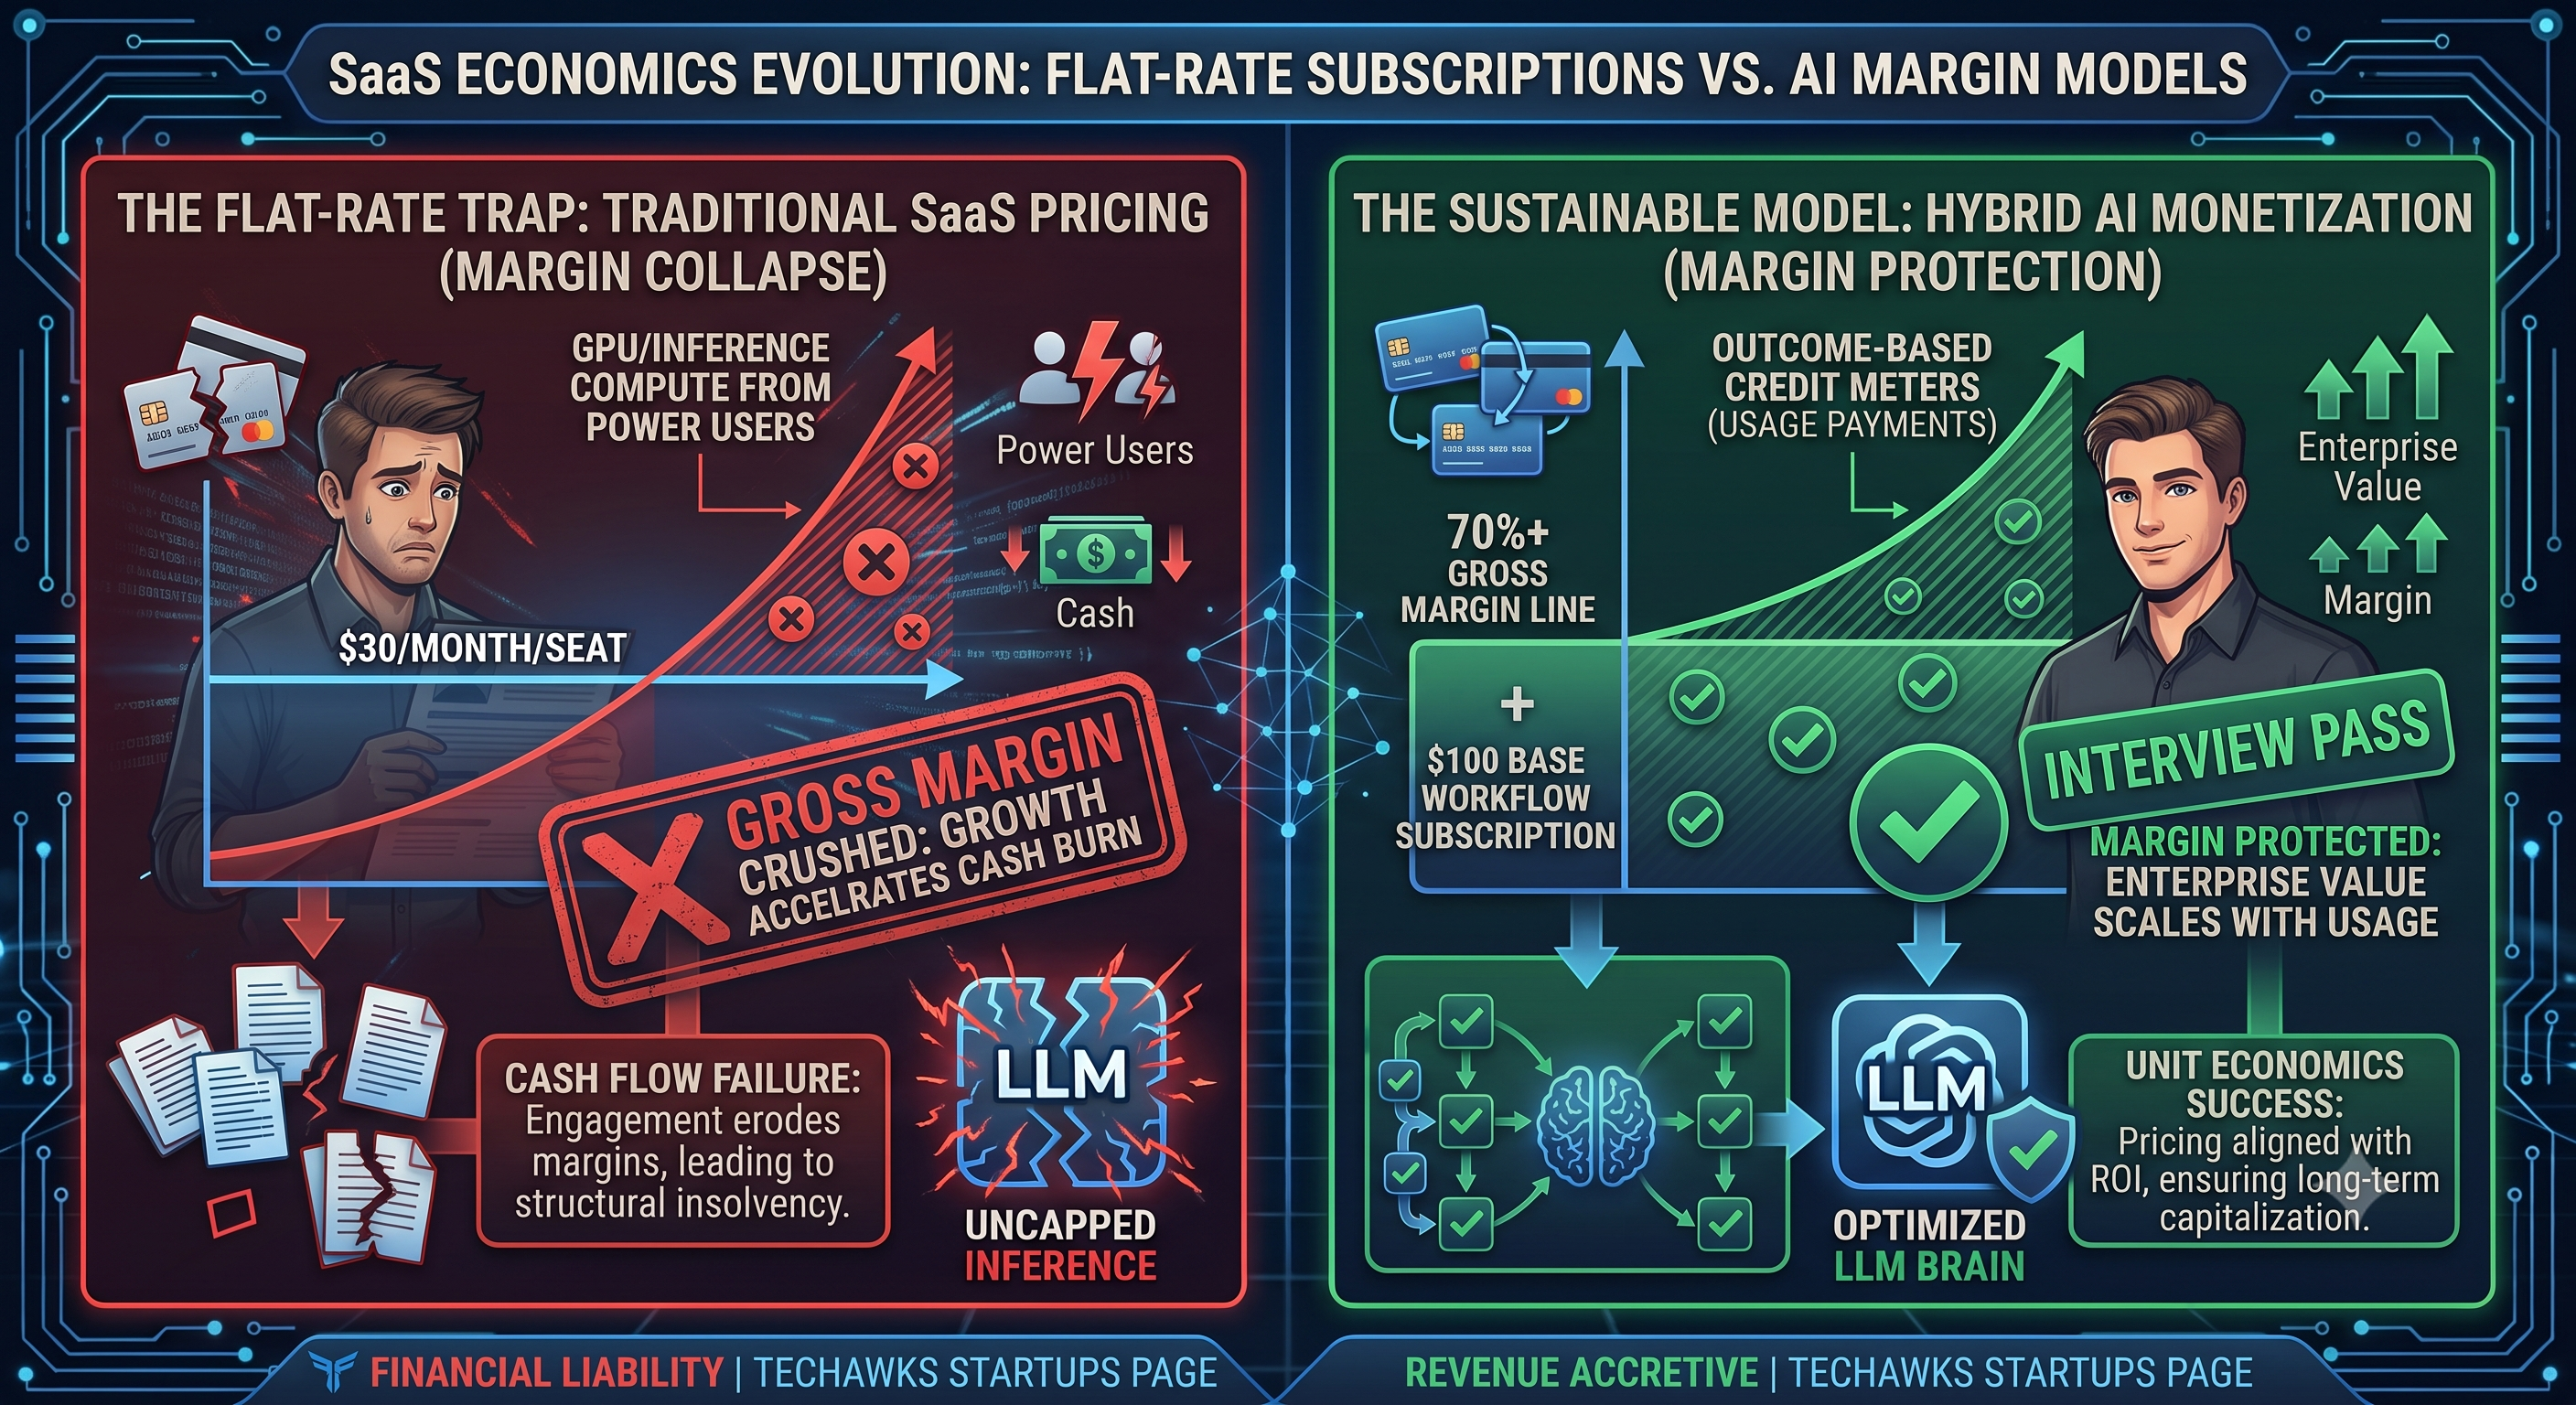 0 Comments 0 Shares 41 Views 0 Reviews
-
The Junior Developer Paradox: Why AI Code Generation Isn't Eliminating Software Jobs—It’s Changing What Counts as Experience
Job boards and tech forums are flooded with demoralizing doom-posting:
❌ The Myth: "Companies aren't hiring developers anymore because LLMs write code faster. Learning syntax and building portfolio projects is officially obsolete."
✅ The Reality: Hiring hasn’t stopped; it has bifurcated. Because AI tools now generate baseline syntax in seconds, companies no longer evaluate candidates on how fast they write code—they evaluate candidates on verification, architectural judgment, and security vigilance.
The Barbell Market: What Hiring Teams Actually Need
When an LLM can scaffold a boilerplate full-stack app in three minutes, shipping raw code is no longer a differentiator. However, industry security audits show that nearly 45% of AI-generated code contains known vulnerabilities, edge-case hallucinations, or memory leaks.
Engineering leaders aren't looking for coders who simply prompt and paste. They are hunting for candidates who act as the critical review layer:
Failure-Domain Awareness: Can you look at an AI-generated microservice and immediately spot the missing rate limits, uncaught database connection drops, or SQL injection vectors?
System Architecture & Tradeoffs: Can you explain why an event-driven queue fits a workload better than a polling REST pattern, rather than simply accepting whatever architecture an LLM defaults to?
Observability & Debugging Mastery: Any beginner can ask an AI to generate an API; a production-ready engineer understands how to trace a distributed latency bottleneck using telemetry, logs, and profiling tools when things break in staging.
How to Re-Engineer Your Resume & Portfolio Right Now
Retire Generic Scaffolding Projects: Stop submitting generic clones (e.g., standard Todo apps, basic e-commerce templates). Interviewers know AI wrote 90% of it.
Showcase the "Why" and the "Fix": Document your pull requests with deep architecture explanations: "Here is why the initial implementation failed at 5,000 concurrent requests, and how I refactored the database indexing and connection pool."
Highlight Systems Engineering: Emphasize integration testing, CI/CD pipeline configuration, Docker containerization, and automated schema validation. These are the skills hiring managers pay a premium for.
The takeaway: AI makes writing boilerplate free. That means your value as a job seeker lies entirely in your engineering judgment, code skepticism, and system design.
Discussion Question
What is your biggest roadblock in technical interviews right now—passing automated screening filters, or proving architectural depth beyond syntax?
CTA (Join Tech Jobs & Opportunities)
Join the Tech Jobs & Opportunities community to access verified openings, resume teardowns, and interview prep designed for today's technical hiring landscape.The Junior Developer Paradox: Why AI Code Generation Isn't Eliminating Software Jobs—It’s Changing What Counts as Experience Job boards and tech forums are flooded with demoralizing doom-posting: ❌ The Myth: "Companies aren't hiring developers anymore because LLMs write code faster. Learning syntax and building portfolio projects is officially obsolete." ✅ The Reality: Hiring hasn’t stopped; it has bifurcated. Because AI tools now generate baseline syntax in seconds, companies no longer evaluate candidates on how fast they write code—they evaluate candidates on verification, architectural judgment, and security vigilance. The Barbell Market: What Hiring Teams Actually Need When an LLM can scaffold a boilerplate full-stack app in three minutes, shipping raw code is no longer a differentiator. However, industry security audits show that nearly 45% of AI-generated code contains known vulnerabilities, edge-case hallucinations, or memory leaks. Engineering leaders aren't looking for coders who simply prompt and paste. They are hunting for candidates who act as the critical review layer: Failure-Domain Awareness: Can you look at an AI-generated microservice and immediately spot the missing rate limits, uncaught database connection drops, or SQL injection vectors? System Architecture & Tradeoffs: Can you explain why an event-driven queue fits a workload better than a polling REST pattern, rather than simply accepting whatever architecture an LLM defaults to? Observability & Debugging Mastery: Any beginner can ask an AI to generate an API; a production-ready engineer understands how to trace a distributed latency bottleneck using telemetry, logs, and profiling tools when things break in staging. How to Re-Engineer Your Resume & Portfolio Right Now Retire Generic Scaffolding Projects: Stop submitting generic clones (e.g., standard Todo apps, basic e-commerce templates). Interviewers know AI wrote 90% of it. Showcase the "Why" and the "Fix": Document your pull requests with deep architecture explanations: "Here is why the initial implementation failed at 5,000 concurrent requests, and how I refactored the database indexing and connection pool." Highlight Systems Engineering: Emphasize integration testing, CI/CD pipeline configuration, Docker containerization, and automated schema validation. These are the skills hiring managers pay a premium for. The takeaway: AI makes writing boilerplate free. That means your value as a job seeker lies entirely in your engineering judgment, code skepticism, and system design. Discussion Question What is your biggest roadblock in technical interviews right now—passing automated screening filters, or proving architectural depth beyond syntax? CTA (Join Tech Jobs & Opportunities) Join the Tech Jobs & Opportunities community to access verified openings, resume teardowns, and interview prep designed for today's technical hiring landscape.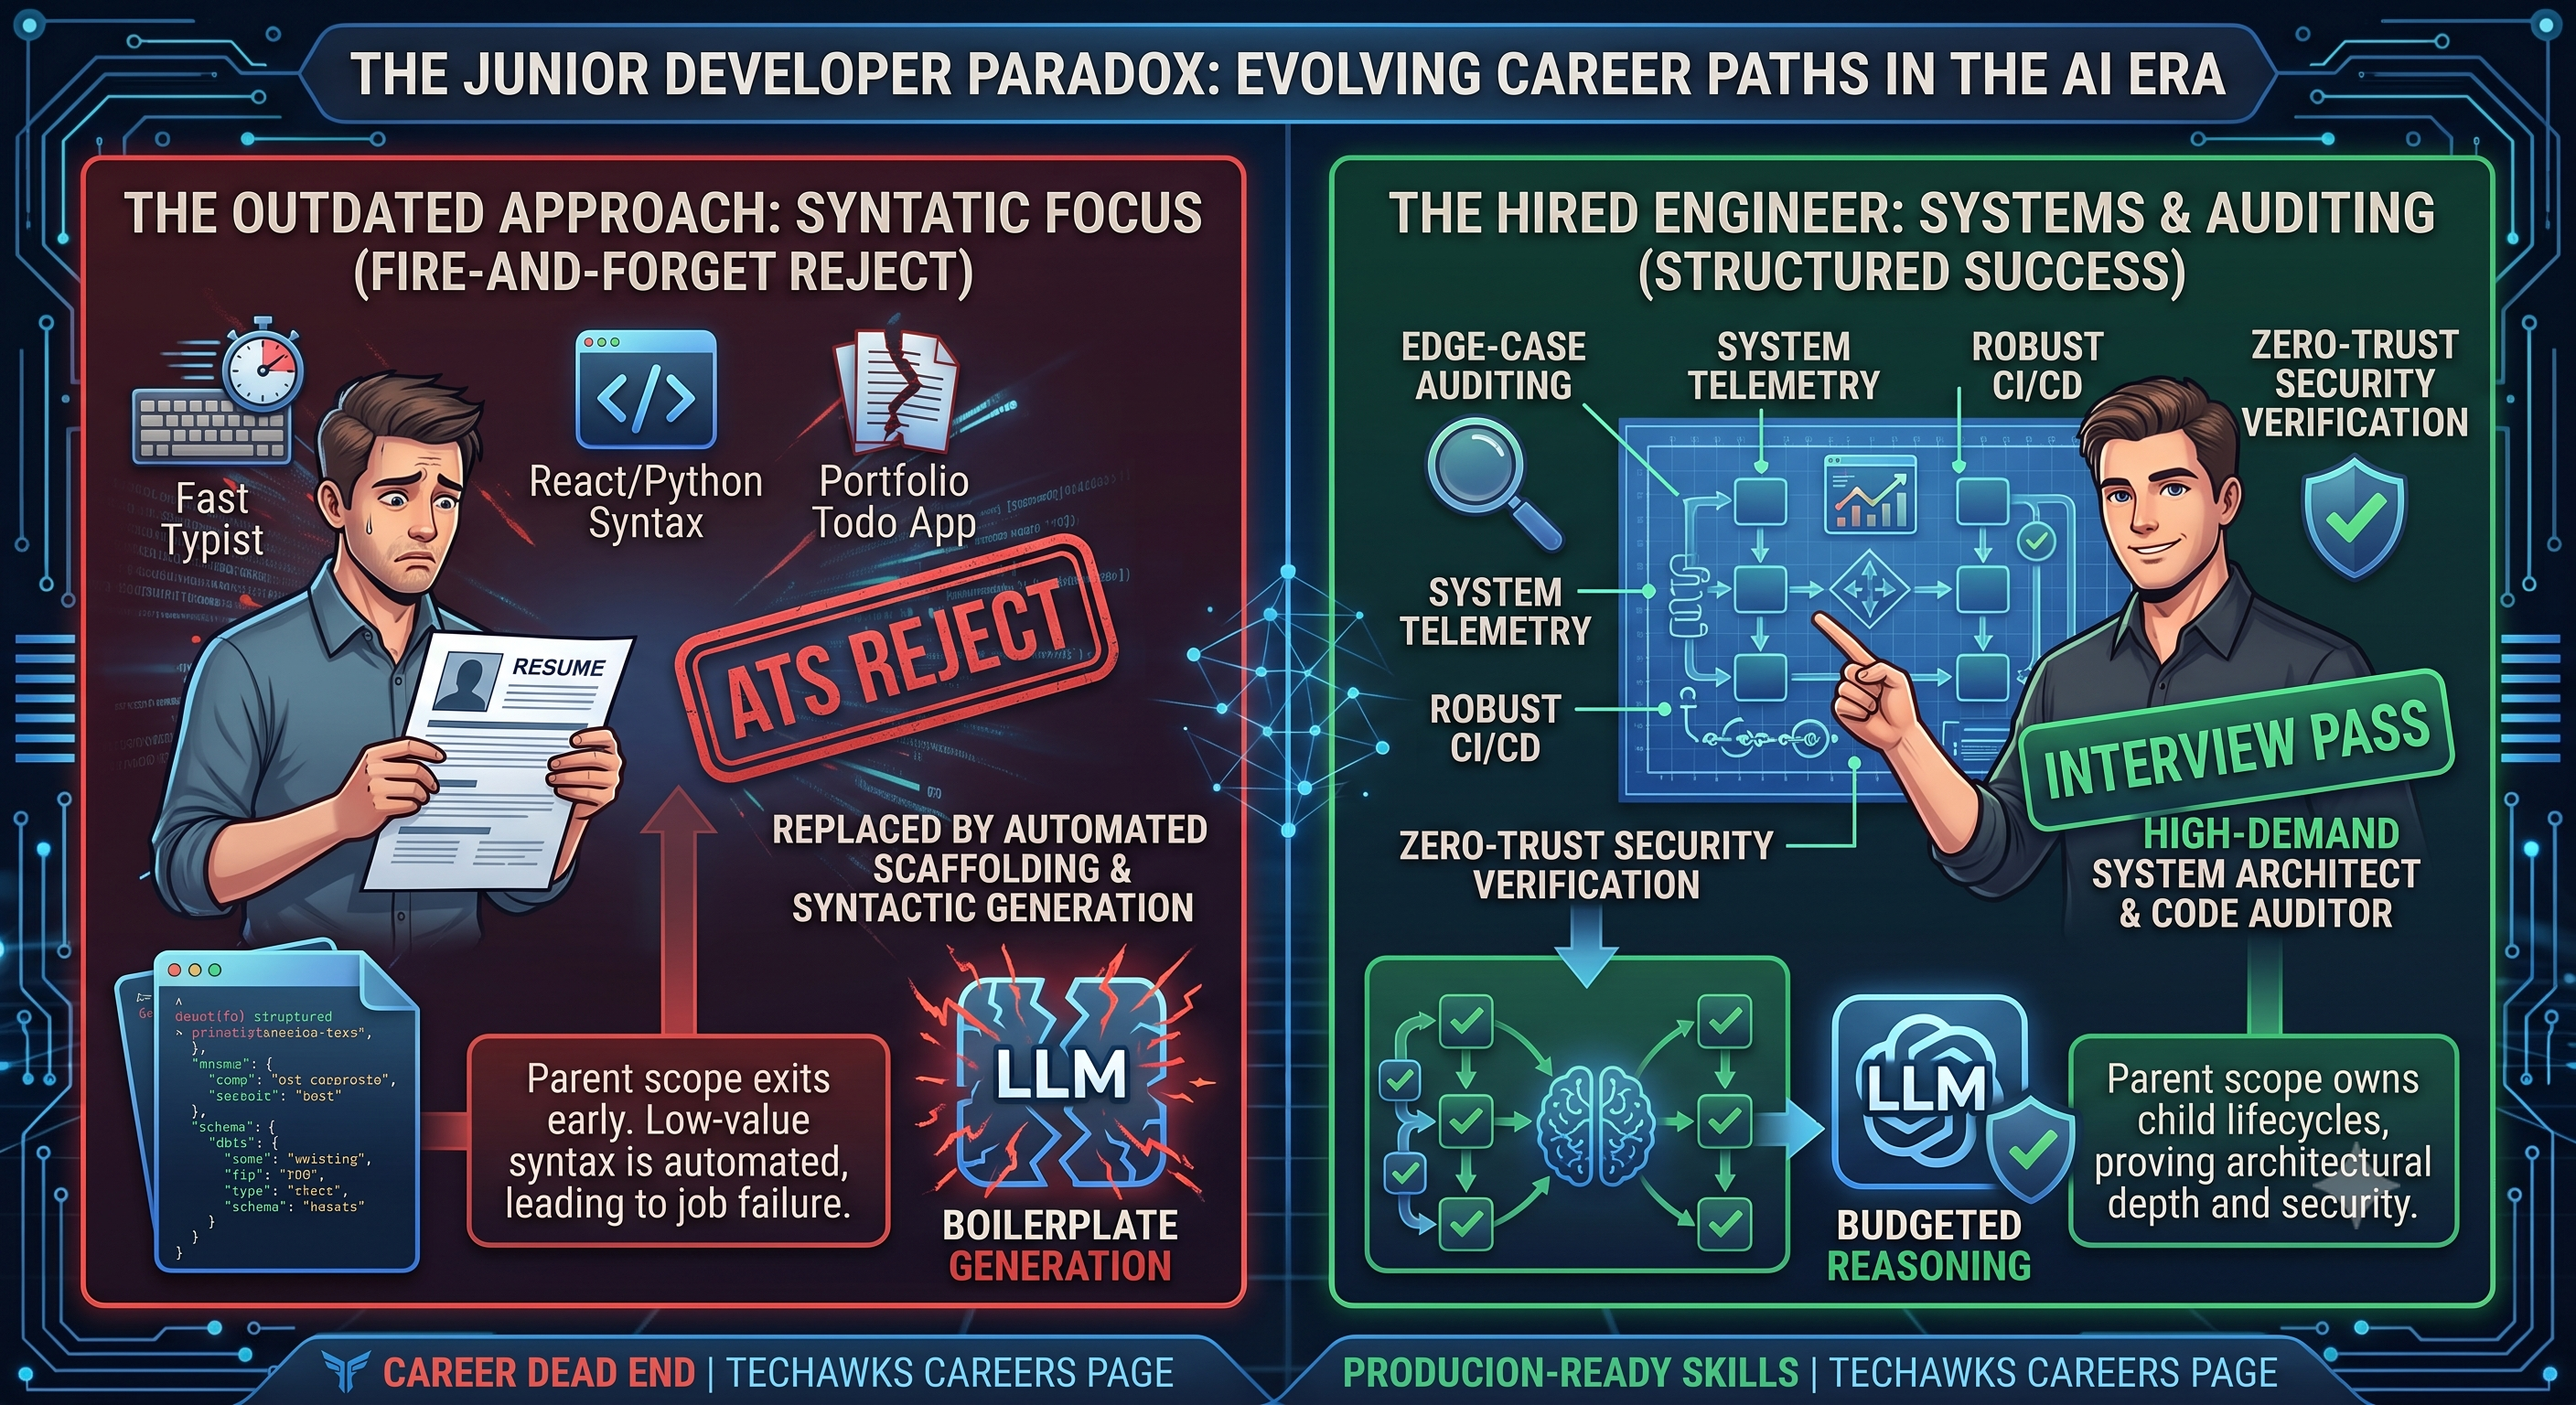 0 Comments 0 Shares 25 Views 0 Reviews
More Stories

 Arabic
 French
 Spanish
 Portuguese
 Deutsch
 Turkish
 Dutch
 Italiano
 Russian
 Romaian
 Portuguese (Brazil)
 Greek