• Cloud 3.0 & Data Sovereignty: The Architecture Defining Canadian Enterprise AI
    As Canadian technology leaders scale generative AI from experimental sandboxes to production, data sovereignty is no longer just a policy checklist—it has become a core distributed systems problem.


    Under Canadian privacy frameworks (PIPEDA, Quebec's Law 25, and evolving provincial standards), organizations face strict boundaries regarding extraterritorial data transit, residency, and third-party AI processing. The common architectural flaw? Relying on multi-tenant foundation model APIs that process user payloads outside Canadian borders, triggering automatic cross-border exposure.


    The Solution: The Sovereign AI Retrieval Pipeline
    To achieve compliant enterprise AI, engineering teams in Toronto, Montreal, Vancouver, and Calgary are adopting a localized Sovereign Retrieval-Augmented Generation (RAG) architecture:


    In-Region Compute & Isolation: Deploy workloads exclusively within Canadian cloud regions (e.g., ca-central-1) utilizing isolated VPCs and dedicated endpoint interfaces (PrivateLink) to block public internet traversal.


    Deterministic Data Sanitization: Integrate an inline PII/de-identification proxy (such as Microsoft Presidio or specialized local NLP filters) before vectorization occurs.


    Local Vector Embeddings & Storage: Generate embeddings in-region and store vector indexes in sovereign, self-hosted or tenant-isolated vector databases (e.g., Qdrant, Milvus, or pgvector on Canadian instances).


    On-Premise / Sovereign Inference Endpoints: Route retrieval payloads only to locally deployed open-weights models (via vLLM/Ollama in-region) or certified local cloud LLM instances with contractual zero-data-retention and geographic lockdown guarantees.


    Architecting for local data sovereignty protects your organization against regulatory audits while drastically reducing network egress latency for Canadian end users.


    Discussion Question
    Poll for Canadian Tech Leaders & Engineers:
    Where is your team currently hosting production AI inference and sensitive customer data?


    [ ] 100% In-Region Canadian Cloud (e.g., AWS ca-central-1 / Azure Canada Central)


    [ ] On-Premise / Private Hybrid Infrastructure


    [ ] Cross-Border Multi-Region Cloud Architecture


    [ ] Evaluating Sovereignty & Compliance Frameworks Right Now


    Drop your setup and biggest architectural bottleneck in the comments.


    CTA
    Join Techawks Canada — Connect with the top software engineers, architects, and tech leaders across the Canadian ecosystem. Follow the Techawks Canada page for daily deep dives into systems engineering, cloud architecture, and local tech standards.
    Cloud 3.0 & Data Sovereignty: The Architecture Defining Canadian Enterprise AI As Canadian technology leaders scale generative AI from experimental sandboxes to production, data sovereignty is no longer just a policy checklist—it has become a core distributed systems problem. Under Canadian privacy frameworks (PIPEDA, Quebec's Law 25, and evolving provincial standards), organizations face strict boundaries regarding extraterritorial data transit, residency, and third-party AI processing. The common architectural flaw? Relying on multi-tenant foundation model APIs that process user payloads outside Canadian borders, triggering automatic cross-border exposure. The Solution: The Sovereign AI Retrieval Pipeline To achieve compliant enterprise AI, engineering teams in Toronto, Montreal, Vancouver, and Calgary are adopting a localized Sovereign Retrieval-Augmented Generation (RAG) architecture: In-Region Compute & Isolation: Deploy workloads exclusively within Canadian cloud regions (e.g., ca-central-1) utilizing isolated VPCs and dedicated endpoint interfaces (PrivateLink) to block public internet traversal. Deterministic Data Sanitization: Integrate an inline PII/de-identification proxy (such as Microsoft Presidio or specialized local NLP filters) before vectorization occurs. Local Vector Embeddings & Storage: Generate embeddings in-region and store vector indexes in sovereign, self-hosted or tenant-isolated vector databases (e.g., Qdrant, Milvus, or pgvector on Canadian instances). On-Premise / Sovereign Inference Endpoints: Route retrieval payloads only to locally deployed open-weights models (via vLLM/Ollama in-region) or certified local cloud LLM instances with contractual zero-data-retention and geographic lockdown guarantees. Architecting for local data sovereignty protects your organization against regulatory audits while drastically reducing network egress latency for Canadian end users. Discussion Question Poll for Canadian Tech Leaders & Engineers: Where is your team currently hosting production AI inference and sensitive customer data? [ ] 100% In-Region Canadian Cloud (e.g., AWS ca-central-1 / Azure Canada Central) [ ] On-Premise / Private Hybrid Infrastructure [ ] Cross-Border Multi-Region Cloud Architecture [ ] Evaluating Sovereignty & Compliance Frameworks Right Now Drop your setup and biggest architectural bottleneck in the comments. CTA Join Techawks Canada — Connect with the top software engineers, architects, and tech leaders across the Canadian ecosystem. Follow the Techawks Canada page for daily deep dives into systems engineering, cloud architecture, and local tech standards.
    0 Commentarii 0 Distribuiri 26 Views 0 previzualizare
  • The Chatbox Is an Anti-Pattern: Designing Intent Previews and Shared Autonomy for Agentic UX
    For three years, products default-shipped conversational sidebars for every AI capability. But as software shifts from assistive chatbots that generate text to agentic systems that execute multi-step mutations across production state, the chat UI falls apart.


    In chat, everything is an uninspected black box until the action completes. When an autonomous agent touches databases, schedules emails, or runs cloud deployments, presenting the user with a single fait accompli message ("I just updated 42 customer accounts") triggers cognitive anxiety and causes users to retract system permissions.


    Modern product design is shifting toward Structured Scaffolding & Dynamic Intent Previews.


    Plaintext
    [ ANTI-PATTERN: The Conversational Black Box ]
    User Prompt ──> [Chat Interface Spinner] ──> Silent Multi-Step Action ──> "Done! 42 records updated"
    (Zero Visibility) (Zero Steerability) (High Anxiety / Revoked Trust)


    [ RESILIENT PATTERN: Steerable Agentic UX Scaffolding ]
    User Intent ──> [Structured Intent Preview] ──> [Dynamic Autonomy Dial] ──> Progressive Execution
    • Step-by-step DAG • Watch / Confirm / Auto • Live Diff & Inline Override
    • Reversible State Diff • Instant Checkpoint Rollback
    Here is how high-performing product and design teams are architecting agentic interfaces:


    Replace Chat Responses with "Intent Previews" (Pre-Action Clarity)
    Before an agent executes multi-step external API calls, replace generic loading spinners with a sequential plan breakdown. Expose:


    What data the agent referenced.


    Which specific systems will be altered.


    What downstream effects will occur before execution happens.


    Build the "Autonomy Dial" (Variable Consent)
    Autonomy in product design is never binary. Provide users with clear tier switches:


    Suggest & Review: Agent builds drafts; user reviews before any execution.


    Act with Confirmation: Agent prepares calls and stops at irreversible checkpoints (e.g., destructive actions or payments).


    Autonomous Background: Agent operates within explicit guardrails and reports via digest audit logs.


    Inline Steerability and State Diffs (During Action)
    Never make error recovery an all-or-nothing rollback. Provide inline diff components—similar to code review pull requests—allowing users to edit single parameters, pause intermediate agent steps, or redirect reasoning without restarting the entire workflow.


    Discussion Question (Poll)
    When designing interfaces for autonomous multi-step agents, how is your team handling user control and trust?


    Option A: Intent previews & explicit confirmation modals before execution


    Option B: Reversible dry-run simulation sandbox before committing state


    Option C: Ambient activity feed with post-action undo / rollback checkpoints


    Option D: Conversational chat interface with inline structured card widgets


    CTA
    Designing the next generation of AI-native products, design systems, and agentic experiences?


    👉 Join the Techawks Product, UX & Design Community to exchange component teardowns, user research insights, and interactive product blueprints with top product leaders.
    The Chatbox Is an Anti-Pattern: Designing Intent Previews and Shared Autonomy for Agentic UX For three years, products default-shipped conversational sidebars for every AI capability. But as software shifts from assistive chatbots that generate text to agentic systems that execute multi-step mutations across production state, the chat UI falls apart. In chat, everything is an uninspected black box until the action completes. When an autonomous agent touches databases, schedules emails, or runs cloud deployments, presenting the user with a single fait accompli message ("I just updated 42 customer accounts") triggers cognitive anxiety and causes users to retract system permissions. Modern product design is shifting toward Structured Scaffolding & Dynamic Intent Previews. Plaintext [ ANTI-PATTERN: The Conversational Black Box ] User Prompt ──> [Chat Interface Spinner] ──> Silent Multi-Step Action ──> "Done! 42 records updated" (Zero Visibility) (Zero Steerability) (High Anxiety / Revoked Trust) [ RESILIENT PATTERN: Steerable Agentic UX Scaffolding ] User Intent ──> [Structured Intent Preview] ──> [Dynamic Autonomy Dial] ──> Progressive Execution • Step-by-step DAG • Watch / Confirm / Auto • Live Diff & Inline Override • Reversible State Diff • Instant Checkpoint Rollback Here is how high-performing product and design teams are architecting agentic interfaces: Replace Chat Responses with "Intent Previews" (Pre-Action Clarity) Before an agent executes multi-step external API calls, replace generic loading spinners with a sequential plan breakdown. Expose: What data the agent referenced. Which specific systems will be altered. What downstream effects will occur before execution happens. Build the "Autonomy Dial" (Variable Consent) Autonomy in product design is never binary. Provide users with clear tier switches: Suggest & Review: Agent builds drafts; user reviews before any execution. Act with Confirmation: Agent prepares calls and stops at irreversible checkpoints (e.g., destructive actions or payments). Autonomous Background: Agent operates within explicit guardrails and reports via digest audit logs. Inline Steerability and State Diffs (During Action) Never make error recovery an all-or-nothing rollback. Provide inline diff components—similar to code review pull requests—allowing users to edit single parameters, pause intermediate agent steps, or redirect reasoning without restarting the entire workflow. Discussion Question (Poll) When designing interfaces for autonomous multi-step agents, how is your team handling user control and trust? Option A: Intent previews & explicit confirmation modals before execution Option B: Reversible dry-run simulation sandbox before committing state Option C: Ambient activity feed with post-action undo / rollback checkpoints Option D: Conversational chat interface with inline structured card widgets CTA Designing the next generation of AI-native products, design systems, and agentic experiences? 👉 Join the Techawks Product, UX & Design Community to exchange component teardowns, user research insights, and interactive product blueprints with top product leaders.
    0 Commentarii 0 Distribuiri 27 Views 0 previzualizare
  • The Death of the 80% Gross Margin: Rethinking SaaS Unit Economics
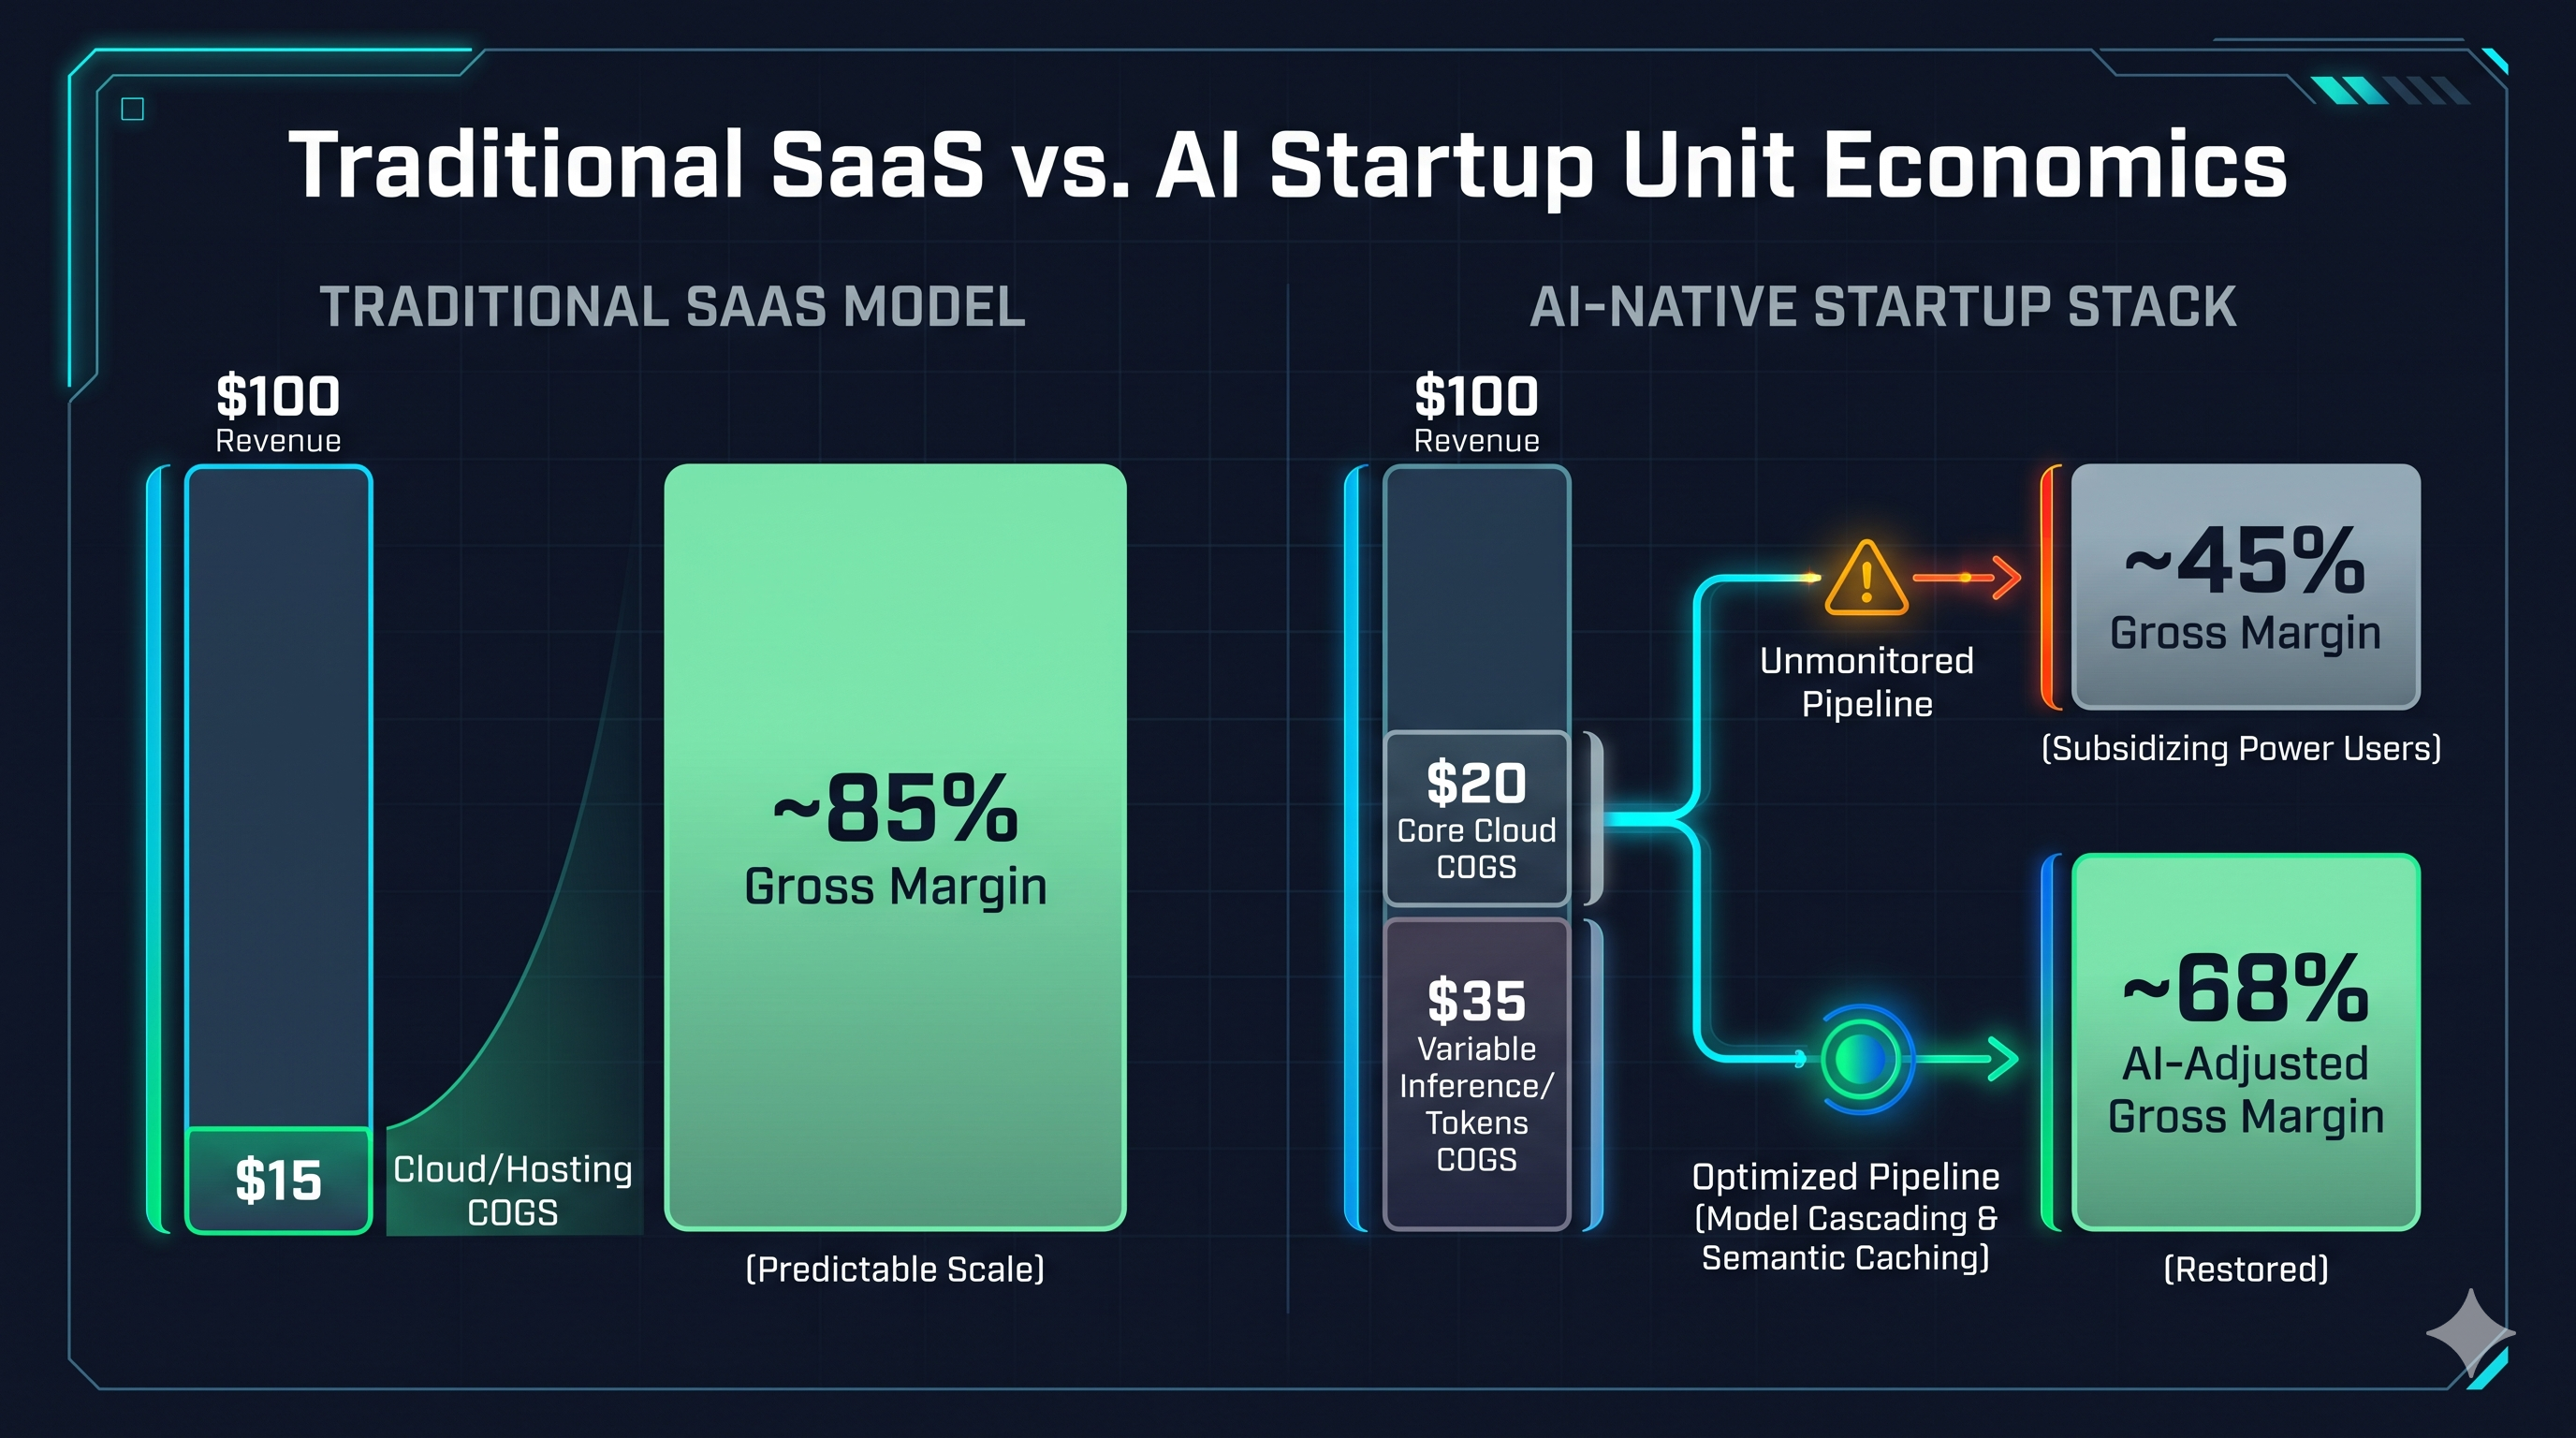
    For two decades, venture-backed B2B software relied on a golden benchmark: 75% to 80%+ gross margins. You wrote code once, cloud hosting cost pennies per tenant, and every incremental revenue dollar flowed almost straight to gross profit.


    In software startups running autonomous workflows and multi-step inference, that assumption is broken. Industry benchmark data reveals average gross margins on AI products hover near 50–53%, with heavy inference workloads behaving as variable Cost of Goods Sold (COGS) rather than fixed overhead.


    When a single power customer runs agentic multi-step task loops, their token consumption can easily exceed their flat monthly seat fee. Founders who ignore this scale themselves into negative-margin cohorts.


    Plaintext
    [ ANTI-PATTERN: The Flat-Rate AI Margin Bleed ]
    Flat $49/mo User ──> Uncapped Agent Loops ──> Dynamic Frontier Calls ──> $65 Compute COGS
    │
    ▼
    Net Unit Margin: -32% (Loss)


    [ RESILIENT PATTERN: The Defensible AI Unit Economics Stack ]
    Hybrid Billing ──> Semantic Prompt Cache ──> Cascading Router ──> Fixed + Metered Profit
    ($29 Base + Overage) (Zero Cost / Instant) (SLM First -> Frontier) (Guaranteed 65%+ Margin)
    Here is how early-stage founders are defending unit economics and gross margins:


    Calculate "AI-Adjusted Gross Margin" Per Cohort
    Stop analyzing blended gross margins. Blend masks toxic customers. Attribute token egress and cloud GPU cost directly to individual customer accounts to identify the top 5% of users responsible for 50%+ of inference spend.


    Deploy Model Routing & Tiered Fallbacks
    Directing 100% of tasks to frontier reasoning models is an architectural leak. Implement intent classifiers to route routine classification, formatting, and vector queries to smaller, distilled models or local SLMs at 1/10th the cost. Reserve frontier calls exclusively for complex synthesis.


    Transition from Pure Flat-Rate to Hybrid Value-Metric Pricing
    Pure per-seat pricing fails when value scales with automated output. Shift to platform base fee + consumption credits (or outcome-based billing tied to resolved tickets, processed docs, or completed runs) to ensure revenue scales parallel to underlying compute.


    Discussion Question (Poll)
    As a founder or tech lead, how is your startup pricing its AI-heavy features to protect gross margins?


    Option A: Traditional flat subscription (absorbing variable compute costs)


    Option B: Hybrid pricing (base subscription fee + metered usage/credits)


    Option C: Pure consumption-based or outcome-based billing


    Option D: Strict usage quotas & rate-limiting per billing tier


    CTA
    Navigating early-stage monetization, customer acquisition costs, and defensible tech unit economics?


    👉 Join the Techawks Startup Founders & Entrepreneurs Community to share pricing frameworks, investor pitch decks, and architectural benchmarks with fellow founders.
    The Death of the 80% Gross Margin: Rethinking SaaS Unit Economics For two decades, venture-backed B2B software relied on a golden benchmark: 75% to 80%+ gross margins. You wrote code once, cloud hosting cost pennies per tenant, and every incremental revenue dollar flowed almost straight to gross profit. In software startups running autonomous workflows and multi-step inference, that assumption is broken. Industry benchmark data reveals average gross margins on AI products hover near 50–53%, with heavy inference workloads behaving as variable Cost of Goods Sold (COGS) rather than fixed overhead. When a single power customer runs agentic multi-step task loops, their token consumption can easily exceed their flat monthly seat fee. Founders who ignore this scale themselves into negative-margin cohorts. Plaintext [ ANTI-PATTERN: The Flat-Rate AI Margin Bleed ] Flat $49/mo User ──> Uncapped Agent Loops ──> Dynamic Frontier Calls ──> $65 Compute COGS │ ▼ Net Unit Margin: -32% (Loss) [ RESILIENT PATTERN: The Defensible AI Unit Economics Stack ] Hybrid Billing ──> Semantic Prompt Cache ──> Cascading Router ──> Fixed + Metered Profit ($29 Base + Overage) (Zero Cost / Instant) (SLM First -> Frontier) (Guaranteed 65%+ Margin) Here is how early-stage founders are defending unit economics and gross margins: Calculate "AI-Adjusted Gross Margin" Per Cohort Stop analyzing blended gross margins. Blend masks toxic customers. Attribute token egress and cloud GPU cost directly to individual customer accounts to identify the top 5% of users responsible for 50%+ of inference spend. Deploy Model Routing & Tiered Fallbacks Directing 100% of tasks to frontier reasoning models is an architectural leak. Implement intent classifiers to route routine classification, formatting, and vector queries to smaller, distilled models or local SLMs at 1/10th the cost. Reserve frontier calls exclusively for complex synthesis. Transition from Pure Flat-Rate to Hybrid Value-Metric Pricing Pure per-seat pricing fails when value scales with automated output. Shift to platform base fee + consumption credits (or outcome-based billing tied to resolved tickets, processed docs, or completed runs) to ensure revenue scales parallel to underlying compute. Discussion Question (Poll) As a founder or tech lead, how is your startup pricing its AI-heavy features to protect gross margins? Option A: Traditional flat subscription (absorbing variable compute costs) Option B: Hybrid pricing (base subscription fee + metered usage/credits) Option C: Pure consumption-based or outcome-based billing Option D: Strict usage quotas & rate-limiting per billing tier CTA Navigating early-stage monetization, customer acquisition costs, and defensible tech unit economics? 👉 Join the Techawks Startup Founders & Entrepreneurs Community to share pricing frameworks, investor pitch decks, and architectural benchmarks with fellow founders.
    0 Commentarii 0 Distribuiri 40 Views 0 previzualizare
  • Why Defensive Schema Typing Is Replacing Trust-Based API Contracts in Modern TypeScript
    Most developers treat TypeScript interfaces and types as runtime shields. But TypeScript types vanish completely upon compilation.


    When code receives external payloads—whether from third-party APIs, database queries, webhooks, or dynamic JSON endpoints—casting with data as UserProfile bypasses runtime safety checks. The moment upstream teams rename an ID field or return an unexpected null, code crashes in production with TypeError: Cannot read properties of undefined.


    The shift in production backend and frontend codebases is moving away from blind casting toward Parse, Don't Validate with zero-cost runtime schema parsers (like Zod, Valibot, and TypeBox).


    Plaintext
    [ ANTI-PATTERN: Blind Type Assertion ]
    External API Response ──> JSON.parse() ──> `as UserPayload` (Zero Runtime Checks)
    │
    ▼
    Runtime crash in Prod (`undefined.id`)


    [ RESILIENT PATTERN: Runtime Boundary Parsing ]
    External API Response ──> Schema.safeParse() ──┬──> [Success] ──> Strongly-Typed Runtime Data
    │
    └──> [Failure] ──> Graceful Fallback / Metric Log
    Here is how to structure robust boundary parsing in modern TypeScript:


    Infer Types from Schemas, Not the Reverse
    Avoid writing a TypeScript interface and then writing a separate manual validation function that drifts out of sync. Define the runtime schema as the single source of truth, then infer the static TypeScript type automatically:


    TypeScript
    import { z } from 'zod';


    export const UserSchema = z.object({
    id: z.string().uuid(),
    email: z.string().email(),
    role: z.enum(['admin', 'member', 'guest']).default('guest'),
    metadata: z.record(z.unknown()).optional(),
    });


    export type User = z.infer<typeof UserSchema>;
    Always Prefer safeParse Over parse in High-Throughput Paths
    Using .parse() throws an exception on failure, which causes expensive try/catch allocations and unhandled rejections if missed. Using .safeParse() returns a discriminated union ({ success: true, data } | { success: false, error }), forcing developers to explicitly handle edge cases before accessing state.


    Strip Unknown Properties at Network Ingress
    Malicious or unintended payload bloating can pollute cache stores and memory footprints. Enforce strict stripping or rejection at the API contract layer to prevent prototype pollution and schema mutation vulnerabilities.


    Discussion Question (Poll)
    How does your team handle incoming API payload validation at production boundaries?


    Option A: Runtime parsing with Zod / Valibot / TypeBox on every network boundary


    Option B: Traditional manual checks (typeof, in operator, and custom type guards)


    Option C: Generated types from OpenAPI / GraphQL specifications (trusting the schema)


    Option D: Plain TypeScript assertions (as Type) with standard try/catch error boundaries


    CTA
    Want to level up your software engineering craft, modern TypeScript patterns, and robust backend system designs?


    👉 Join the Techawks Developers & Coding Community to exchange code architectures, review real-world patterns, and build production-grade software together.
    Why Defensive Schema Typing Is Replacing Trust-Based API Contracts in Modern TypeScript Most developers treat TypeScript interfaces and types as runtime shields. But TypeScript types vanish completely upon compilation. When code receives external payloads—whether from third-party APIs, database queries, webhooks, or dynamic JSON endpoints—casting with data as UserProfile bypasses runtime safety checks. The moment upstream teams rename an ID field or return an unexpected null, code crashes in production with TypeError: Cannot read properties of undefined. The shift in production backend and frontend codebases is moving away from blind casting toward Parse, Don't Validate with zero-cost runtime schema parsers (like Zod, Valibot, and TypeBox). Plaintext [ ANTI-PATTERN: Blind Type Assertion ] External API Response ──> JSON.parse() ──> `as UserPayload` (Zero Runtime Checks) │ ▼ Runtime crash in Prod (`undefined.id`) [ RESILIENT PATTERN: Runtime Boundary Parsing ] External API Response ──> Schema.safeParse() ──┬──> [Success] ──> Strongly-Typed Runtime Data │ └──> [Failure] ──> Graceful Fallback / Metric Log Here is how to structure robust boundary parsing in modern TypeScript: Infer Types from Schemas, Not the Reverse Avoid writing a TypeScript interface and then writing a separate manual validation function that drifts out of sync. Define the runtime schema as the single source of truth, then infer the static TypeScript type automatically: TypeScript import { z } from 'zod'; export const UserSchema = z.object({ id: z.string().uuid(), email: z.string().email(), role: z.enum(['admin', 'member', 'guest']).default('guest'), metadata: z.record(z.unknown()).optional(), }); export type User = z.infer<typeof UserSchema>; Always Prefer safeParse Over parse in High-Throughput Paths Using .parse() throws an exception on failure, which causes expensive try/catch allocations and unhandled rejections if missed. Using .safeParse() returns a discriminated union ({ success: true, data } | { success: false, error }), forcing developers to explicitly handle edge cases before accessing state. Strip Unknown Properties at Network Ingress Malicious or unintended payload bloating can pollute cache stores and memory footprints. Enforce strict stripping or rejection at the API contract layer to prevent prototype pollution and schema mutation vulnerabilities. Discussion Question (Poll) How does your team handle incoming API payload validation at production boundaries? Option A: Runtime parsing with Zod / Valibot / TypeBox on every network boundary Option B: Traditional manual checks (typeof, in operator, and custom type guards) Option C: Generated types from OpenAPI / GraphQL specifications (trusting the schema) Option D: Plain TypeScript assertions (as Type) with standard try/catch error boundaries CTA Want to level up your software engineering craft, modern TypeScript patterns, and robust backend system designs? 👉 Join the Techawks Developers & Coding Community to exchange code architectures, review real-world patterns, and build production-grade software together.
    0 Commentarii 0 Distribuiri 39 Views 0 previzualizare
  • Architecting for India's DPDP Act: Why Your Consent Layer Can't Just Be an Afterthought in a Modal
    As India solidifies its compliance roadmap for the DPDP Act alongside sectoral mandates (RBI payment localization, SEBI frameworks, and UIDAI data vaults), engineering orgs across Bengaluru, Hyderabad, Pune, and NCR are facing a major architectural overhaul.


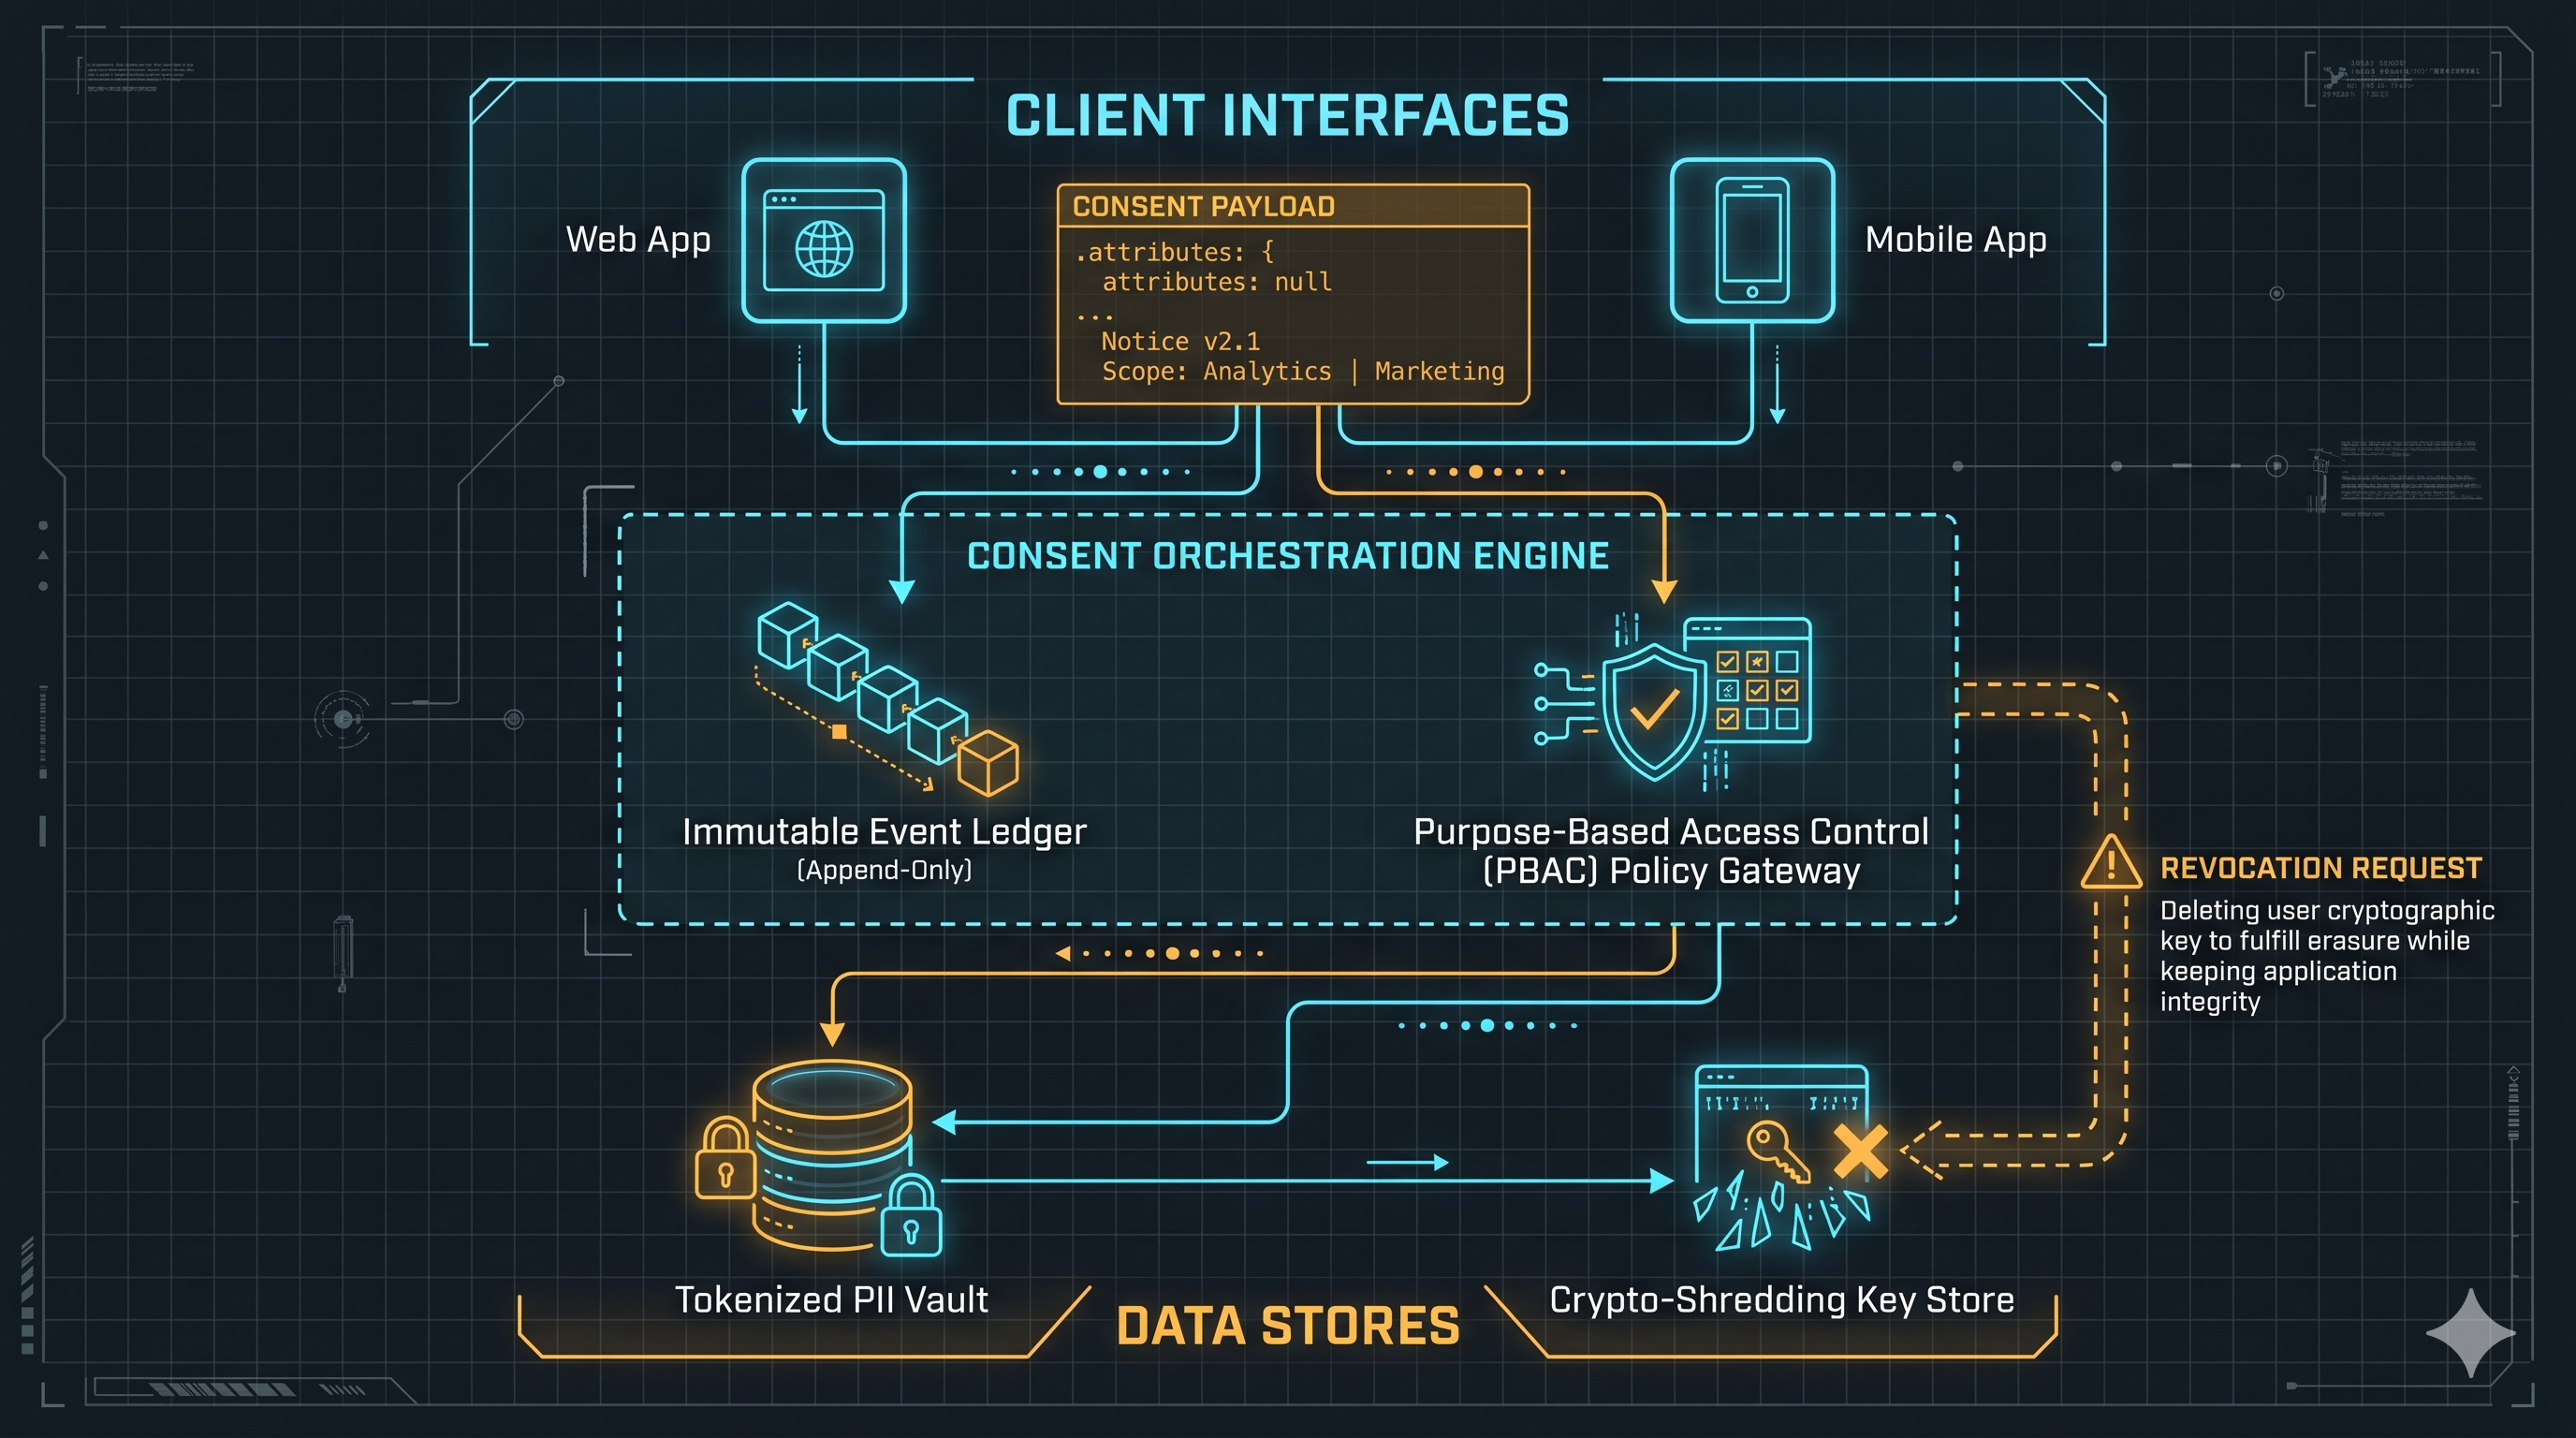
    Consent under DPDP must be free, specific, informed, unconditional, and unambiguously revocable with an easy withdrawal mechanism. For developers building high-throughput consumer tech, fintech, or SaaS platforms, this makes treating user consent as a static boolean flag (is_consented: true) in your SQL users table completely obsolete.


    Here is how systems architects are structuring a modern Consent-Aware Data Pipeline:


    Decouple Consent into an Event-Driven Audit Ledger:


    Treat consent as an immutable time-series event, not mutable user state.


    When a user opts in or revokes consent for a specific processing purpose (e.g., promotional profiling vs. transactional telemetry), publish an event (ConsentUpdatedEvent) to an event stream (such as Kafka or Redpanda).


    Persist every state change with the exact notice version, scope timestamp, and identity hash into an append-only consent registry.


    Downstream Tokenization & Purpose-Based Access Control (PBAC):


    Decouple raw PII from application processing layers using internal tokenization services.


    Inject purpose context into your data access calls:


    Python
    # Enforce purpose-scoped retrieval at the data gateway
    def get_user_profile(user_id, purpose="order_fulfillment"):
    consent_status = consent_service.verify(user_id, purpose)
    if not consent_status.is_valid():
    raise PermissionError("DPDP: Purpose consent missing or revoked")
    return token_vault.resolve_pii(user_id, fields=consent_status.permitted_fields)
    Handling the "Right to Erasure" Across Distributed Systems:


    When an Indian data principal requests data deletion or withdraws consent, your architecture must reliably propagate that deletion to replica stores, analytics data lakes, and vector indices.


    Avoid full table rebuilds by employing cryptographic erasure (crypto-shredding): encrypt individual user records with unique per-user keys. Deleting the specific user's encryption key renders their distributed data unrecoverable, fulfilling compliance without breaking immutable event stores.


    Discussion Question
    For engineering teams and CTOs building for the Indian ecosystem: How is your team handling consent revocation downstream in your analytics lakes and caching layers? Have you opted for crypto-shredding, modular microservices with dedicated consent tokens, or external consent management platforms?


    CTA
    Join Techawks India: Connect with our nationwide network of engineering leads, security researchers, and systems architects as we break down deep-dive engineering patterns, compliance blueprints, and tech innovations shaping the Indian ecosystem. Drop your thoughts below and subscribe to the page!
    Architecting for India's DPDP Act: Why Your Consent Layer Can't Just Be an Afterthought in a Modal As India solidifies its compliance roadmap for the DPDP Act alongside sectoral mandates (RBI payment localization, SEBI frameworks, and UIDAI data vaults), engineering orgs across Bengaluru, Hyderabad, Pune, and NCR are facing a major architectural overhaul. Consent under DPDP must be free, specific, informed, unconditional, and unambiguously revocable with an easy withdrawal mechanism. For developers building high-throughput consumer tech, fintech, or SaaS platforms, this makes treating user consent as a static boolean flag (is_consented: true) in your SQL users table completely obsolete. Here is how systems architects are structuring a modern Consent-Aware Data Pipeline: Decouple Consent into an Event-Driven Audit Ledger: Treat consent as an immutable time-series event, not mutable user state. When a user opts in or revokes consent for a specific processing purpose (e.g., promotional profiling vs. transactional telemetry), publish an event (ConsentUpdatedEvent) to an event stream (such as Kafka or Redpanda). Persist every state change with the exact notice version, scope timestamp, and identity hash into an append-only consent registry. Downstream Tokenization & Purpose-Based Access Control (PBAC): Decouple raw PII from application processing layers using internal tokenization services. Inject purpose context into your data access calls: Python # Enforce purpose-scoped retrieval at the data gateway def get_user_profile(user_id, purpose="order_fulfillment"): consent_status = consent_service.verify(user_id, purpose) if not consent_status.is_valid(): raise PermissionError("DPDP: Purpose consent missing or revoked") return token_vault.resolve_pii(user_id, fields=consent_status.permitted_fields) Handling the "Right to Erasure" Across Distributed Systems: When an Indian data principal requests data deletion or withdraws consent, your architecture must reliably propagate that deletion to replica stores, analytics data lakes, and vector indices. Avoid full table rebuilds by employing cryptographic erasure (crypto-shredding): encrypt individual user records with unique per-user keys. Deleting the specific user's encryption key renders their distributed data unrecoverable, fulfilling compliance without breaking immutable event stores. Discussion Question For engineering teams and CTOs building for the Indian ecosystem: How is your team handling consent revocation downstream in your analytics lakes and caching layers? Have you opted for crypto-shredding, modular microservices with dedicated consent tokens, or external consent management platforms? CTA Join Techawks India: Connect with our nationwide network of engineering leads, security researchers, and systems architects as we break down deep-dive engineering patterns, compliance blueprints, and tech innovations shaping the Indian ecosystem. Drop your thoughts below and subscribe to the page!
    0 Commentarii 0 Distribuiri 70 Views 0 previzualizare
  • The SaaS Margin Collapse: Why AI Startups Face an "Inference COGS" Crisis (And How to Architect Around It)
    For two decades, software startups raised capital on the back of 75% to 85% gross margins: once code was deployed, serving an additional user cost fractions of a cent.


    In AI-first software, every user action triggers an inference compute cycle. AI startup gross margins hover closer to 50% to 60%, with some high-growth wrappers dipping as low as 25% to 30%. When your pricing is fixed per seat ($30/seat/month) but your heavy users consume $70 in token passes, scale doesn't create operating leverage—it accelerates cash burn.


    Founders must shift from naive API proxy wrappers to a tiered model-routing architecture.


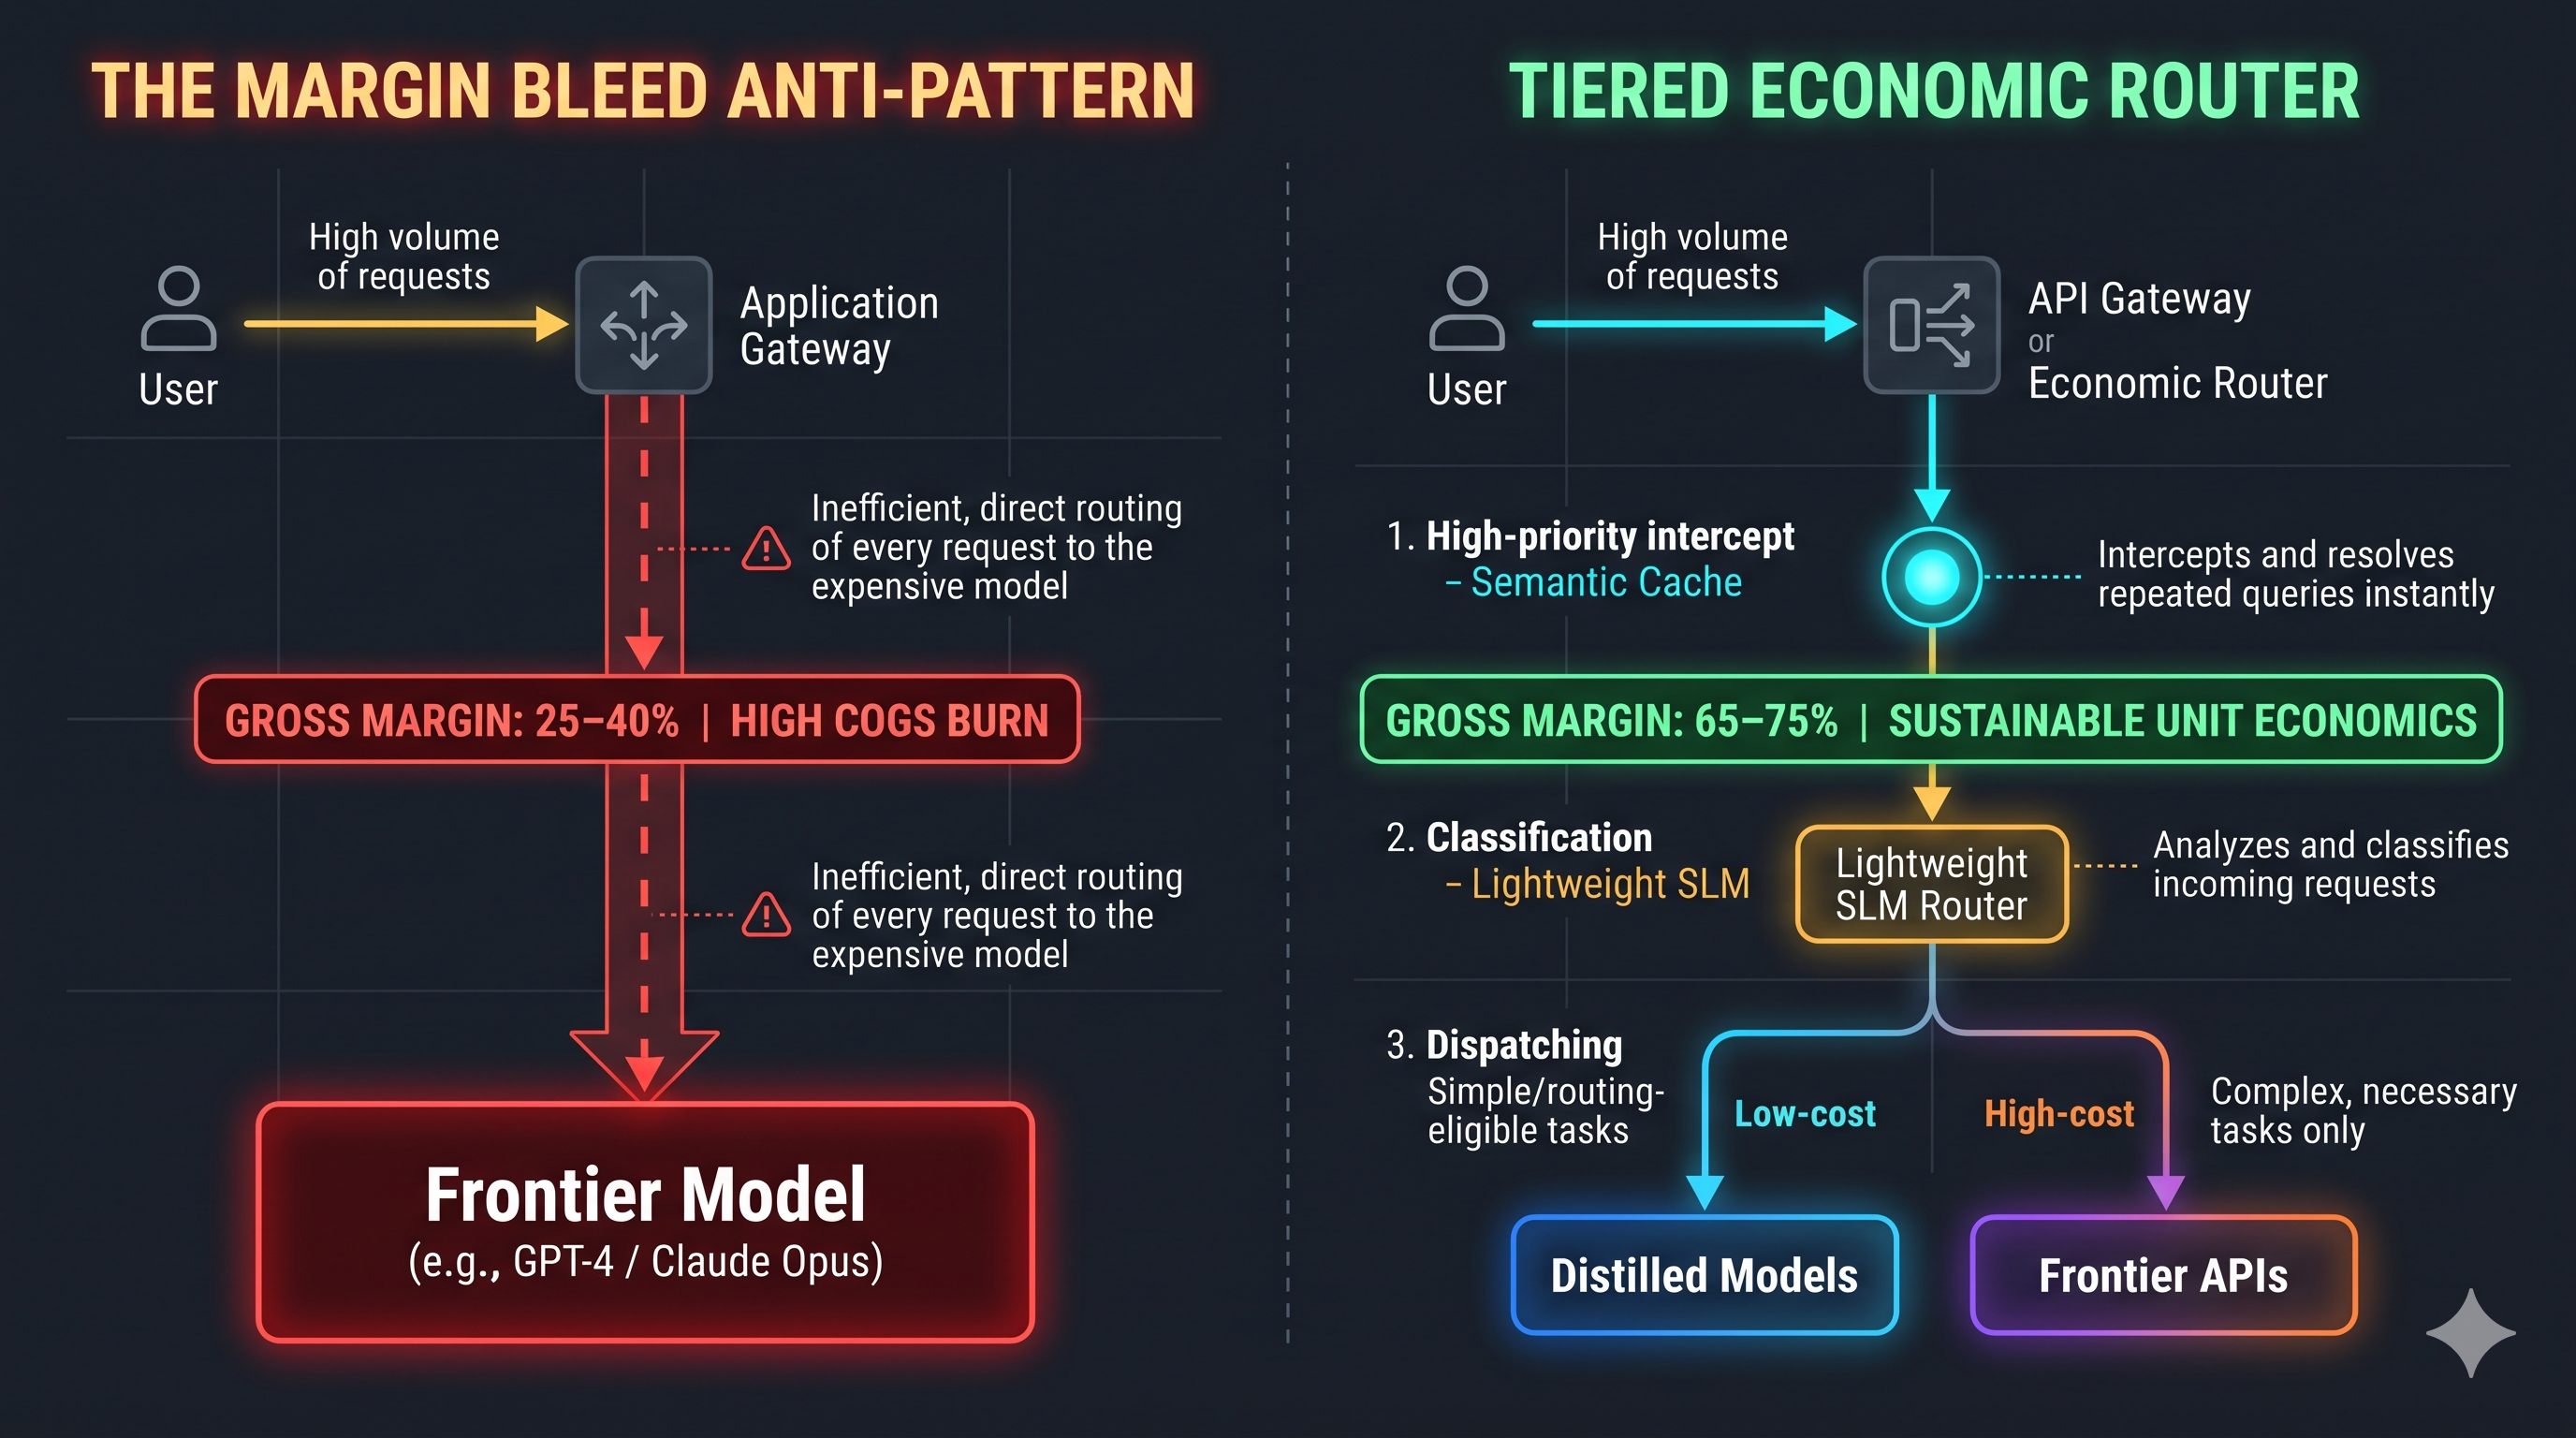
    The Margin-Killing Anti-Pattern vs. Tiered Inference
    Margin Trap (Naive Proxy):
    [User Request] ➔ Universal Frontier Model ($$$$) ➔ Static Output
    Margin: ~25-45% (Every token hits the most expensive provider)


    Sustainable Margin Architecture:
    [User Request]
    │
    ├──> [Semantic Cache (Redis)] ──────────────> Fast Return ($0)
    │
    ├──> [Rule / Complexity Classifier (1B/3B)]
    │
    ├── Simple/Structured ──> [Self-Hosted SLM / Distilled Model] ($)
    └── Deep Multi-Step ───> [Frontier Reasoning API] ($$$$)
    Margin: 65-75% (Targeted compute allocation)
    3 Architectural Rules to Protect Startup Gross Margins
    Implement Aggressive Semantic Caching at the Gateway


    Between 20% and 40% of queries within specific verticals (e.g., customer support, document parsing, boilerplate drafting) share semantic intent. Serving cached vector similarity matches from an in-memory cache directly eliminates 100% of LLM compute costs on repeated workflows.


    Decouple "Thinking" from "Synthesizing" (Cascade Routing)


    Use compact, distilled models (1B to 8B parameter models running on cost-effective cloud or edge instances) for classification, extraction, and JSON schema formatting. Route tasks to flagship foundation models only when deep synthetic reasoning or multi-hop evaluation is strictly required.


    Align Pricing with Compute Units (Kill Naive Flat-Rate Tiers)


    If your product involves agentic workflows or open-ended code generation, pure per-seat flat pricing exposes you to tail-risk power users. Move to hybrid pricing: a base platform fee combined with credit allowances or outcome-based micro-metering that protects your floor gross margin.


    Discussion Question


    For founders building AI products: What is your current blended gross margin, and at what monthly query volume did you find it economically viable to switch from closed frontier APIs to self-hosted open-weight SLMs?


    CTA (Join Startup Founders & Entrepreneurs)


    Build defensible products, fix your unit economics, and scale capital-efficient startups alongside venture-backed founders.


    👉 Join Startup Founders & Entrepreneurs: [techawks.io/founders-community]
    The SaaS Margin Collapse: Why AI Startups Face an "Inference COGS" Crisis (And How to Architect Around It) For two decades, software startups raised capital on the back of 75% to 85% gross margins: once code was deployed, serving an additional user cost fractions of a cent. In AI-first software, every user action triggers an inference compute cycle. AI startup gross margins hover closer to 50% to 60%, with some high-growth wrappers dipping as low as 25% to 30%. When your pricing is fixed per seat ($30/seat/month) but your heavy users consume $70 in token passes, scale doesn't create operating leverage—it accelerates cash burn. Founders must shift from naive API proxy wrappers to a tiered model-routing architecture. The Margin-Killing Anti-Pattern vs. Tiered Inference Margin Trap (Naive Proxy): [User Request] ➔ Universal Frontier Model ($$$$) ➔ Static Output Margin: ~25-45% (Every token hits the most expensive provider) Sustainable Margin Architecture: [User Request] │ ├──> [Semantic Cache (Redis)] ──────────────> Fast Return ($0) │ ├──> [Rule / Complexity Classifier (1B/3B)] │ ├── Simple/Structured ──> [Self-Hosted SLM / Distilled Model] ($) └── Deep Multi-Step ───> [Frontier Reasoning API] ($$$$) Margin: 65-75% (Targeted compute allocation) 3 Architectural Rules to Protect Startup Gross Margins Implement Aggressive Semantic Caching at the Gateway Between 20% and 40% of queries within specific verticals (e.g., customer support, document parsing, boilerplate drafting) share semantic intent. Serving cached vector similarity matches from an in-memory cache directly eliminates 100% of LLM compute costs on repeated workflows. Decouple "Thinking" from "Synthesizing" (Cascade Routing) Use compact, distilled models (1B to 8B parameter models running on cost-effective cloud or edge instances) for classification, extraction, and JSON schema formatting. Route tasks to flagship foundation models only when deep synthetic reasoning or multi-hop evaluation is strictly required. Align Pricing with Compute Units (Kill Naive Flat-Rate Tiers) If your product involves agentic workflows or open-ended code generation, pure per-seat flat pricing exposes you to tail-risk power users. Move to hybrid pricing: a base platform fee combined with credit allowances or outcome-based micro-metering that protects your floor gross margin. Discussion Question For founders building AI products: What is your current blended gross margin, and at what monthly query volume did you find it economically viable to switch from closed frontier APIs to self-hosted open-weight SLMs? CTA (Join Startup Founders & Entrepreneurs) Build defensible products, fix your unit economics, and scale capital-efficient startups alongside venture-backed founders. 👉 Join Startup Founders & Entrepreneurs: [techawks.io/founders-community]
    0 Commentarii 0 Distribuiri 81 Views 0 previzualizare
  • The Consent Boundary Collapse: Why Indian Engineering Stacks Need Cryptographic Consent Artifacts for DPDP Compliance
    India's data architecture landscape is experiencing its most radical transformation since the rollout of UPI.


    Between the enforcement of the Digital Personal Data Protection Act (DPDP Act) and the nationwide expansion of the Data Empowerment and Protection Architecture (DEPA) (anchored by the RBI Account Aggregator ecosystem), data ownership is shifting from proprietary corporate silos to citizen-centric consent protocols.


    Most consumer applications, fintechs, and SaaS backends built in India still rely on The Boolean Consent Anti-Pattern:


    A user checks a bundled modal on signup.


    The backend stamps is_consented = 1 in the users table.


    Telemetry, analytics, and CRM workers read customer PII across microservices with zero purpose validation or scope lifecycle checks.


    Under DPDP audit, a boolean flag is indefensible. The law demands unbundled, purpose-limited, itemized, and revocable consent. If a user consents to loan underwriting but revokes marketing outreach, or revokes processing entirely after 90 days, your downstream data pipelines, analytics lakes, and third-party webhooks must execute cryptographic erasure and purpose-fencing automatically.


    To build compliant, population-scale Indian tech backends, engineering teams must transition to Cryptographic Consent Artefacts & Purpose-Fenced Ingress.


    Plaintext
    [ ANTI-PATTERN: THE UNGOVERNED BOOLEAN CONSENT ]
    User Signup ──► Bundled "Agree All" Modal ──► users.has_consented = true ──► Unrestricted Downstream Pipeline (Analytics / Marketing / Models) ──► Non-Compliance Audit (Penalties up to ₹250 Cr)


    [ PRODUCTION ARCHITECTURE: DEPA-COMPLIANT CONSENT ARTEFACT ENGINE ]
    Data Principal ──► Registered Consent Manager / Granular UI
    │
    ▼
    Signed Digital Consent Artefact (W3C / MeitY Machine-Readable XML/JSON)
    [Scope: Financial / Purpose: CreditUnderwrite / Expiry: 30D / Revocable: Yes]
    │
    ▼
    Consent Verification API Gateway
    │
    ┌───────────────────┴───────────────────┐
    ▼ ▼
    Authorized Pipeline Automated Revocation Bus
    (Purpose: Underwriting) (Kafka / EventBridge Deletion Hook)
    │ │
    ▼ ▼
    Ephemereal Data Vault (Encrypted) Zero-Copy Lakehouse Purge / Shard Erasure
    Here are three core architectural shifts Indian software engineers and platform architects must implement today:


    1. Adopt Machine-Readable, Signed Consent Artefacts
    Replace static database booleans with structured, cryptographic consent artefacts (mirroring the Electronic Consent specifications of MeitY and DEPA):


    A consent record must specify:


    purpose_code: The exact legal and operational reason for data capture (e.g., IN.GOV.KYC_VERIFICATION).


    data_fields: Explicit itemization of fields accessed (e.g., ["pan", "bank_statement_summary"]).


    expiry_timestamp: Concrete TTL after which data retention is illegal without affirmative renewal.


    digital_signature: Asymmetric cryptographic signature generated by the Data Principal or registered Consent Manager.


    2. Implement Purpose-Fenced Ingress at the API Gateway
    Do not trust internal microservices to voluntarily respect user consent parameters.


    3. Engineer Automated Consent Revocation Webhooks
    The DPDP Act guarantees Data Principals the right to withdraw consent with the same ease it was granted.


    This event fans out to internal microservices, triggering:


    Invalidation of cached identity claims.


    Discussion Question
    For Indian backend engineers, CTOs, and platform leads: How is your team adapting its data pipelines for DPDP Act compliance—have you decoupled consent into dedicated microservices/artefacts, and how are you handling user consent revocation across your cold storage and analytics data lakes?


    CTA
    Building the next generation of high-scale, resilient tech systems in India?
    👉 Join the Techawks India community to collaborate with top engineers, CTOs, and systems architects shaping India's tech ecosystem!
    The Consent Boundary Collapse: Why Indian Engineering Stacks Need Cryptographic Consent Artifacts for DPDP Compliance India's data architecture landscape is experiencing its most radical transformation since the rollout of UPI. Between the enforcement of the Digital Personal Data Protection Act (DPDP Act) and the nationwide expansion of the Data Empowerment and Protection Architecture (DEPA) (anchored by the RBI Account Aggregator ecosystem), data ownership is shifting from proprietary corporate silos to citizen-centric consent protocols. Most consumer applications, fintechs, and SaaS backends built in India still rely on The Boolean Consent Anti-Pattern: A user checks a bundled modal on signup. The backend stamps is_consented = 1 in the users table. Telemetry, analytics, and CRM workers read customer PII across microservices with zero purpose validation or scope lifecycle checks. Under DPDP audit, a boolean flag is indefensible. The law demands unbundled, purpose-limited, itemized, and revocable consent. If a user consents to loan underwriting but revokes marketing outreach, or revokes processing entirely after 90 days, your downstream data pipelines, analytics lakes, and third-party webhooks must execute cryptographic erasure and purpose-fencing automatically. To build compliant, population-scale Indian tech backends, engineering teams must transition to Cryptographic Consent Artefacts & Purpose-Fenced Ingress. Plaintext [ ANTI-PATTERN: THE UNGOVERNED BOOLEAN CONSENT ] User Signup ──► Bundled "Agree All" Modal ──► users.has_consented = true ──► Unrestricted Downstream Pipeline (Analytics / Marketing / Models) ──► Non-Compliance Audit (Penalties up to ₹250 Cr) [ PRODUCTION ARCHITECTURE: DEPA-COMPLIANT CONSENT ARTEFACT ENGINE ] Data Principal ──► Registered Consent Manager / Granular UI │ ▼ Signed Digital Consent Artefact (W3C / MeitY Machine-Readable XML/JSON) [Scope: Financial / Purpose: CreditUnderwrite / Expiry: 30D / Revocable: Yes] │ ▼ Consent Verification API Gateway │ ┌───────────────────┴───────────────────┐ ▼ ▼ Authorized Pipeline Automated Revocation Bus (Purpose: Underwriting) (Kafka / EventBridge Deletion Hook) │ │ ▼ ▼ Ephemereal Data Vault (Encrypted) Zero-Copy Lakehouse Purge / Shard Erasure Here are three core architectural shifts Indian software engineers and platform architects must implement today: 1. Adopt Machine-Readable, Signed Consent Artefacts Replace static database booleans with structured, cryptographic consent artefacts (mirroring the Electronic Consent specifications of MeitY and DEPA): A consent record must specify: purpose_code: The exact legal and operational reason for data capture (e.g., IN.GOV.KYC_VERIFICATION). data_fields: Explicit itemization of fields accessed (e.g., ["pan", "bank_statement_summary"]). expiry_timestamp: Concrete TTL after which data retention is illegal without affirmative renewal. digital_signature: Asymmetric cryptographic signature generated by the Data Principal or registered Consent Manager. 2. Implement Purpose-Fenced Ingress at the API Gateway Do not trust internal microservices to voluntarily respect user consent parameters. 3. Engineer Automated Consent Revocation Webhooks The DPDP Act guarantees Data Principals the right to withdraw consent with the same ease it was granted. This event fans out to internal microservices, triggering: Invalidation of cached identity claims. Discussion Question For Indian backend engineers, CTOs, and platform leads: How is your team adapting its data pipelines for DPDP Act compliance—have you decoupled consent into dedicated microservices/artefacts, and how are you handling user consent revocation across your cold storage and analytics data lakes? CTA Building the next generation of high-scale, resilient tech systems in India? 👉 Join the Techawks India community to collaborate with top engineers, CTOs, and systems architects shaping India's tech ecosystem!
    0 Commentarii 0 Distribuiri 51 Views 0 previzualizare
  • The Blind Rolling Update Trap: Why Production Kubernetes Requires Automated Metric-Driven Rollbacks
    Most DevOps teams rely on native Deployment strategies: bump the image tag, watch pods transition to Running, and assume the release succeeded.


    Here is the operational reality: a broken microservice can pass an HTTP /healthz liveness probe with a 200 OK while failing 40% of database queries, throwing downstream 502s, or spiking P99 latency past 3,000 ms. Under a standard rolling update, Kubernetes continues terminating healthy older pods until 100% of your cluster is serving degraded traffic.


    By the time an engineer wakes up, logs in through VPN, checks telemetry, and runs kubectl rollout undo, your SLA is already breached.


    To run resilient cloud systems, platform and DevOps teams must replace blind rolling updates with Progressive Delivery paired with Automated Metric-Driven Rollbacks.


    Plaintext
    [ ANTI-PATTERN: BLIND ROLLING UPDATE ]
    Git Commit ──► CI Build ──► kubectl set image ──► Basic Health Check (200 OK) ──► Full Pod Replacement ──► P99 Latency & 5xx Spikes ──► Manual Emergency Triage


    [ PRODUCTION PATTERN: PROGRESSIVE CANARY WITH TELEMETRY GUARDRAILS ]
    GitOps Commit ──► Canary Ingress (5% Traffic) ──► Continuous PromQL Evaluation ──► Step Increment (25% ➔ 50%) ──► Automated Rollback IF Error Budget Degrades
    │
    └──► Latency / Error Violation Detected ──► Instant Zero-Touch Traffic Reversion (< 15s)
    Here are the three engineering primitives required to automate deployment safety:


    1. Decouple Deployment from Release via Traffic Shaping
    Pods being scheduled on nodes (deployment) should never automatically mean all end users hit that code (release).


    Utilize a service mesh (Istio/Linkerd) or advanced ingress controller (Traefik/Envoy/ALB) managed by a progressive delivery controller (such as Argo Rollouts or Flagger).


    Route a precise slice of production traffic—starting at 2% to 5%—to the canary replica while keeping 95% of traffic safely anchored on the known-stable revision.


    2. Replace Manual Checks with In-Flight Metric Analysis
    Define declarative AnalysisTemplates that query your Prometheus/OpenTelemetry backend directly during the rollout:


    Failure Condition: http_requests_5xx_rate > 0.01 or histogram_quantile(0.99, rate(http_request_duration_seconds_bucket[2m])) > 0.5.


    If consecutive analysis runs breach these thresholds, the controller immediately cuts ingress traffic back to 100% stable, scales down the canary pods, and marks the rollout as aborted—all within 15 to 30 seconds.


    3. Standardize "SLO-as-Code" Inside Golden Path Templates
    Do not let individual application squads write one-off rollout scripts.


    Platform engineers should bake baseline progressive deployment manifests into Internal Developer Platform (IDP) templates.


    Every newly scaffolded microservice automatically inherits standardized error-budget analysis rules, OpenTelemetry trace propagation, and automated rollback policies out of the box.


    DevOps maturity isn’t measured by how quickly you can push code into a cluster; it’s measured by how autonomously your infrastructure can detect, contain, and rollback a regression without human intervention.


    Discussion Question
    For Cloud and DevOps engineers: What progressive delivery tooling do you run in production (Argo Rollouts, Flagger, or custom service mesh routing), and what is the primary metric (e.g., P99 latency, 5xx rate, or custom business KPI) that triggers your automated abort?


    CTA
    Ready to level up your Kubernetes architecture, GitOps pipelines, and cloud platform engineering?
    👉 Join Cloud, DevOps & Open Source to exchange real-world infrastructure patterns with platform engineers and DevOps builders across the Techawks community.
    The Blind Rolling Update Trap: Why Production Kubernetes Requires Automated Metric-Driven Rollbacks Most DevOps teams rely on native Deployment strategies: bump the image tag, watch pods transition to Running, and assume the release succeeded. Here is the operational reality: a broken microservice can pass an HTTP /healthz liveness probe with a 200 OK while failing 40% of database queries, throwing downstream 502s, or spiking P99 latency past 3,000 ms. Under a standard rolling update, Kubernetes continues terminating healthy older pods until 100% of your cluster is serving degraded traffic. By the time an engineer wakes up, logs in through VPN, checks telemetry, and runs kubectl rollout undo, your SLA is already breached. To run resilient cloud systems, platform and DevOps teams must replace blind rolling updates with Progressive Delivery paired with Automated Metric-Driven Rollbacks. Plaintext [ ANTI-PATTERN: BLIND ROLLING UPDATE ] Git Commit ──► CI Build ──► kubectl set image ──► Basic Health Check (200 OK) ──► Full Pod Replacement ──► P99 Latency & 5xx Spikes ──► Manual Emergency Triage [ PRODUCTION PATTERN: PROGRESSIVE CANARY WITH TELEMETRY GUARDRAILS ] GitOps Commit ──► Canary Ingress (5% Traffic) ──► Continuous PromQL Evaluation ──► Step Increment (25% ➔ 50%) ──► Automated Rollback IF Error Budget Degrades │ └──► Latency / Error Violation Detected ──► Instant Zero-Touch Traffic Reversion (< 15s) Here are the three engineering primitives required to automate deployment safety: 1. Decouple Deployment from Release via Traffic Shaping Pods being scheduled on nodes (deployment) should never automatically mean all end users hit that code (release). Utilize a service mesh (Istio/Linkerd) or advanced ingress controller (Traefik/Envoy/ALB) managed by a progressive delivery controller (such as Argo Rollouts or Flagger). Route a precise slice of production traffic—starting at 2% to 5%—to the canary replica while keeping 95% of traffic safely anchored on the known-stable revision. 2. Replace Manual Checks with In-Flight Metric Analysis Define declarative AnalysisTemplates that query your Prometheus/OpenTelemetry backend directly during the rollout: Failure Condition: http_requests_5xx_rate > 0.01 or histogram_quantile(0.99, rate(http_request_duration_seconds_bucket[2m])) > 0.5. If consecutive analysis runs breach these thresholds, the controller immediately cuts ingress traffic back to 100% stable, scales down the canary pods, and marks the rollout as aborted—all within 15 to 30 seconds. 3. Standardize "SLO-as-Code" Inside Golden Path Templates Do not let individual application squads write one-off rollout scripts. Platform engineers should bake baseline progressive deployment manifests into Internal Developer Platform (IDP) templates. Every newly scaffolded microservice automatically inherits standardized error-budget analysis rules, OpenTelemetry trace propagation, and automated rollback policies out of the box. DevOps maturity isn’t measured by how quickly you can push code into a cluster; it’s measured by how autonomously your infrastructure can detect, contain, and rollback a regression without human intervention. Discussion Question For Cloud and DevOps engineers: What progressive delivery tooling do you run in production (Argo Rollouts, Flagger, or custom service mesh routing), and what is the primary metric (e.g., P99 latency, 5xx rate, or custom business KPI) that triggers your automated abort? CTA Ready to level up your Kubernetes architecture, GitOps pipelines, and cloud platform engineering? 👉 Join Cloud, DevOps & Open Source to exchange real-world infrastructure patterns with platform engineers and DevOps builders across the Techawks community.
    0 Commentarii 0 Distribuiri 65 Views 0 previzualizare
  • The Conversational Interface Fallacy: Why Chatbots Are the Worst Pattern for Complex User Workflows
    When generative AI arrived, the immediate design reflex across B2B software was universal: replace dashboards, forms, and workflows with an omnipresent chatbot window.


    Two years into deploying AI-native products, the user feedback is clear: pure conversational interfaces create severe interaction fatigue.


    Chat introduces friction:


    The "Blank Canvas" Paradox: Users must guess what the system can and cannot do.


    Invisible State: You cannot scan, filter, or reorder outputs cleanly inside a sequential vertical chat log.


    Low Information Density: Chat is synchronous and transient, whereas complex decision-making requires persistent spatial context.


    The most resilient AI products aren't replacing graphical interfaces with natural language—they are adopting Hybrid Canvas Architectures (Intent Scaffolding + Generative UI).


    Plaintext
    [ ANTI-PATTERN: THE UNBOUNDED CHAT WRAPPER ]
    User Intent ──► Open Text Box ("What can you do?") ──► High Prompt Friction ──► Wall of Text Output ──► Low Interaction / Drop-off


    [ PRODUCTION PATTERN: HYBRID CANVAS & GENERATIVE UI ]
    Action Trigger ──► Contextual Intent Chips ──► Dynamic Visual Component (Data Table / Form / Canvas) ──► Direct Spatial Manipulation ──► State Persistence
    Here is how modern product managers and UX architects design generative experiences that drive real product adoption:


    1. Shift from Open Prompts to "Scaffolded Intent"
    Never make the user initiate from zero. Replace bare text prompts with contextual, dynamic affordances:


    Contextual Suggestions: Display intent "chips" or micro-actions based on where the user is in their journey (e.g., "Filter outliers", "Summarize anomalies", "Draft response to client").


    Constrained Inputs: Combine natural language input with structured UI pickers, dropdowns, and sliders to eliminate syntax ambiguity before sending instructions to the model.


    2. Implement Dynamic Generative UI (Component-Driven Responses)
    Text is an output anti-pattern for structured tasks. If a user asks an AI to compare pricing plans, prioritize features, or triage bug reports:


    Anti-pattern: Generating five paragraphs of narrative text.


    Production Pattern: Render dynamic, interactive components—such as sortable data tables, diff-viewers, or interactive toggle cards. Users should be able to click, re-sort, and approve states visually without typing back-and-forth prompts.


    3. Anchor on Persistent Dual-Pane Workspaces (Canvas over Chat)
    High-leverage tasks require side-by-side execution:


    Left Pane (The Copilot / Command Layer): Handles intent generation, prompt variations, and version rollback commands.


    Right Pane (The Artifact / Canvas): Houses the persistent document, code block, dashboard, or design asset where the user retains direct editing control.


    This separates temporary conversational deliberation from the permanent artifact being built.


    Great AI product design isn't about proving how well an LLM can mimic a human conversation. It’s about building an interface that compresses cognitive load, preserves user agency, and gets the user to their desired outcome with the least amount of effort.


    Discussion Question
    For PMs and Product Designers: Where in your product workflow has a chat interface failed, and how did you pivot toward structured or canvas-based visual UI?


    CTA
    Ready to dive deep into modern AI UX patterns, product strategy, and next-generation design systems?
    👉 Join Product, UX & Design to collaborate with product managers, UX researchers, and interface designers across the Techawks community.
    The Conversational Interface Fallacy: Why Chatbots Are the Worst Pattern for Complex User Workflows When generative AI arrived, the immediate design reflex across B2B software was universal: replace dashboards, forms, and workflows with an omnipresent chatbot window. Two years into deploying AI-native products, the user feedback is clear: pure conversational interfaces create severe interaction fatigue. Chat introduces friction: The "Blank Canvas" Paradox: Users must guess what the system can and cannot do. Invisible State: You cannot scan, filter, or reorder outputs cleanly inside a sequential vertical chat log. Low Information Density: Chat is synchronous and transient, whereas complex decision-making requires persistent spatial context. The most resilient AI products aren't replacing graphical interfaces with natural language—they are adopting Hybrid Canvas Architectures (Intent Scaffolding + Generative UI). Plaintext [ ANTI-PATTERN: THE UNBOUNDED CHAT WRAPPER ] User Intent ──► Open Text Box ("What can you do?") ──► High Prompt Friction ──► Wall of Text Output ──► Low Interaction / Drop-off [ PRODUCTION PATTERN: HYBRID CANVAS & GENERATIVE UI ] Action Trigger ──► Contextual Intent Chips ──► Dynamic Visual Component (Data Table / Form / Canvas) ──► Direct Spatial Manipulation ──► State Persistence Here is how modern product managers and UX architects design generative experiences that drive real product adoption: 1. Shift from Open Prompts to "Scaffolded Intent" Never make the user initiate from zero. Replace bare text prompts with contextual, dynamic affordances: Contextual Suggestions: Display intent "chips" or micro-actions based on where the user is in their journey (e.g., "Filter outliers", "Summarize anomalies", "Draft response to client"). Constrained Inputs: Combine natural language input with structured UI pickers, dropdowns, and sliders to eliminate syntax ambiguity before sending instructions to the model. 2. Implement Dynamic Generative UI (Component-Driven Responses) Text is an output anti-pattern for structured tasks. If a user asks an AI to compare pricing plans, prioritize features, or triage bug reports: Anti-pattern: Generating five paragraphs of narrative text. Production Pattern: Render dynamic, interactive components—such as sortable data tables, diff-viewers, or interactive toggle cards. Users should be able to click, re-sort, and approve states visually without typing back-and-forth prompts. 3. Anchor on Persistent Dual-Pane Workspaces (Canvas over Chat) High-leverage tasks require side-by-side execution: Left Pane (The Copilot / Command Layer): Handles intent generation, prompt variations, and version rollback commands. Right Pane (The Artifact / Canvas): Houses the persistent document, code block, dashboard, or design asset where the user retains direct editing control. This separates temporary conversational deliberation from the permanent artifact being built. Great AI product design isn't about proving how well an LLM can mimic a human conversation. It’s about building an interface that compresses cognitive load, preserves user agency, and gets the user to their desired outcome with the least amount of effort. Discussion Question For PMs and Product Designers: Where in your product workflow has a chat interface failed, and how did you pivot toward structured or canvas-based visual UI? CTA Ready to dive deep into modern AI UX patterns, product strategy, and next-generation design systems? 👉 Join Product, UX & Design to collaborate with product managers, UX researchers, and interface designers across the Techawks community.
    0 Commentarii 0 Distribuiri 60 Views 0 previzualizare
  • The 80% Gross Margin Illusion: Why AI Startups Are Quietly Bleeding Runway
    For fifteen years, B2B software companies traded on a single fundamental assumption: an 80%+ gross margin. You wrote the code once, hosted it on commodity cloud VMs, and served millions of requests for fractions of a cent.In AI products, this assumption has collapsed.
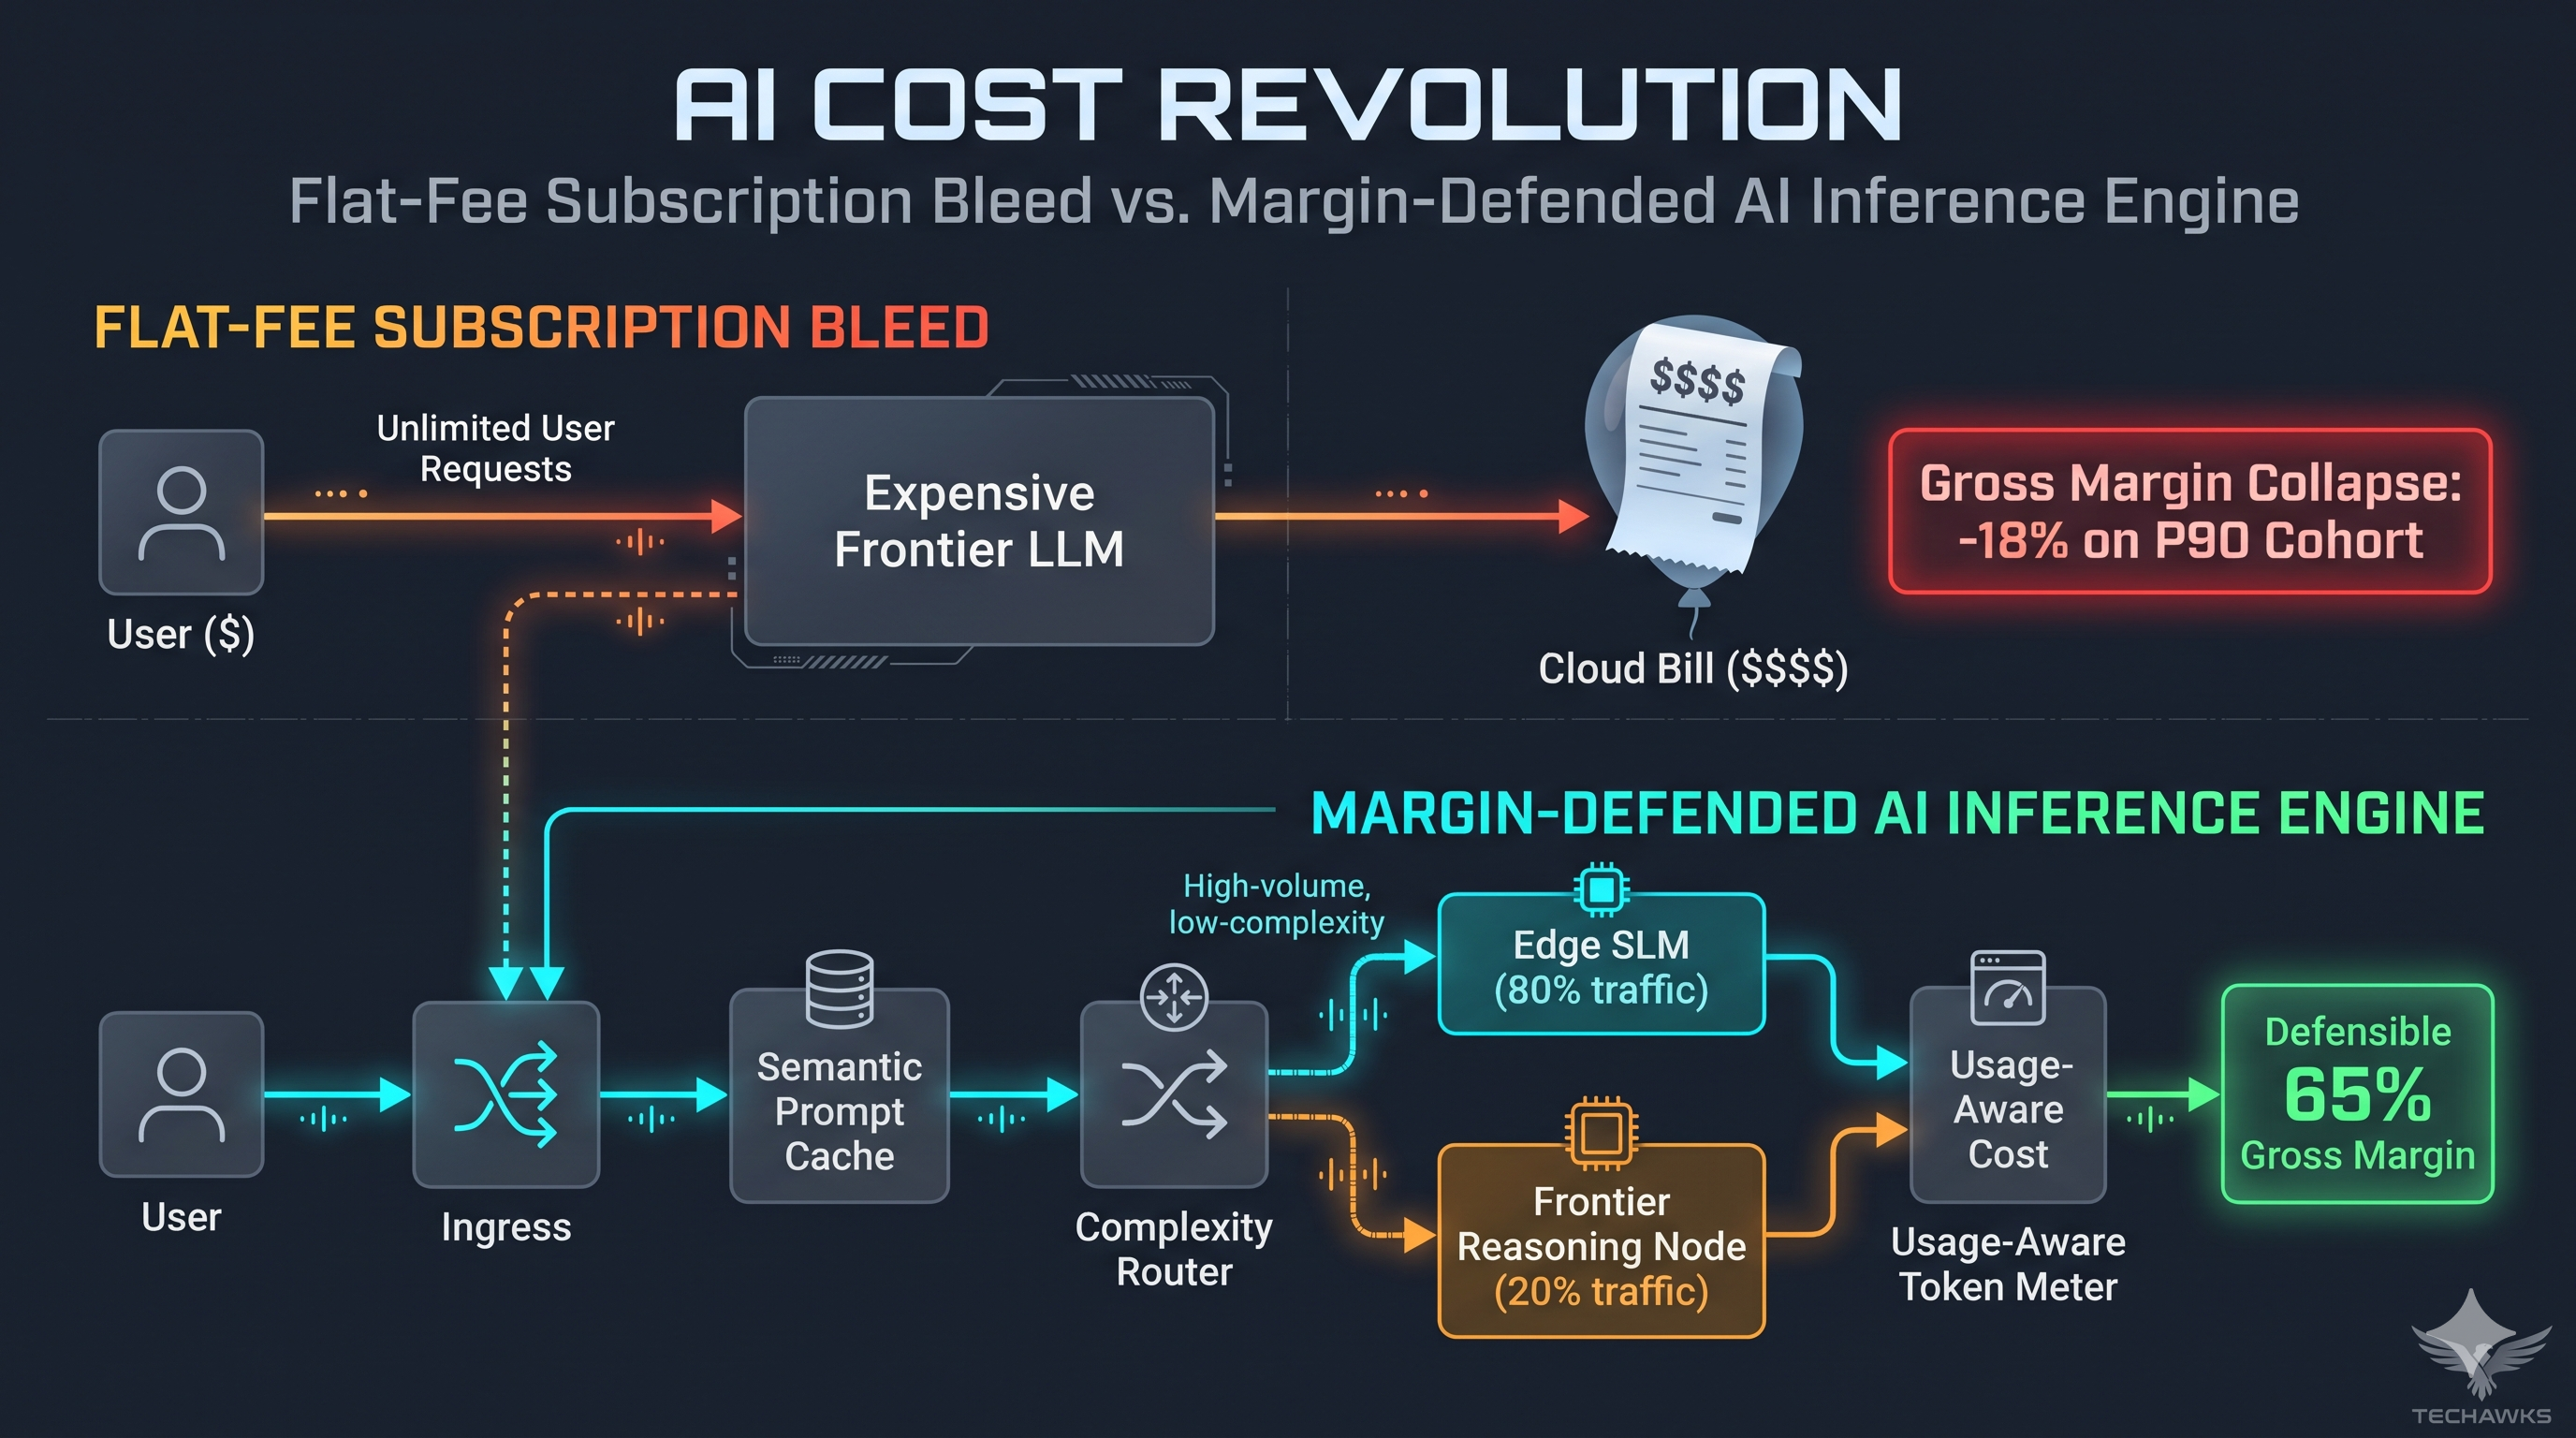
    Recent enterprise benchmark data reveals that AI software operates at an average gross margin of 50% to 60% (with unoptimized architectures dipping below 40%). The culprit isn't marketing spend or customer acquisition—it is treating non-deterministic model inference like general operating expenses (OpEx) instead of direct Cost of Goods Sold (COGS).Plaintext[ ANTI-PATTERN: FLAT-FEE SUBSCRIPTION SQUEEZE ]
    User Subscribes ($49/mo) ──► Unbounded LLM Calls ──► Top 10% Power Users (10x Token Load) ──► Serving Cost ($68/mo) ──► Negative Gross Margin / Cash Bleed


    [ PRODUCTION PATTERN: MARGIN-DEFENDED VALUE ENGINE ]
    User Ingress ──► Semantic Cache (Free Hit) ──► Complexity Classifier ──► Tiered Routing (SLM vs Frontier) ──► Usage-Aware Pricing Floor ──► Defensible 65%+ Margin
    If you are building an AI startup, you cannot wait until your Series A data room to fix unit economics. Here is the operational framework to defend your margins from day one:
    1. Measure AI-Adjusted Gross Margin (COGS Separation)Stop burying LLM API bills, fine-tuning compute, and vector database queries inside general cloud infrastructure.
    Calculate your Inference Cost Ratio ($\frac{\text{Direct Inference Costs}}{\text{Gross Revenue}}$) per customer cohort.
    Isolate your P90 and P99 users. In unmetered flat-fee models, the top decile of power users routinely consumes 10x the median token volume, turning enterprise contract wins into net-negative margin liabilities.
    2. Implement Dynamic Cascading Model RoutingNever hit an expensive frontier model (e.g., $5 to $15 per million tokens) for tasks that a distilled, specialized small language model (SLM) can handle at a 90% discount.
    Tier 1 (Deterministic/Cached): Semantic caching handles recurring user queries and system prompts before touching a model bus.
    Tier 2 (Classification & Extraction): Lightweight, fine-tuned 1B–8B parameter models handle structural parsing, entity extraction, and intent classification.
    Tier 3 (Complex Synthesis): Frontier models are invoked strictly for complex multi-hop reasoning or ambiguous edge cases.3. Shift from Seat-Based to Value-Metric & Hybrid BillingFlat per-seat pricing with uncapped generative capabilities is an open-ended liability. The SaaS pricing playbook has changed:
    Transition to a base platform fee + consumption-aware credit tiers.Set strict internal soft-caps or token allowances tied directly to the contract price.
    Anchor pricing on delivered customer value (e.g., per resolved ticket, per qualified lead, or per verified workflow) rather than passing raw token consumption through to the customer.
    In the current funding climate, investors don't reward vanity top-line growth backed by subsidizing model compute. The founders who build resilient, lasting companies will be those who can defend durable unit economics at scale.
    Discussion Question
    Founders: How are you managing inference unit economics today—pure flat tiers with fair-use limits, credits-based billing, or dynamic model routing under the hood? What surprised you most about your P90 user costs?
    CTA
    Scaling an AI venture and navigating early-stage product economics, fundraising, and architecture?
    👉 Join Startup Founders & Entrepreneurs to share playbooks, benchmark metrics, and build alongside fellow tech founders in the Techawks network.
    The 80% Gross Margin Illusion: Why AI Startups Are Quietly Bleeding Runway For fifteen years, B2B software companies traded on a single fundamental assumption: an 80%+ gross margin. You wrote the code once, hosted it on commodity cloud VMs, and served millions of requests for fractions of a cent.In AI products, this assumption has collapsed. Recent enterprise benchmark data reveals that AI software operates at an average gross margin of 50% to 60% (with unoptimized architectures dipping below 40%). The culprit isn't marketing spend or customer acquisition—it is treating non-deterministic model inference like general operating expenses (OpEx) instead of direct Cost of Goods Sold (COGS).Plaintext[ ANTI-PATTERN: FLAT-FEE SUBSCRIPTION SQUEEZE ] User Subscribes ($49/mo) ──► Unbounded LLM Calls ──► Top 10% Power Users (10x Token Load) ──► Serving Cost ($68/mo) ──► Negative Gross Margin / Cash Bleed [ PRODUCTION PATTERN: MARGIN-DEFENDED VALUE ENGINE ] User Ingress ──► Semantic Cache (Free Hit) ──► Complexity Classifier ──► Tiered Routing (SLM vs Frontier) ──► Usage-Aware Pricing Floor ──► Defensible 65%+ Margin If you are building an AI startup, you cannot wait until your Series A data room to fix unit economics. Here is the operational framework to defend your margins from day one: 1. Measure AI-Adjusted Gross Margin (COGS Separation)Stop burying LLM API bills, fine-tuning compute, and vector database queries inside general cloud infrastructure. Calculate your Inference Cost Ratio ($\frac{\text{Direct Inference Costs}}{\text{Gross Revenue}}$) per customer cohort. Isolate your P90 and P99 users. In unmetered flat-fee models, the top decile of power users routinely consumes 10x the median token volume, turning enterprise contract wins into net-negative margin liabilities. 2. Implement Dynamic Cascading Model RoutingNever hit an expensive frontier model (e.g., $5 to $15 per million tokens) for tasks that a distilled, specialized small language model (SLM) can handle at a 90% discount. Tier 1 (Deterministic/Cached): Semantic caching handles recurring user queries and system prompts before touching a model bus. Tier 2 (Classification & Extraction): Lightweight, fine-tuned 1B–8B parameter models handle structural parsing, entity extraction, and intent classification. Tier 3 (Complex Synthesis): Frontier models are invoked strictly for complex multi-hop reasoning or ambiguous edge cases.3. Shift from Seat-Based to Value-Metric & Hybrid BillingFlat per-seat pricing with uncapped generative capabilities is an open-ended liability. The SaaS pricing playbook has changed: Transition to a base platform fee + consumption-aware credit tiers.Set strict internal soft-caps or token allowances tied directly to the contract price. Anchor pricing on delivered customer value (e.g., per resolved ticket, per qualified lead, or per verified workflow) rather than passing raw token consumption through to the customer. In the current funding climate, investors don't reward vanity top-line growth backed by subsidizing model compute. The founders who build resilient, lasting companies will be those who can defend durable unit economics at scale. Discussion Question Founders: How are you managing inference unit economics today—pure flat tiers with fair-use limits, credits-based billing, or dynamic model routing under the hood? What surprised you most about your P90 user costs? CTA Scaling an AI venture and navigating early-stage product economics, fundraising, and architecture? 👉 Join Startup Founders & Entrepreneurs to share playbooks, benchmark metrics, and build alongside fellow tech founders in the Techawks network.
    0 Commentarii 0 Distribuiri 61 Views 0 previzualizare
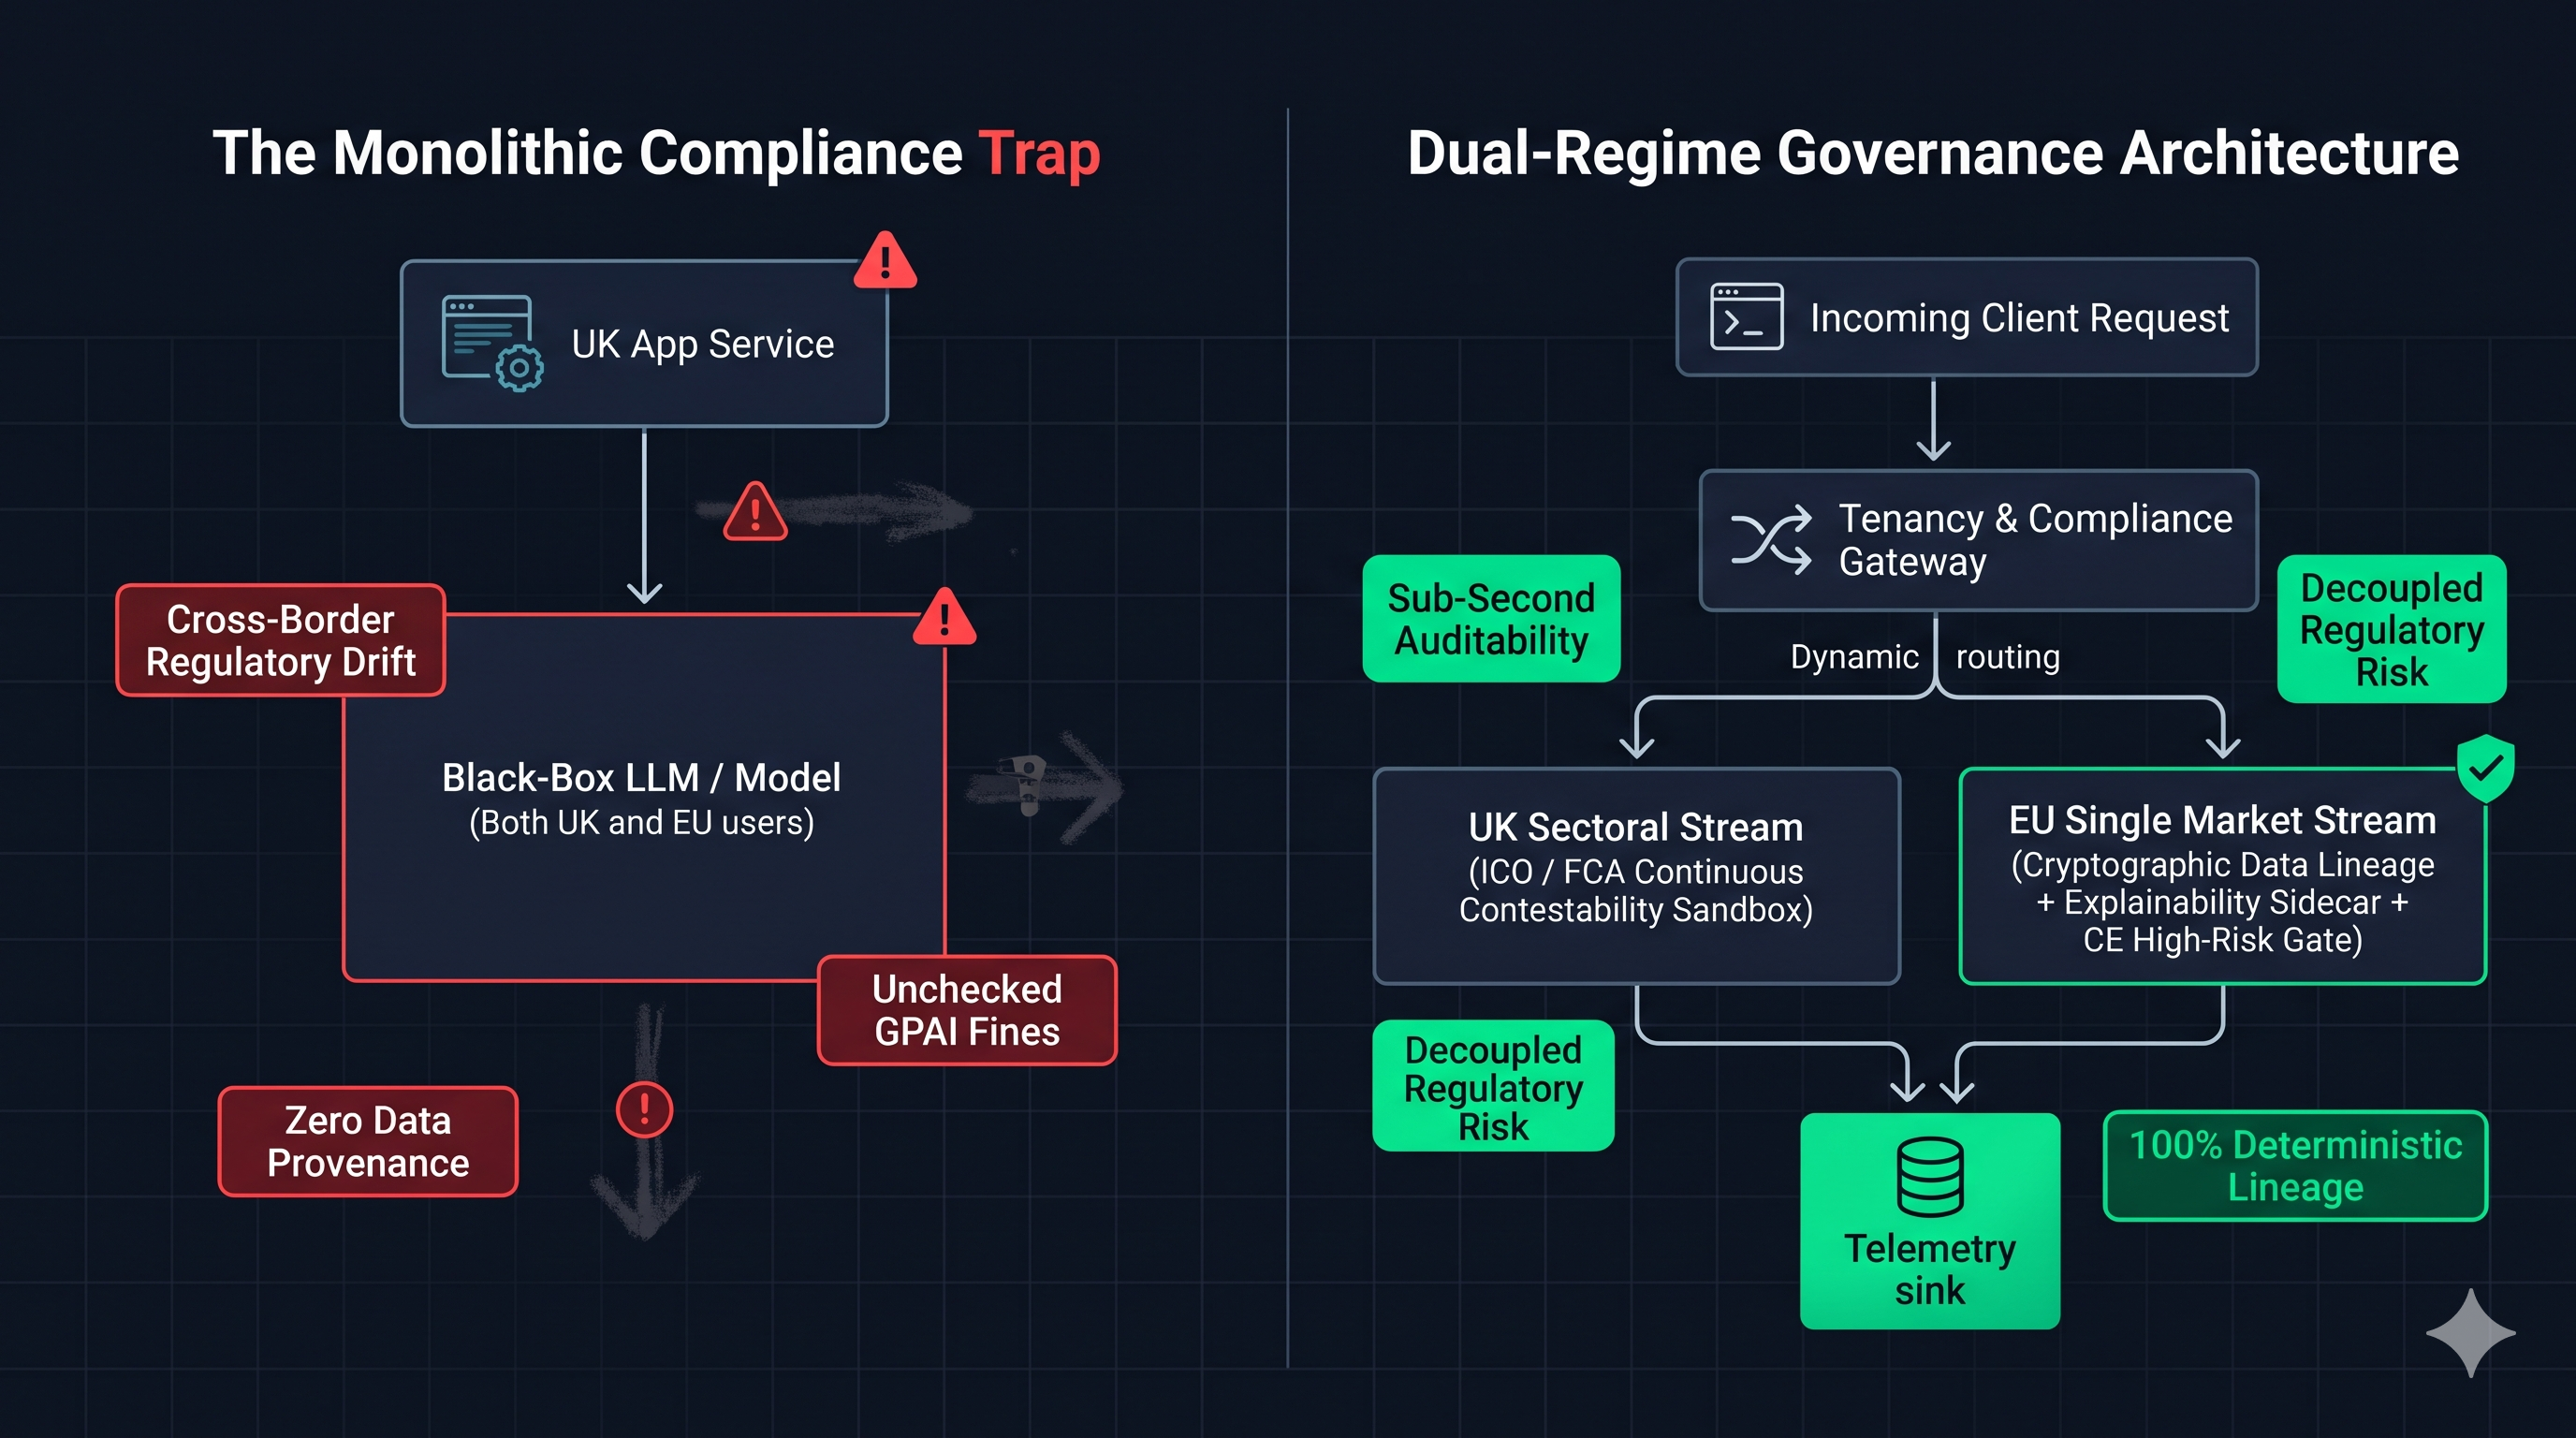
  • The UK-EU AI Divide: Why Engineering Teams Must Architect Dual-Regime Model Governance
    The United Kingdom and the European Union have taken fundamentally opposing paths to artificial intelligence oversight:


    The UK’s Sectoral, Principles-Led Model: The UK deliberately avoided an omnibus horizontal AI statute, instead distributing oversight across established statutory regulators (FCA, ICO, CMA, Ofcom) coordinated via the Digital Regulation Cooperation Forum (DRCF) and DSIT’s central risk functions. It prioritizes outcomes, contextual safety, and sandboxes over blanket technical mandates.


    The EU AI Act’s Strict Classification: The EU enforces horizontal risk tiers with severe penalties (up to €35 million or 7% of global turnover) for high-risk and general-purpose AI (GPAI) systems.


    Here is the engineering reality for UK tech companies: regulatory jurisdiction attaches to user impact, not deployment origin.


    If a UK-headquartered fintech, healthtech, or SaaS product processes inputs or delivers automated decisions impacting users inside the EU single market, your pipeline immediately falls under the EU AI Act’s high-risk obligations. Treating compliance as an afterthought handled by legal teams creates architectural gridlock.


    The Technical Solution: Dual-Regime Telemetry & Lineage Gates
    Forward-thinking UK software architects are decoupling regional compliance into deterministic system abstractions:


    Deterministic Data Lineage & Training Governance:


    High-risk classifications require rigorous data provenance. Implement cryptographic data hashing and metadata tracing across datasets (capturing demographic distribution, synthetic data ratios, and curation flags).


    If a model variant serves an EU endpoint, the ingestion pipeline must deterministically verify that training data governance meets strict accuracy, statistical representation, and bias audits before inference promotion.


    Decoupled Explainability & Continuous Drift Probes:


    The UK's ICO guidelines and the FCA’s AI experimentation frameworks emphasize contestability and transparency—requiring clear auditability for automated financial and identity profiling.


    Do not rely on black-box model outputs. Integrate decoupled feature attribution modules (e.g., integrated gradients or TreeSHAP sidecars) that emit machine-readable rationale logs for every automated classification, enabling sub-second audit reconstruction.


    Runtime Geo-Partitioning & Model Tiering:


    Route user queries through an API gateway middleware that evaluates geographic tenancy and regulatory classification.


    An identical user request originating from Manchester vs. Dublin can be dynamically routed to different backend model checkpoints or policy-enforced guardrail nodes—satisfying strict EU CE-marking and technical documentation gates while taking full advantage of UK sandbox iterations.


    In modern systems engineering, compliance cannot be a periodic manual audit. It must be built directly into your CI/CD pipelines, telemetry schemas, and routing layers.


    Discussion Question
    For UK software teams serving both domestic and European users: are you maintaining unified model pipelines with the strictest common denominator compliance, or have you architected dual-regime routing and automated data lineage gates?


    CTA
    Join Techawks UK: Connect with leading British software architects, fintech engineering leads, and technical founders discussing resilient distributed architectures, AI governance, and UK-global scaling inside the Techawks UK community. Link in bio/comments.
    The UK-EU AI Divide: Why Engineering Teams Must Architect Dual-Regime Model Governance The United Kingdom and the European Union have taken fundamentally opposing paths to artificial intelligence oversight: The UK’s Sectoral, Principles-Led Model: The UK deliberately avoided an omnibus horizontal AI statute, instead distributing oversight across established statutory regulators (FCA, ICO, CMA, Ofcom) coordinated via the Digital Regulation Cooperation Forum (DRCF) and DSIT’s central risk functions. It prioritizes outcomes, contextual safety, and sandboxes over blanket technical mandates. The EU AI Act’s Strict Classification: The EU enforces horizontal risk tiers with severe penalties (up to €35 million or 7% of global turnover) for high-risk and general-purpose AI (GPAI) systems. Here is the engineering reality for UK tech companies: regulatory jurisdiction attaches to user impact, not deployment origin. If a UK-headquartered fintech, healthtech, or SaaS product processes inputs or delivers automated decisions impacting users inside the EU single market, your pipeline immediately falls under the EU AI Act’s high-risk obligations. Treating compliance as an afterthought handled by legal teams creates architectural gridlock. The Technical Solution: Dual-Regime Telemetry & Lineage Gates Forward-thinking UK software architects are decoupling regional compliance into deterministic system abstractions: Deterministic Data Lineage & Training Governance: High-risk classifications require rigorous data provenance. Implement cryptographic data hashing and metadata tracing across datasets (capturing demographic distribution, synthetic data ratios, and curation flags). If a model variant serves an EU endpoint, the ingestion pipeline must deterministically verify that training data governance meets strict accuracy, statistical representation, and bias audits before inference promotion. Decoupled Explainability & Continuous Drift Probes: The UK's ICO guidelines and the FCA’s AI experimentation frameworks emphasize contestability and transparency—requiring clear auditability for automated financial and identity profiling. Do not rely on black-box model outputs. Integrate decoupled feature attribution modules (e.g., integrated gradients or TreeSHAP sidecars) that emit machine-readable rationale logs for every automated classification, enabling sub-second audit reconstruction. Runtime Geo-Partitioning & Model Tiering: Route user queries through an API gateway middleware that evaluates geographic tenancy and regulatory classification. An identical user request originating from Manchester vs. Dublin can be dynamically routed to different backend model checkpoints or policy-enforced guardrail nodes—satisfying strict EU CE-marking and technical documentation gates while taking full advantage of UK sandbox iterations. In modern systems engineering, compliance cannot be a periodic manual audit. It must be built directly into your CI/CD pipelines, telemetry schemas, and routing layers. Discussion Question For UK software teams serving both domestic and European users: are you maintaining unified model pipelines with the strictest common denominator compliance, or have you architected dual-regime routing and automated data lineage gates? CTA Join Techawks UK: Connect with leading British software architects, fintech engineering leads, and technical founders discussing resilient distributed architectures, AI governance, and UK-global scaling inside the Techawks UK community. Link in bio/comments.
    0 Commentarii 0 Distribuiri 58 Views 0 previzualizare
  • The 2 Gigawatt Grid Ceiling: Why US Cloud Architects Are Designing for Carbon-Aware Spatial Load Shifting
    For the past decade, cloud system architecture treated power and cooling as infinite abstract utilities managed by AWS, Azure, or GCP. You provisioned instances, autoscale groups expanded, and the underlying datacenter absorbed the draw.


    In the US tech corridor, that abstraction has broken down.


    With PJM Interconnection facing over 70 GW of prospective large-load requests and regional transmission queues stretching 5 to 7 years, regulatory bodies (FERC) and regional transmission organizations (RTOs) are capping unbacked firm grid access. The limiting constraint on US enterprise AI compute is no longer chip availability—it is electrical grid interconnects and substation thermal limits.


    Engineering teams scaling massive AI pipelines cannot wait for multi-year transmission line overhauls. Instead, top infrastructure architects are transitioning from static, monolithic datacenter footprints to Grid-Aware Spatial Load Shifting:


    1. Decoupling Batch Pre-training from Real-Time Inference
    Inference workloads require strict low-latency proximity to end users (e.g., US-East / US-West metros). Massive batch jobs—such as fine-tuning, synthetic data generation, and offline embedding runs—do not.


    System schedulers must treat electrical grid marginal emissions and real-time megawatt pricing (locational marginal pricing, or LMP) as dynamic orchestration parameters.


    When grid reserve margins tighten in PJM (Mid-Atlantic) during peak summer or winter heating alerts, control planes must automatically throttle or migrate non-urgent checkpoint jobs to regions with surplus renewable generation (such as ERCOT wind during off-peak hours or MISO hydro/solar).


    2. Hardware-Aware Dynamic Power Throttling
    Training clusters generate extreme step-function load spikes during distributed all-reduce synchronization barriers.


    Instead of designing power delivery strictly for unmitigated peak wattage (which drives up capacity interconnection costs), modern orchestrators enforce dynamic power-capping at the server baseboard management controller (BMC) level.


    By shaving off the top 10% of transient power spikes via micro-throttling clock frequencies during communication phases, facilities fit up to 20% more accelerator density within existing utility interconnection limits.


    3. Ephemeral Cross-Region Checkpointing (Disaster & Curtailment Recovery)
    As grid operators debate conditional curtailment rules for unsupported high-density loads, applications must treat cluster power as potentially non-firm.


    Production distributed training jobs must implement sub-minute distributed checkpointing to asynchronous object stores. If a facility receives a Demand Response (DR) signal, workloads pause cleanly, state flushes, and worker pools rehydrate in alternative geographic zones without corrupted weights.


    Software engineers used to optimize for bytes and cycles. The next generation of lead cloud architects must master megawatt curves, transmission topology, and grid elasticity.


    Discussion Question
    As US power constraints reshape datacenter capacity across major tech hubs, is your team actively engineering carbon-aware or energy-scheduled workload migration across cloud regions, or are you still relying on single-region multi-zone provisioning?


    CTA
    Join Techawks USA: Connect with lead cloud infrastructure architects, principal systems engineers, and DevOps directors discussing large-scale cloud resilience, power-constrained architectures, and next-gen US tech infrastructure. Link in bio/comments.
    The 2 Gigawatt Grid Ceiling: Why US Cloud Architects Are Designing for Carbon-Aware Spatial Load Shifting For the past decade, cloud system architecture treated power and cooling as infinite abstract utilities managed by AWS, Azure, or GCP. You provisioned instances, autoscale groups expanded, and the underlying datacenter absorbed the draw. In the US tech corridor, that abstraction has broken down. With PJM Interconnection facing over 70 GW of prospective large-load requests and regional transmission queues stretching 5 to 7 years, regulatory bodies (FERC) and regional transmission organizations (RTOs) are capping unbacked firm grid access. The limiting constraint on US enterprise AI compute is no longer chip availability—it is electrical grid interconnects and substation thermal limits. Engineering teams scaling massive AI pipelines cannot wait for multi-year transmission line overhauls. Instead, top infrastructure architects are transitioning from static, monolithic datacenter footprints to Grid-Aware Spatial Load Shifting: 1. Decoupling Batch Pre-training from Real-Time Inference Inference workloads require strict low-latency proximity to end users (e.g., US-East / US-West metros). Massive batch jobs—such as fine-tuning, synthetic data generation, and offline embedding runs—do not. System schedulers must treat electrical grid marginal emissions and real-time megawatt pricing (locational marginal pricing, or LMP) as dynamic orchestration parameters. When grid reserve margins tighten in PJM (Mid-Atlantic) during peak summer or winter heating alerts, control planes must automatically throttle or migrate non-urgent checkpoint jobs to regions with surplus renewable generation (such as ERCOT wind during off-peak hours or MISO hydro/solar). 2. Hardware-Aware Dynamic Power Throttling Training clusters generate extreme step-function load spikes during distributed all-reduce synchronization barriers. Instead of designing power delivery strictly for unmitigated peak wattage (which drives up capacity interconnection costs), modern orchestrators enforce dynamic power-capping at the server baseboard management controller (BMC) level. By shaving off the top 10% of transient power spikes via micro-throttling clock frequencies during communication phases, facilities fit up to 20% more accelerator density within existing utility interconnection limits. 3. Ephemeral Cross-Region Checkpointing (Disaster & Curtailment Recovery) As grid operators debate conditional curtailment rules for unsupported high-density loads, applications must treat cluster power as potentially non-firm. Production distributed training jobs must implement sub-minute distributed checkpointing to asynchronous object stores. If a facility receives a Demand Response (DR) signal, workloads pause cleanly, state flushes, and worker pools rehydrate in alternative geographic zones without corrupted weights. Software engineers used to optimize for bytes and cycles. The next generation of lead cloud architects must master megawatt curves, transmission topology, and grid elasticity. Discussion Question As US power constraints reshape datacenter capacity across major tech hubs, is your team actively engineering carbon-aware or energy-scheduled workload migration across cloud regions, or are you still relying on single-region multi-zone provisioning? CTA Join Techawks USA: Connect with lead cloud infrastructure architects, principal systems engineers, and DevOps directors discussing large-scale cloud resilience, power-constrained architectures, and next-gen US tech infrastructure. Link in bio/comments.
    0 Commentarii 0 Distribuiri 65 Views 0 previzualizare
Sponsorizeaza Paginile