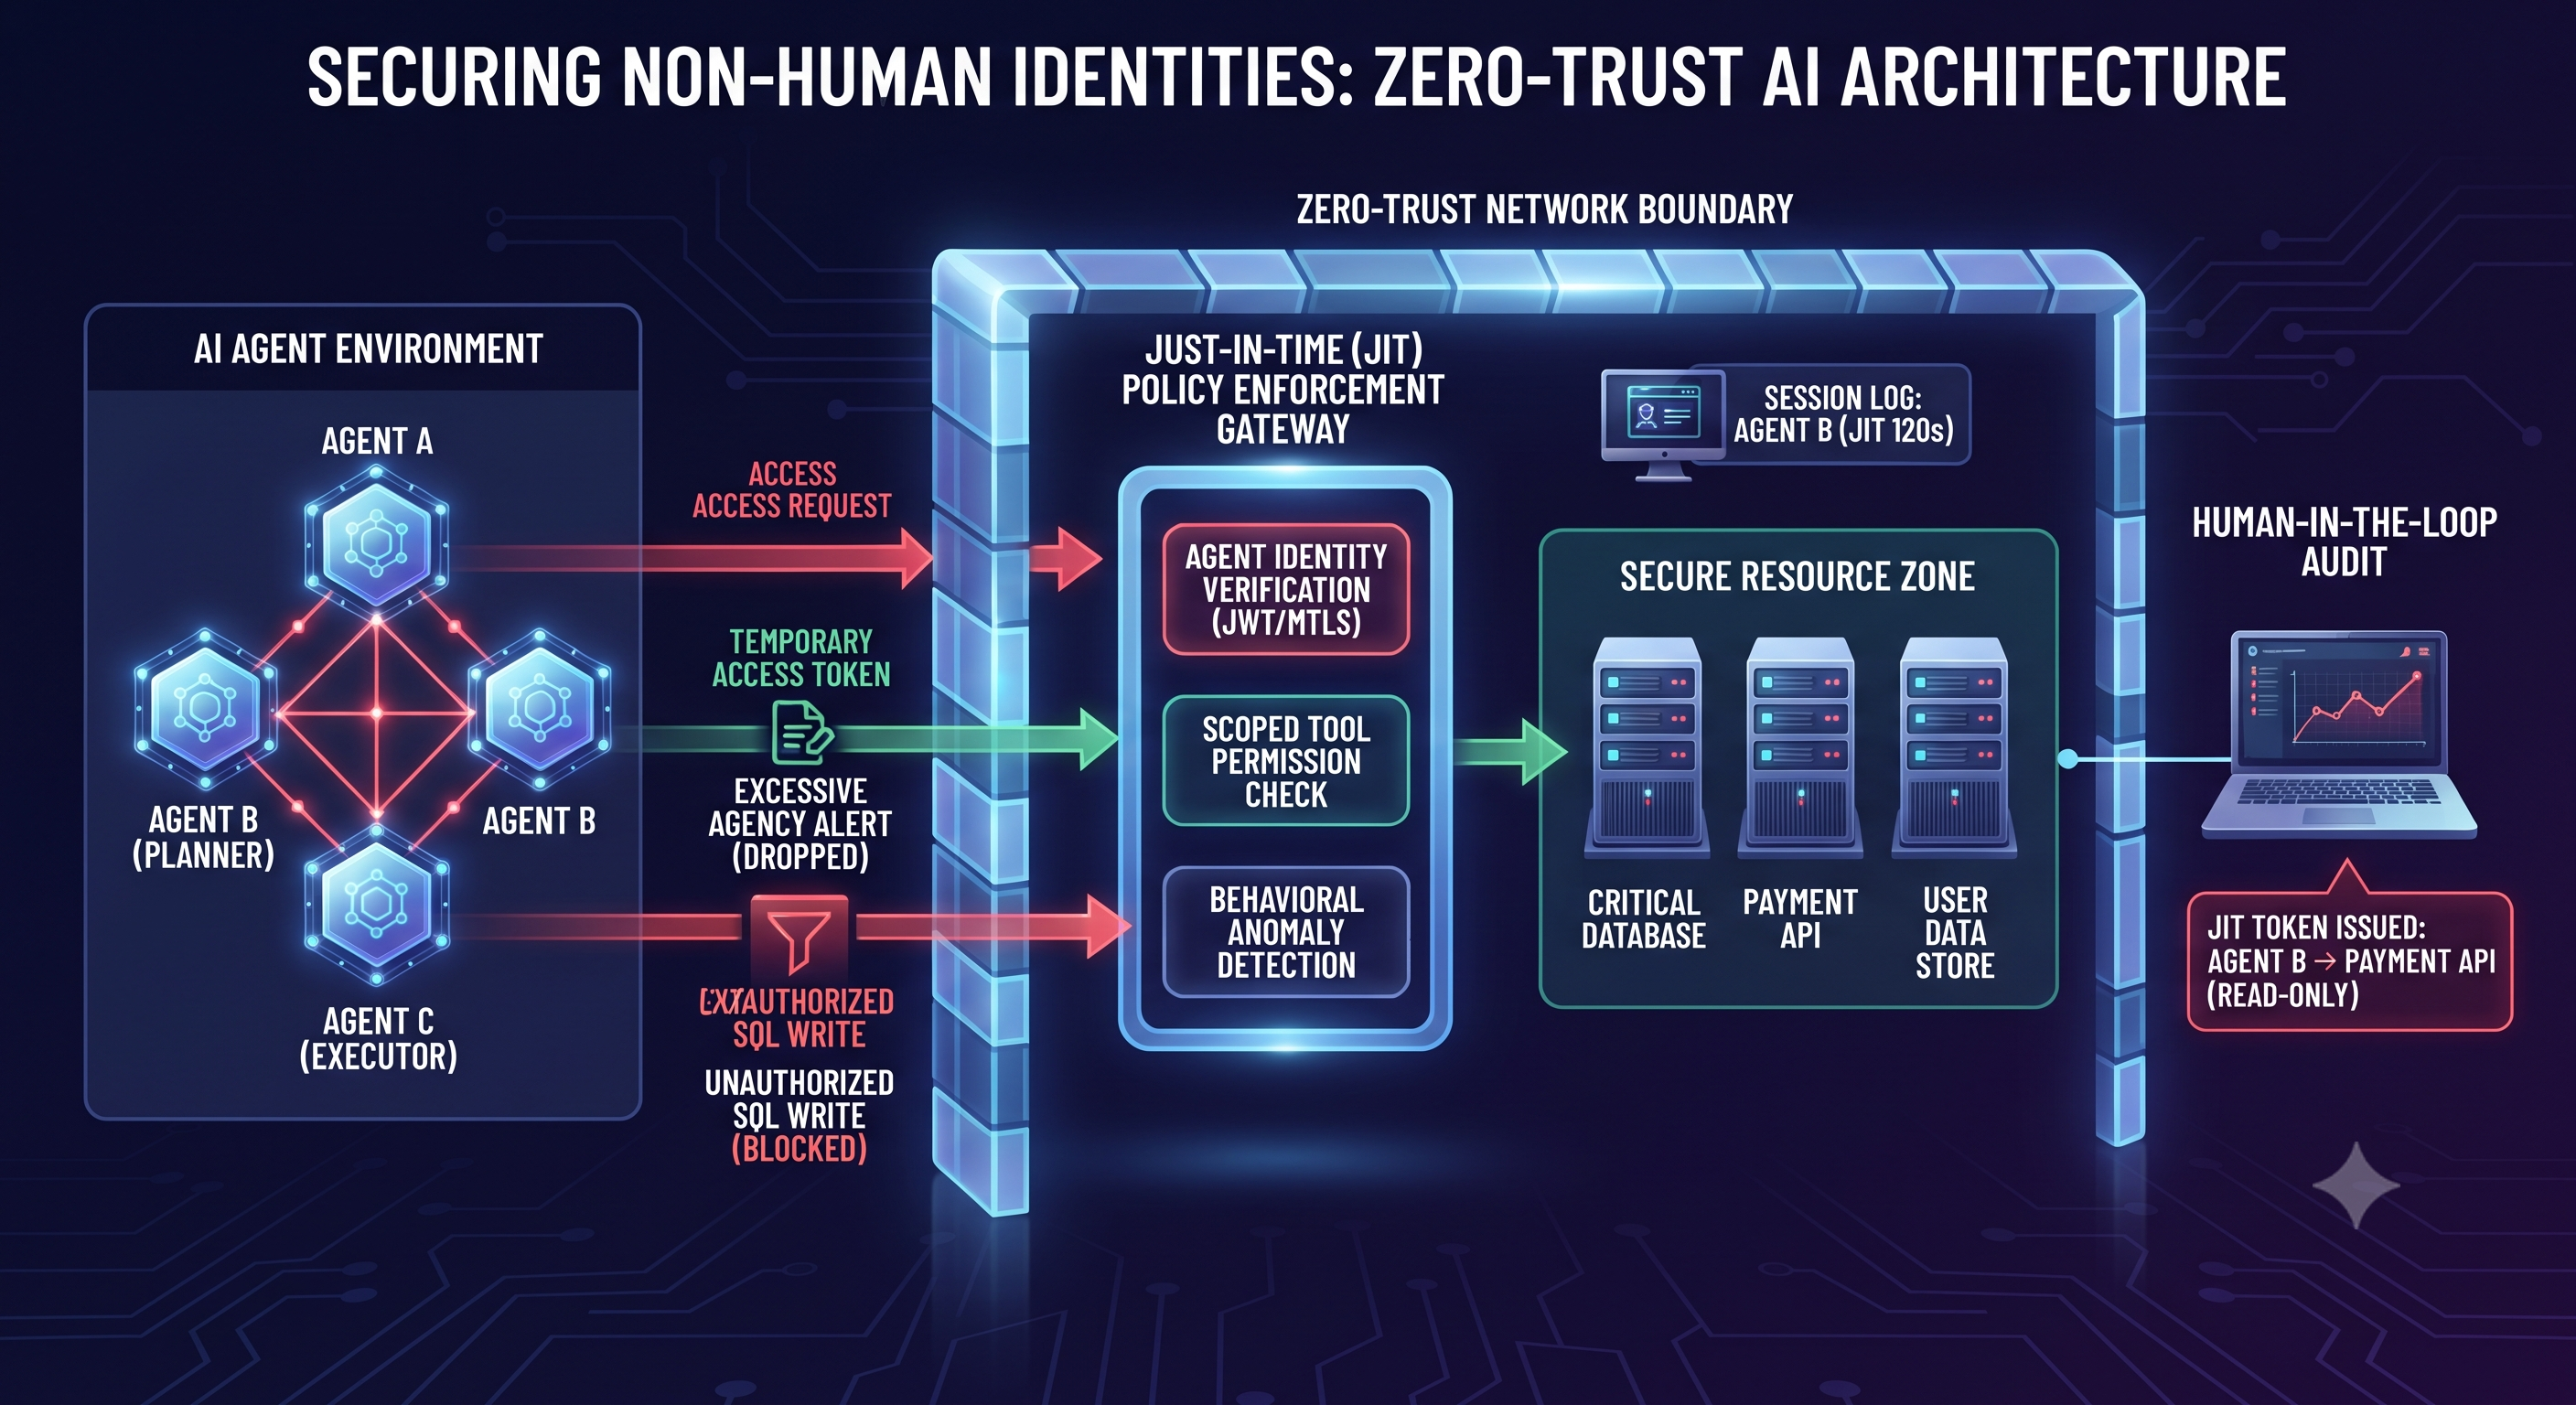
• Beyond Traditional Perimeters: Securing Non-Human Identities in Agentic AI Architectures


    As engineering teams transition from static chatbots to autonomous multi-agent systems, the security paradigm has fundamentally shifted. AI agents are no longer passive tools waiting for input; they actively query databases, invoke APIs, and execute workflows across distributed environments.


    However, organizations frequently assign these non-human identities broad, standing privileges or shared API keys inherited from development environments.


    Why it matters:
    When an autonomous agent operates with excessive agency or unconstrained tool permissions, a single prompt injection or agent goal hijack can grant attackers system-wide lateral movement without ever triggering traditional identity alerts. Traditional perimeter defenses crumble when the threat originates from a compromised, trusted internal agent loop.


    How to secure it (The Defensive Blueprint):


    Enforce Least-Privilege Scoping: Never give an AI agent standing database write permissions or broad service keys. Scope credentials strictly to the specific tool execution required for the immediate task.


    Implement Just-In-Time (JIT) Access: Replace long-lived API secrets with short-lived, dynamically generated tokens that expire immediately upon task completion.


    Deterministic Inter-Agent Validation: Never allow agents to trust downstream or upstream communications blindly. Enforce cryptographic identity verification and schema validation at every single inter-agent handoff.


    Discussion Question: How is your security team auditing non-human identities and tool permissions across your AI workflows? Are you relying on static API keys or implementing JIT access controls?


    CTA (Join Cybersecurity & Ethical Hacking): Ready to master the cutting edge of threat defense and secure next-gen infrastructure? Join the Cybersecurity & Ethical Hacking community to connect with security professionals and ethical hackers shaping resilient systems.
    Beyond Traditional Perimeters: Securing Non-Human Identities in Agentic AI Architectures As engineering teams transition from static chatbots to autonomous multi-agent systems, the security paradigm has fundamentally shifted. AI agents are no longer passive tools waiting for input; they actively query databases, invoke APIs, and execute workflows across distributed environments. However, organizations frequently assign these non-human identities broad, standing privileges or shared API keys inherited from development environments. Why it matters: When an autonomous agent operates with excessive agency or unconstrained tool permissions, a single prompt injection or agent goal hijack can grant attackers system-wide lateral movement without ever triggering traditional identity alerts. Traditional perimeter defenses crumble when the threat originates from a compromised, trusted internal agent loop. How to secure it (The Defensive Blueprint): Enforce Least-Privilege Scoping: Never give an AI agent standing database write permissions or broad service keys. Scope credentials strictly to the specific tool execution required for the immediate task. Implement Just-In-Time (JIT) Access: Replace long-lived API secrets with short-lived, dynamically generated tokens that expire immediately upon task completion. Deterministic Inter-Agent Validation: Never allow agents to trust downstream or upstream communications blindly. Enforce cryptographic identity verification and schema validation at every single inter-agent handoff. Discussion Question: How is your security team auditing non-human identities and tool permissions across your AI workflows? Are you relying on static API keys or implementing JIT access controls? CTA (Join Cybersecurity & Ethical Hacking): Ready to master the cutting edge of threat defense and secure next-gen infrastructure? Join the Cybersecurity & Ethical Hacking community to connect with security professionals and ethical hackers shaping resilient systems.
    0 Comentários 0 Compartilhamentos 27 Visualizações 0 Anterior
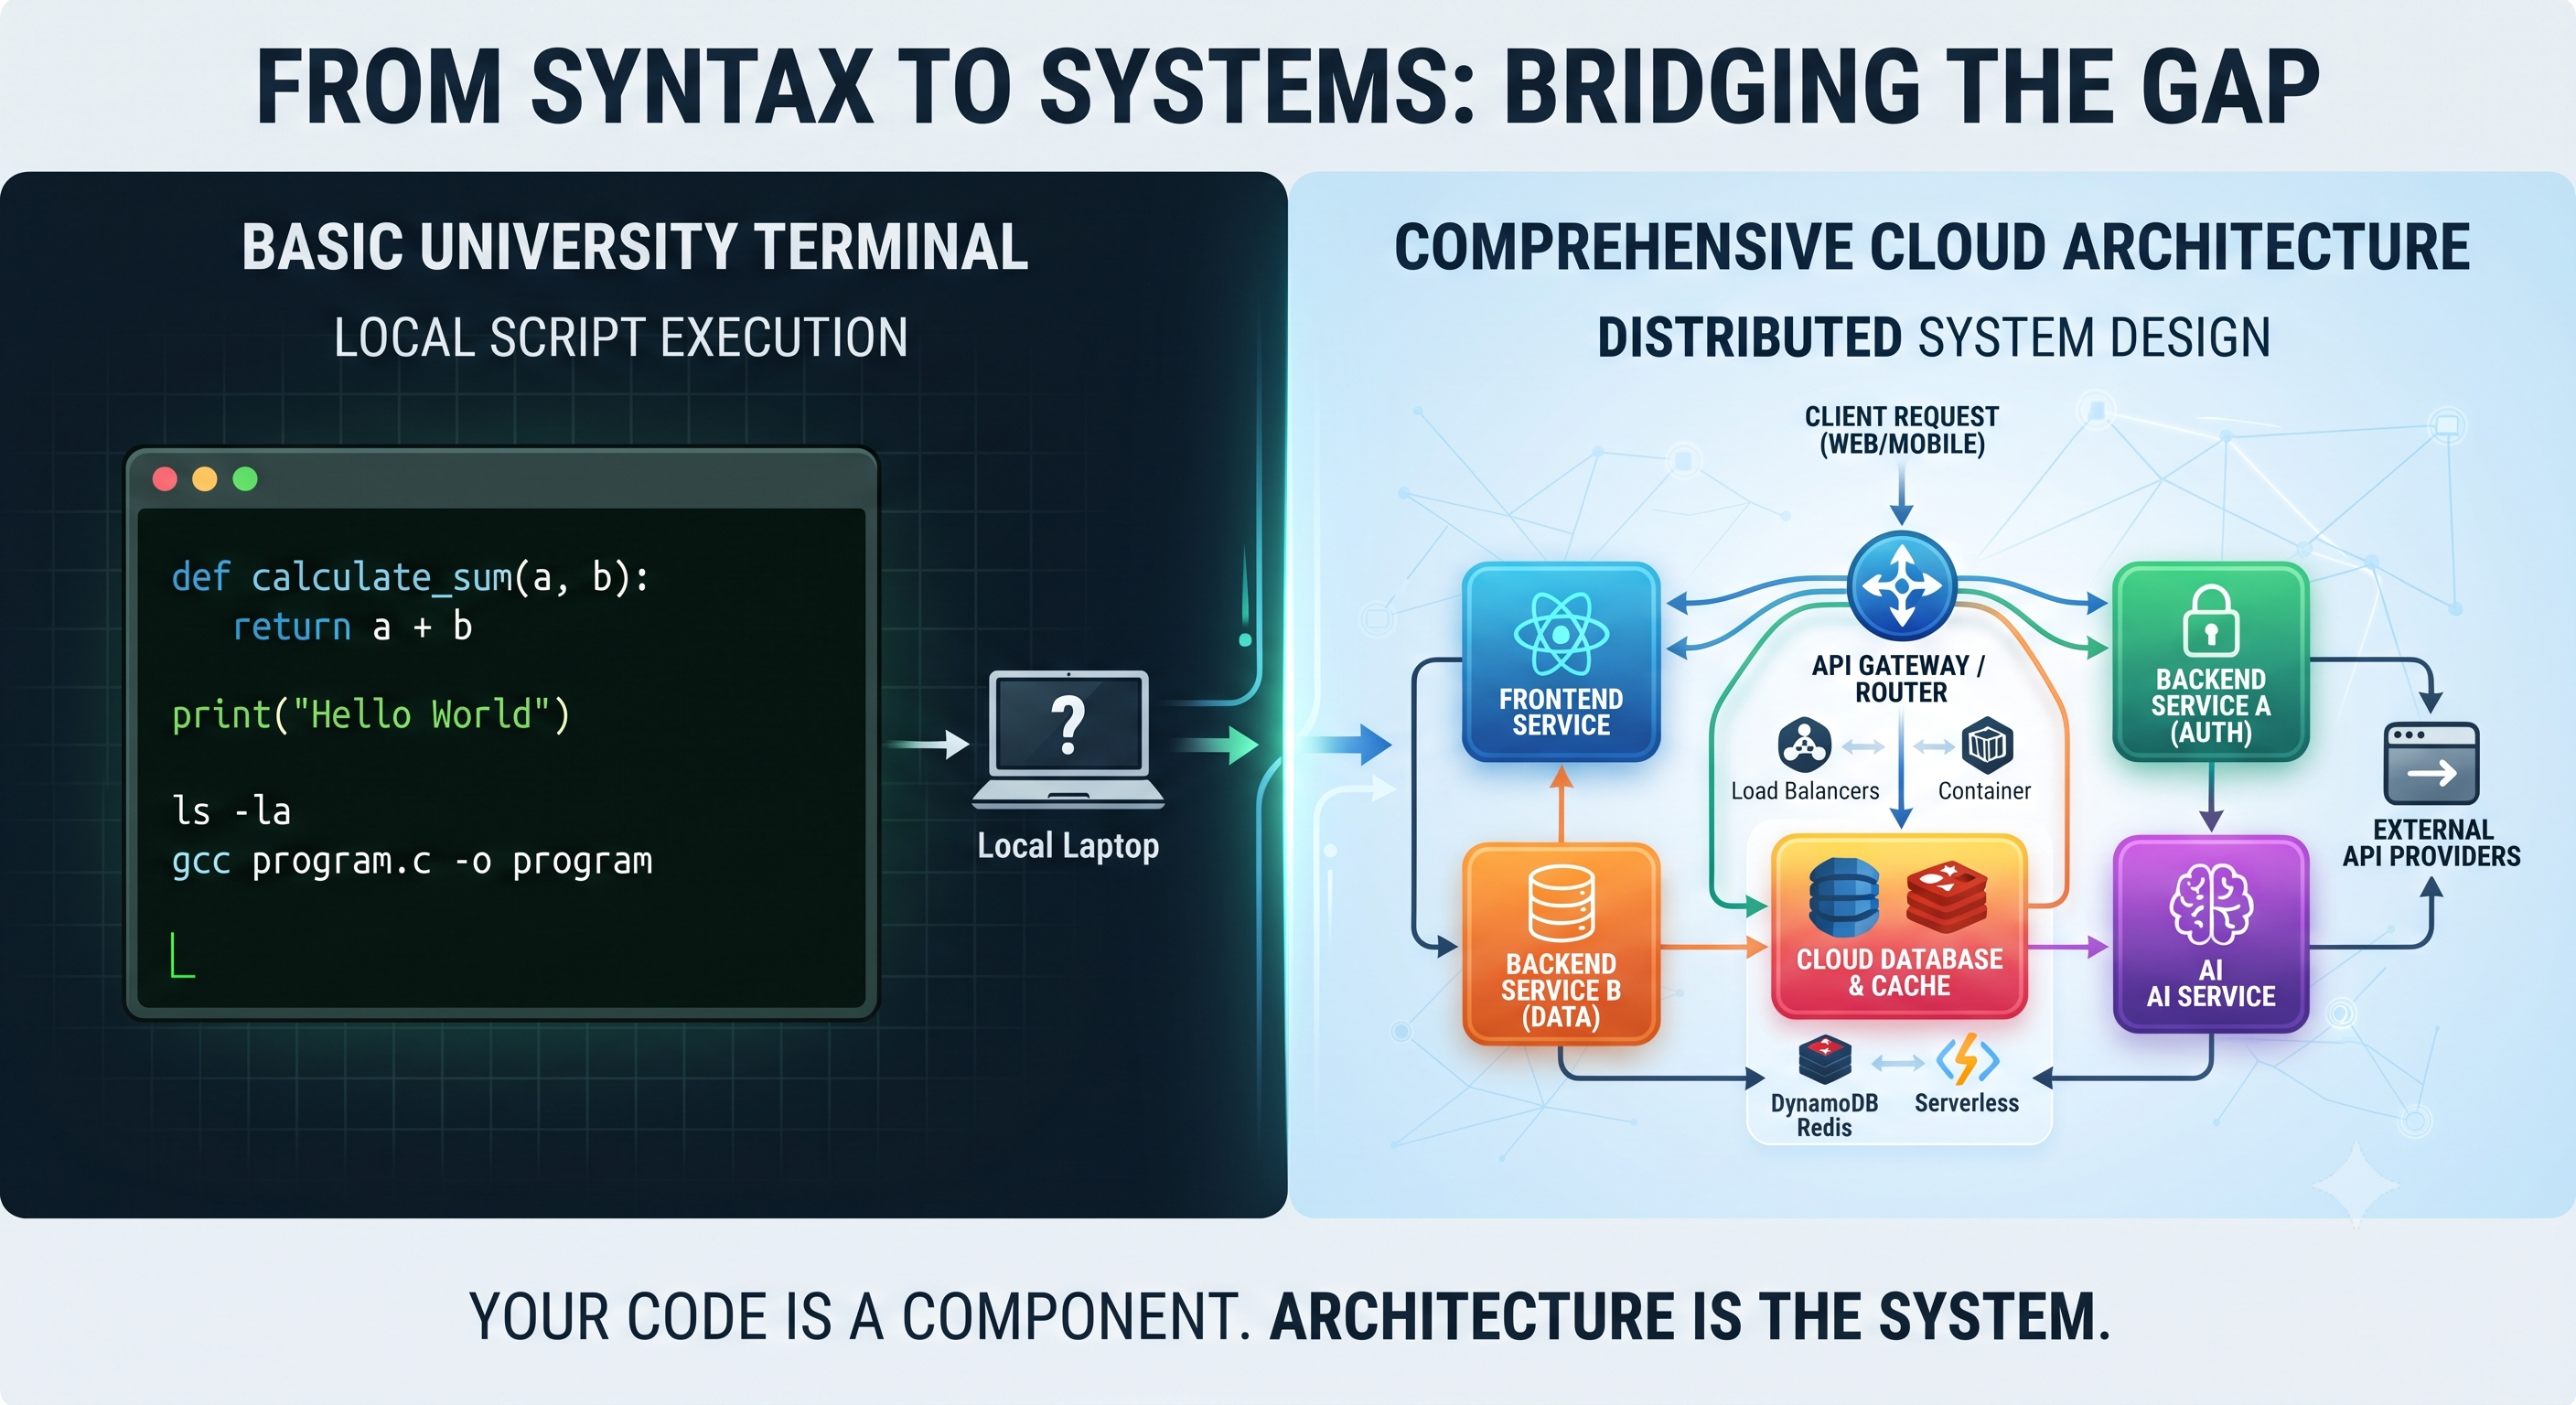
  • Beyond Syntax: Why Your Computer Science Curriculum is Missing the System Architecture Gap


    As a student stepping into the tech landscape, it is easy to fall into the trap of treating code syntax as the ultimate destination. But with AI coding assistants and automation handling routine boilerplate instantly, the real competitive edge for early-career developers is systems thinking.


    Writing a working algorithm in isolation is completely different from designing an application that handles provider gateways, concurrent user loads, state management, and error resilience.


    Why it matters:
    Hiring managers aren't looking for human syntax compilers; they want problem solvers who understand how components interact across a distributed stack. If you don't know how data flows from a client application through a gateway proxy, or how to decouple business logic from third-party APIs, your portfolio projects will look identical to thousands of other tutorial apps.


    How to bridge the gap (The Student Blueprint):


    Build Beyond the Terminal: Stop building scripts that only run locally in your console. Deploy full-stack apps that include environment configuration, database management, and error fallbacks.


    Master the API Gateway Concept: Learn how modern applications route traffic, handle rate limits, and abstract external dependencies instead of hardcoding API keys directly into your source files.


    Document Your Architecture: Practice drawing system architecture diagrams for your student projects. Being able to explain why you chose a specific data flow or storage layer matters much more than memorizing syntax.


    Discussion Question: How are you supplementing your university coursework or self-study with system design and architecture practices? What is the hardest part about moving from writing small scripts to building complete systems?


    CTA (Join Students in Tech): Ready to accelerate your learning and build real-world engineering skills? Join the Students in Tech community to collaborate with peers, share project blueprints, and prepare for the future of software development.
    Beyond Syntax: Why Your Computer Science Curriculum is Missing the System Architecture Gap As a student stepping into the tech landscape, it is easy to fall into the trap of treating code syntax as the ultimate destination. But with AI coding assistants and automation handling routine boilerplate instantly, the real competitive edge for early-career developers is systems thinking. Writing a working algorithm in isolation is completely different from designing an application that handles provider gateways, concurrent user loads, state management, and error resilience. Why it matters: Hiring managers aren't looking for human syntax compilers; they want problem solvers who understand how components interact across a distributed stack. If you don't know how data flows from a client application through a gateway proxy, or how to decouple business logic from third-party APIs, your portfolio projects will look identical to thousands of other tutorial apps. How to bridge the gap (The Student Blueprint): Build Beyond the Terminal: Stop building scripts that only run locally in your console. Deploy full-stack apps that include environment configuration, database management, and error fallbacks. Master the API Gateway Concept: Learn how modern applications route traffic, handle rate limits, and abstract external dependencies instead of hardcoding API keys directly into your source files. Document Your Architecture: Practice drawing system architecture diagrams for your student projects. Being able to explain why you chose a specific data flow or storage layer matters much more than memorizing syntax. Discussion Question: How are you supplementing your university coursework or self-study with system design and architecture practices? What is the hardest part about moving from writing small scripts to building complete systems? CTA (Join Students in Tech): Ready to accelerate your learning and build real-world engineering skills? Join the Students in Tech community to collaborate with peers, share project blueprints, and prepare for the future of software development.
    0 Comentários 0 Compartilhamentos 18 Visualizações 0 Anterior
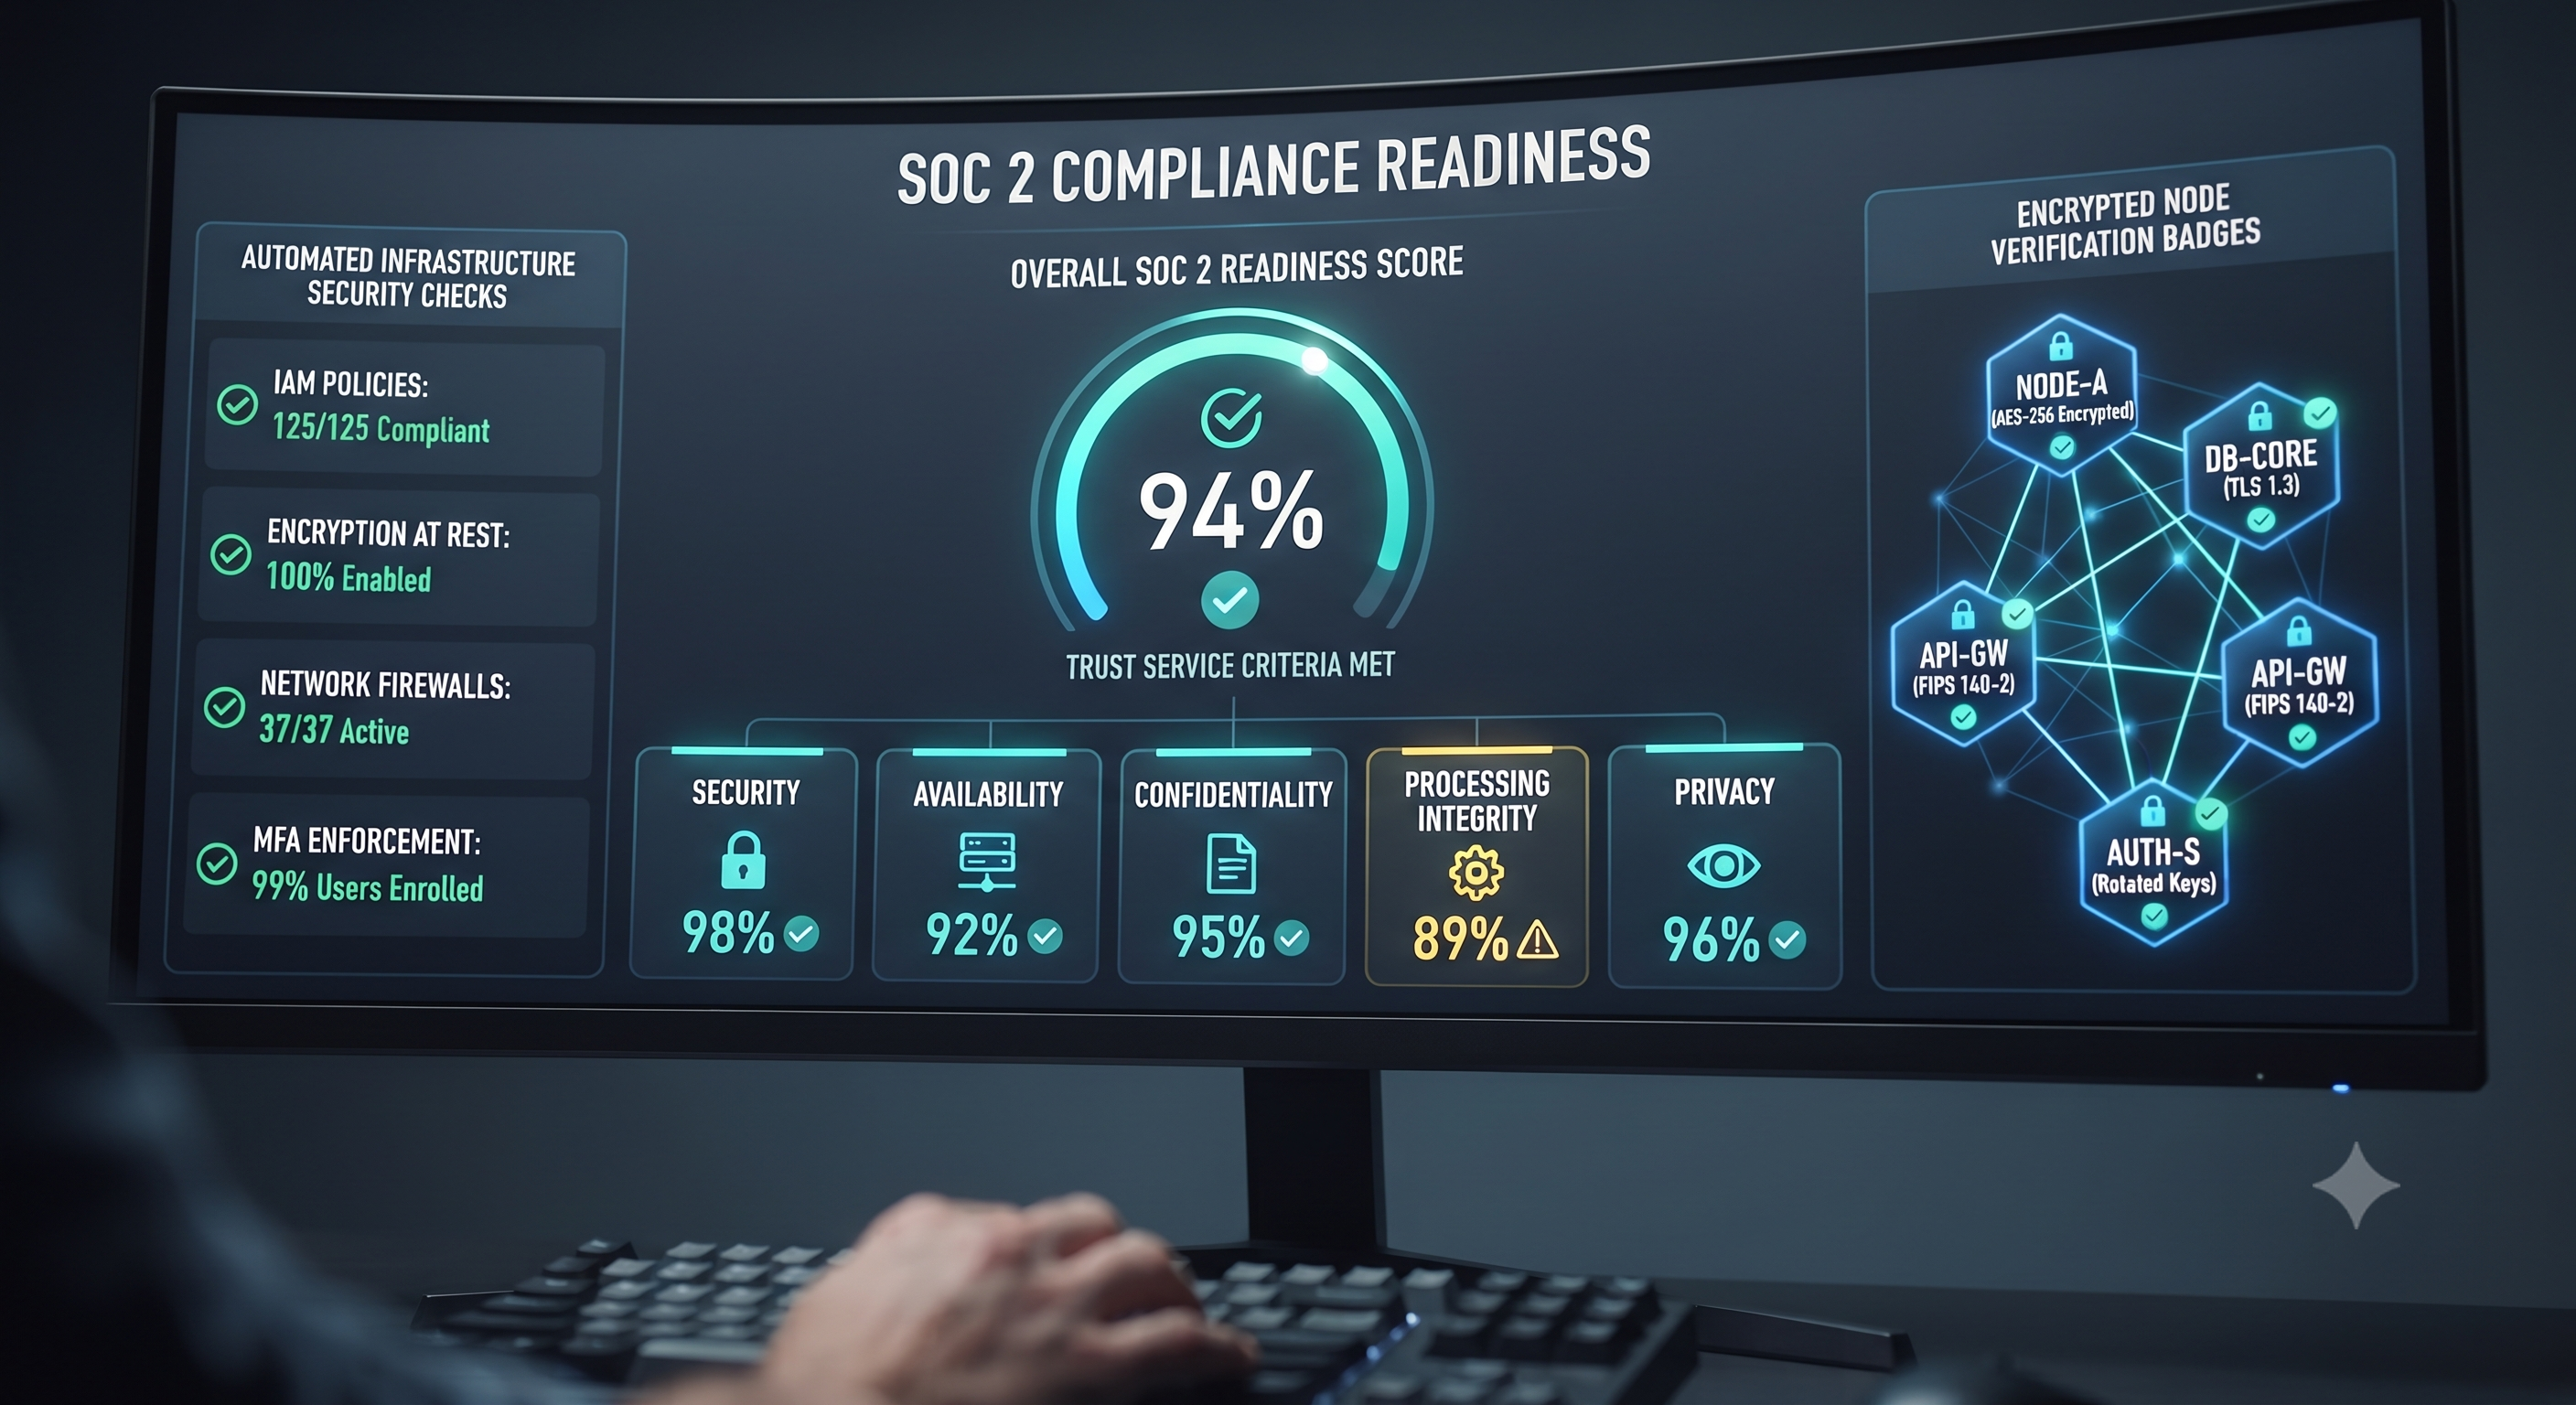
  • The US Tech Compliance & SOC 2 Readiness Checklist: 5 Core Trust Pillars for Scaling SaaS Startups


    As US technology startups scale from early seed traction to enterprise-ready growth, establishing automated compliance and rigorous data governance is non-negotiable. Passing an audit isn't just about checking legal boxes; it’s about proving to customers that their data is protected by enterprise-grade guardrails from day one.


    Audit and fortify your infrastructure for enterprise procurement with this SOC 2 readiness checklist:


    [ ] Automated Identity & Access Management (IAM): Enforce strict multi-factor authentication (MFA), role-based access control (RBAC), and automated offboarding across all internal developer tools and cloud consoles.


    [ ] Continuous Infrastructure Monitoring: Implement automated compliance scanners and log centralization tools to detect unauthorized configuration changes or security drift in real time.


    [ ] Version-Controlled Access & Change Management: Ensure every production code deployment, database migration, and infrastructure update goes through mandatory pull request reviews and CI/CD audit trails.


    [ ] Encrypted Data at Rest & in Transit: Mandate robust encryption standards (AES-256 for storage, TLS 1.3 for transit) backed by automated key rotation via AWS KMS or HashiCorp Vault.


    [ ] Formalized Incident Response Playbook: Document, test, and automate your incident detection, escalation, and post-mortem workflows so you can respond transparently to enterprise security questionnaires.


    Why It Matters
    Enterprise buyers don't just buy software—they buy risk reduction. Building compliance into your engineering workflow early accelerates your sales cycle, builds instant market trust, and sets your startup apart in a crowded ecosystem.


    Discussion Question
    What has been your startup's biggest bottleneck when transitioning from an ad-hoc security setup to formal SOC 2 compliance for enterprise sales? Let’s share notes below! 👇


    CTA (Join Techawks USA)
    Ready to build, scale, and sell to US enterprises? Join the Techawks USA community to connect with local founders, share compliance strategies, and accelerate your growth.
    The US Tech Compliance & SOC 2 Readiness Checklist: 5 Core Trust Pillars for Scaling SaaS Startups As US technology startups scale from early seed traction to enterprise-ready growth, establishing automated compliance and rigorous data governance is non-negotiable. Passing an audit isn't just about checking legal boxes; it’s about proving to customers that their data is protected by enterprise-grade guardrails from day one. Audit and fortify your infrastructure for enterprise procurement with this SOC 2 readiness checklist: [ ] Automated Identity & Access Management (IAM): Enforce strict multi-factor authentication (MFA), role-based access control (RBAC), and automated offboarding across all internal developer tools and cloud consoles. [ ] Continuous Infrastructure Monitoring: Implement automated compliance scanners and log centralization tools to detect unauthorized configuration changes or security drift in real time. [ ] Version-Controlled Access & Change Management: Ensure every production code deployment, database migration, and infrastructure update goes through mandatory pull request reviews and CI/CD audit trails. [ ] Encrypted Data at Rest & in Transit: Mandate robust encryption standards (AES-256 for storage, TLS 1.3 for transit) backed by automated key rotation via AWS KMS or HashiCorp Vault. [ ] Formalized Incident Response Playbook: Document, test, and automate your incident detection, escalation, and post-mortem workflows so you can respond transparently to enterprise security questionnaires. Why It Matters Enterprise buyers don't just buy software—they buy risk reduction. Building compliance into your engineering workflow early accelerates your sales cycle, builds instant market trust, and sets your startup apart in a crowded ecosystem. Discussion Question What has been your startup's biggest bottleneck when transitioning from an ad-hoc security setup to formal SOC 2 compliance for enterprise sales? Let’s share notes below! 👇 CTA (Join Techawks USA) Ready to build, scale, and sell to US enterprises? Join the Techawks USA community to connect with local founders, share compliance strategies, and accelerate your growth.
    0 Comentários 0 Compartilhamentos 735 Visualizações 0 Anterior
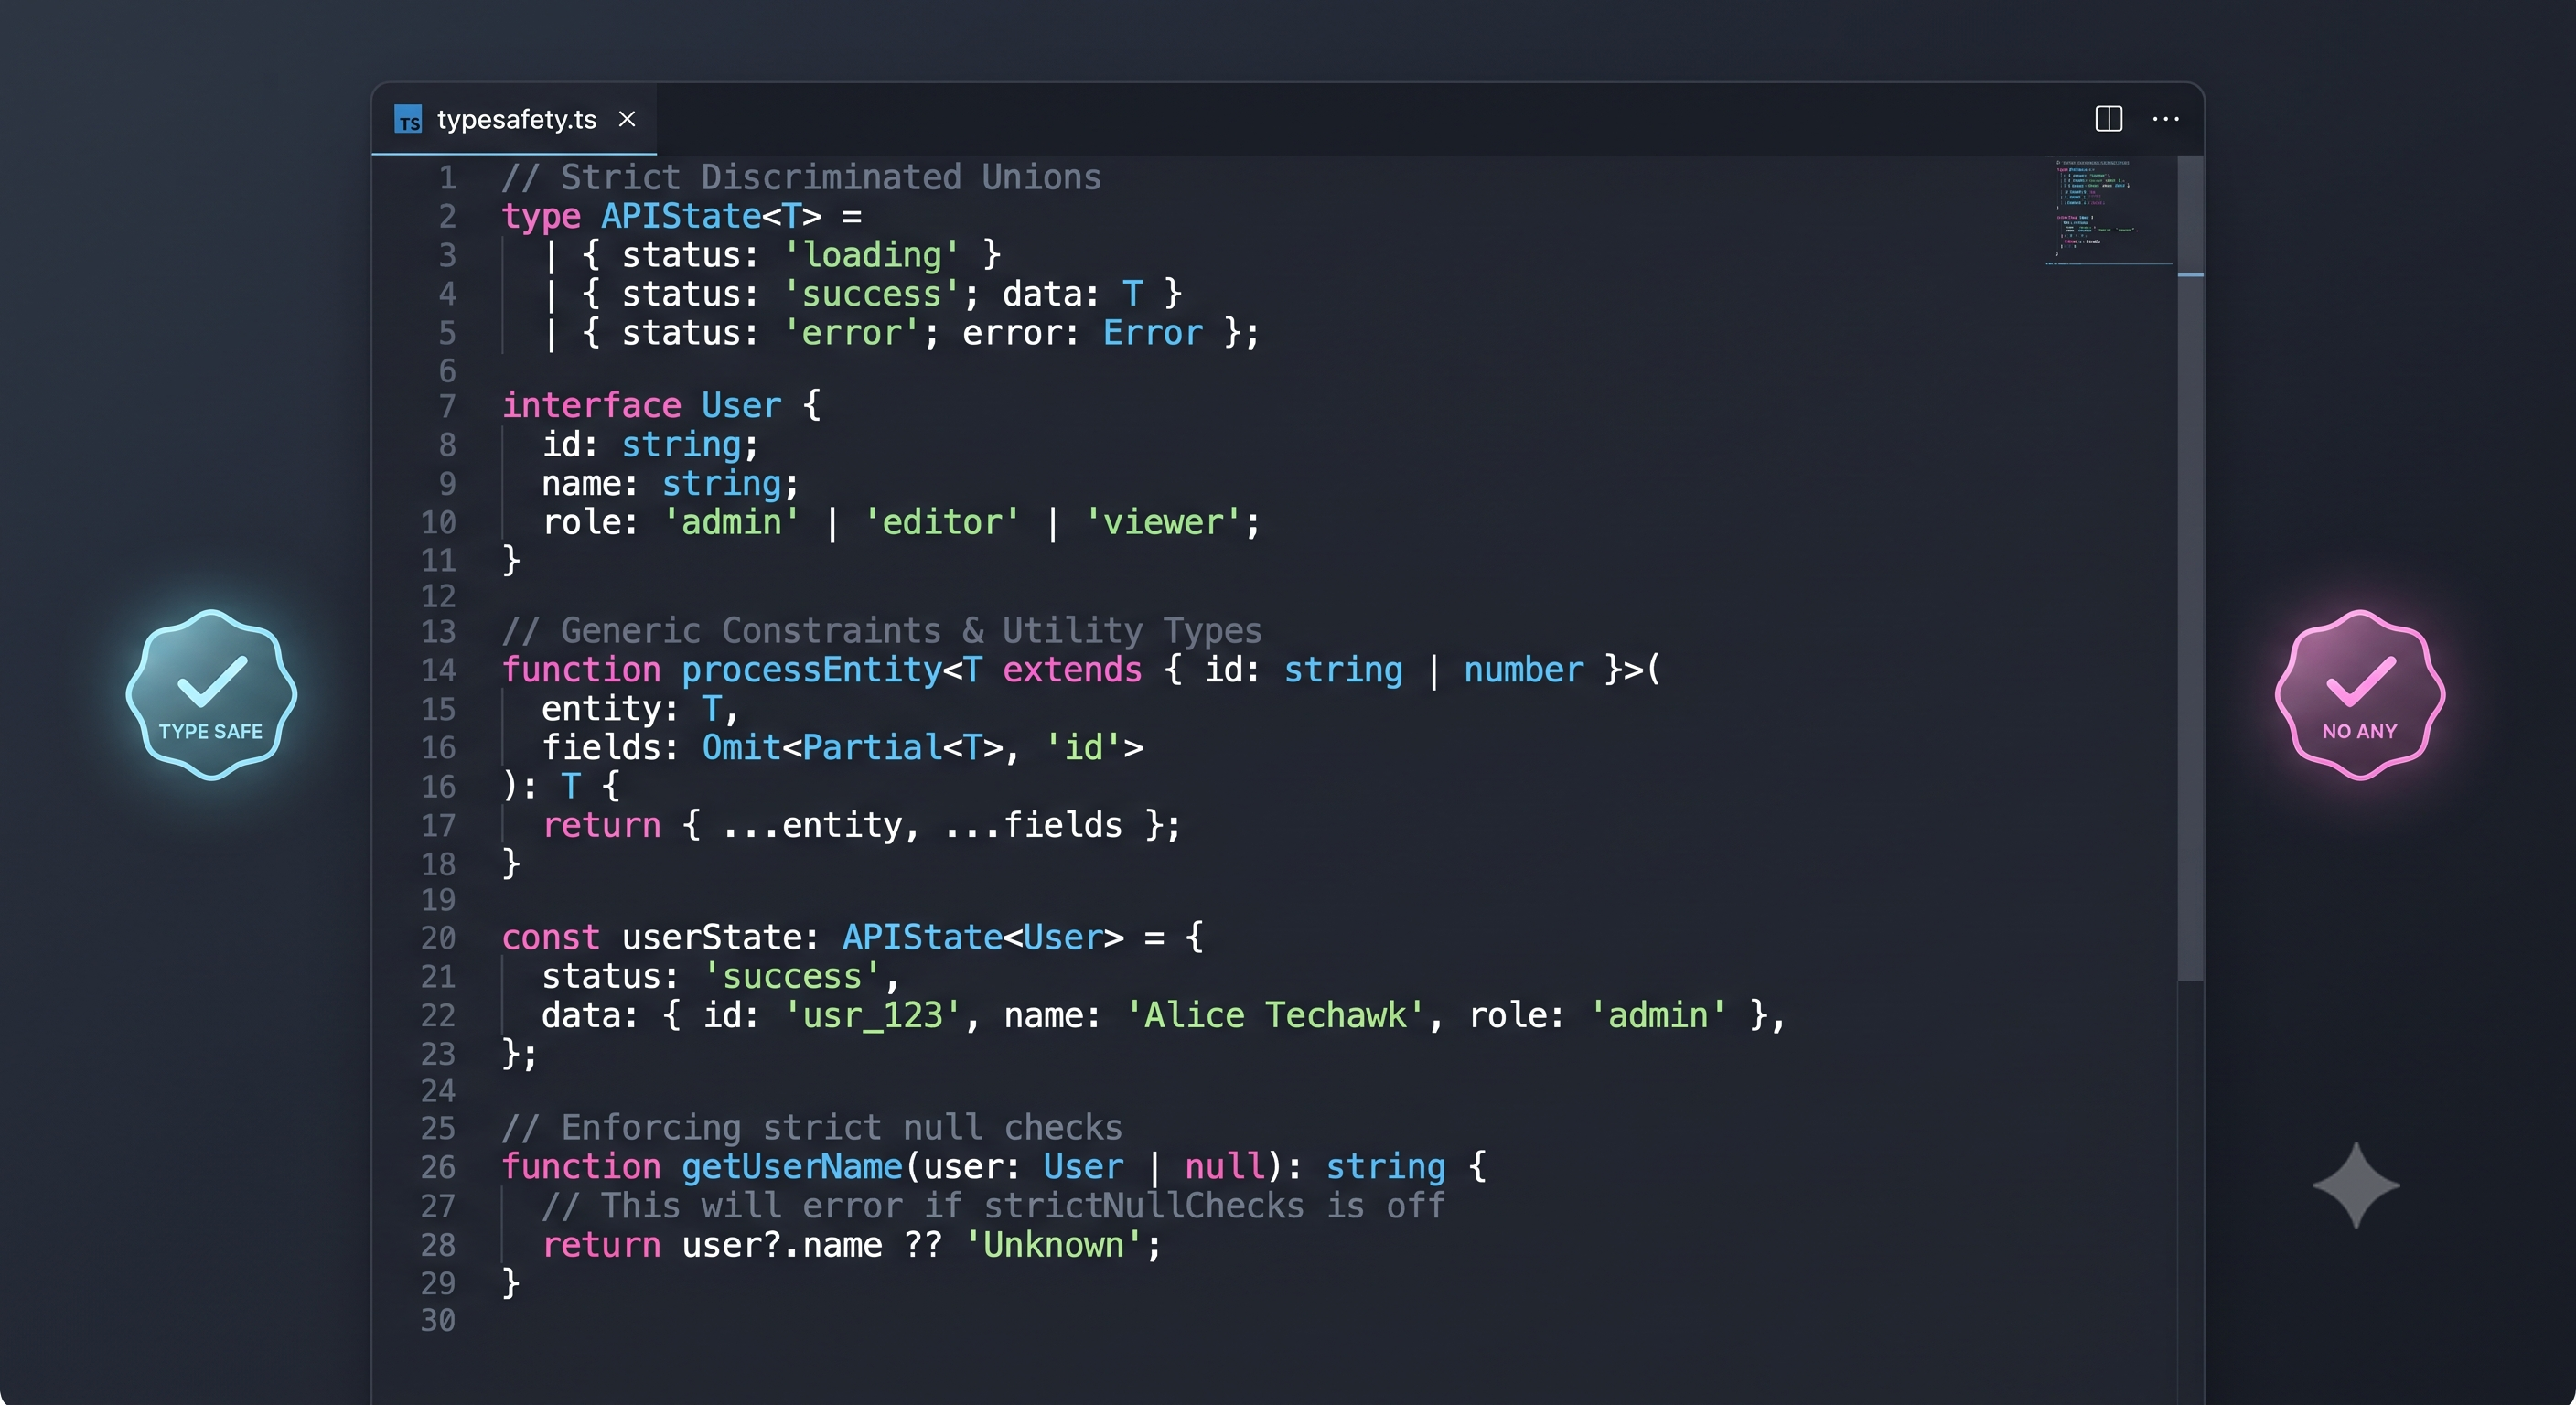
  • The TypeScript Type-Safety Checklist: 5 Patterns to Eliminate any and Bulletproof Your Codebase


    As professional developer surveys highlight, strict typing is foundational for maintaining massive, fast-evolving codebases. But leveraging TypeScript effectively means moving beyond basic interfaces and embracing advanced type-level programming.


    Audit and elevate your code quality with this developer checklist:


    [ ] Ban Implicit & Explicit any: Enforce strict rules in your tsconfig.json (noImplicitAny: true) and replace lazy any types with unknown combined with type guards.


    [ ] Leverage Discriminated Unions: Model complex state (like async loading, success, and error states) using tagged union types instead of optional properties that allow illegal states.


    [ ] Utilize Utility Types Effectively: Master built-in utilities like Omit, Pick, Record, and ReturnType to derive types dynamically rather than duplicating manual definitions.


    [ ] Constrain Generics Properly: Use the extends keyword on generic type parameters to restrict inputs and maintain predictable inference boundaries.


    [ ] Enable Strict Null Checks: Turn on strictNullChecks to force explicit handling of null and undefined, wiping out entire classes of production TypeError bugs.


    Why It Matters
    TypeScript isn't just about catching typos before compile time—it's about creating living documentation and self-documenting code contracts. Strong typing empowers your team to refactor fearlessly and scale applications without second-guessing system behavior.


    Discussion Question
    What is your preferred strategy for managing deeply nested API response types without turning your code into an unreadable maintenance nightmare? Let’s talk code below! 👇


    CTA (Join Developers & Coding)
    Ready to sharpen your engineering skills and write cleaner code? Join the Developers & Coding community to collaborate with fellow developers, share architectural patterns, and level up your stack.
    The TypeScript Type-Safety Checklist: 5 Patterns to Eliminate any and Bulletproof Your Codebase As professional developer surveys highlight, strict typing is foundational for maintaining massive, fast-evolving codebases. But leveraging TypeScript effectively means moving beyond basic interfaces and embracing advanced type-level programming. Audit and elevate your code quality with this developer checklist: [ ] Ban Implicit & Explicit any: Enforce strict rules in your tsconfig.json (noImplicitAny: true) and replace lazy any types with unknown combined with type guards. [ ] Leverage Discriminated Unions: Model complex state (like async loading, success, and error states) using tagged union types instead of optional properties that allow illegal states. [ ] Utilize Utility Types Effectively: Master built-in utilities like Omit, Pick, Record, and ReturnType to derive types dynamically rather than duplicating manual definitions. [ ] Constrain Generics Properly: Use the extends keyword on generic type parameters to restrict inputs and maintain predictable inference boundaries. [ ] Enable Strict Null Checks: Turn on strictNullChecks to force explicit handling of null and undefined, wiping out entire classes of production TypeError bugs. Why It Matters TypeScript isn't just about catching typos before compile time—it's about creating living documentation and self-documenting code contracts. Strong typing empowers your team to refactor fearlessly and scale applications without second-guessing system behavior. Discussion Question What is your preferred strategy for managing deeply nested API response types without turning your code into an unreadable maintenance nightmare? Let’s talk code below! 👇 CTA (Join Developers & Coding) Ready to sharpen your engineering skills and write cleaner code? Join the Developers & Coding community to collaborate with fellow developers, share architectural patterns, and level up your stack.
    0 Comentários 0 Compartilhamentos 75 Visualizações 0 Anterior
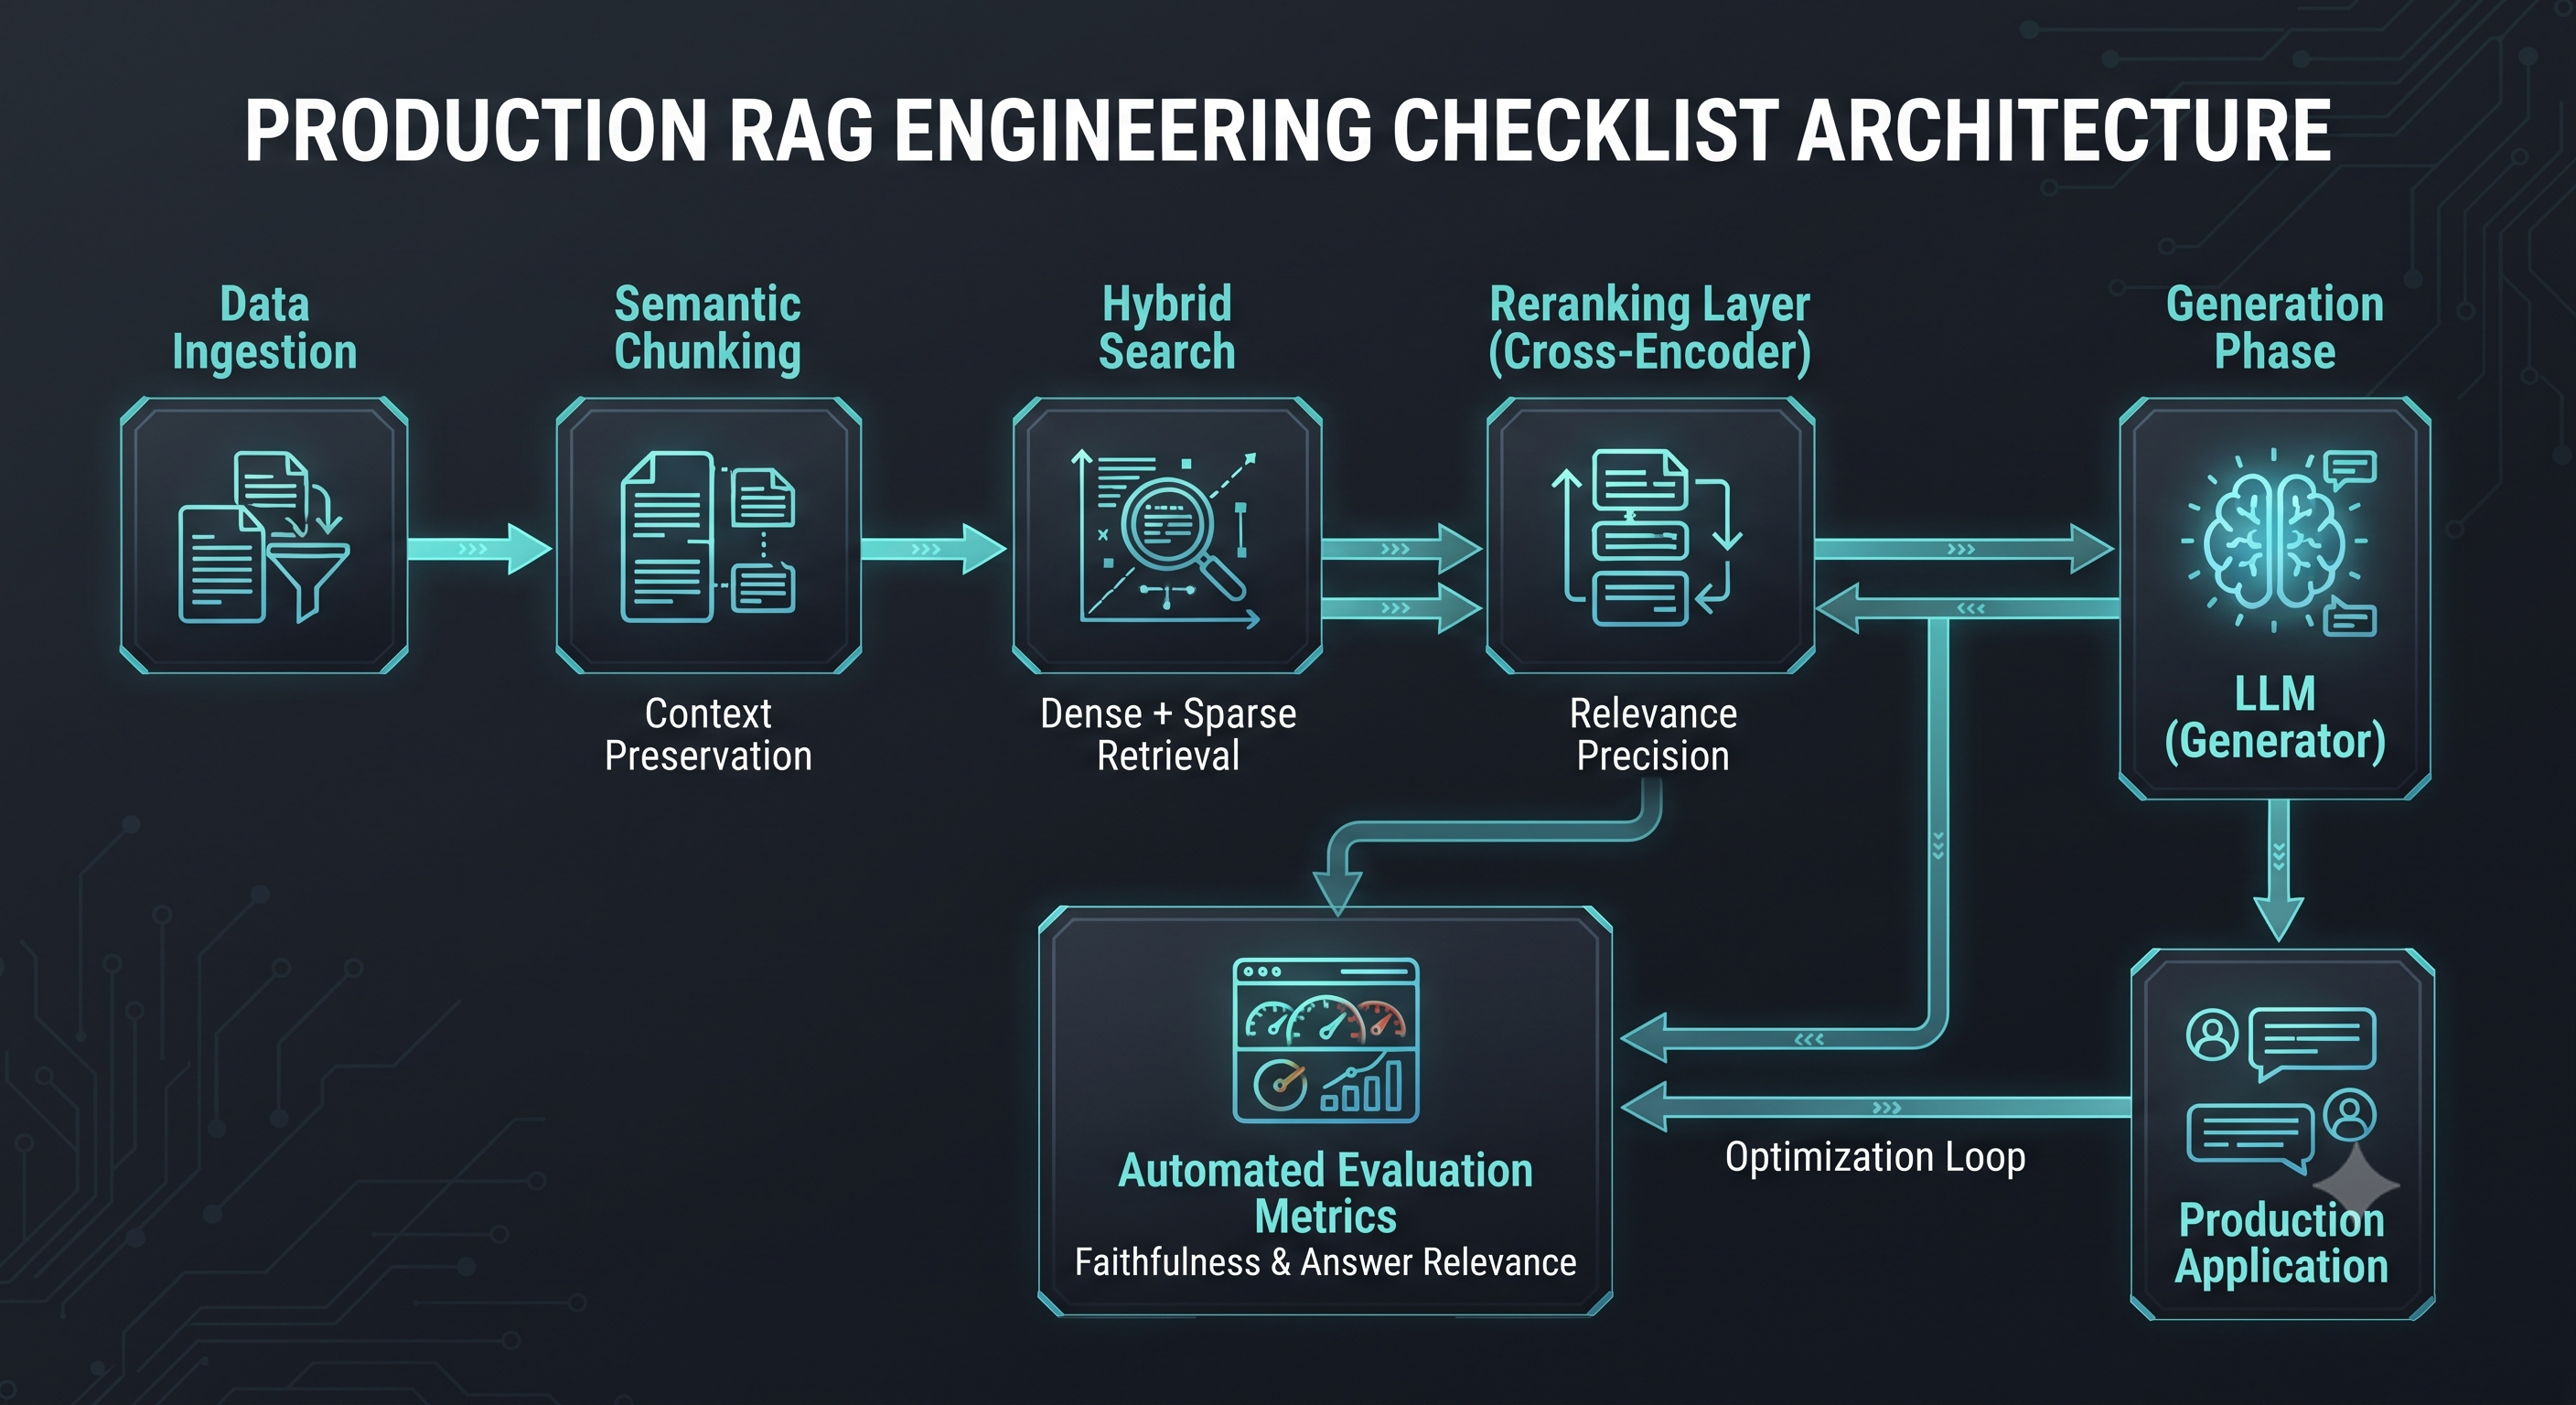
  • The Production RAG Engineering Checklist: 5 Crucial Guardrails for Context Retrieval and Accuracy


    As AI builders scaling production systems quickly discover, naive vector search isn't enough to guarantee deterministic, enterprise-grade accuracy. If your RAG pipeline is spitting out irrelevant answers or missing nuanced user intent, it's time to audit your workflow.


    Optimize and bulletproof your retrieval pipeline with this production engineering checklist:


    [ ] Hybrid Search Integration: Combine dense vector embeddings with sparse keyword search (BM25) to ensure semantic depth doesn't compromise exact keyword and ID matching.


    [ ] Reranking Layers (Cross-Encoders): Implement a reranker (like Cohere Rerank or BGE-Reranker) to evaluate top-k initial retrieval results and pass only the highest-precision chunks to the generator.


    [ ] Semantic Chunking Strategies: Move away from fixed-token splitting; use semantic chunking to keep logical paragraphs, code blocks, and markdown headers intact.


    [ ] Dynamic Context Window Management: Set strict token budget caps and token pruning logic to prevent prompt dilution and control API inference costs.


    [ ] Automated Hallucination Evaluation: Integrate automated evaluation frameworks (like RAGAS or TruLens) into your CI/CD pipeline to continuously measure faithfulness, answer relevance, and context precision.


    Why It Matters
    Users don't care how sleek your vector database is; they care if the AI gives the correct, verifiable answer. Implementing these architectural layers transforms a brittle prototype into a robust production system that scales reliably under heavy real-world traffic.


    Discussion Question
    What is your go-to strategy for tackling latency bottlenecks when adding a cross-encoder reranking step to a high-throughput RAG pipeline? Let’s share notes below! 👇


    CTA (Join AI Builders & Enthusiasts)
    Ready to build better AI systems? Join the AI Builders & Enthusiasts community to connect with fellow developers, share production patterns, and master modern AI engineering.
    The Production RAG Engineering Checklist: 5 Crucial Guardrails for Context Retrieval and Accuracy As AI builders scaling production systems quickly discover, naive vector search isn't enough to guarantee deterministic, enterprise-grade accuracy. If your RAG pipeline is spitting out irrelevant answers or missing nuanced user intent, it's time to audit your workflow. Optimize and bulletproof your retrieval pipeline with this production engineering checklist: [ ] Hybrid Search Integration: Combine dense vector embeddings with sparse keyword search (BM25) to ensure semantic depth doesn't compromise exact keyword and ID matching. [ ] Reranking Layers (Cross-Encoders): Implement a reranker (like Cohere Rerank or BGE-Reranker) to evaluate top-k initial retrieval results and pass only the highest-precision chunks to the generator. [ ] Semantic Chunking Strategies: Move away from fixed-token splitting; use semantic chunking to keep logical paragraphs, code blocks, and markdown headers intact. [ ] Dynamic Context Window Management: Set strict token budget caps and token pruning logic to prevent prompt dilution and control API inference costs. [ ] Automated Hallucination Evaluation: Integrate automated evaluation frameworks (like RAGAS or TruLens) into your CI/CD pipeline to continuously measure faithfulness, answer relevance, and context precision. Why It Matters Users don't care how sleek your vector database is; they care if the AI gives the correct, verifiable answer. Implementing these architectural layers transforms a brittle prototype into a robust production system that scales reliably under heavy real-world traffic. Discussion Question What is your go-to strategy for tackling latency bottlenecks when adding a cross-encoder reranking step to a high-throughput RAG pipeline? Let’s share notes below! 👇 CTA (Join AI Builders & Enthusiasts) Ready to build better AI systems? Join the AI Builders & Enthusiasts community to connect with fellow developers, share production patterns, and master modern AI engineering.
    0 Comentários 0 Compartilhamentos 83 Visualizações 0 Anterior
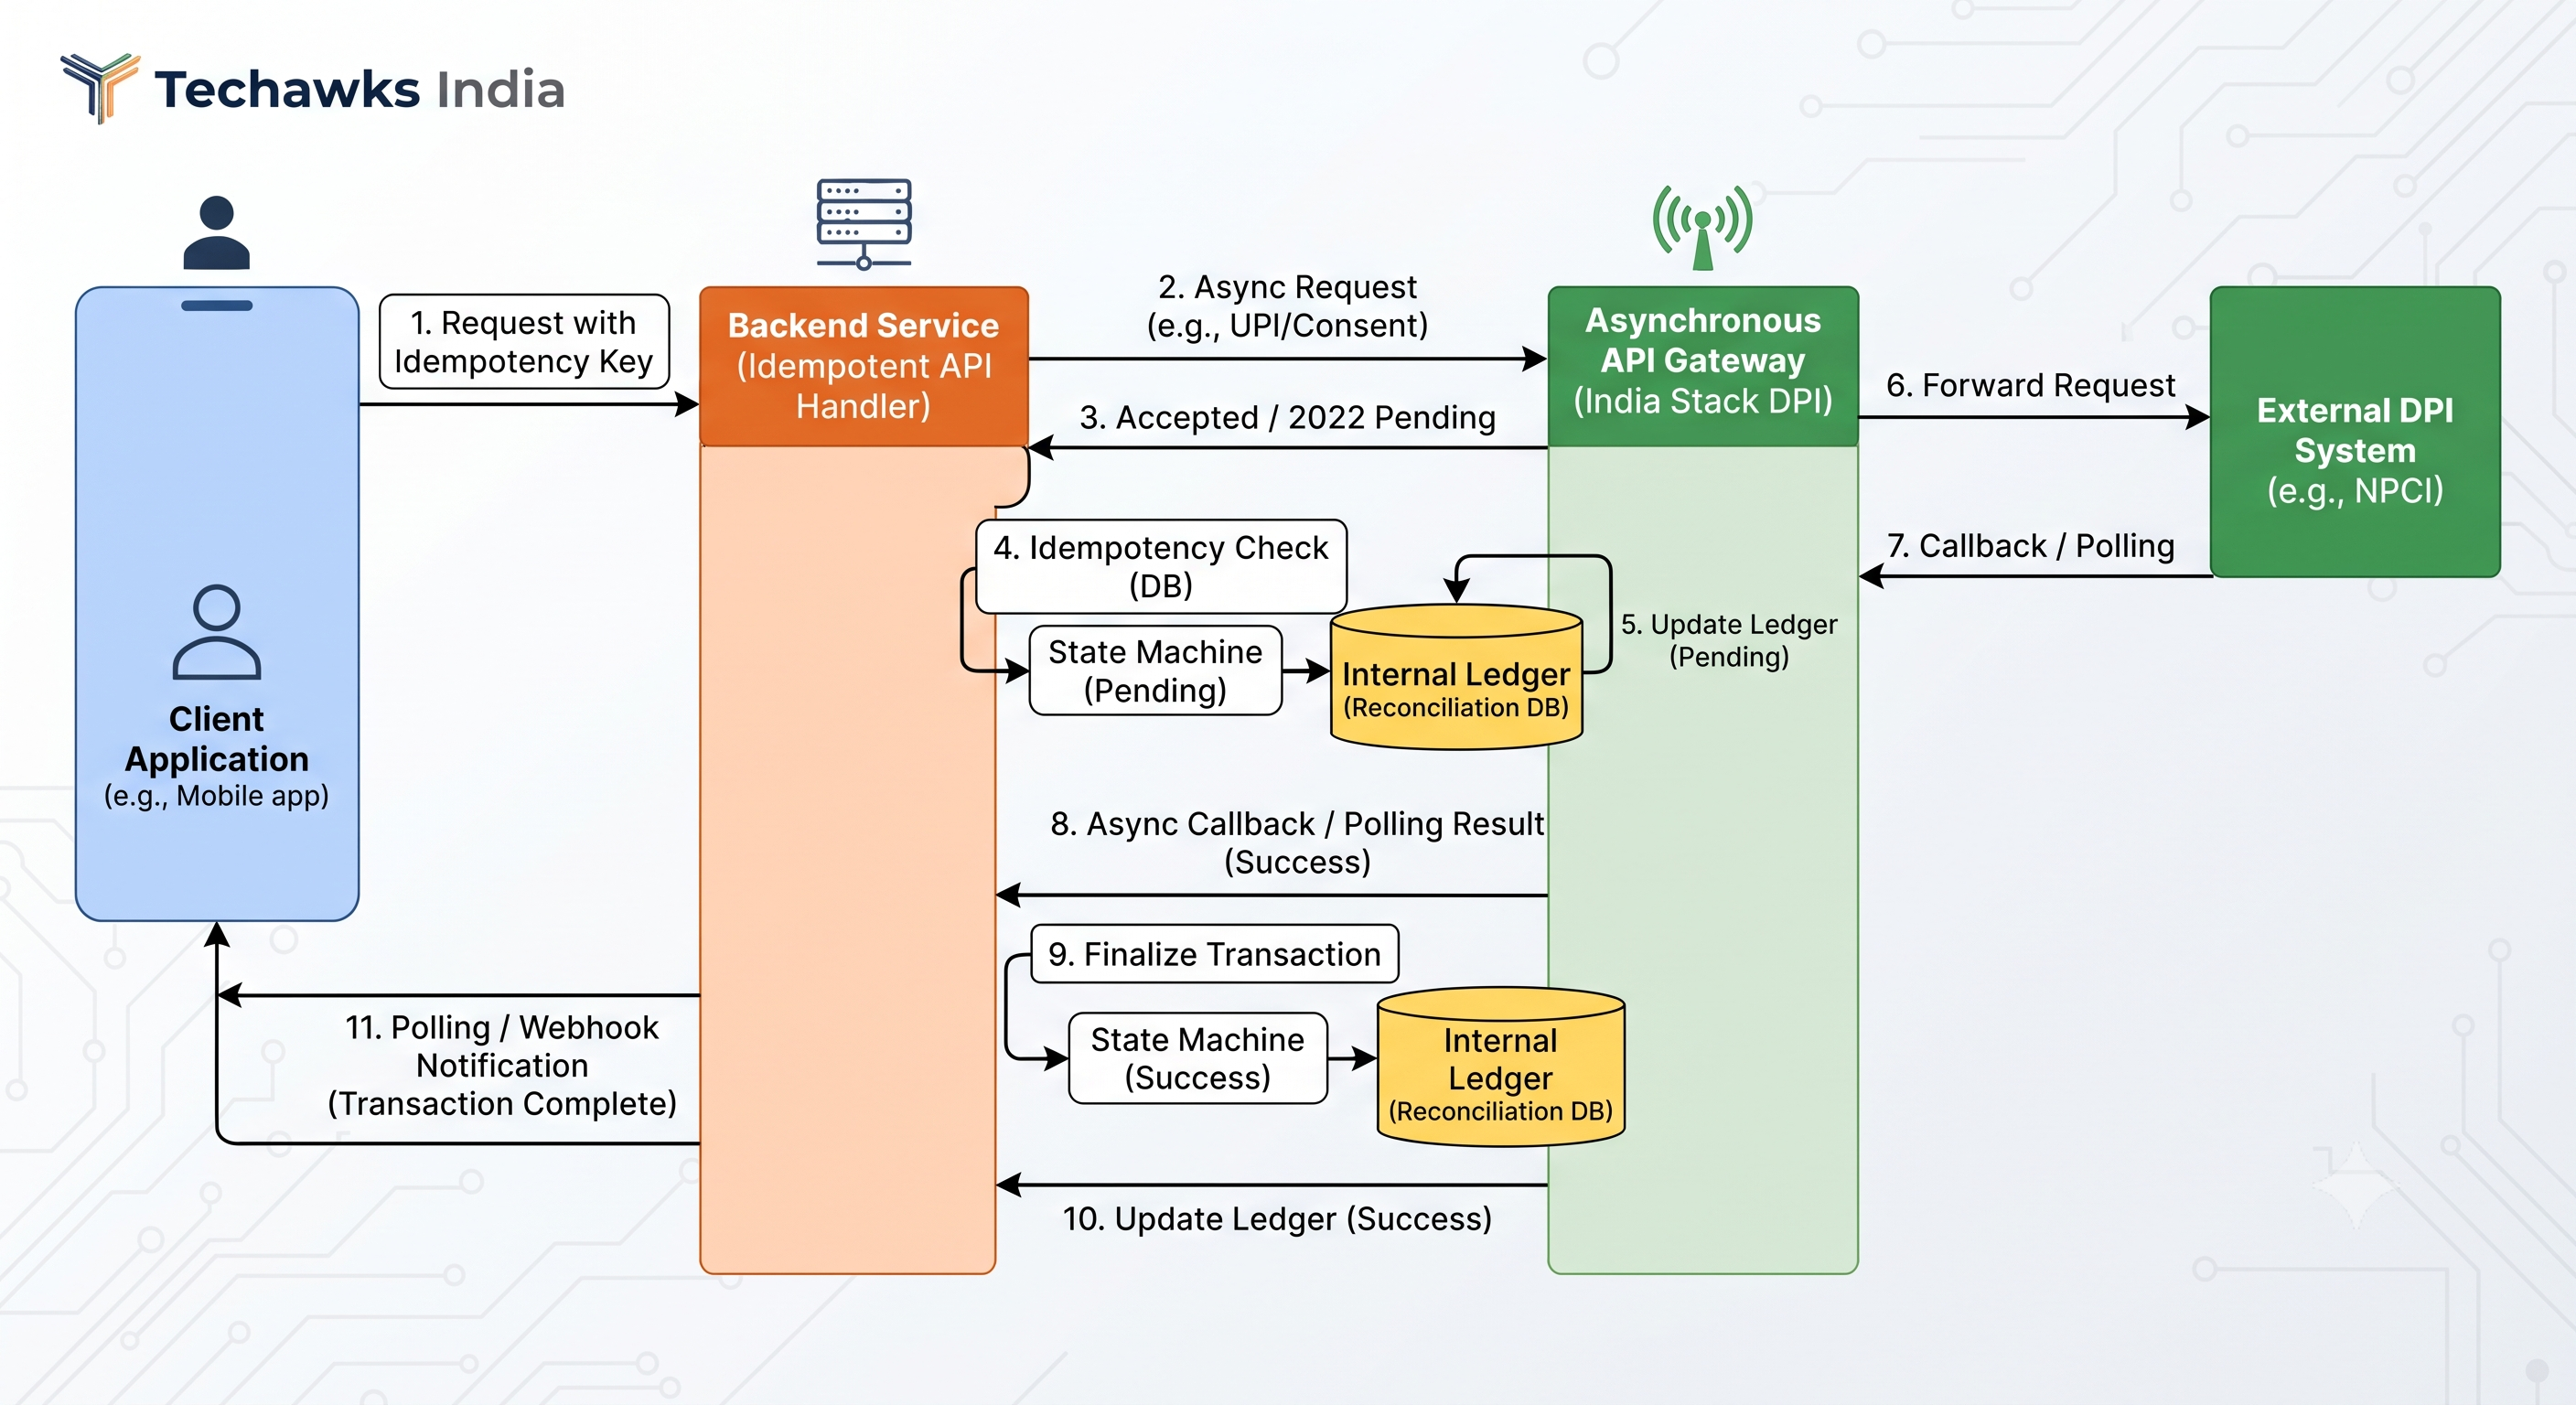
  • Scaling Beyond the Happy Path: Why Building on India Stack DPI Requires Resilient System Architecture


    As developers and architects in India’s fast-moving tech ecosystem, we have unprecedented access to population-scale public rails like Aadhaar verification, UPI payments, and open commerce protocols. But treating these public APIs like standard vendor endpoints is a recipe for production failure.


    Enter Resilient DPI Architecture (Handling Asynchronous Scale):
    When designing apps that plug into India Stack components, your engineering mindset must shift toward fault-tolerant distributed systems:


    Implement Strict Idempotency Keys: Network timeouts happen. Ensure your transaction or request handlers include unique idempotency keys to prevent duplicate debits or multi-submit glitches when retrying failed calls.


    Design for Asynchronous States: Never assume a transaction completes synchronously. Build robust state machines that gracefully handle intermediate limbo states (such as pending or timed-out responses) with clear polling or webhook fallback loops.


    Isolate Internal Ledgers from Rail Dashboards: Never rely on a third-party payment gateway or aggregator dashboard as your source of truth. Maintain your own double-entry internal ledger to reconcile rail events against local states reliably.


    By engineering resilience directly into your core backend logic, you turn public digital infrastructure into a powerful, reliable growth engine for your users.


    Discussion Question: What is the trickiest edge case you’ve encountered when handling timeout states or retries on high-volume UPI or API integrations? Let’s talk code below! 👇


    CTA (Join Techawks India): Ready to build world-class, population-scale systems for the Indian tech landscape? Join our community of developers and engineers at Techawks India to master the architectures that matter.
    Scaling Beyond the Happy Path: Why Building on India Stack DPI Requires Resilient System Architecture As developers and architects in India’s fast-moving tech ecosystem, we have unprecedented access to population-scale public rails like Aadhaar verification, UPI payments, and open commerce protocols. But treating these public APIs like standard vendor endpoints is a recipe for production failure. Enter Resilient DPI Architecture (Handling Asynchronous Scale): When designing apps that plug into India Stack components, your engineering mindset must shift toward fault-tolerant distributed systems: Implement Strict Idempotency Keys: Network timeouts happen. Ensure your transaction or request handlers include unique idempotency keys to prevent duplicate debits or multi-submit glitches when retrying failed calls. Design for Asynchronous States: Never assume a transaction completes synchronously. Build robust state machines that gracefully handle intermediate limbo states (such as pending or timed-out responses) with clear polling or webhook fallback loops. Isolate Internal Ledgers from Rail Dashboards: Never rely on a third-party payment gateway or aggregator dashboard as your source of truth. Maintain your own double-entry internal ledger to reconcile rail events against local states reliably. By engineering resilience directly into your core backend logic, you turn public digital infrastructure into a powerful, reliable growth engine for your users. Discussion Question: What is the trickiest edge case you’ve encountered when handling timeout states or retries on high-volume UPI or API integrations? Let’s talk code below! 👇 CTA (Join Techawks India): Ready to build world-class, population-scale systems for the Indian tech landscape? Join our community of developers and engineers at Techawks India to master the architectures that matter.
    0 Comentários 0 Compartilhamentos 184 Visualizações 0 Anterior
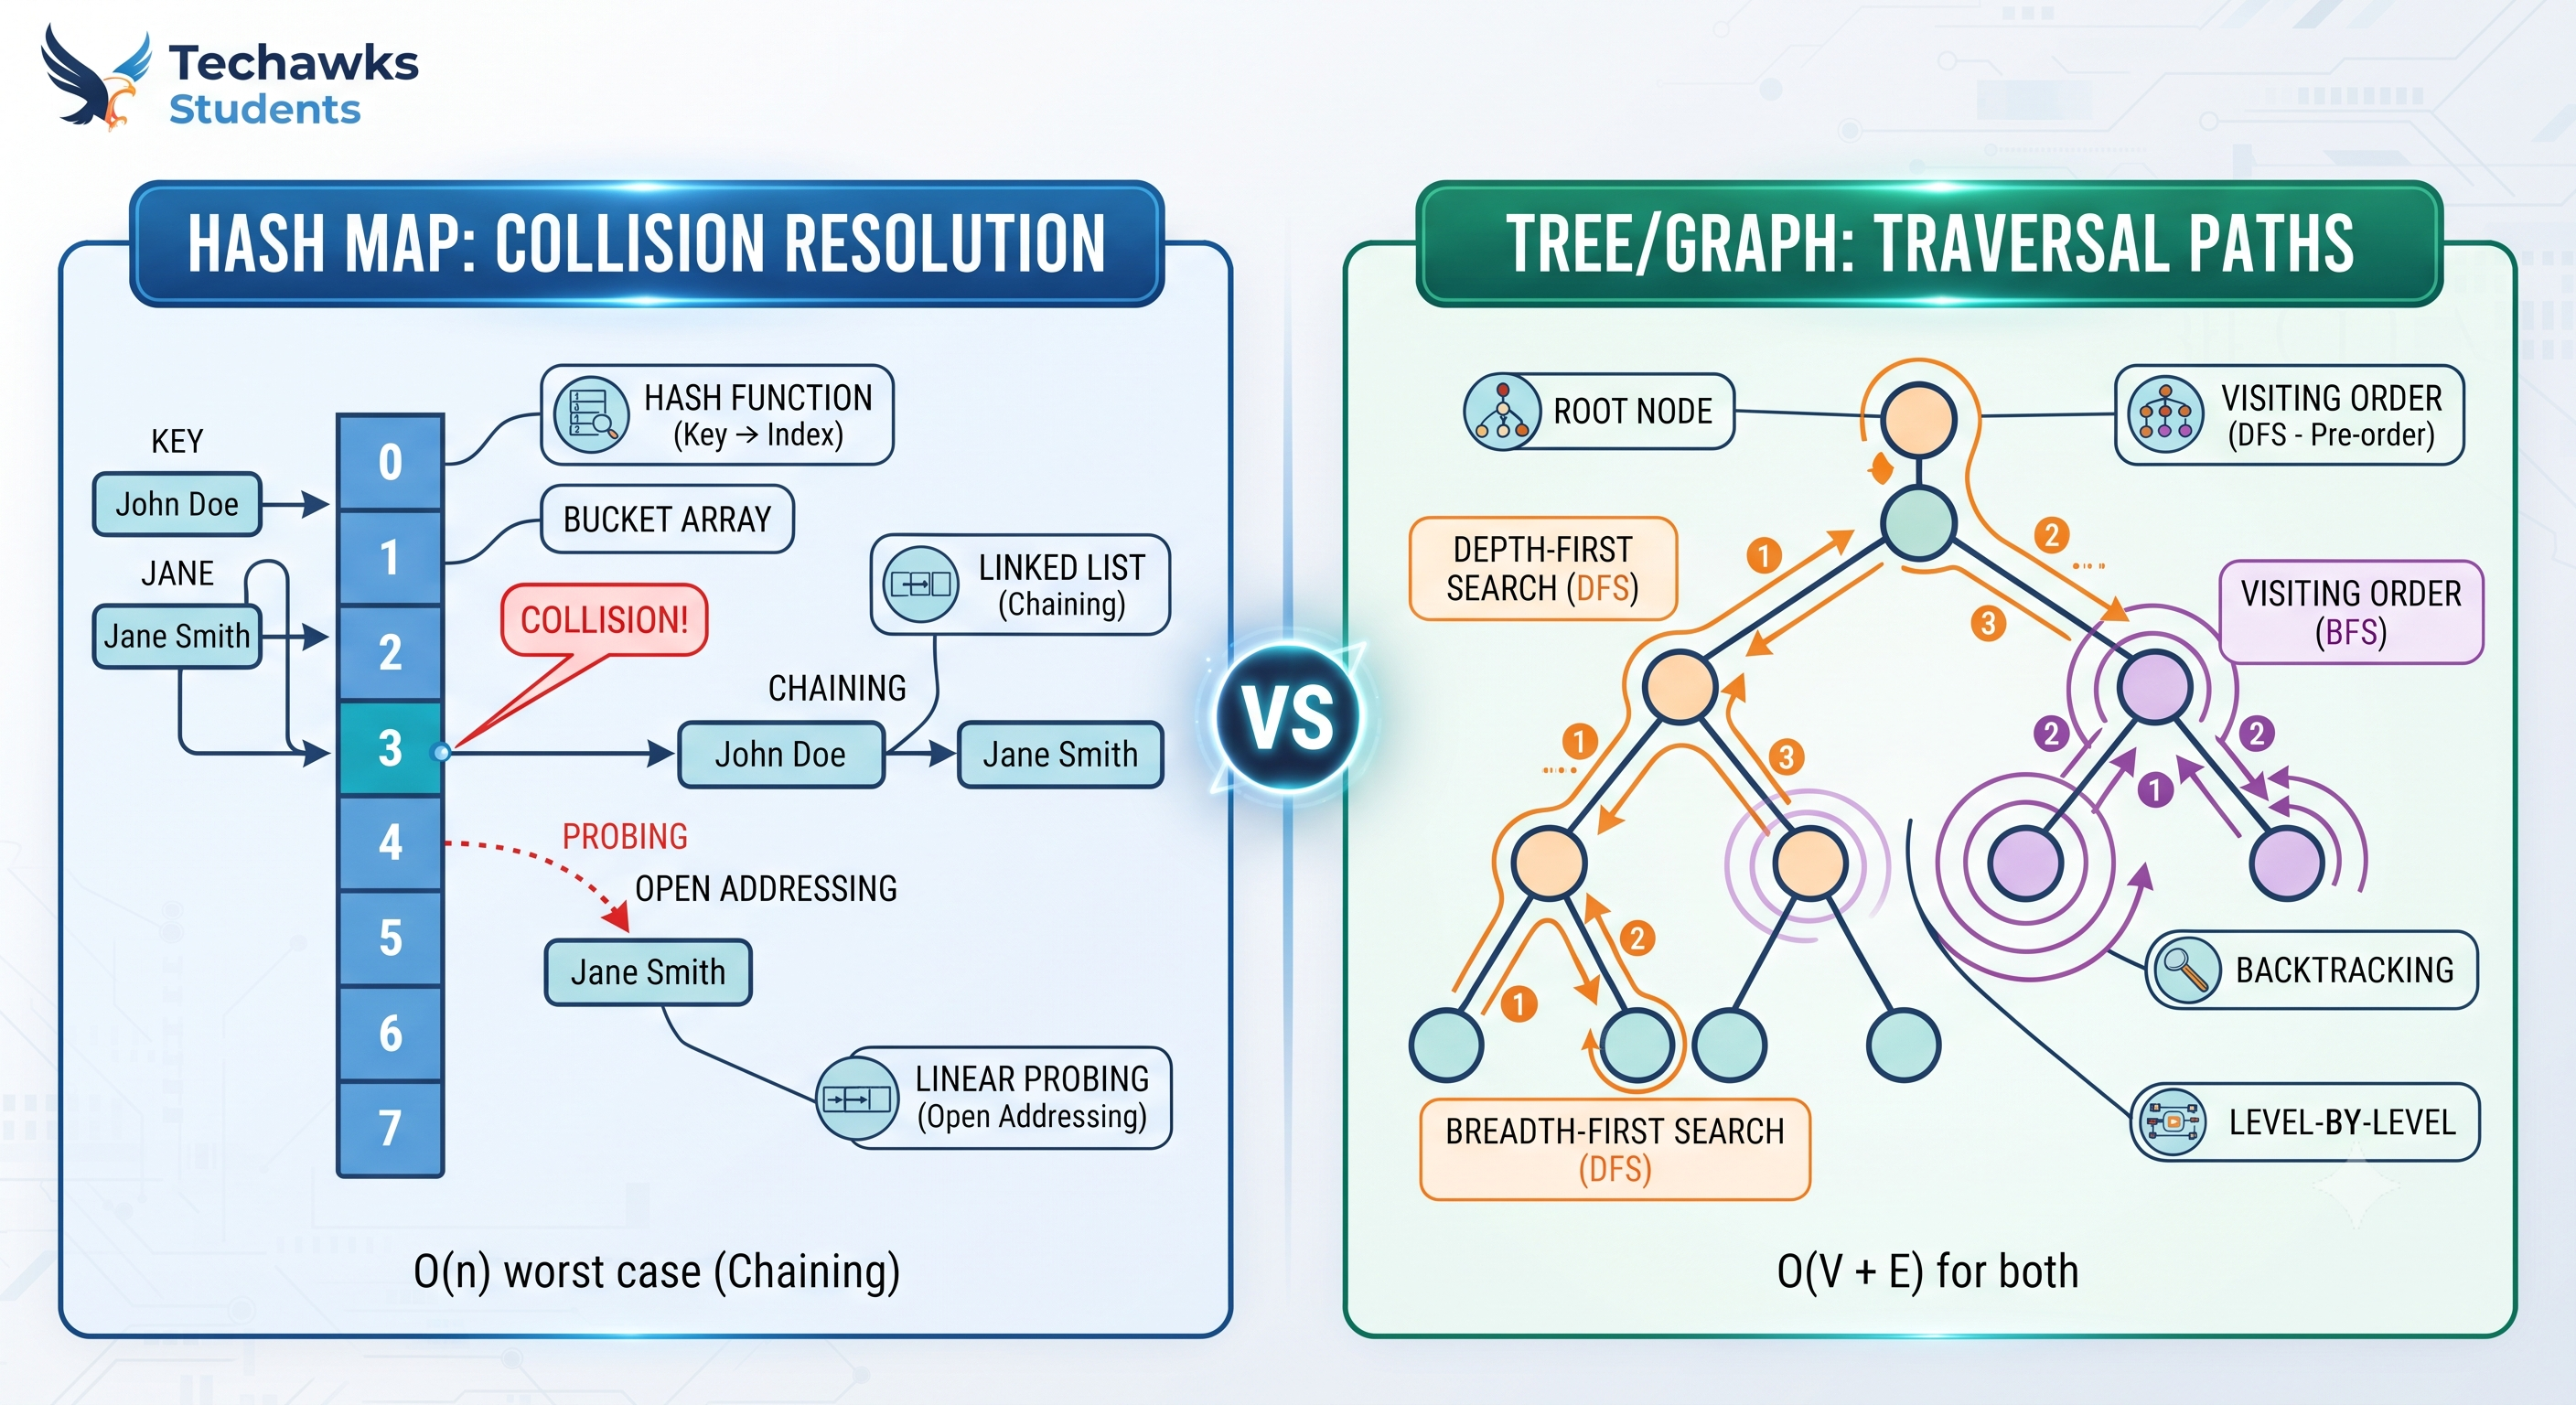
  • Beyond Basic Coding: Why Learning Abstract Data Structures Unlocks Faster Problem Solving


    When you're first learning to code, it’s easy to treat arrays and loops as the answer to every problem. But as your codebases grow and datasets expand, choosing the wrong data structure can turn an O(n) operation into a massive performance bottleneck.


    Enter the Power of Abstract Data Types (ADTs):
    Understanding how structures like Hash Maps, Graphs, and Heaps are structured in memory changes how you approach software engineering:


    Master Hash Function Mechanics: Learn how keys map to memory addresses and how collision resolution (like chaining or open addressing) impacts lookup speeds.


    Visualize Graph Traversals: Understand when to use Breadth-First Search (BFS) versus Depth-First Search (DFS) for pathfinding, dependency resolution, and network mapping.


    Leverage Priority Queues: Use heaps when you need constant access to the largest or smallest elements without sorting an entire array every time new data arrives.


    By shifting your focus from syntax memorization to structural efficiency, you build a mental framework that makes learning new languages and passing technical evaluations much easier.


    Discussion Question: What data structure do you find the most challenging to implement from scratch? Let’s break it down together in the comments! 👇


    CTA (Join Students in Tech): Ready to accelerate your computer science journey and build a rock-solid foundation? Join our community of students and learners at Techawks to master the concepts that matter.
    Beyond Basic Coding: Why Learning Abstract Data Structures Unlocks Faster Problem Solving When you're first learning to code, it’s easy to treat arrays and loops as the answer to every problem. But as your codebases grow and datasets expand, choosing the wrong data structure can turn an O(n) operation into a massive performance bottleneck. Enter the Power of Abstract Data Types (ADTs): Understanding how structures like Hash Maps, Graphs, and Heaps are structured in memory changes how you approach software engineering: Master Hash Function Mechanics: Learn how keys map to memory addresses and how collision resolution (like chaining or open addressing) impacts lookup speeds. Visualize Graph Traversals: Understand when to use Breadth-First Search (BFS) versus Depth-First Search (DFS) for pathfinding, dependency resolution, and network mapping. Leverage Priority Queues: Use heaps when you need constant access to the largest or smallest elements without sorting an entire array every time new data arrives. By shifting your focus from syntax memorization to structural efficiency, you build a mental framework that makes learning new languages and passing technical evaluations much easier. Discussion Question: What data structure do you find the most challenging to implement from scratch? Let’s break it down together in the comments! 👇 CTA (Join Students in Tech): Ready to accelerate your computer science journey and build a rock-solid foundation? Join our community of students and learners at Techawks to master the concepts that matter.
    0 Comentários 0 Compartilhamentos 111 Visualizações 0 Anterior
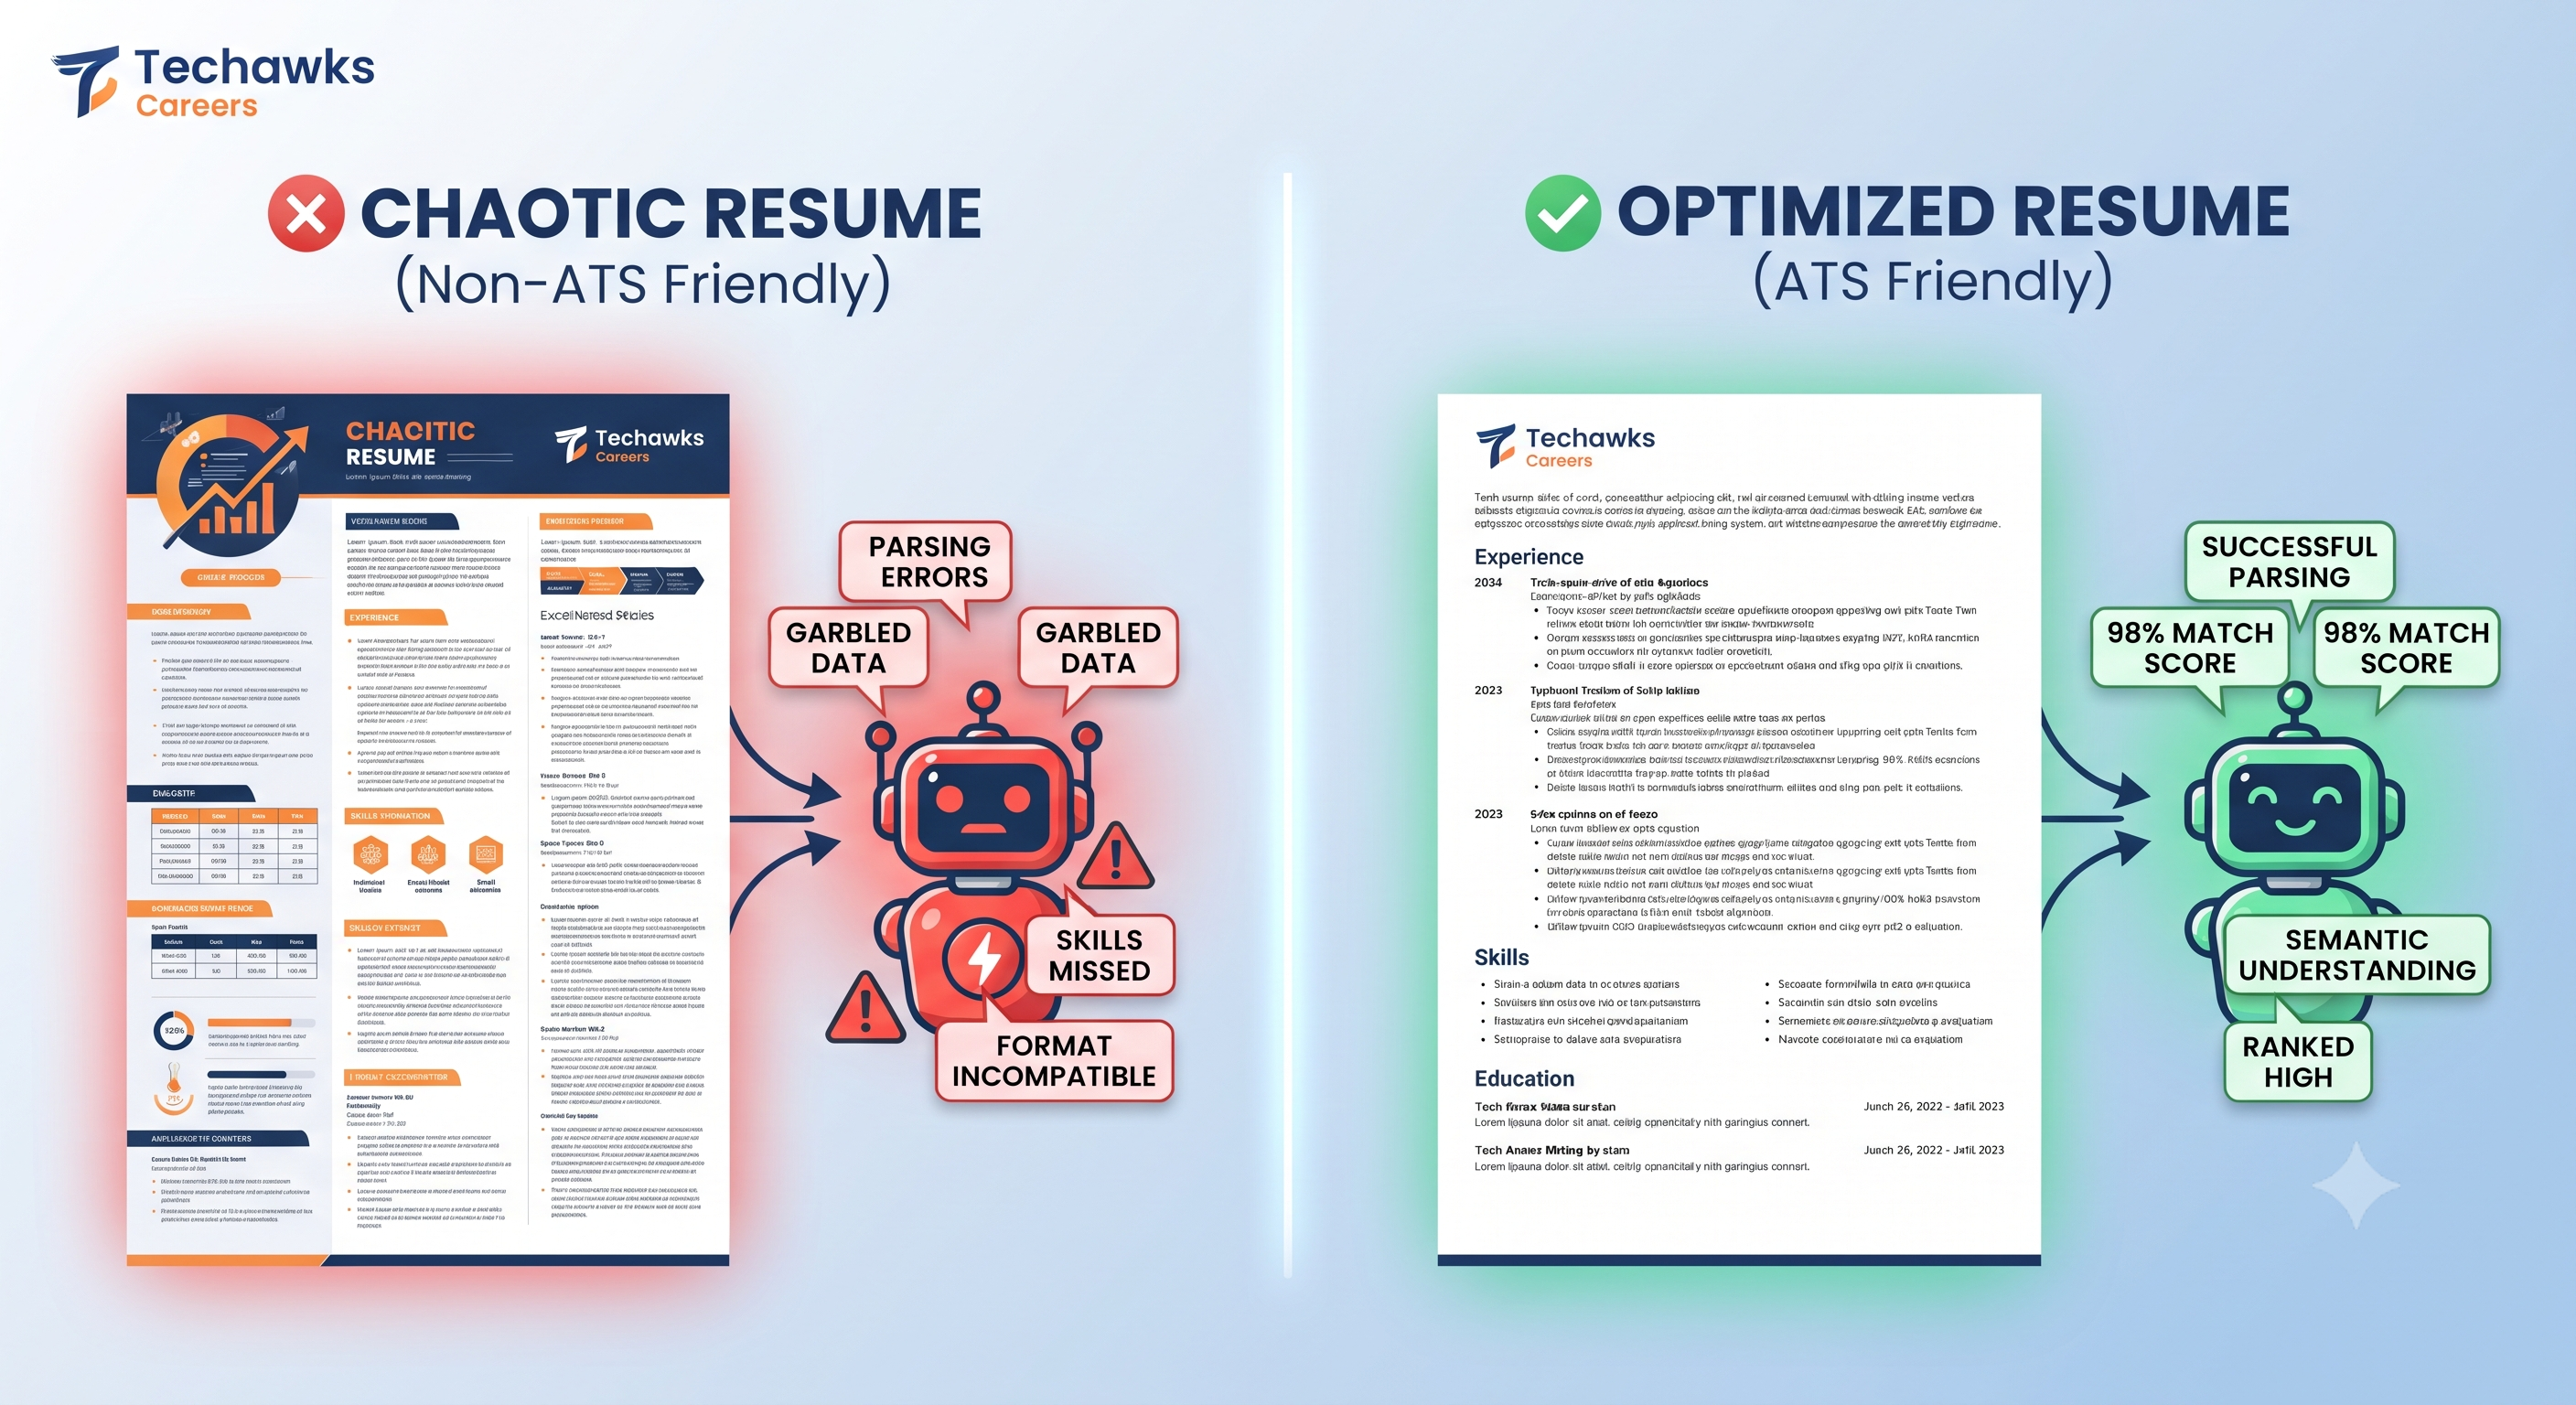
  • Beating the ATS Black Hole: Why AI Resume Parsers Fail and How to Optimize Your Profile


    Job seekers often assume a human reads their resume first. In reality, over 75% of large enterprises use automated ATS and AI embedding models to parse, rank, and filter resumes before a recruiter ever looks at them.


    Enter AI-Driven Resume Parsers (Semantic Vector Matching):
    Modern ATS tools don't just look for keyword matching anymore; they use vector embeddings to judge semantic similarity between your experience and the job description. Here is how you can beat the algorithm:


    Structure for Parsers, Not Just Aesthetics: Avoid multi-column layouts, tables, text boxes, and graphic elements. Linear, clean Markdown or standard single-column PDF formatting ensures structural text extraction without data loss.


    Map Experience to Core Competencies: Instead of hiding skills in dense paragraphs, use clear, standard industry headings (e.g., "Technical Skills", "Professional Experience") followed by bullet points detailing metrics and tools.


    Mirror Relevant Terminology: Incorporate explicit tool names and methodologies from the job description naturally into your impact statements so the vector model scores your semantic proximity higher.


    By understanding the technical pipeline of hiring software, you stop guessing and start engineering a resume that gets flagged for human review.


    Discussion Question: Have you ever experimented with tailoring your resume format specifically for ATS algorithms, or do you prefer keeping it traditional? Let’s share strategies below! 👇


    CTA (Join Tech Jobs & Opportunities): Ready to land your next big career milestone? Join our community of job seekers and professionals at Techawks to master the tools, resume strategies, and insights that matter.
    Beating the ATS Black Hole: Why AI Resume Parsers Fail and How to Optimize Your Profile Job seekers often assume a human reads their resume first. In reality, over 75% of large enterprises use automated ATS and AI embedding models to parse, rank, and filter resumes before a recruiter ever looks at them. Enter AI-Driven Resume Parsers (Semantic Vector Matching): Modern ATS tools don't just look for keyword matching anymore; they use vector embeddings to judge semantic similarity between your experience and the job description. Here is how you can beat the algorithm: Structure for Parsers, Not Just Aesthetics: Avoid multi-column layouts, tables, text boxes, and graphic elements. Linear, clean Markdown or standard single-column PDF formatting ensures structural text extraction without data loss. Map Experience to Core Competencies: Instead of hiding skills in dense paragraphs, use clear, standard industry headings (e.g., "Technical Skills", "Professional Experience") followed by bullet points detailing metrics and tools. Mirror Relevant Terminology: Incorporate explicit tool names and methodologies from the job description naturally into your impact statements so the vector model scores your semantic proximity higher. By understanding the technical pipeline of hiring software, you stop guessing and start engineering a resume that gets flagged for human review. Discussion Question: Have you ever experimented with tailoring your resume format specifically for ATS algorithms, or do you prefer keeping it traditional? Let’s share strategies below! 👇 CTA (Join Tech Jobs & Opportunities): Ready to land your next big career milestone? Join our community of job seekers and professionals at Techawks to master the tools, resume strategies, and insights that matter.
    0 Comentários 0 Compartilhamentos 113 Visualizações 0 Anterior
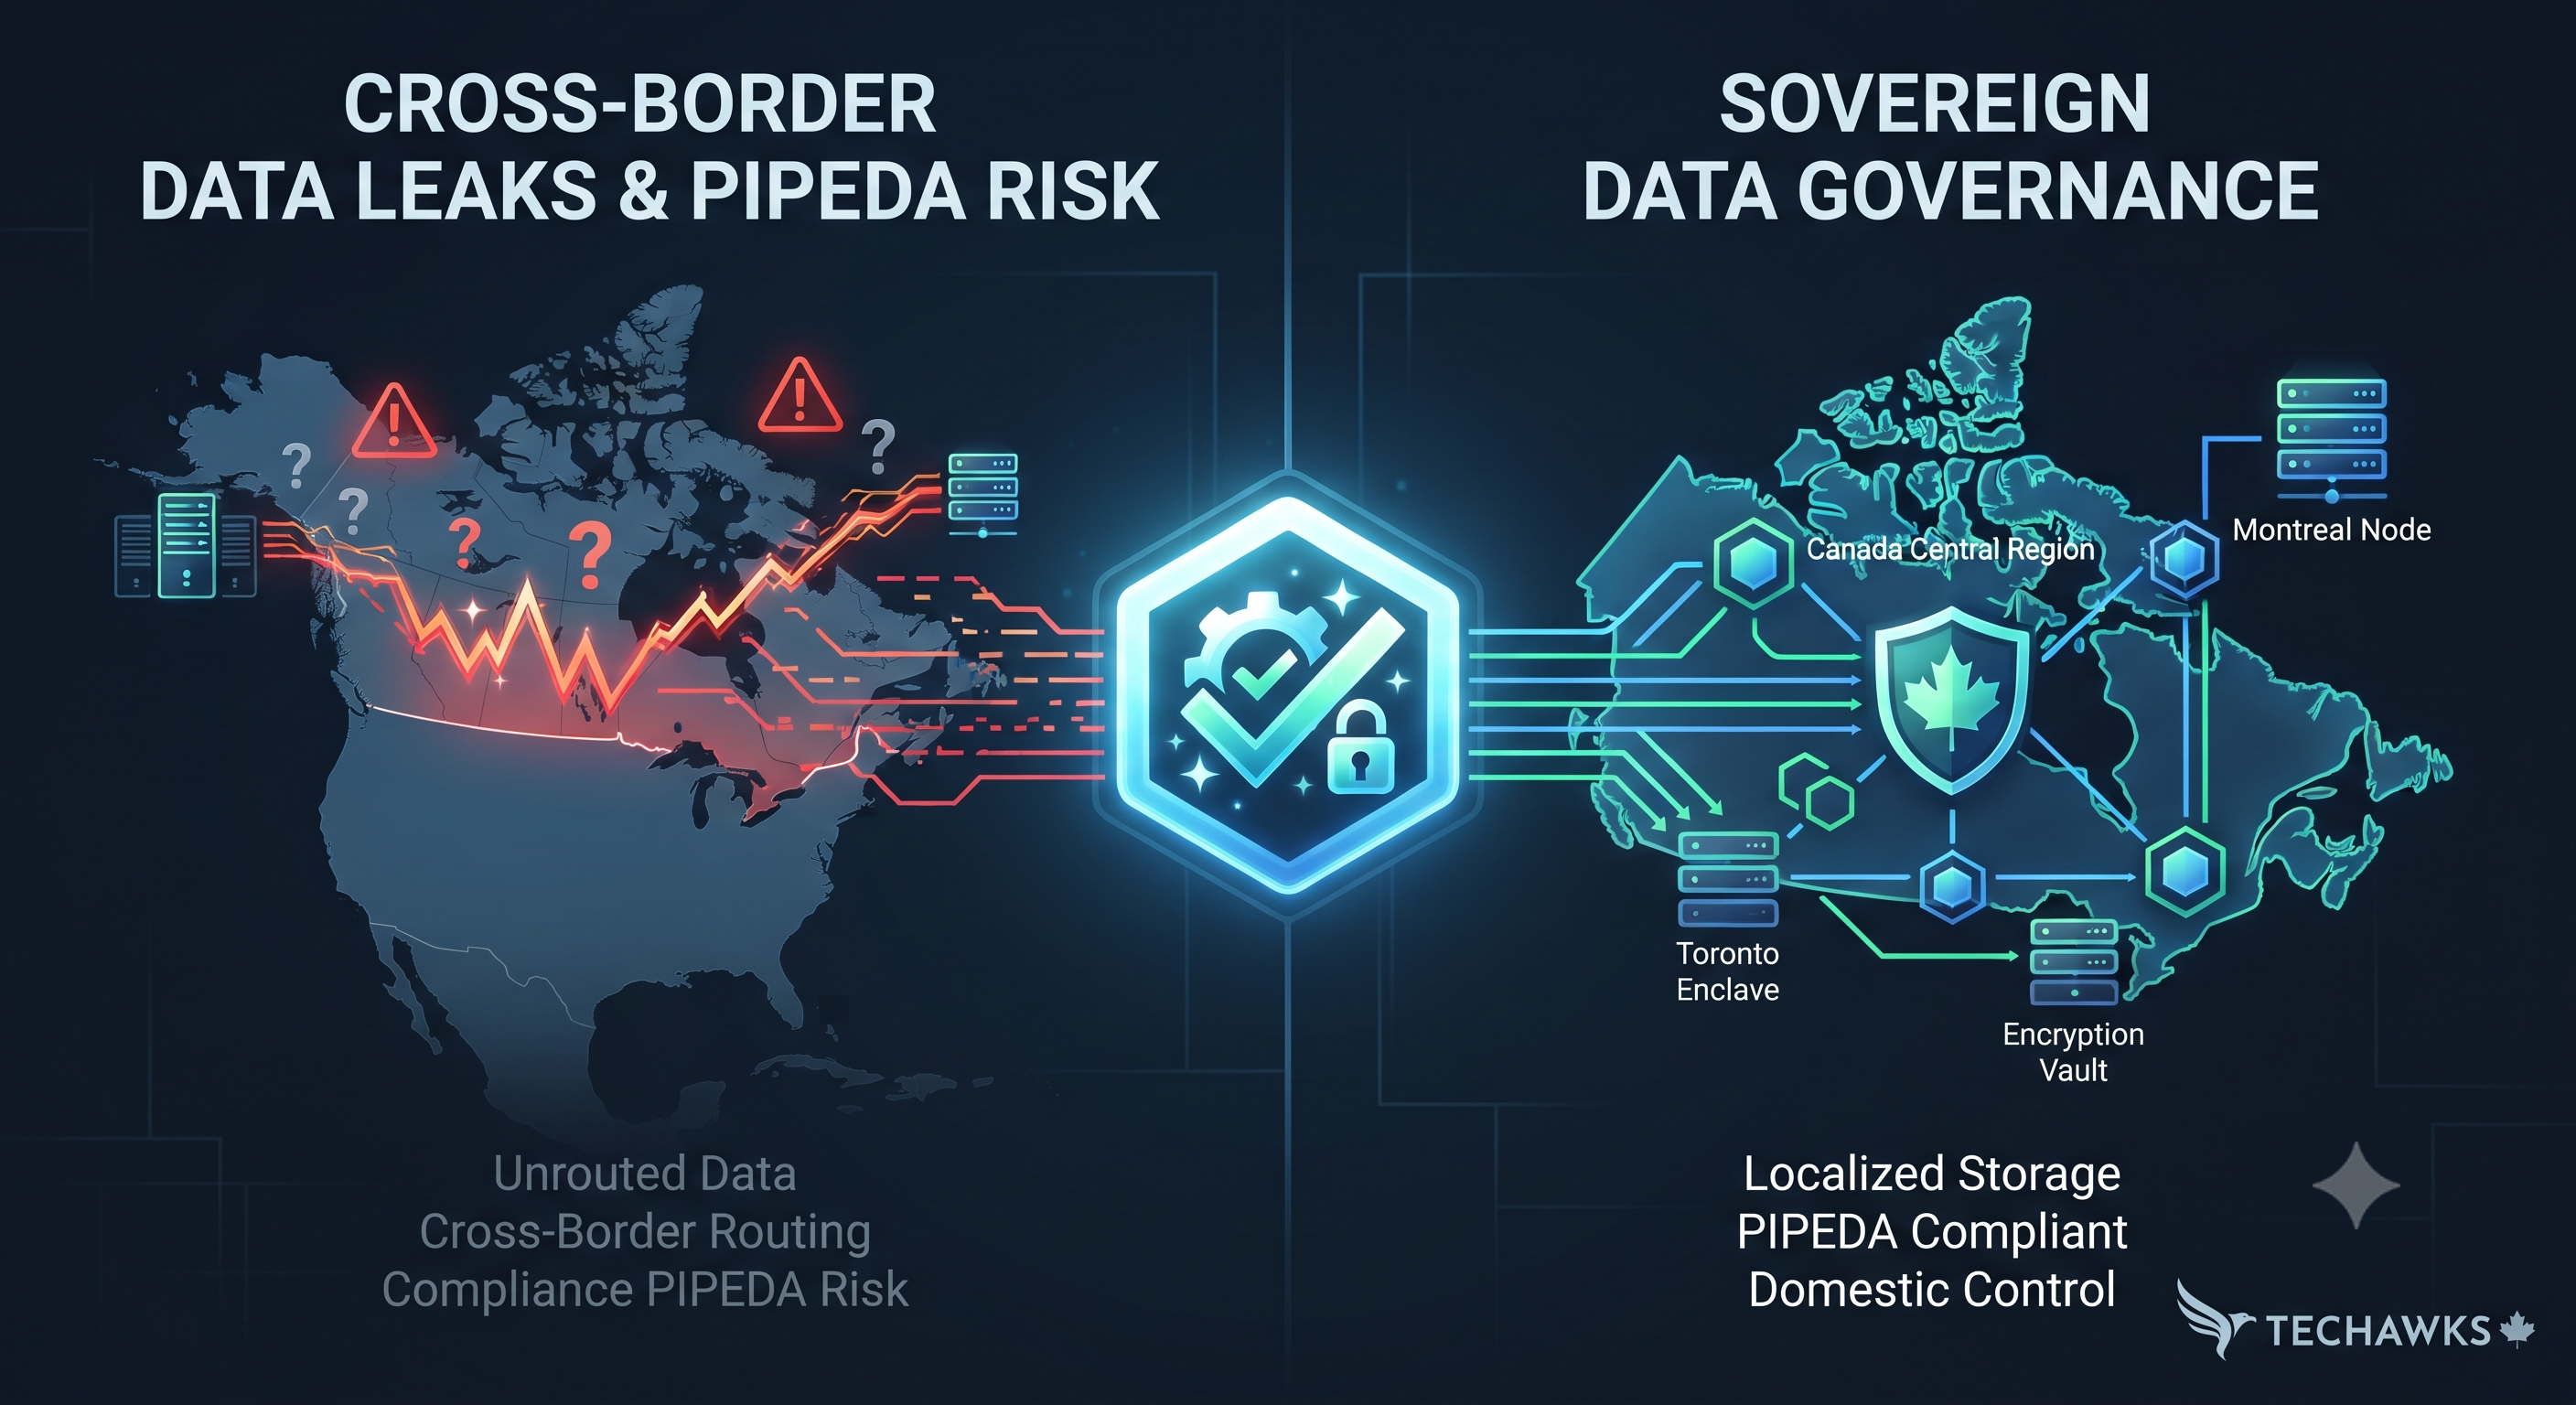
  • Stop Ignoring Data Residency: The 3-Step Compliance Framework for Canadian Tech Scale-Ups


    We have all been there: launching a digital product on a standard global cloud configuration, assuming that data storage locations do not matter as long as the service runs fast. While rapid deployment is essential, treating Canadian privacy legislation and cross-border data routing as an afterthought leaves your organization vulnerable to regulatory penalties and lost enterprise trust.


    To transform data compliance from a barrier into a secure, competitive advantage for Canada's tech ecosystem, put every system through this rigorous 3-step challenge framework:


    Step 1: The Cloud Region & Data Residency Audit
    Default cloud configurations often replicate database backups or route traffic across international borders without explicit developer awareness. Before signing your next client, audit your exact data storage and backup locations. Ask yourself: Is all sensitive user data strictly housed within Canadian cloud regions (such as AWS Canada Central or GCP Montreal/Toronto)? Strip out cross-border replication vectors for protected data.


    Step 2: The PIPEDA & Provincial Privacy Compliance Check
    Complying with the Personal Information Protection and Electronic Documents Act (PIPEDA)—along with stringent provincial equivalents like Quebec's Law 25—requires rigorous consent management and transparent data handling practices. Implement automated data inventory mapping so you can instantly verify how personal information is collected, used, and disclosed within Canadian jurisdictions.


    Step 3: The Cross-Border Transfer & Encryption Pass
    If data must transit outside Canadian borders for specialized third-party processing, ensure it is protected by robust end-to-end encryption with keys managed exclusively within domestic control. Strip out unencrypted third-party analytics trackers that inadvertently leak personal identifiers to foreign servers.


    The Challenge for Today:
    Open your cloud provider's database management console and check the physical region of your primary storage buckets and read replicas. If a single byte of sensitive Canadian user data is sitting outside domestic borders, refactor your infrastructure deployment script immediately.


    Key Takeaways
    Secure Domestic Storage: Never rely on default cloud routing; explicitly pin your primary databases and backups to Canadian cloud regions.


    Master Compliance Frameworks: Align your data governance tightly with PIPEDA and provincial privacy laws to win enterprise and public sector trust.


    Control Cross-Border Transit: Enforce strict end-to-end encryption and eliminate unvetted third-party trackers that leak user data internationally.


    CTA (Join Techawks Canada)
    Want to elevate your engineering standards and connect with innovators across the Canadian tech ecosystem? Join Techawks Canada today to share governance patterns, tackle weekly engineering challenges, and build secure, trusted software together.
    Stop Ignoring Data Residency: The 3-Step Compliance Framework for Canadian Tech Scale-Ups We have all been there: launching a digital product on a standard global cloud configuration, assuming that data storage locations do not matter as long as the service runs fast. While rapid deployment is essential, treating Canadian privacy legislation and cross-border data routing as an afterthought leaves your organization vulnerable to regulatory penalties and lost enterprise trust. To transform data compliance from a barrier into a secure, competitive advantage for Canada's tech ecosystem, put every system through this rigorous 3-step challenge framework: Step 1: The Cloud Region & Data Residency Audit Default cloud configurations often replicate database backups or route traffic across international borders without explicit developer awareness. Before signing your next client, audit your exact data storage and backup locations. Ask yourself: Is all sensitive user data strictly housed within Canadian cloud regions (such as AWS Canada Central or GCP Montreal/Toronto)? Strip out cross-border replication vectors for protected data. Step 2: The PIPEDA & Provincial Privacy Compliance Check Complying with the Personal Information Protection and Electronic Documents Act (PIPEDA)—along with stringent provincial equivalents like Quebec's Law 25—requires rigorous consent management and transparent data handling practices. Implement automated data inventory mapping so you can instantly verify how personal information is collected, used, and disclosed within Canadian jurisdictions. Step 3: The Cross-Border Transfer & Encryption Pass If data must transit outside Canadian borders for specialized third-party processing, ensure it is protected by robust end-to-end encryption with keys managed exclusively within domestic control. Strip out unencrypted third-party analytics trackers that inadvertently leak personal identifiers to foreign servers. The Challenge for Today: Open your cloud provider's database management console and check the physical region of your primary storage buckets and read replicas. If a single byte of sensitive Canadian user data is sitting outside domestic borders, refactor your infrastructure deployment script immediately. Key Takeaways Secure Domestic Storage: Never rely on default cloud routing; explicitly pin your primary databases and backups to Canadian cloud regions. Master Compliance Frameworks: Align your data governance tightly with PIPEDA and provincial privacy laws to win enterprise and public sector trust. Control Cross-Border Transit: Enforce strict end-to-end encryption and eliminate unvetted third-party trackers that leak user data internationally. CTA (Join Techawks Canada) Want to elevate your engineering standards and connect with innovators across the Canadian tech ecosystem? Join Techawks Canada today to share governance patterns, tackle weekly engineering challenges, and build secure, trusted software together.
    0 Comentários 0 Compartilhamentos 381 Visualizações 0 Anterior
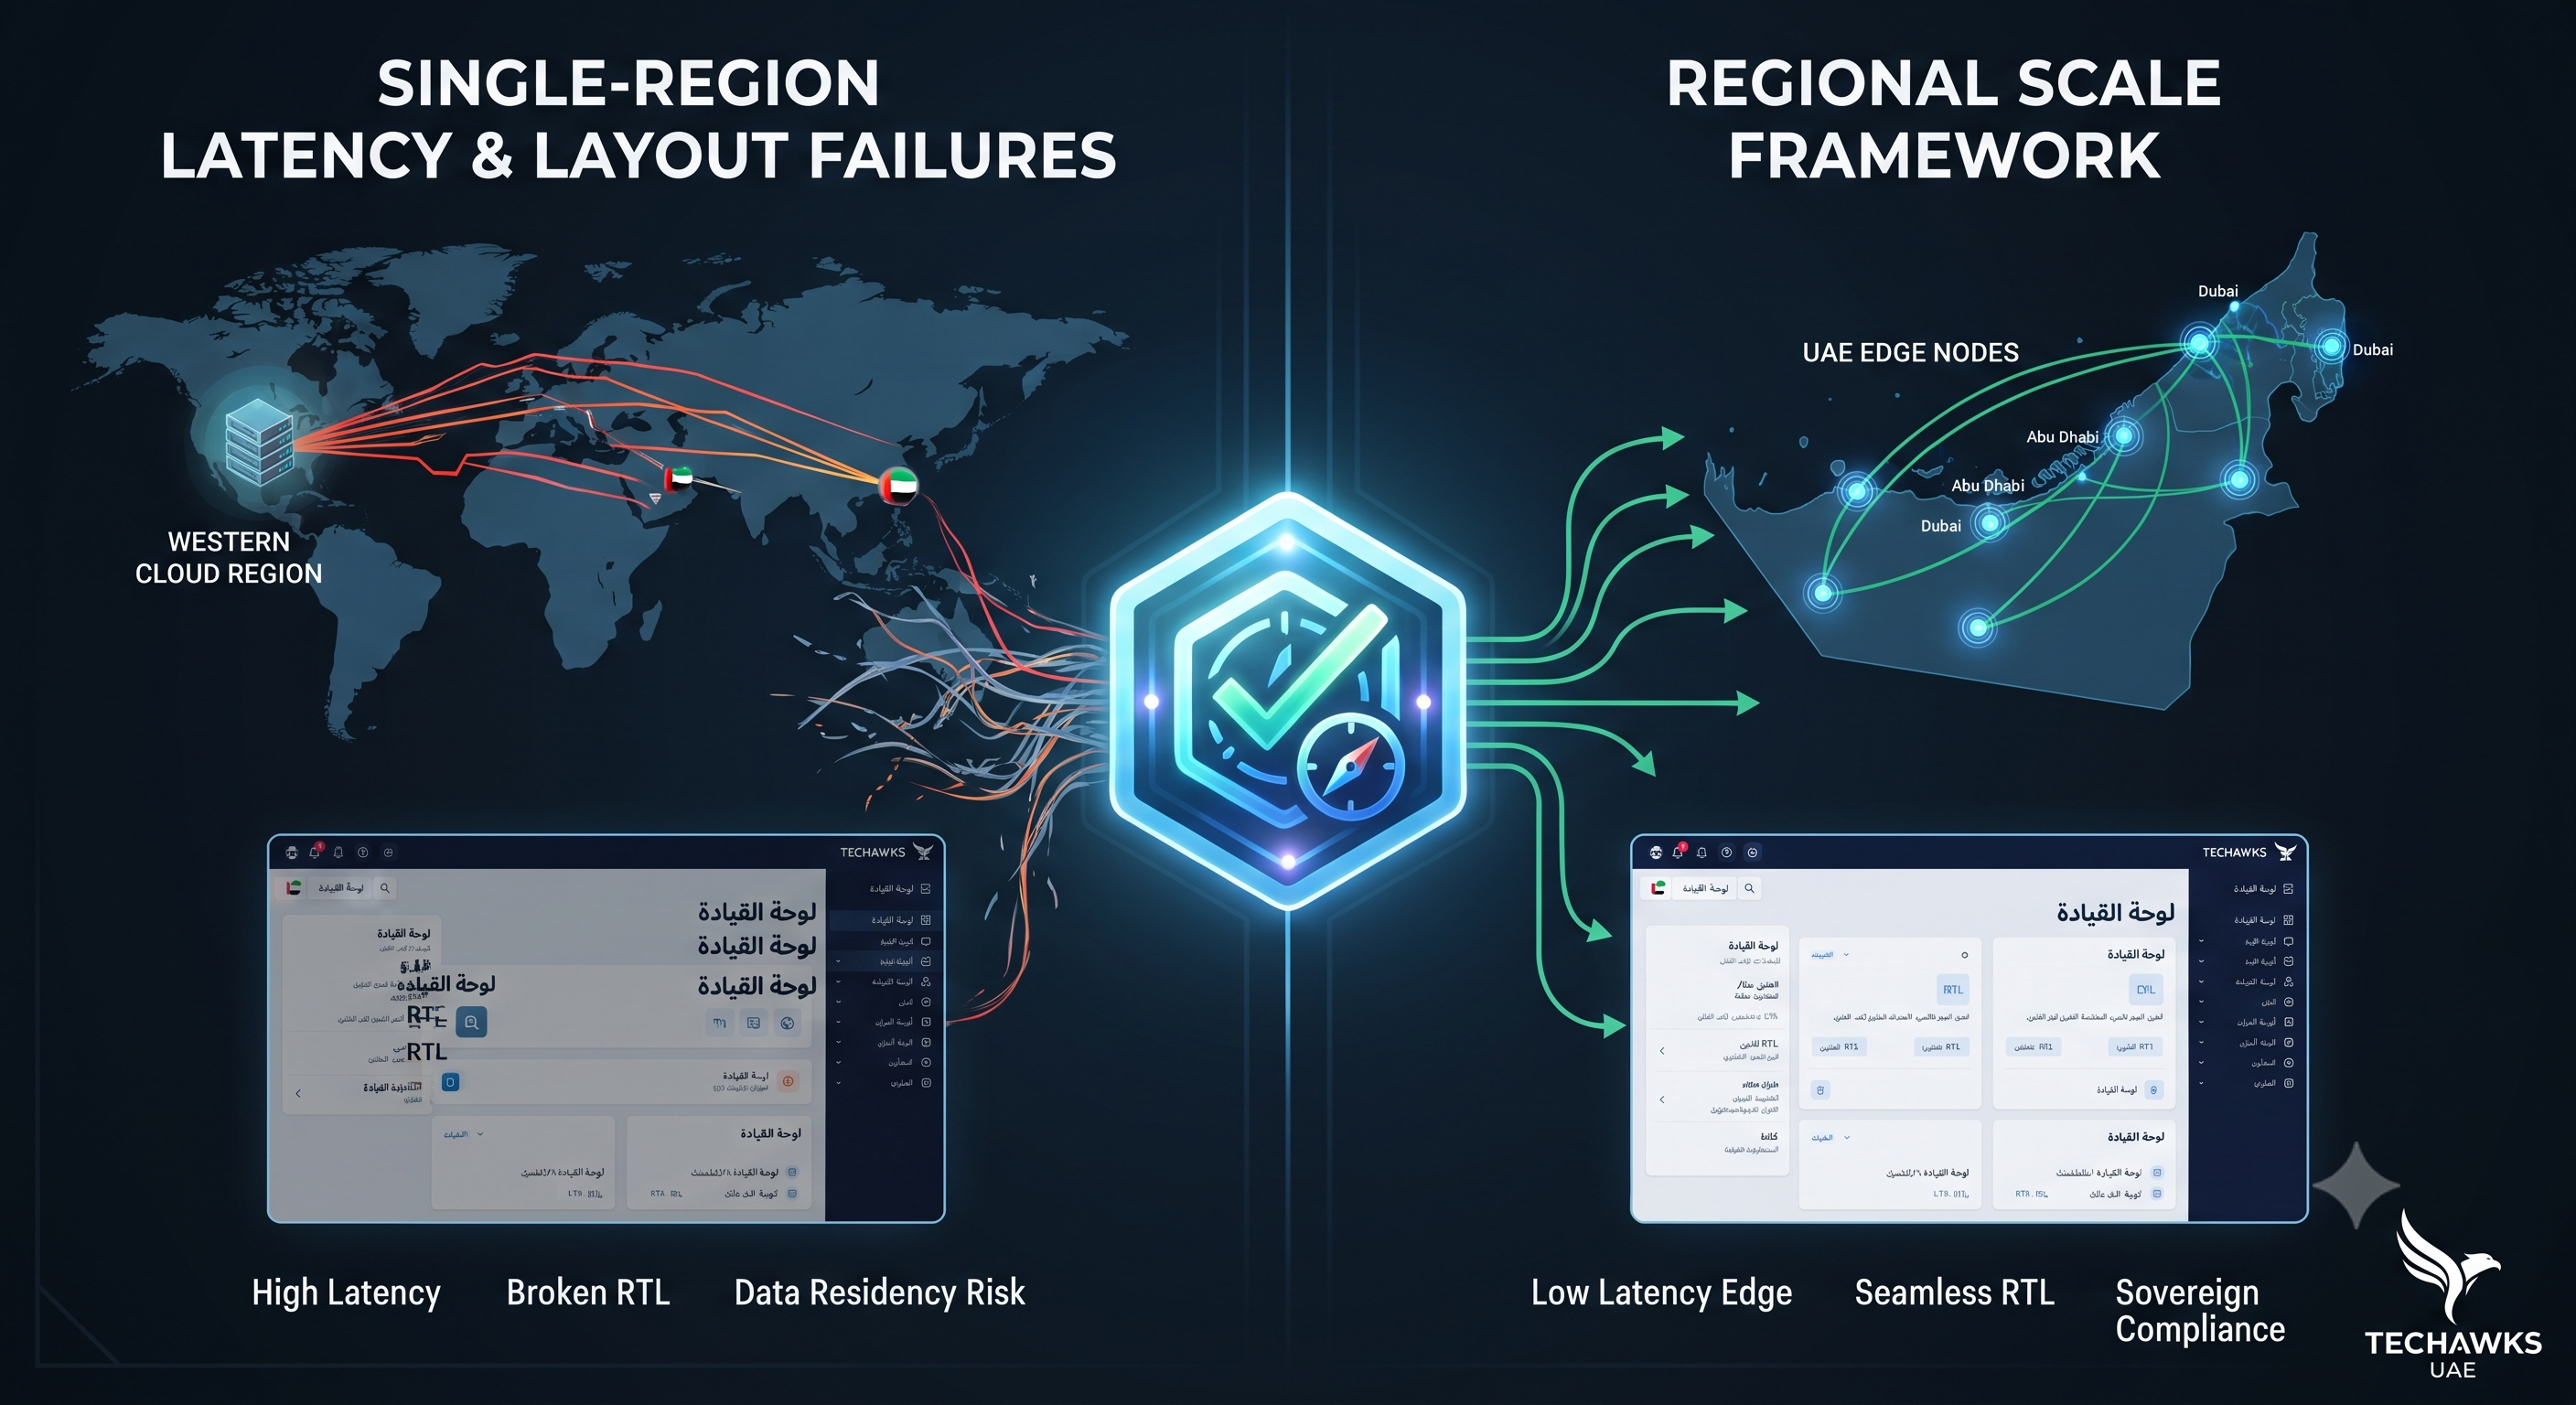
  • Stop Building Without Localization Guardrails: The 3-Step Multi-Regional Architecture Framework for UAE Tech Scale-Ups


    We have all been there: launching an application globally while assuming a single Western cloud region and left-to-right design will suffice everywhere. While rapid deployment is essential, treating localization and regional data governance as checkboxes leads to poor performance, compliance risks, and high user churn.


    To transform a standard deployment into a robust, high-performance regional operation suited for the UAE's thriving digital economy, put every system through this rigorous 3-step challenge framework:


    Step 1: The Local Edge & Low-Latency Routing Audit
    Distant cloud regions introduce severe network latency for users accessing services from the Middle East. Before pushing any service live, audit your CDN and server placement. Ask yourself: Are our static assets and API endpoints cached at regional edge nodes within the UAE? Leverage local data centers and multi-region routing to ensure lightning-fast response times.


    Step 2: The Bi-Directional UI & Localization Check
    Supporting diverse linguistic communities requires more than simple text translation. Ensure your application architecture fully supports dynamic layout mirroring (LTR and RTL), proper font rendering for Arabic typography, and localized date, currency, and numerical formatting without breaking UI components.


    Step 3: The Data Residency & Sovereign Compliance Pass
    Many regional sectors and enterprise clients require data to remain strictly within domestic borders. Strip out cross-border logging vulnerabilities, implement local data residency storage policies, and ensure your cloud infrastructure complies with regional regulatory data protection standards.


    The Challenge for Today:
    Open your application's deployment topology and frontend codebase. Test your UI layout in an RTL configuration and check your primary database hosting region. If your data is stored thousands of miles away or your UI breaks under localized text, refactor your architecture before regional users experience the lag.


    Key Takeaways
    Optimize for Edge Latency: Deploy services and edge caching nodes close to your regional users to eliminate network lag.


    Master Bi-Directional Design: Build robust UI systems that seamlessly handle RTL layouts, localized typography, and regional formatting.


    Ensure Data Residency: Comply with local regulatory frameworks by keeping sensitive data stored within domestic cloud regions.


    CTA (Join Techawks UAE)
    Want to elevate your technical architecture and connect with innovators across the UAE tech ecosystem? Join Techawks UAE today to share regional scaling patterns, tackle weekly engineering challenges, and build world-class products together.
    Stop Building Without Localization Guardrails: The 3-Step Multi-Regional Architecture Framework for UAE Tech Scale-Ups We have all been there: launching an application globally while assuming a single Western cloud region and left-to-right design will suffice everywhere. While rapid deployment is essential, treating localization and regional data governance as checkboxes leads to poor performance, compliance risks, and high user churn. To transform a standard deployment into a robust, high-performance regional operation suited for the UAE's thriving digital economy, put every system through this rigorous 3-step challenge framework: Step 1: The Local Edge & Low-Latency Routing Audit Distant cloud regions introduce severe network latency for users accessing services from the Middle East. Before pushing any service live, audit your CDN and server placement. Ask yourself: Are our static assets and API endpoints cached at regional edge nodes within the UAE? Leverage local data centers and multi-region routing to ensure lightning-fast response times. Step 2: The Bi-Directional UI & Localization Check Supporting diverse linguistic communities requires more than simple text translation. Ensure your application architecture fully supports dynamic layout mirroring (LTR and RTL), proper font rendering for Arabic typography, and localized date, currency, and numerical formatting without breaking UI components. Step 3: The Data Residency & Sovereign Compliance Pass Many regional sectors and enterprise clients require data to remain strictly within domestic borders. Strip out cross-border logging vulnerabilities, implement local data residency storage policies, and ensure your cloud infrastructure complies with regional regulatory data protection standards. The Challenge for Today: Open your application's deployment topology and frontend codebase. Test your UI layout in an RTL configuration and check your primary database hosting region. If your data is stored thousands of miles away or your UI breaks under localized text, refactor your architecture before regional users experience the lag. Key Takeaways Optimize for Edge Latency: Deploy services and edge caching nodes close to your regional users to eliminate network lag. Master Bi-Directional Design: Build robust UI systems that seamlessly handle RTL layouts, localized typography, and regional formatting. Ensure Data Residency: Comply with local regulatory frameworks by keeping sensitive data stored within domestic cloud regions. CTA (Join Techawks UAE) Want to elevate your technical architecture and connect with innovators across the UAE tech ecosystem? Join Techawks UAE today to share regional scaling patterns, tackle weekly engineering challenges, and build world-class products together.
    0 Comentários 0 Compartilhamentos 228 Visualizações 0 Anterior
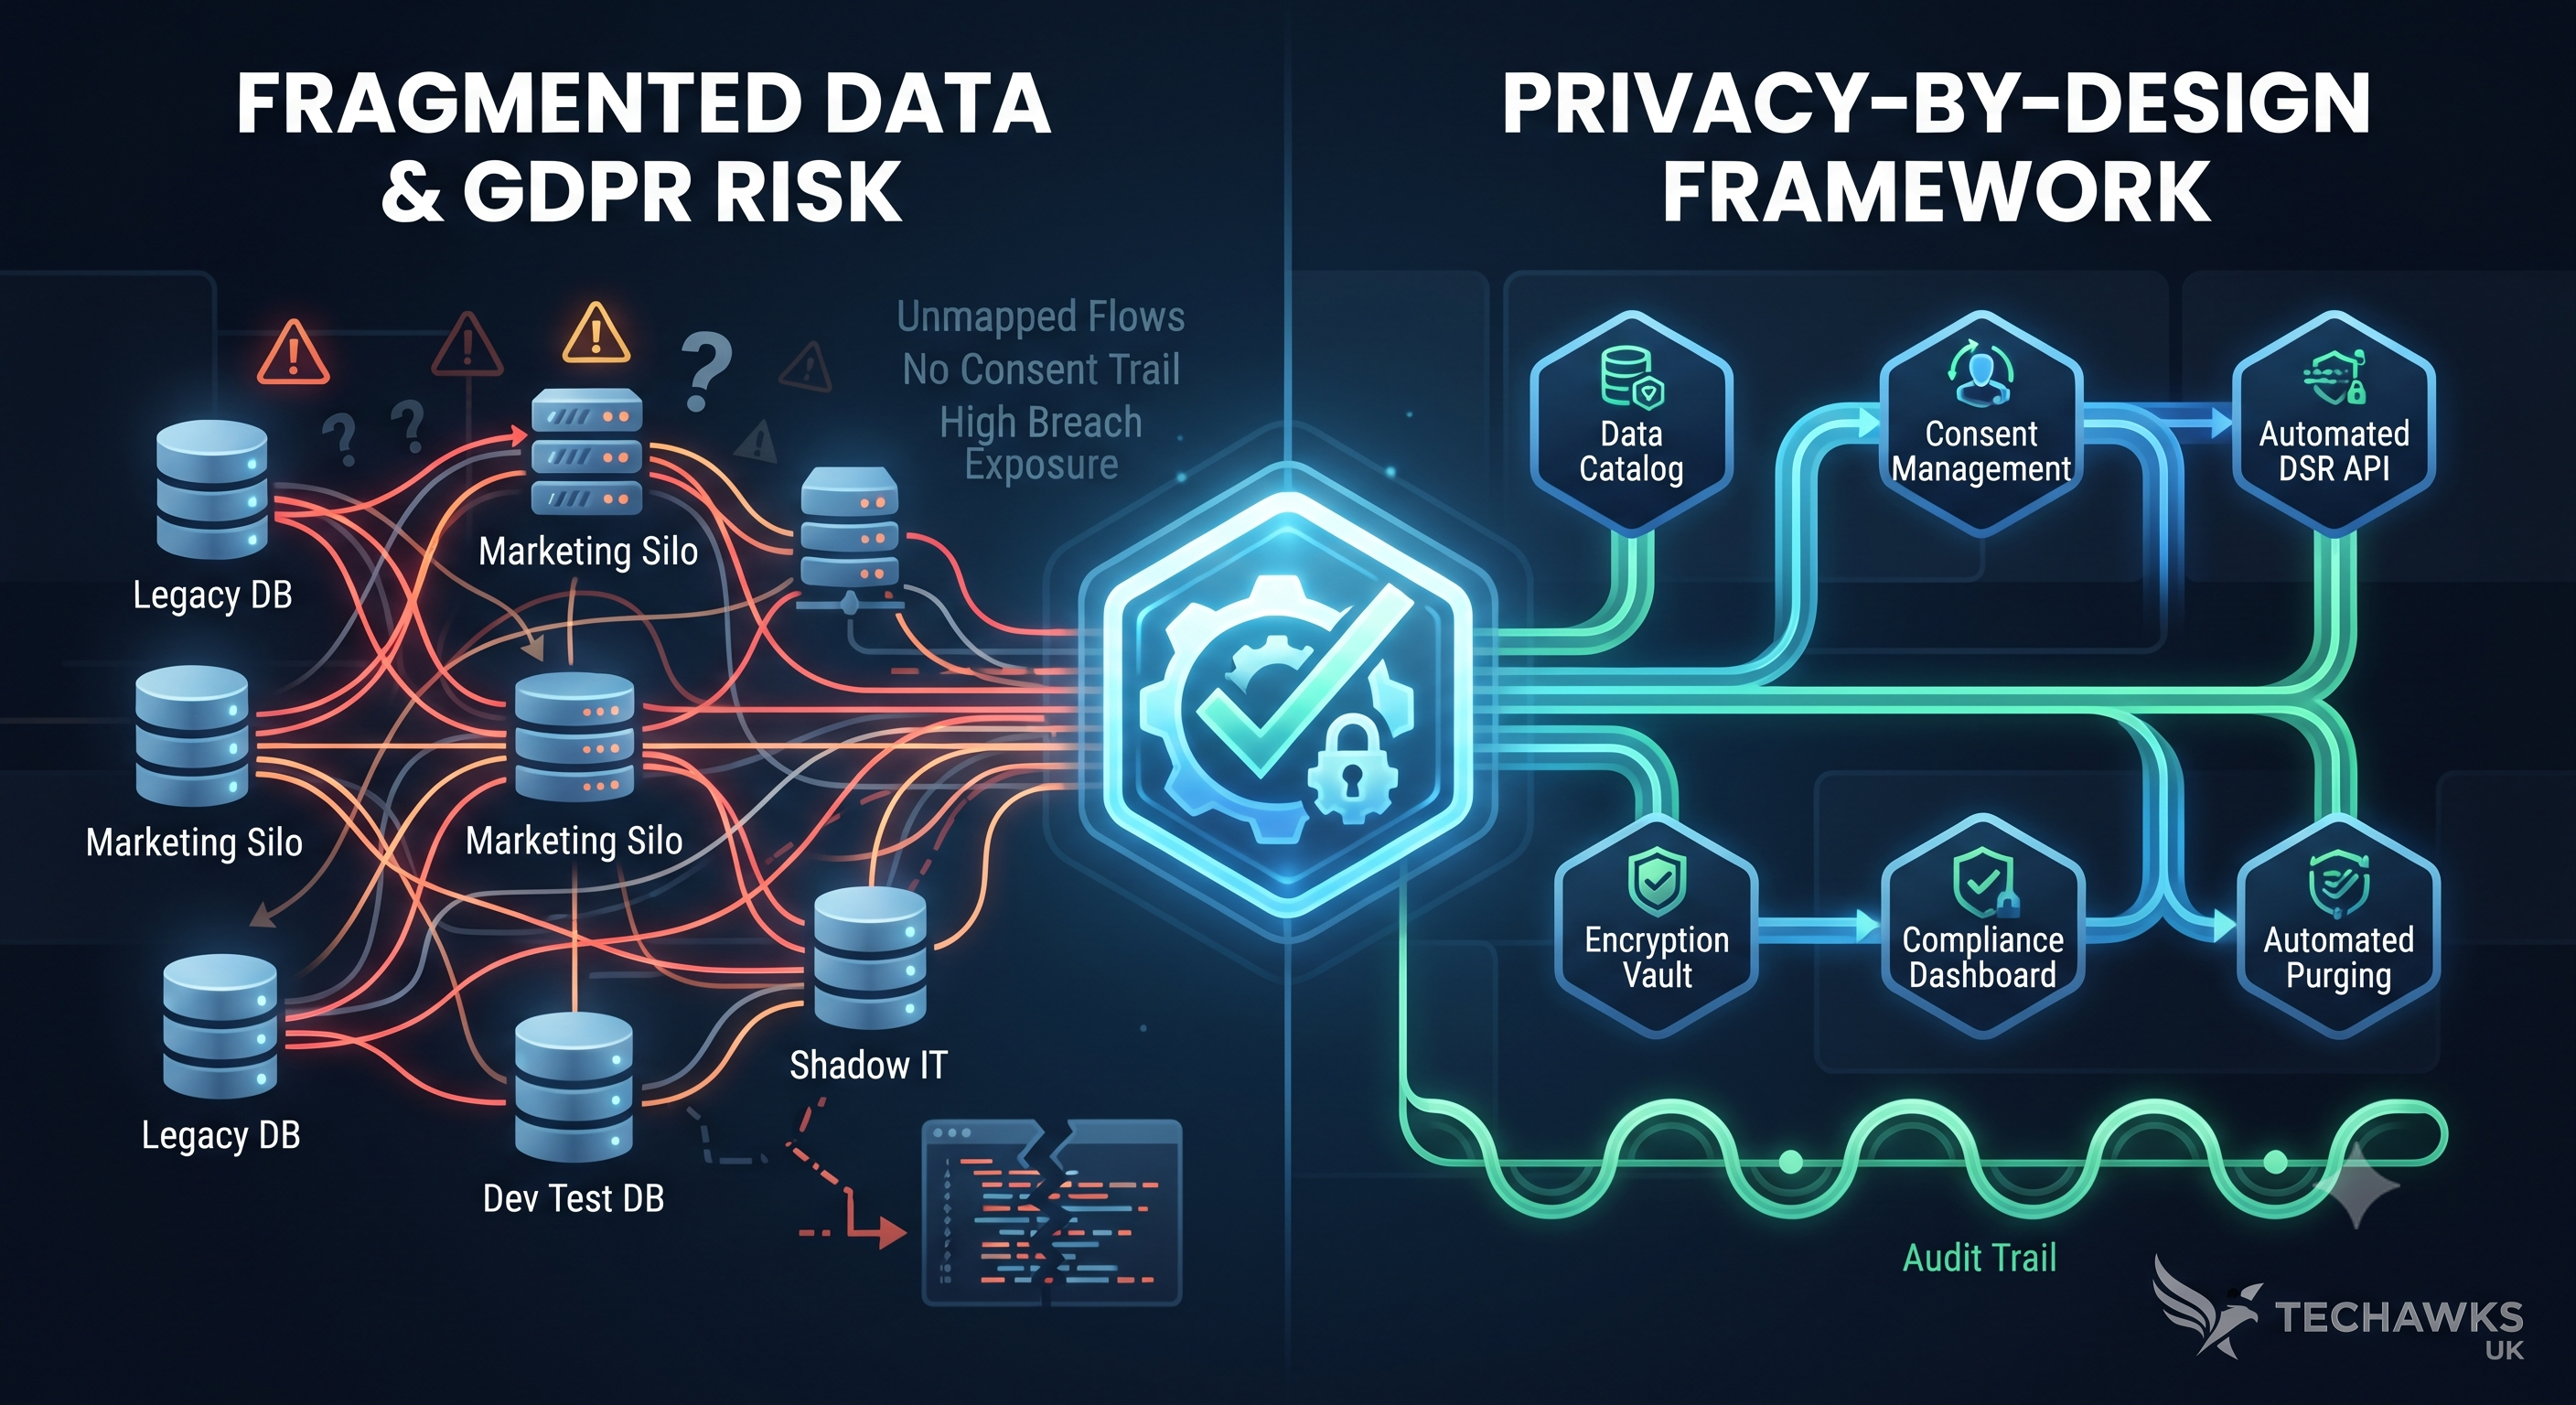
  • Stop Ignoring Compliance: The 3-Step Data Governance & Privacy Framework for UK Tech Scale-Ups


    We have all been there: collecting user data freely during the early growth phase, assuming that sorting out privacy policies and data mapping can wait until later. While moving fast is essential, treating UK GDPR and data governance as a checkbox exercise leaves your organization exposed to severe regulatory penalties and loss of customer trust.


    To transform data privacy from a burden into a secure, competitive advantage, put every system through this rigorous 3-step challenge framework:


    Step 1: The End-to-End Data Flow Mapping Audit
    You cannot protect or delete data if you do not know where it lives. Before pushing new features live, map every data pipeline from ingestion to third-party storage. Ask yourself: Do we have a complete record of every personal identifier entering our systems, and exactly where is it processed? Eliminate shadow databases and unauthorized third-party trackers immediately.


    Step 2: The Automated Data Subject Rights (DSR) Workflow
    Handling Subject Access Requests (SARs) or "right to be forgotten" requests manually via scattered support tickets leads to missed statutory deadlines and compliance failures. Implement automated tools and scripts that can securely query, export, or redact a user's data across all microservices and storage tiers within minutes.


    Step 3: The Privacy-by-Design & Minimization Pass
    Collecting excessive data "just in case" increases your liability footprint during a breach. Strip out non-essential data collection fields, enforce strict data retention limits with automated purging schedules, and ensure encryption at rest and in transit across all environments.


    The Challenge for Today:
    Open your application's primary sign-up flow and database schema. Trace how a user's data is stored and whether your system can completely expunge that data across all tables upon request. If you find manual bottlenecks, refactor your data pipeline before a compliance audit tests it for you.


    Key Takeaways
    Map Your Data: Maintain rigorous end-to-end documentation of all personal data flows to eliminate hidden shadow storage.


    Automate Requests: Build streamlined, automated workflows to handle Subject Access Requests well within regulatory deadlines.


    Practice Minimization: Collect only necessary data points and enforce strict retention schedules with automated purging.


    CTA (Join Techawks UK)
    Want to elevate your engineering standards and compliance practices alongside thousands of tech professionals across the United Kingdom? Join Techawks UK today to share governance patterns, tackle weekly engineering challenges, and build secure, trusted software together.
    Stop Ignoring Compliance: The 3-Step Data Governance & Privacy Framework for UK Tech Scale-Ups We have all been there: collecting user data freely during the early growth phase, assuming that sorting out privacy policies and data mapping can wait until later. While moving fast is essential, treating UK GDPR and data governance as a checkbox exercise leaves your organization exposed to severe regulatory penalties and loss of customer trust. To transform data privacy from a burden into a secure, competitive advantage, put every system through this rigorous 3-step challenge framework: Step 1: The End-to-End Data Flow Mapping Audit You cannot protect or delete data if you do not know where it lives. Before pushing new features live, map every data pipeline from ingestion to third-party storage. Ask yourself: Do we have a complete record of every personal identifier entering our systems, and exactly where is it processed? Eliminate shadow databases and unauthorized third-party trackers immediately. Step 2: The Automated Data Subject Rights (DSR) Workflow Handling Subject Access Requests (SARs) or "right to be forgotten" requests manually via scattered support tickets leads to missed statutory deadlines and compliance failures. Implement automated tools and scripts that can securely query, export, or redact a user's data across all microservices and storage tiers within minutes. Step 3: The Privacy-by-Design & Minimization Pass Collecting excessive data "just in case" increases your liability footprint during a breach. Strip out non-essential data collection fields, enforce strict data retention limits with automated purging schedules, and ensure encryption at rest and in transit across all environments. The Challenge for Today: Open your application's primary sign-up flow and database schema. Trace how a user's data is stored and whether your system can completely expunge that data across all tables upon request. If you find manual bottlenecks, refactor your data pipeline before a compliance audit tests it for you. Key Takeaways Map Your Data: Maintain rigorous end-to-end documentation of all personal data flows to eliminate hidden shadow storage. Automate Requests: Build streamlined, automated workflows to handle Subject Access Requests well within regulatory deadlines. Practice Minimization: Collect only necessary data points and enforce strict retention schedules with automated purging. CTA (Join Techawks UK) Want to elevate your engineering standards and compliance practices alongside thousands of tech professionals across the United Kingdom? Join Techawks UK today to share governance patterns, tackle weekly engineering challenges, and build secure, trusted software together.
    0 Comentários 0 Compartilhamentos 234 Visualizações 0 Anterior
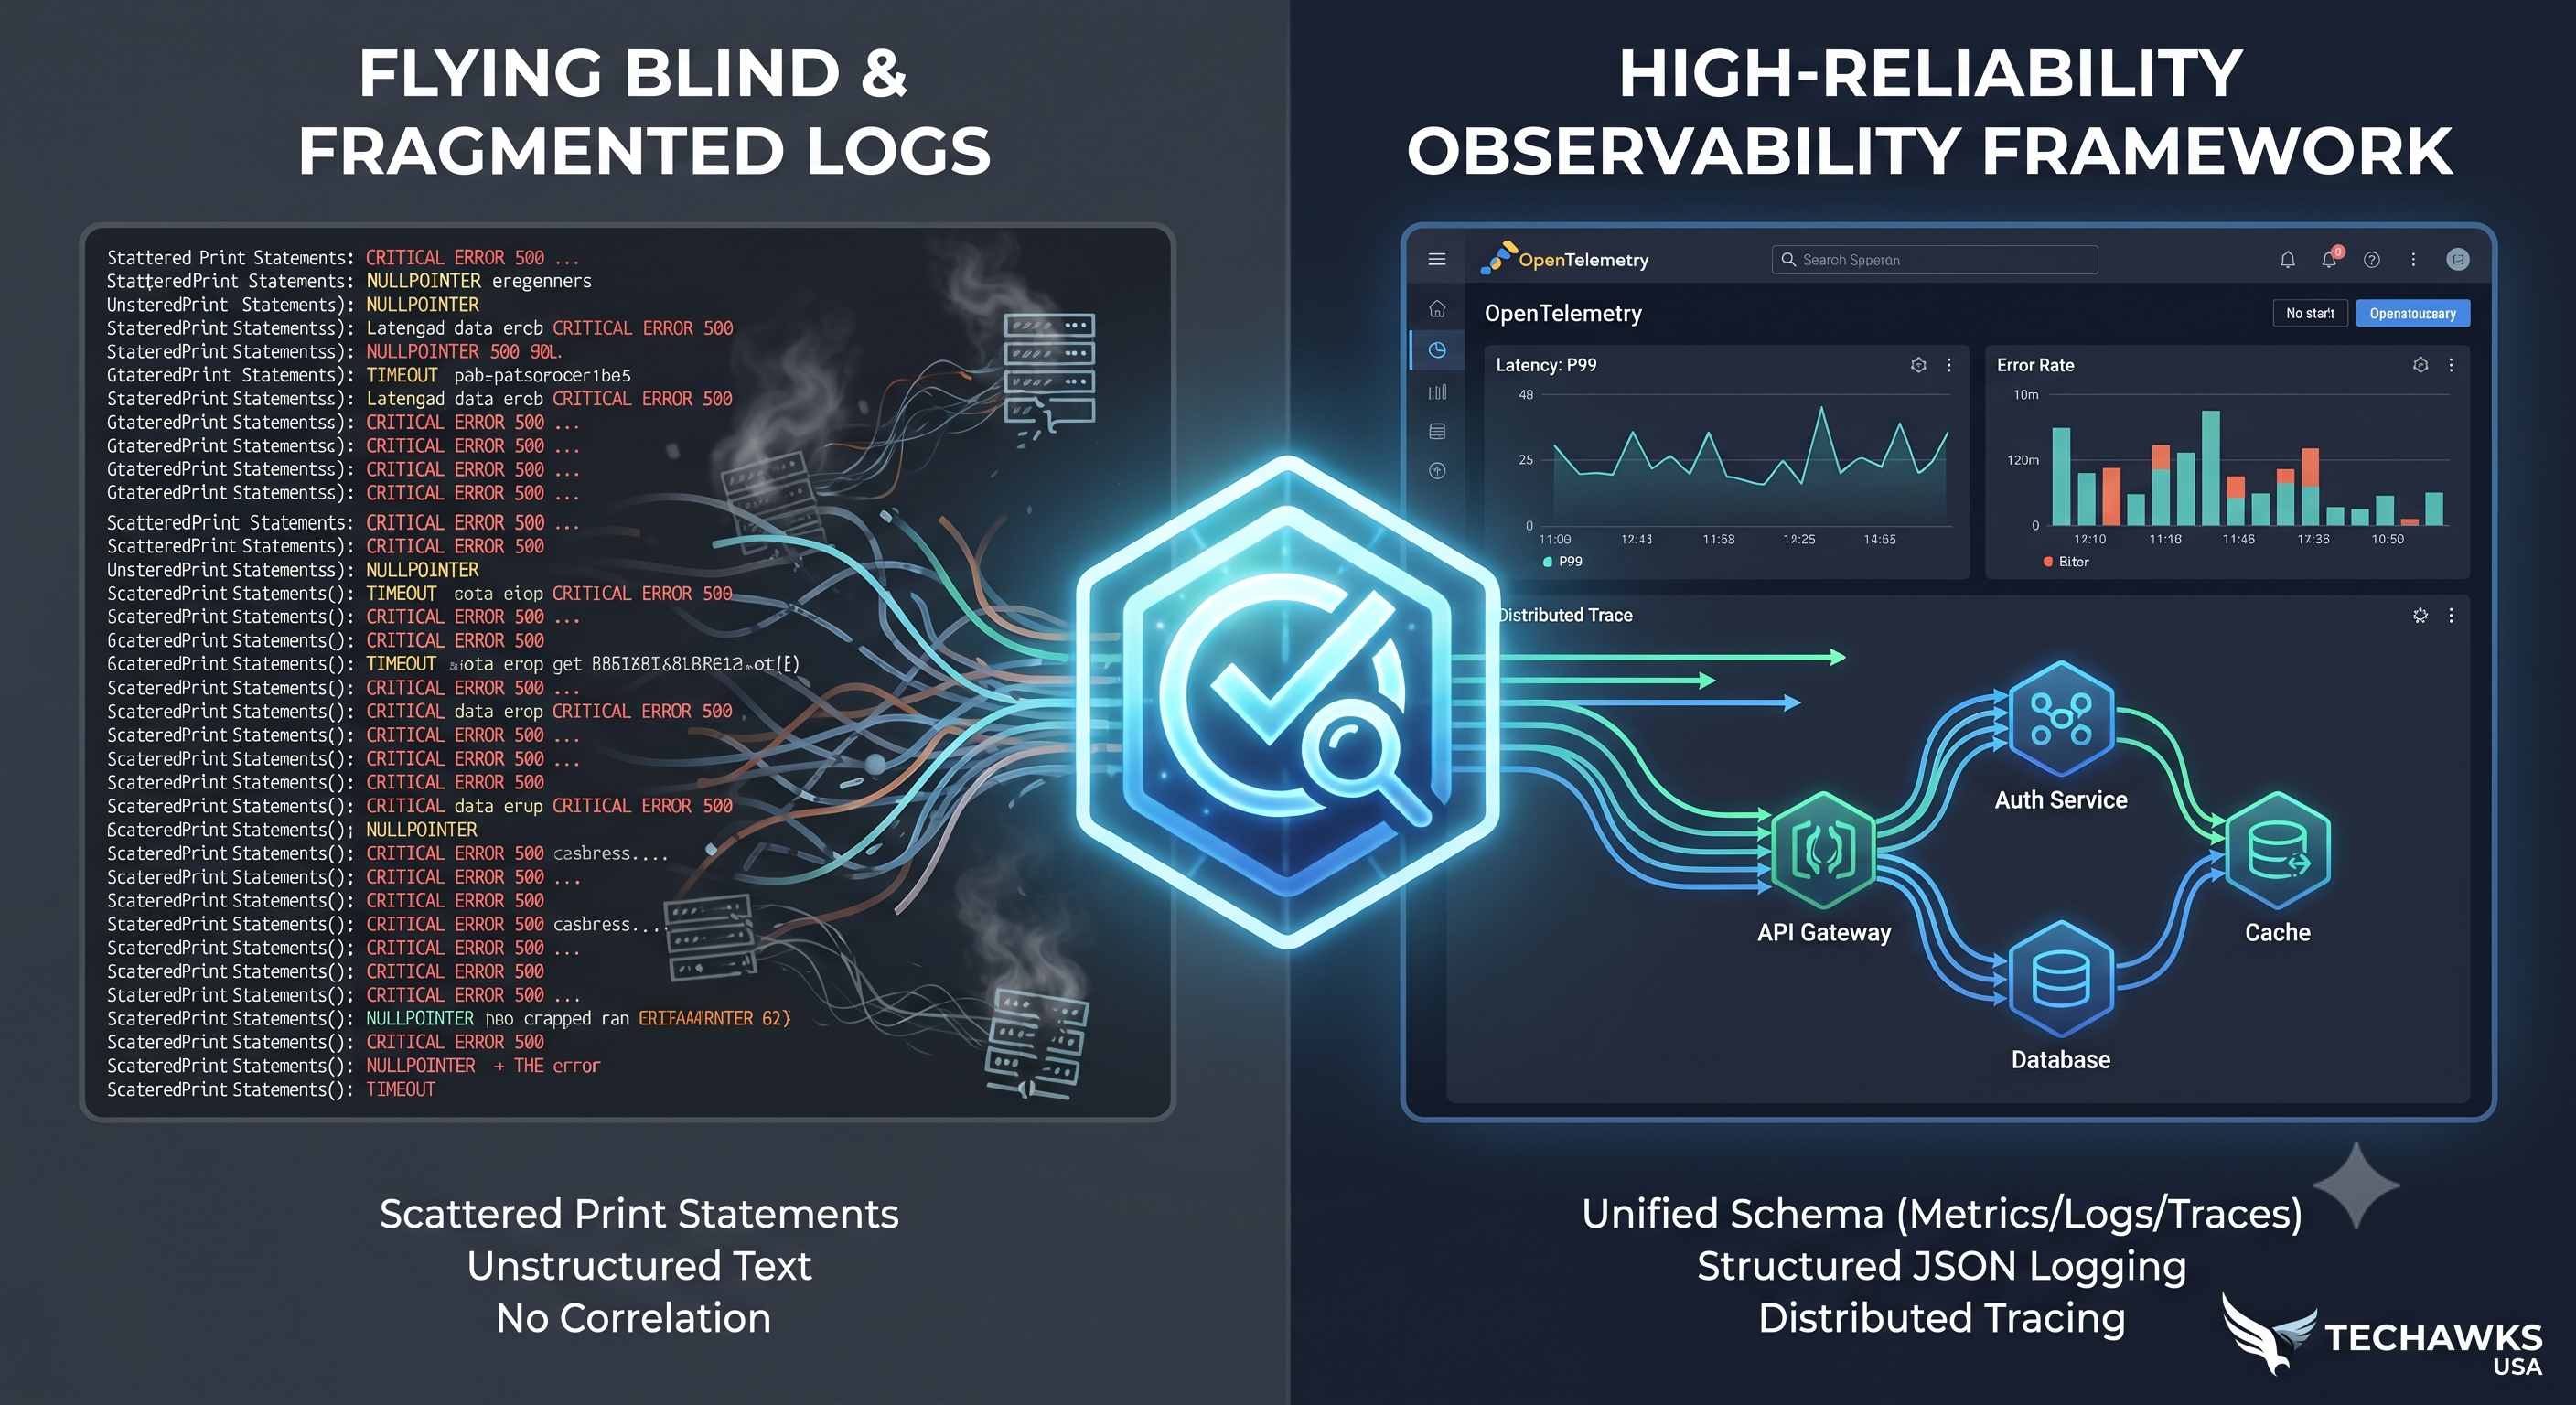
  • Stop Shipping Without Observability: The 3-Step Telemetry Framework for High-Reliability US Tech Systems


    We have all been there: staring at a generic 500 error screen, rushing to check disparate logs, metrics, and traces across multiple dashboards, and wishing you had better visibility into system state. While rapid feature delivery is essential, treating telemetry and monitoring as an afterthought leads to prolonged downtime and inflated incident response times.


    To transform naive logging practices into a robust, high-reliability operational framework suited for modern US tech engineering standards, put every service through this rigorous 3-step challenge framework:


    Step 1: The Unified OpenTelemetry Audit
    Scattered print statements and custom log formats create noise instead of insight. Before pushing any service live, standardize your instrumentation using OpenTelemetry to collect metrics, logs, and distributed traces under a single unified schema. Ask yourself: Can I trace a single user request seamlessly from the API gateway down to the database layer?


    Step 2: The Structured Logging & Context Propagation Check
    Unstructured text logs make automated querying and root-cause analysis nearly impossible during high-pressure incidents. Strip out plain-text strings, enforce strict JSON structured logging, and ensure unique correlation IDs and request contexts are propagated across every asynchronous worker and microservice boundary.


    Step 3: The Proactive Alerting & Threshold Optimization Pass
    Alert fatigue is real; if your team receives dozens of noisy alerts for trivial CPU spikes, they will eventually ignore the ones that actually matter. Strip out vanity metrics, focus your alerting thresholds strictly on customer-facing symptoms (like latency degradation and error rates rather than raw resource usage), and establish clear escalation runbooks.


    The Challenge for Today:
    Open your core application's recent error logs and trace histories. Pick one critical user transaction path and check if you can track it end-to-end within 60 seconds using your current monitoring tool. If you hit a blind spot, refactor your telemetry before your users experience an unmonitored failure.


    Key Takeaways
    Unify Your Telemetry: Standardize your metrics, logs, and traces using OpenTelemetry to eliminate fragmented monitoring.


    Enforce Structured Logging: Replace plain-text logs with structured JSON and propagate unique correlation IDs across all service boundaries.


    Focus Alerts on Impact: Tune alerts away from noisy resource metrics and focus strictly on customer-facing symptoms and actionable thresholds.


    CTA (Join Techawks USA)
    Want to elevate your system reliability and engineering practices alongside thousands of tech professionals across the United States? Join Techawks USA today to share observability patterns, tackle weekly engineering challenges, and build resilient systems together.
    Stop Shipping Without Observability: The 3-Step Telemetry Framework for High-Reliability US Tech Systems We have all been there: staring at a generic 500 error screen, rushing to check disparate logs, metrics, and traces across multiple dashboards, and wishing you had better visibility into system state. While rapid feature delivery is essential, treating telemetry and monitoring as an afterthought leads to prolonged downtime and inflated incident response times. To transform naive logging practices into a robust, high-reliability operational framework suited for modern US tech engineering standards, put every service through this rigorous 3-step challenge framework: Step 1: The Unified OpenTelemetry Audit Scattered print statements and custom log formats create noise instead of insight. Before pushing any service live, standardize your instrumentation using OpenTelemetry to collect metrics, logs, and distributed traces under a single unified schema. Ask yourself: Can I trace a single user request seamlessly from the API gateway down to the database layer? Step 2: The Structured Logging & Context Propagation Check Unstructured text logs make automated querying and root-cause analysis nearly impossible during high-pressure incidents. Strip out plain-text strings, enforce strict JSON structured logging, and ensure unique correlation IDs and request contexts are propagated across every asynchronous worker and microservice boundary. Step 3: The Proactive Alerting & Threshold Optimization Pass Alert fatigue is real; if your team receives dozens of noisy alerts for trivial CPU spikes, they will eventually ignore the ones that actually matter. Strip out vanity metrics, focus your alerting thresholds strictly on customer-facing symptoms (like latency degradation and error rates rather than raw resource usage), and establish clear escalation runbooks. The Challenge for Today: Open your core application's recent error logs and trace histories. Pick one critical user transaction path and check if you can track it end-to-end within 60 seconds using your current monitoring tool. If you hit a blind spot, refactor your telemetry before your users experience an unmonitored failure. Key Takeaways Unify Your Telemetry: Standardize your metrics, logs, and traces using OpenTelemetry to eliminate fragmented monitoring. Enforce Structured Logging: Replace plain-text logs with structured JSON and propagate unique correlation IDs across all service boundaries. Focus Alerts on Impact: Tune alerts away from noisy resource metrics and focus strictly on customer-facing symptoms and actionable thresholds. CTA (Join Techawks USA) Want to elevate your system reliability and engineering practices alongside thousands of tech professionals across the United States? Join Techawks USA today to share observability patterns, tackle weekly engineering challenges, and build resilient systems together.
    0 Comentários 0 Compartilhamentos 226 Visualizações 0 Anterior
Páginas Impulsionadas