• Scaling Beyond 16 Billion Transactions: Why Indian Engineering Teams Are Rethinking Asynchronous DPI Integration
    India’s Digital Public Infrastructure (DPI) operates at a concurrency scale unseen anywhere else globally—processing over 16 billion monthly UPI transactions alone, with thousands of public and private APIs exchanging real-time payloads.
    However, for Indian software engineers building fintech, logistics, and consumer tech platforms, interacting with state-level distributed protocols introduces a harsh reality: you do not control the upstream latency distribution.
    When an upstream payment service provider (PSP) or an open network protocol experiences an unexpected 800ms latency jitter during peak sales traffic, synchronous HTTP calls trigger three immediate failure cascades:
    Thread Starvation: Inbound connection pools get tied up waiting for upstream TCP socket responses, causing microservices to reject ordinary read queries.
    Amplified Retry Storms: Aggressive, naive client-side retries hit already degraded upstream bank switches, escalating a transient slowdown into an outright system outage.
    Divergent State Horizons: When an upstream API times out after 10 seconds, your system assumes a network failure while the banking switch actually commits the debit—leading to costly reconciliation mismatches.
    The Architectural Pattern: The Outbox-Worker Paradigm with Dynamic BackoffTo build resilient platforms on top of India Stack and open protocols (Beckn/ONDC), senior backend teams decouple client execution from gateway commits:
    Transactional Outbox + Idempotency Keys: Never invoke an external DPI API directly within a client-facing web request cycle. Write the transaction intent and payload atomically into an internal outbox table within the same database commit, keyed with an immutable idempotency_key (UUID v7/SHA-256 hash of order metadata).
    Decoupled Asynchronous Workers: Background queue consumers (Kafka, RabbitMQ) read outbox records and execute gateway network calls. If the gateway lags, downstream workers absorb the backpressure without blocking incoming client requests.Circuit Breakers with Jittered Exponential Backoff: Implement circuit breakers (e.g., resilience4j or custom Envoy filters) that trip immediately when upstream error rates cross 5%. When retrying, use full jitter:$$\text{Delay} = \text{random}(0, \min(M, B \times 2^{\text{attempt}}))$$This prevents synchronized "thundering herds" from battering recovery nodes.Webhook Re-conciliation Webhooks Over Polling: Rely primarily on signed asynchronous webhooks to transition states from PENDING to SUCCESS, backed by a periodic reconciliation cron strictly for abandoned sessions.Designing for the Indian tech ecosystem means designing for massive transaction volume and uneven network conditions. When you build with asynchronous resilience, your stack scales effortlessly alongside the country's digital rails.
    Discussion Question
    For engineers building on UPI, Account Aggregator, or ONDC: how does your platform handle upstream gateway timeouts without locking database connection pools or causing user double-debit panic?
    CTA
    Join Techawks India: Connect with top Indian software architects, backend engineers, and engineering leaders discussing large-scale distributed systems, India Stack architecture, and high-concurrency engineering. Link in bio/comments.
    Scaling Beyond 16 Billion Transactions: Why Indian Engineering Teams Are Rethinking Asynchronous DPI Integration India’s Digital Public Infrastructure (DPI) operates at a concurrency scale unseen anywhere else globally—processing over 16 billion monthly UPI transactions alone, with thousands of public and private APIs exchanging real-time payloads. However, for Indian software engineers building fintech, logistics, and consumer tech platforms, interacting with state-level distributed protocols introduces a harsh reality: you do not control the upstream latency distribution. When an upstream payment service provider (PSP) or an open network protocol experiences an unexpected 800ms latency jitter during peak sales traffic, synchronous HTTP calls trigger three immediate failure cascades: Thread Starvation: Inbound connection pools get tied up waiting for upstream TCP socket responses, causing microservices to reject ordinary read queries. Amplified Retry Storms: Aggressive, naive client-side retries hit already degraded upstream bank switches, escalating a transient slowdown into an outright system outage. Divergent State Horizons: When an upstream API times out after 10 seconds, your system assumes a network failure while the banking switch actually commits the debit—leading to costly reconciliation mismatches. The Architectural Pattern: The Outbox-Worker Paradigm with Dynamic BackoffTo build resilient platforms on top of India Stack and open protocols (Beckn/ONDC), senior backend teams decouple client execution from gateway commits: Transactional Outbox + Idempotency Keys: Never invoke an external DPI API directly within a client-facing web request cycle. Write the transaction intent and payload atomically into an internal outbox table within the same database commit, keyed with an immutable idempotency_key (UUID v7/SHA-256 hash of order metadata). Decoupled Asynchronous Workers: Background queue consumers (Kafka, RabbitMQ) read outbox records and execute gateway network calls. If the gateway lags, downstream workers absorb the backpressure without blocking incoming client requests.Circuit Breakers with Jittered Exponential Backoff: Implement circuit breakers (e.g., resilience4j or custom Envoy filters) that trip immediately when upstream error rates cross 5%. When retrying, use full jitter:$$\text{Delay} = \text{random}(0, \min(M, B \times 2^{\text{attempt}}))$$This prevents synchronized "thundering herds" from battering recovery nodes.Webhook Re-conciliation Webhooks Over Polling: Rely primarily on signed asynchronous webhooks to transition states from PENDING to SUCCESS, backed by a periodic reconciliation cron strictly for abandoned sessions.Designing for the Indian tech ecosystem means designing for massive transaction volume and uneven network conditions. When you build with asynchronous resilience, your stack scales effortlessly alongside the country's digital rails. Discussion Question For engineers building on UPI, Account Aggregator, or ONDC: how does your platform handle upstream gateway timeouts without locking database connection pools or causing user double-debit panic? CTA Join Techawks India: Connect with top Indian software architects, backend engineers, and engineering leaders discussing large-scale distributed systems, India Stack architecture, and high-concurrency engineering. Link in bio/comments.
    0 Commentaires 0 Parts 2 Vue 0 Aperçu
  • The Chatbot Interface Trap: Why Generative UI & Scaffolding Are Replacing the Text Box
    The conversational chatbot UI was a helpful transition bridge, but in enterprise workflows, a blank prompt input is one of the highest-friction interfaces ever designed.


    A blank text box forces users to confront the "Prompting Paradox":


    Users must guess what the underlying system is capable of doing.


    Users must guess the exact syntax or structure required to produce an accurate result.


    Users must manually review walls of unstructured markdown text to verify correctness.


    When an interface hides its functional boundaries behind a cursor, users don't feel empowered—they feel uncertain.


    Product managers and product designers are actively abandoning static chat overlays for Generative UI (GenUI) and Structured Scaffolding:


    1. Inverting Autonomy from "Chat" to "Staged Action Cards"
    Autonomous agents should never simply output conversational text stating what they did. Instead of: "I analyzed the dataset and can update your inventory levels," the interface should render a deterministic, interactive Action Preview Card.


    The card displays the precise database mutation payload, highlights affected records, and provides an editable preview with explicit Confirm, Edit, or Reject controls.


    Keep the human in the loop at the point of irreversible impact, not as an afterthought in chat text.


    2. Deterministic Component Rendering (Generative UI)
    Rather than streaming conversational paragraphs, modern agentic systems stream structured JSON to the client, which dynamically hydrates pre-built design system components (e.g., interactive data tables, comparison split-views, or multi-select filters).


    The AI dynamically orchestrates which components appear based on intent, but the components themselves obey strict design tokens, accessibility constraints, and deterministic click interactions.


    3. Progressive Disclosure Over Monolithic Output
    Do not dump multi-step agent reasoning logs into user-facing viewports. Expose high-level milestones by default (e.g., "Parsed 12 schemas ➔ Validated payment intent"), allowing curious power users to expand technical execution traces on demand.


    The goal of AI UX is not to simulate human conversation. The goal is to accelerate user intent while providing radical visibility, predictable recovery states, and zero-ambiguity control.


    Discussion Question
    For PMs and product designers shipping agentic and AI-native workflows: how is your team transitioning away from conversational text threads toward structured, dynamic UI components—and where have you encountered the biggest friction in your design systems?


    CTA
    Join Product, UX & Design: Connect with lead product managers, principal product designers, and design system architects mastering AI interaction patterns, Generative UI, and user experience strategy inside the Techawks Product & UX community. Link in bio/comments.
    The Chatbot Interface Trap: Why Generative UI & Scaffolding Are Replacing the Text Box The conversational chatbot UI was a helpful transition bridge, but in enterprise workflows, a blank prompt input is one of the highest-friction interfaces ever designed. A blank text box forces users to confront the "Prompting Paradox": Users must guess what the underlying system is capable of doing. Users must guess the exact syntax or structure required to produce an accurate result. Users must manually review walls of unstructured markdown text to verify correctness. When an interface hides its functional boundaries behind a cursor, users don't feel empowered—they feel uncertain. Product managers and product designers are actively abandoning static chat overlays for Generative UI (GenUI) and Structured Scaffolding: 1. Inverting Autonomy from "Chat" to "Staged Action Cards" Autonomous agents should never simply output conversational text stating what they did. Instead of: "I analyzed the dataset and can update your inventory levels," the interface should render a deterministic, interactive Action Preview Card. The card displays the precise database mutation payload, highlights affected records, and provides an editable preview with explicit Confirm, Edit, or Reject controls. Keep the human in the loop at the point of irreversible impact, not as an afterthought in chat text. 2. Deterministic Component Rendering (Generative UI) Rather than streaming conversational paragraphs, modern agentic systems stream structured JSON to the client, which dynamically hydrates pre-built design system components (e.g., interactive data tables, comparison split-views, or multi-select filters). The AI dynamically orchestrates which components appear based on intent, but the components themselves obey strict design tokens, accessibility constraints, and deterministic click interactions. 3. Progressive Disclosure Over Monolithic Output Do not dump multi-step agent reasoning logs into user-facing viewports. Expose high-level milestones by default (e.g., "Parsed 12 schemas ➔ Validated payment intent"), allowing curious power users to expand technical execution traces on demand. The goal of AI UX is not to simulate human conversation. The goal is to accelerate user intent while providing radical visibility, predictable recovery states, and zero-ambiguity control. Discussion Question For PMs and product designers shipping agentic and AI-native workflows: how is your team transitioning away from conversational text threads toward structured, dynamic UI components—and where have you encountered the biggest friction in your design systems? CTA Join Product, UX & Design: Connect with lead product managers, principal product designers, and design system architects mastering AI interaction patterns, Generative UI, and user experience strategy inside the Techawks Product & UX community. Link in bio/comments.
    0 Commentaires 0 Parts 6 Vue 0 Aperçu
  • The Lakehouse Reality Check: Why Adopting Apache Iceberg Fails Without Manifest Pruning and Unified Semantic Modeling
    The enterprise migration to open table formats (Apache Iceberg, Delta Lake) has decoupled storage from compute across Snowflake, Databricks, BigQuery, and Trino. Storing raw parquet files on object storage while maintaining ACID transactions, snapshot isolation, and schema evolution provides immense architectural flexibility.


    However, running production analytics on an open lakehouse introduces two critical failure modes that traditional managed data warehouses historically abstracted away:


    1. The Manifest Tree Explosion & Position Delete Bloat
    An Iceberg table is not a single directory of Parquet files; it is a hierarchical tree of metadata.json, Avro manifest lists, Avro manifests, and data/delete files.


    The Micro-Batch Trap: When streaming ingestion tools (such as Kafka or Flink) commit micro-batches every 30 to 60 seconds, they generate thousands of tiny Parquet files and corresponding metadata commits.


    The Consequence: During query planning, query engines spend 80% of their execution time walking deep metadata trees and applying row-level position deletes rather than scanning actual columnar data.


    The Engineering Fix: Automated compaction maintenance is non-negotiable. Schedule atomic file rewrites (REWRITE DATA FILES) with bin-packing or Z-order sorting, alongside orphan file cleanup and snapshot expiration to keep metadata evaluation sub-second.


    2. The Semantic Modeling Vacuum
    Decoupling storage from query engines creates an immediate governance crisis. When StarRocks, DuckDB, Trino, and warehouse engines simultaneously query the same Iceberg tables, business logic fragments.


    If "active revenue" or "churned user" is defined in one BI tool's SQL view and recalculated differently in an AI agent's prompt context, analytics trust collapses.


    The Shift to Centralized Semantic Layers: You cannot leave metric definitions inside distributed SQL queries. Metric definitions must reside in a centralized semantic layer (e.g., dbt semantic layer, Cube) that sits between the open table catalog and downstream consumers. Every query engine, dashboard, and autonomous AI pipeline must pull definitions from a single immutable contract.


    Open table formats solve vendor lock-in, but metadata hygiene and semantic modeling determine whether your lakehouse actually delivers high-throughput analytical value.


    Discussion Question
    For analytics and data platform engineers operating on Iceberg or open lakehouse architectures: how frequently do you run automated manifest compaction, and has your team successfully centralized metrics in a semantic layer or do business definitions still leak into BI-specific SQL views?


    CTA
    Join Data Science & Analytics: Connect with lead data architects, analytics engineers, and data platform specialists discussing modern lakehouse architectures, open table governance, and high-performance querying inside the Techawks Data & Analytics community. Link in bio/comments.
    The Lakehouse Reality Check: Why Adopting Apache Iceberg Fails Without Manifest Pruning and Unified Semantic Modeling The enterprise migration to open table formats (Apache Iceberg, Delta Lake) has decoupled storage from compute across Snowflake, Databricks, BigQuery, and Trino. Storing raw parquet files on object storage while maintaining ACID transactions, snapshot isolation, and schema evolution provides immense architectural flexibility. However, running production analytics on an open lakehouse introduces two critical failure modes that traditional managed data warehouses historically abstracted away: 1. The Manifest Tree Explosion & Position Delete Bloat An Iceberg table is not a single directory of Parquet files; it is a hierarchical tree of metadata.json, Avro manifest lists, Avro manifests, and data/delete files. The Micro-Batch Trap: When streaming ingestion tools (such as Kafka or Flink) commit micro-batches every 30 to 60 seconds, they generate thousands of tiny Parquet files and corresponding metadata commits. The Consequence: During query planning, query engines spend 80% of their execution time walking deep metadata trees and applying row-level position deletes rather than scanning actual columnar data. The Engineering Fix: Automated compaction maintenance is non-negotiable. Schedule atomic file rewrites (REWRITE DATA FILES) with bin-packing or Z-order sorting, alongside orphan file cleanup and snapshot expiration to keep metadata evaluation sub-second. 2. The Semantic Modeling Vacuum Decoupling storage from query engines creates an immediate governance crisis. When StarRocks, DuckDB, Trino, and warehouse engines simultaneously query the same Iceberg tables, business logic fragments. If "active revenue" or "churned user" is defined in one BI tool's SQL view and recalculated differently in an AI agent's prompt context, analytics trust collapses. The Shift to Centralized Semantic Layers: You cannot leave metric definitions inside distributed SQL queries. Metric definitions must reside in a centralized semantic layer (e.g., dbt semantic layer, Cube) that sits between the open table catalog and downstream consumers. Every query engine, dashboard, and autonomous AI pipeline must pull definitions from a single immutable contract. Open table formats solve vendor lock-in, but metadata hygiene and semantic modeling determine whether your lakehouse actually delivers high-throughput analytical value. Discussion Question For analytics and data platform engineers operating on Iceberg or open lakehouse architectures: how frequently do you run automated manifest compaction, and has your team successfully centralized metrics in a semantic layer or do business definitions still leak into BI-specific SQL views? CTA Join Data Science & Analytics: Connect with lead data architects, analytics engineers, and data platform specialists discussing modern lakehouse architectures, open table governance, and high-performance querying inside the Techawks Data & Analytics community. Link in bio/comments.
    0 Commentaires 0 Parts 13 Vue 0 Aperçu
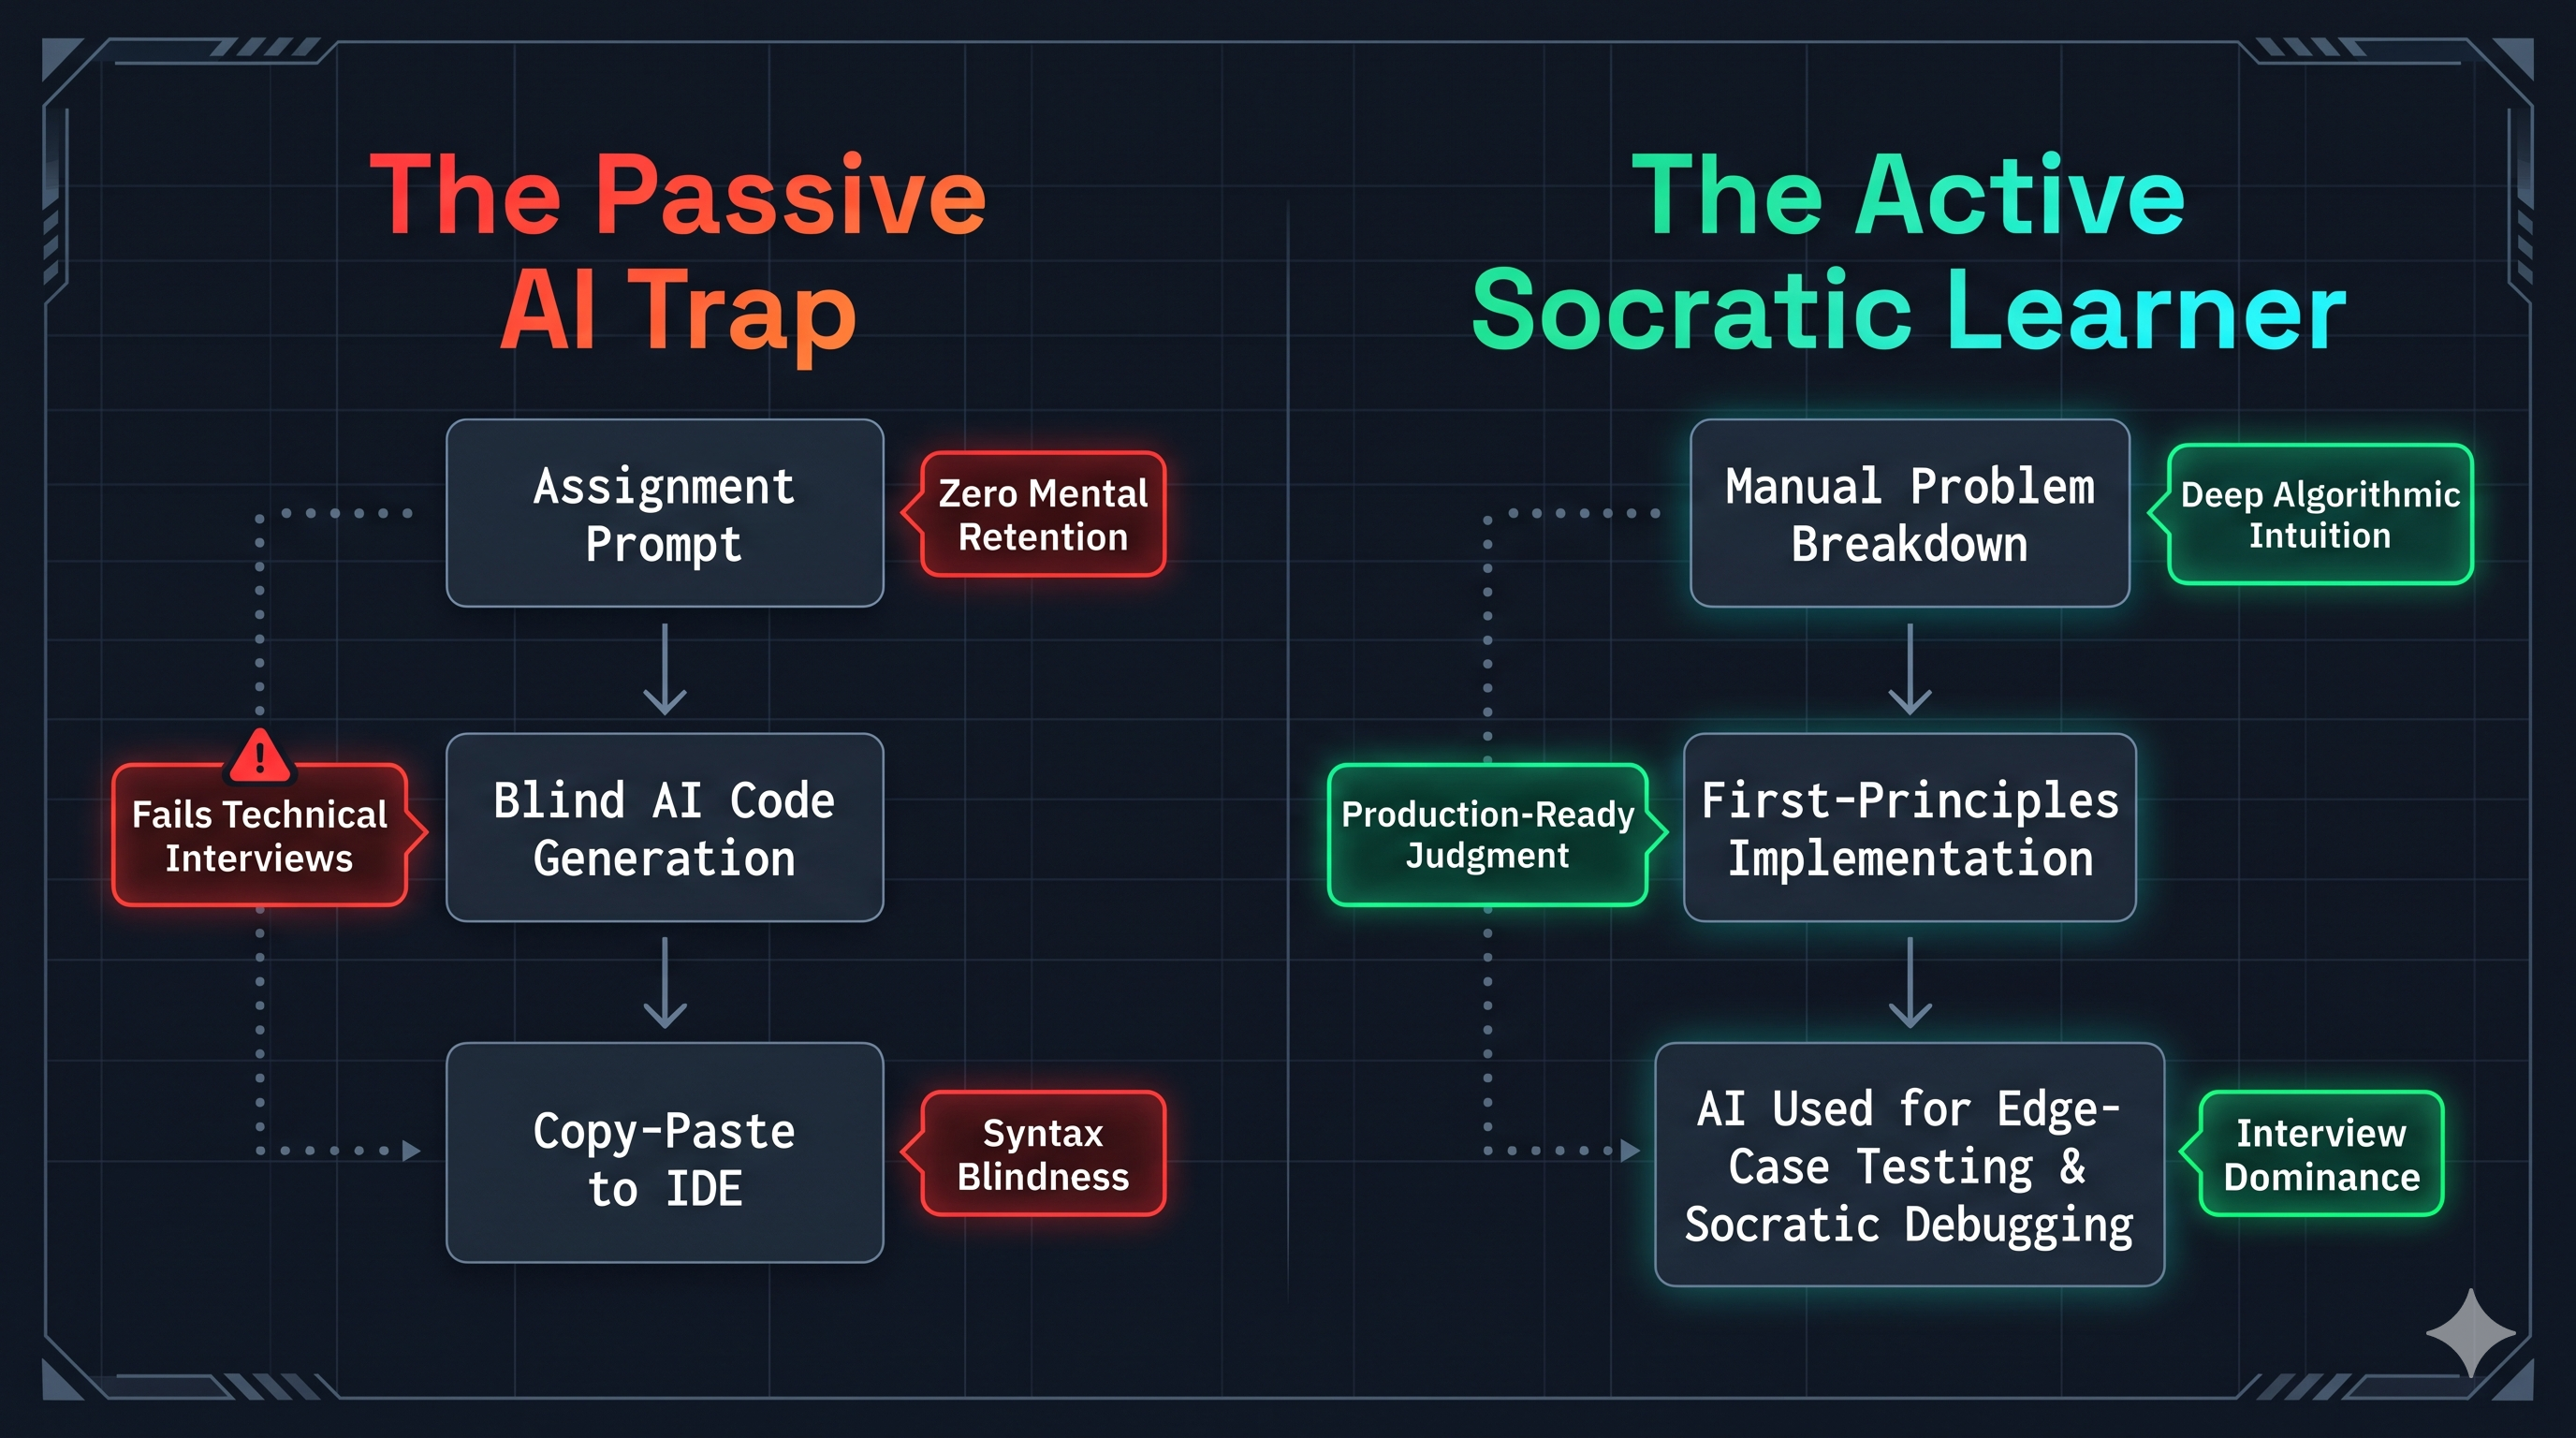
  • The "Vibe-Coding" Trap: Why Relying on AI Generators Is Silently Sabotaging Computer Science Students
    With AI coding assistants capable of generating boilerplate apps in seconds, tech students are falling into a deceptive learning illusion: the illusion of competence.
    When an AI outputs working code, reading it creates a false sense of understanding.
    But software engineering is not reading; it is mental modeling, fault tracing, and architectural reasoning.
    Students who skip the friction of debugging and problem decomposition will face a brutal reality during technical interviews and production internships:
    The Inability to Debug Edge Cases:
    When an AI model hallucinates a race condition or an off-by-one pointer error, a developer without core algorithmic grounding cannot locate the failure mode.
    Mental Atrophy in Algorithmic Decomposition: Breaking a nebulous problem into data structures, time complexity ($O(n)$) constraints, and edge boundaries is a muscle built solely through iterative trial and error.
    Zero Architectural Ownership: If you didn't decide why an array was picked over a hash map, you cannot defend the trade-off when latency spikes under concurrency.
    The Learning Rule: AI as the Socratic Tutor, Not the Code GhostwriterTo graduate as an elite engineer in an AI-accelerated world, invert how you use developer assistants:
    Ban Direct Solution Prompting:
    Never prompt an LLM with "Write a Python script to implement Dijkstra's algorithm." Instead, write your implementation first, then prompt: "Review my Dijkstra implementation. What are two edge-case inputs that will break my termination condition?
    "Reverse Code Dissection: If you run into unfamiliar syntax or an opaque library method, ask the model to explain the underlying memory allocation or call-stack behavior rather than copying it wholesale.
    Master the Primitives First: Operating systems, computer networks, and discrete mathematics cannot be bypassed.
    The less code you have to write manually in the future, the more critical it becomes to deeply understand how memory, compilers, and hardware communicate.
    AI will commoditize syntax generators. It will never commoditize the computer science fundamentals required to evaluate and architect mission-critical software.
    Discussion Question
    For tech students and recent grads: how do you draw the line when using AI tools for your coursework—do you use them as an interactive tutor, or have they become an automatic shortcut to get assignments done?
    CTA
    Join Students in Tech: Connect with fellow computer science students, get mentored by senior software engineers, and master fundamental software engineering concepts inside the Techawks Students community. Link in bio/comments.
    The "Vibe-Coding" Trap: Why Relying on AI Generators Is Silently Sabotaging Computer Science Students With AI coding assistants capable of generating boilerplate apps in seconds, tech students are falling into a deceptive learning illusion: the illusion of competence. When an AI outputs working code, reading it creates a false sense of understanding. But software engineering is not reading; it is mental modeling, fault tracing, and architectural reasoning. Students who skip the friction of debugging and problem decomposition will face a brutal reality during technical interviews and production internships: The Inability to Debug Edge Cases: When an AI model hallucinates a race condition or an off-by-one pointer error, a developer without core algorithmic grounding cannot locate the failure mode. Mental Atrophy in Algorithmic Decomposition: Breaking a nebulous problem into data structures, time complexity ($O(n)$) constraints, and edge boundaries is a muscle built solely through iterative trial and error. Zero Architectural Ownership: If you didn't decide why an array was picked over a hash map, you cannot defend the trade-off when latency spikes under concurrency. The Learning Rule: AI as the Socratic Tutor, Not the Code GhostwriterTo graduate as an elite engineer in an AI-accelerated world, invert how you use developer assistants: Ban Direct Solution Prompting: Never prompt an LLM with "Write a Python script to implement Dijkstra's algorithm." Instead, write your implementation first, then prompt: "Review my Dijkstra implementation. What are two edge-case inputs that will break my termination condition? "Reverse Code Dissection: If you run into unfamiliar syntax or an opaque library method, ask the model to explain the underlying memory allocation or call-stack behavior rather than copying it wholesale. Master the Primitives First: Operating systems, computer networks, and discrete mathematics cannot be bypassed. The less code you have to write manually in the future, the more critical it becomes to deeply understand how memory, compilers, and hardware communicate. AI will commoditize syntax generators. It will never commoditize the computer science fundamentals required to evaluate and architect mission-critical software. Discussion Question For tech students and recent grads: how do you draw the line when using AI tools for your coursework—do you use them as an interactive tutor, or have they become an automatic shortcut to get assignments done? CTA Join Students in Tech: Connect with fellow computer science students, get mentored by senior software engineers, and master fundamental software engineering concepts inside the Techawks Students community. Link in bio/comments.
    0 Commentaires 0 Parts 13 Vue 0 Aperçu
  • The 80% SaaS Margin Era Is Dead: Why Unit-Economics-First Founders Are Winning Seed & Series A
    For nearly two decades, traditional software thrived on near-zero marginal cost: build the product once, serve the next million users for pennies on the dollar, and bank 75% to 85% gross margins.


    That playbook has officially expired.


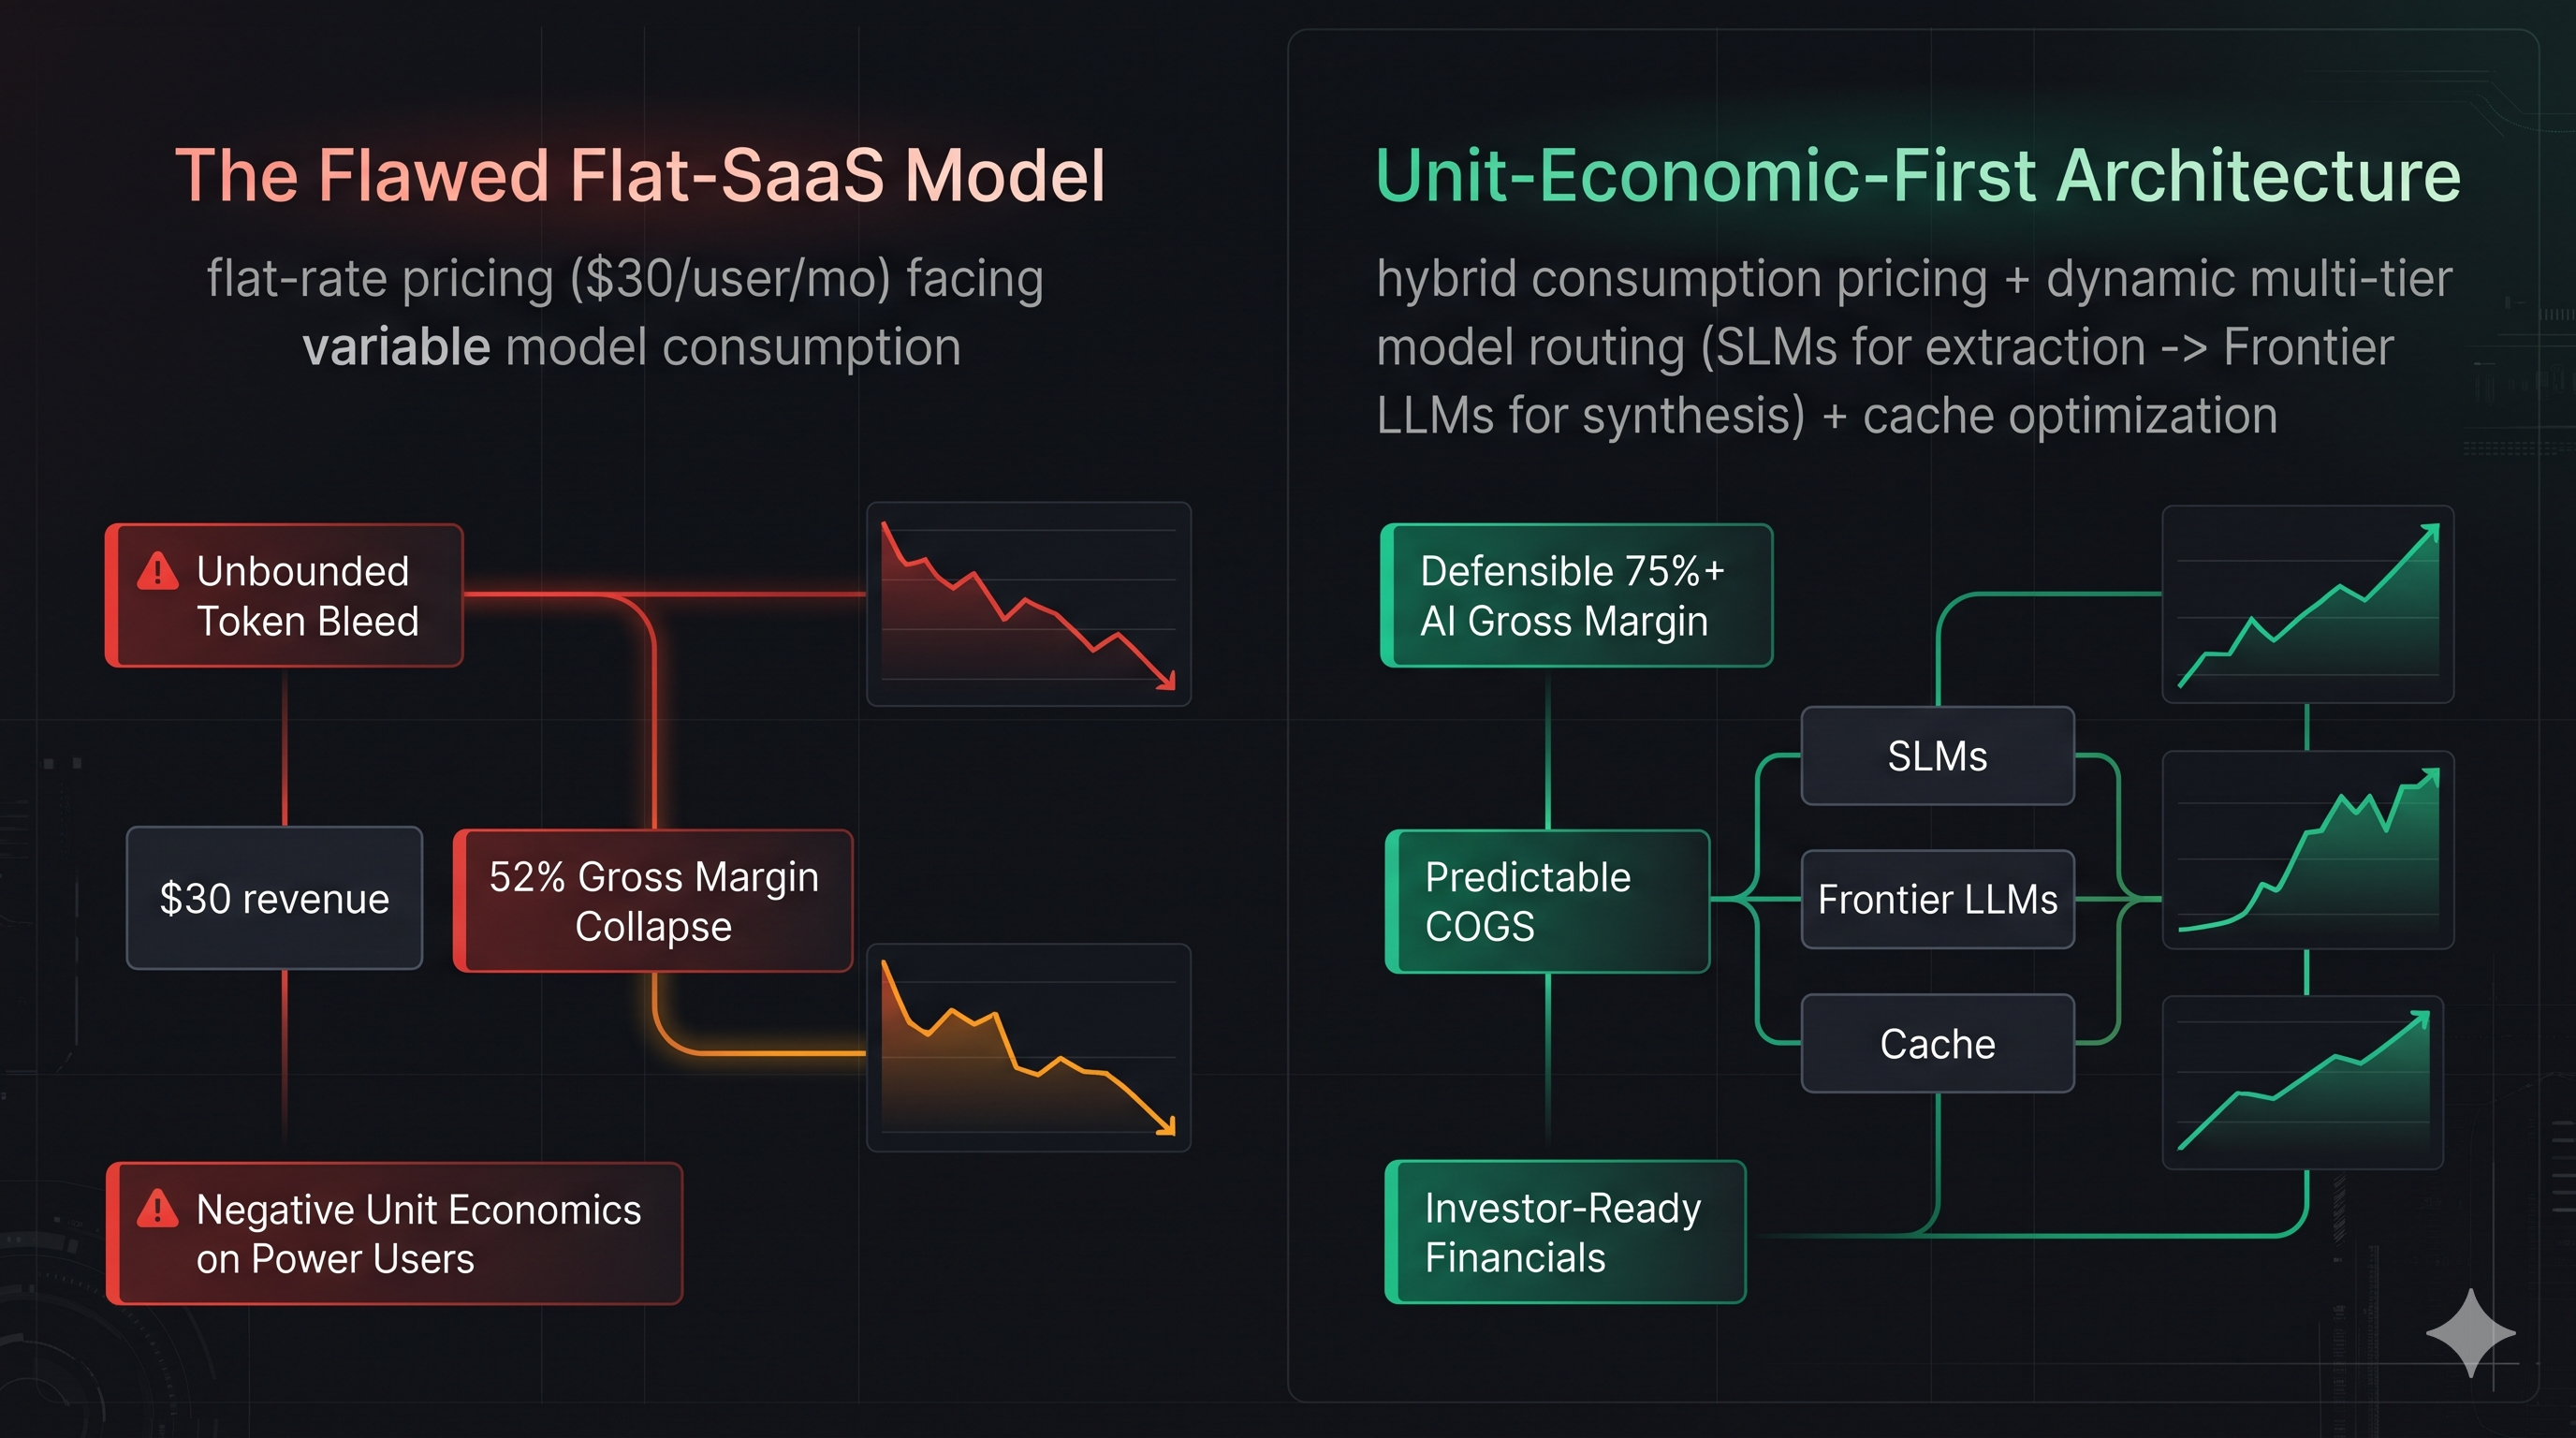
    Industry benchmarks reveal that average gross margins for AI software products hover between 50% and 53%—and in uncontrolled agentic applications, margins can plunge below 30%.


    The cause is not poor product-market fit; it is untracked variable COGS. In an AI-native stack, model inference, vector database lookups, self-critique loops, and recursive tool calls are not operational expenses—they are direct Costs of Goods Sold (COGS). When a heavy user triggers an autonomous workflow that makes 15 calls to resolve a query, a flat $30/month seat fee quietly turns into a money-losing account.


    Founders raising institutional rounds today are being evaluated on AI-Adjusted Gross Margin and unit defensibility. Here is how top-tier founders protect their margin profile:


    Decouple Billing from Flat Seats to Hybrid Consumption: Eliminate all-inclusive flat enterprise tiers for autonomous features. Shift to hybrid models: base platform access + metered credit allowances with automatic usage-based overages.


    Implement Dynamic Inference Routing: Never send a classification, extraction, or summarization task to a flagship frontier model. Route 70%+ of standard utility tasks through specialized, small language models (SLMs) or quantized local endpoints, reserving high-tier reasoning engines strictly for complex multi-hop tasks.


    Audit Per-Cohort Marginal Cost: Stop relying on blended platform-wide compute averages. Track unit margins per customer and per feature. If your top 5% power users are responsible for 60% of your inference spend, your pricing model has a structural leak.


    Vanity ARR will get you upvotes; unit-economic discipline gets your company funded and keeps it solvent.


    Discussion Question
    For founders running AI products: have you shifted from flat-rate pricing to hybrid usage/outcome-based billing, and what has been the customer pushback during contract negotiations?


    CTA
    Join Startup Founders & Entrepreneurs: Discuss unit economics, pricing architecture, go-to-market strategies, and fundraising playbooks with active venture-backed founders inside the Techawks Startups community. Link in bio/comments.
    The 80% SaaS Margin Era Is Dead: Why Unit-Economics-First Founders Are Winning Seed & Series A For nearly two decades, traditional software thrived on near-zero marginal cost: build the product once, serve the next million users for pennies on the dollar, and bank 75% to 85% gross margins. That playbook has officially expired. Industry benchmarks reveal that average gross margins for AI software products hover between 50% and 53%—and in uncontrolled agentic applications, margins can plunge below 30%. The cause is not poor product-market fit; it is untracked variable COGS. In an AI-native stack, model inference, vector database lookups, self-critique loops, and recursive tool calls are not operational expenses—they are direct Costs of Goods Sold (COGS). When a heavy user triggers an autonomous workflow that makes 15 calls to resolve a query, a flat $30/month seat fee quietly turns into a money-losing account. Founders raising institutional rounds today are being evaluated on AI-Adjusted Gross Margin and unit defensibility. Here is how top-tier founders protect their margin profile: Decouple Billing from Flat Seats to Hybrid Consumption: Eliminate all-inclusive flat enterprise tiers for autonomous features. Shift to hybrid models: base platform access + metered credit allowances with automatic usage-based overages. Implement Dynamic Inference Routing: Never send a classification, extraction, or summarization task to a flagship frontier model. Route 70%+ of standard utility tasks through specialized, small language models (SLMs) or quantized local endpoints, reserving high-tier reasoning engines strictly for complex multi-hop tasks. Audit Per-Cohort Marginal Cost: Stop relying on blended platform-wide compute averages. Track unit margins per customer and per feature. If your top 5% power users are responsible for 60% of your inference spend, your pricing model has a structural leak. Vanity ARR will get you upvotes; unit-economic discipline gets your company funded and keeps it solvent. Discussion Question For founders running AI products: have you shifted from flat-rate pricing to hybrid usage/outcome-based billing, and what has been the customer pushback during contract negotiations? CTA Join Startup Founders & Entrepreneurs: Discuss unit economics, pricing architecture, go-to-market strategies, and fundraising playbooks with active venture-backed founders inside the Techawks Startups community. Link in bio/comments.
    0 Commentaires 0 Parts 13 Vue 0 Aperçu
  • The Death of the LeetCode Grind: Why "Code Review & Trade-off Defense" Is the New Technical Interview Bar
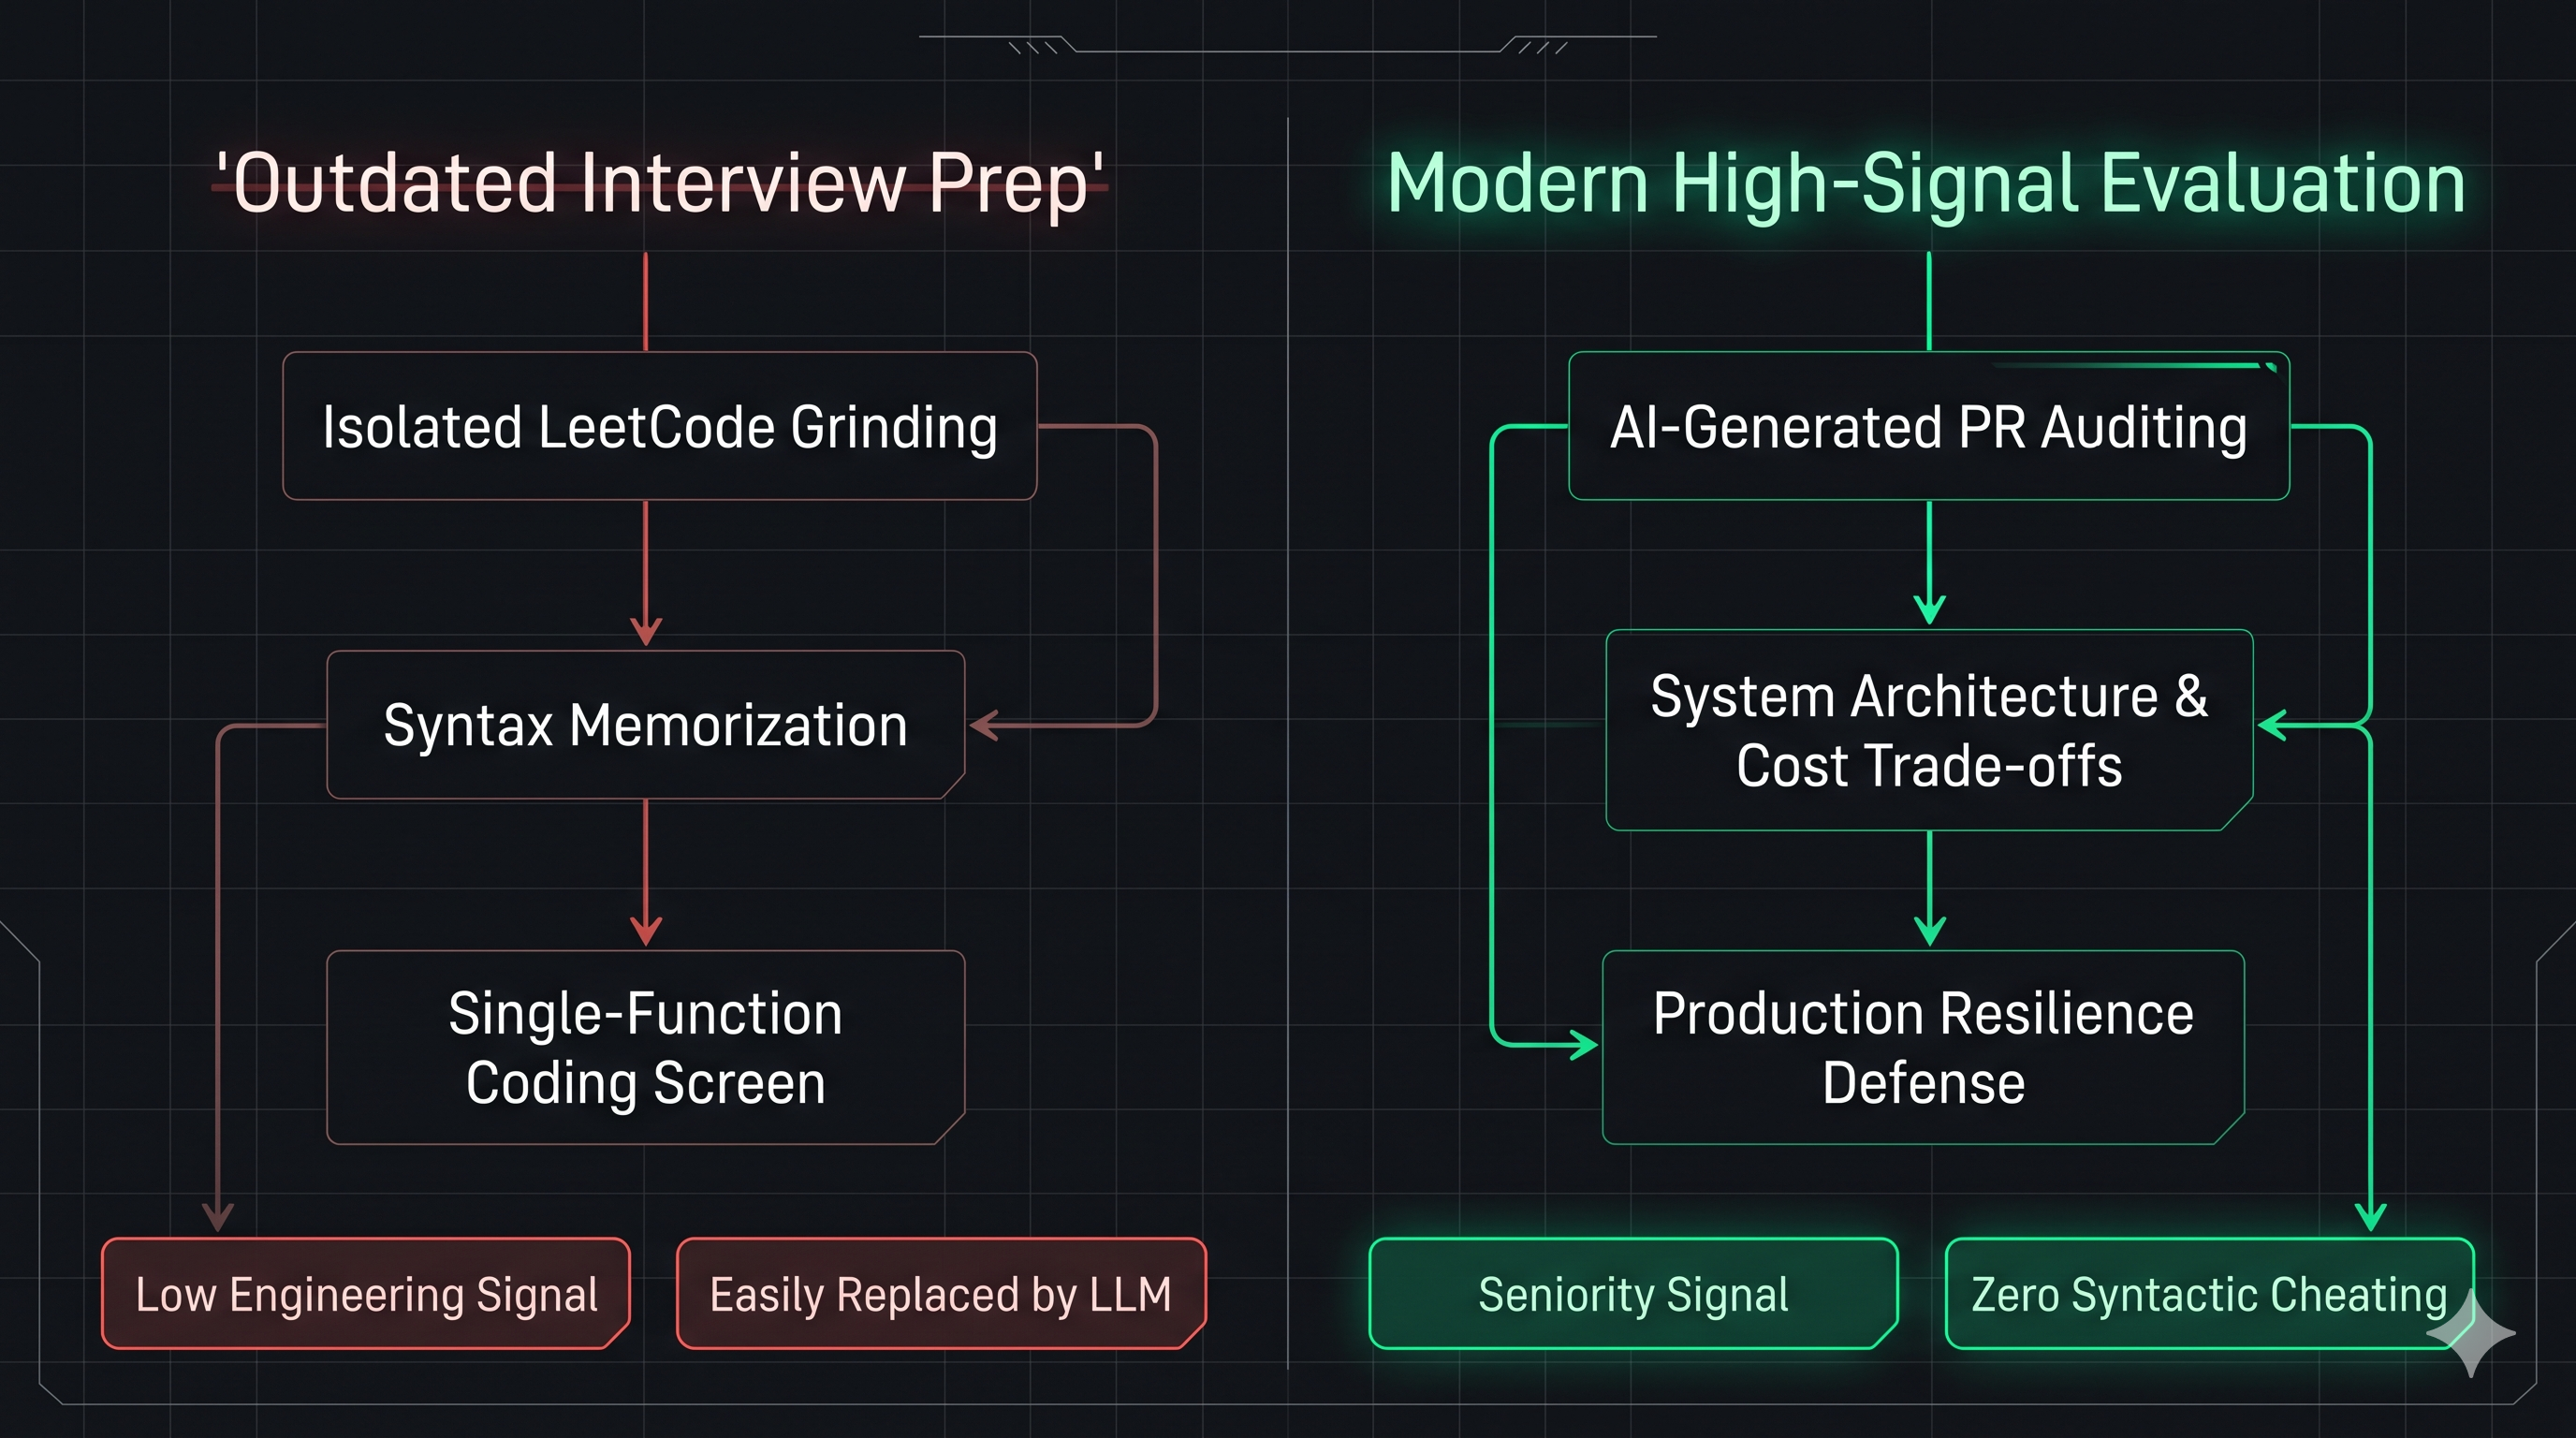
    With over 80% of professional developers actively pairing with AI coding assistants and agentic IDEs, writing syntactically correct boilerplate is no longer a differentiator. Engineering teams already know an LLM can invert a binary tree or write an unoptimized CRUD endpoint in 1.2 seconds.


    What engineering leaders actually struggle with right now is evaluating judgment.


    Technical interview loops across top-tier tech companies are aggressively pivoting away from isolated coding screens toward two new assessment formats:


    The AI-Generated PR Review Screen: Instead of starting from a blank editor, candidates are handed a 400-line pull request produced by an agent or LLM containing subtle concurrency bugs, silent data mutations, and unhandled edge cases. Interviewers aren’t checking if you can write syntax—they are checking if you can catch what AI misses.


    System Design & Cost-Aware Trade-off Defense: System design rounds have expanded from senior staff roles down into mid-level evaluations. Teams evaluate whether you can justify state boundaries, database consistency models, telemetry, and compute cost ceilings under real traffic constraints.


    How to Pivot Your Career Preparation:
    Shift from Memorization to Debugging: Practice opening open-source pull requests and auditing them for race conditions, memory leaks, and leaky abstractions. Articulating why an implementation will degrade under load carries 5x more signal than rewriting it from scratch.


    Defend Architectural Trade-offs Out Loud: Don't just recommend an architectural pattern (e.g., Redis caching or an event-driven queue). State the exact trade-off upfront: "We gain sub-10ms read latency, but we introduce cache invalidation complexity and transient eventual consistency risk."


    Demonstrate AI Orchestration, Not Avoidance: Interviewers respect candidates who know how to prompt, steer, and sanity-check LLM outputs while catching security and architecture pitfalls before merge.


    In modern engineering hiring, you aren't evaluated on whether you can out-code the model. You are evaluated on whether you have the technical seniority to guide, audit, and take ownership of what gets deployed to production.


    Discussion Question
    For engineers currently interviewing or hiring managers running loops: what interview format has given you the clearest signal of a candidate's actual day-one engineering judgment?


    CTA
    Join Tech Jobs & Opportunities: Connect with senior hiring managers, access vetted job referrals, and master modern interview strategies inside the Techawks Careers community. Link in bio/comments.
    The Death of the LeetCode Grind: Why "Code Review & Trade-off Defense" Is the New Technical Interview Bar With over 80% of professional developers actively pairing with AI coding assistants and agentic IDEs, writing syntactically correct boilerplate is no longer a differentiator. Engineering teams already know an LLM can invert a binary tree or write an unoptimized CRUD endpoint in 1.2 seconds. What engineering leaders actually struggle with right now is evaluating judgment. Technical interview loops across top-tier tech companies are aggressively pivoting away from isolated coding screens toward two new assessment formats: The AI-Generated PR Review Screen: Instead of starting from a blank editor, candidates are handed a 400-line pull request produced by an agent or LLM containing subtle concurrency bugs, silent data mutations, and unhandled edge cases. Interviewers aren’t checking if you can write syntax—they are checking if you can catch what AI misses. System Design & Cost-Aware Trade-off Defense: System design rounds have expanded from senior staff roles down into mid-level evaluations. Teams evaluate whether you can justify state boundaries, database consistency models, telemetry, and compute cost ceilings under real traffic constraints. How to Pivot Your Career Preparation: Shift from Memorization to Debugging: Practice opening open-source pull requests and auditing them for race conditions, memory leaks, and leaky abstractions. Articulating why an implementation will degrade under load carries 5x more signal than rewriting it from scratch. Defend Architectural Trade-offs Out Loud: Don't just recommend an architectural pattern (e.g., Redis caching or an event-driven queue). State the exact trade-off upfront: "We gain sub-10ms read latency, but we introduce cache invalidation complexity and transient eventual consistency risk." Demonstrate AI Orchestration, Not Avoidance: Interviewers respect candidates who know how to prompt, steer, and sanity-check LLM outputs while catching security and architecture pitfalls before merge. In modern engineering hiring, you aren't evaluated on whether you can out-code the model. You are evaluated on whether you have the technical seniority to guide, audit, and take ownership of what gets deployed to production. Discussion Question For engineers currently interviewing or hiring managers running loops: what interview format has given you the clearest signal of a candidate's actual day-one engineering judgment? CTA Join Tech Jobs & Opportunities: Connect with senior hiring managers, access vetted job referrals, and master modern interview strategies inside the Techawks Careers community. Link in bio/comments.
    0 Commentaires 0 Parts 13 Vue 0 Aperçu
  • Stop Leaking Unchecked Exceptions: How to Build Bulletproof APIs with the Result Pattern in TypeScript
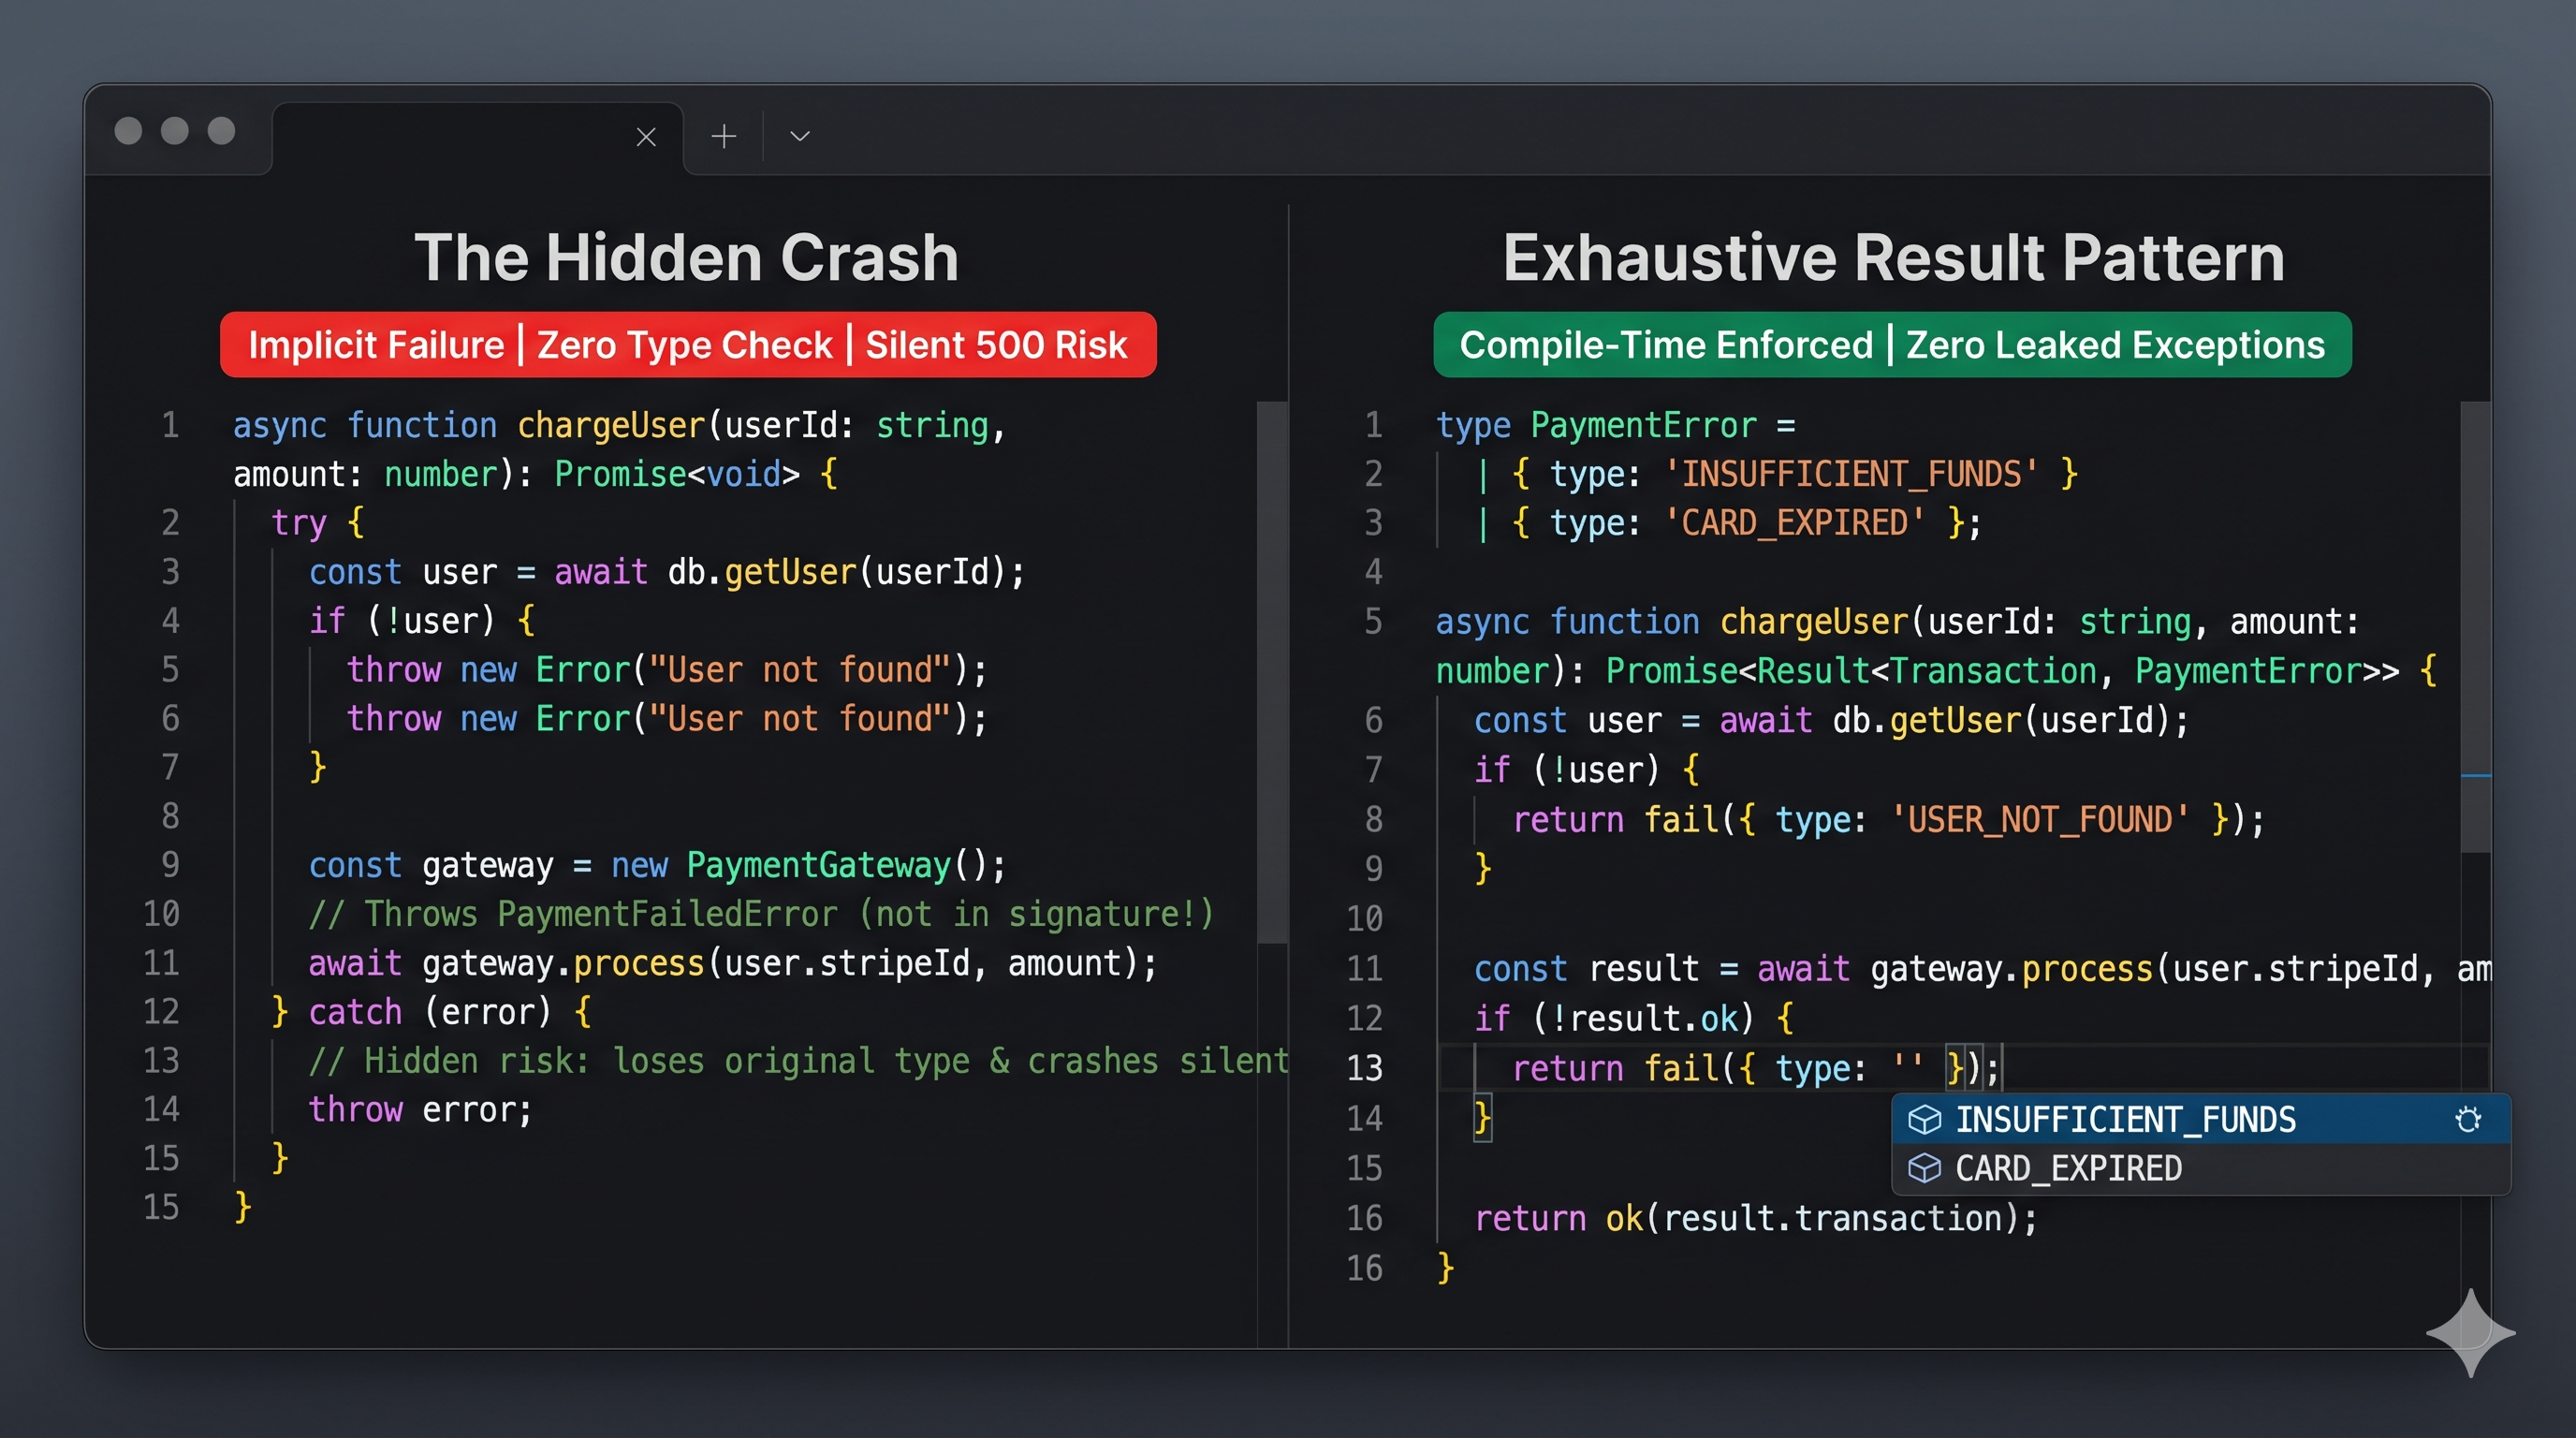
    Throwing exceptions for expected domain failures (e.g., validation errors, expired sessions, or resource conflicts) violates one of software engineering's most fundamental tenets: type safety across execution boundaries.


    When a function signatures looks like this:


    TypeScript
    async function processOrder(orderId: string): Promise<Order>
    The TypeScript compiler has no idea what could go wrong. It forces consumers to guess what exceptions need catching, resulting in swallowed errors, missing fallback states, and unexpected 500 HTTP crashes.


    The Architectural Shift: Explicit Error Modeling
    Languages like Rust make failure paths explicit at the type level using the Result<T, E> algebraic data type. You can implement this cleanly in modern TypeScript without external dependencies using discriminated unions:


    TypeScript
    type Result<T, E = Error> =
    | { success: true; data: T }
    | { success: false; error: E };


    // Define discrete, exhaustive error states
    type PaymentError =
    | { code: 'INSUFFICIENT_FUNDS'; balance: number }
    | { code: 'CARD_EXPIRED' }
    | { code: 'GATEWAY_TIMEOUT' };


    async function chargeCard(amount: number): Promise<Result<Transaction, PaymentError>> {
    if (amount > availableFunds) {
    return {
    success: false,
    error: { code: 'INSUFFICIENT_FUNDS', balance: availableFunds }
    };
    }
    // ... execute charge
    return { success: true, data: transaction };
    }
    Why This Changes Your Code Quality:
    Exhaustive Type Narrowing: Consumers cannot access result.data without explicitly handling if (!result.success). TypeScript will flag unhandled error conditions at build time.


    Deterministic Control Flow: Exceptions are reserved exclusively for truly unrecoverable anomalies (out-of-memory errors, syntax bugs, database connection drops), while expected business failures remain predictable, first-class values.


    Decoupled API Contracts: Your HTTP controller can deterministically map every domain error code directly to its respective HTTP status code (e.g., 402 Payment Required, 408 Timeout) via a simple, exhaustive switch block.


    Stop treating your failure paths as second-class citizens. If a failure can be predicted, it belongs in the return type.


    Discussion Question
    In your current backend codebase, do you handle domain-level failures via custom thrown exception hierarchies or explicit Result / Either types—and what was the tipping point for your team?


    CTA
    Join Developers & Coding: Connect with senior software engineers, backend developers, and systems architects refining clean code patterns, type safety, and scalable architectures inside the Techawks Developers community. Link in bio/comments.
    Stop Leaking Unchecked Exceptions: How to Build Bulletproof APIs with the Result Pattern in TypeScript Throwing exceptions for expected domain failures (e.g., validation errors, expired sessions, or resource conflicts) violates one of software engineering's most fundamental tenets: type safety across execution boundaries. When a function signatures looks like this: TypeScript async function processOrder(orderId: string): Promise<Order> The TypeScript compiler has no idea what could go wrong. It forces consumers to guess what exceptions need catching, resulting in swallowed errors, missing fallback states, and unexpected 500 HTTP crashes. The Architectural Shift: Explicit Error Modeling Languages like Rust make failure paths explicit at the type level using the Result<T, E> algebraic data type. You can implement this cleanly in modern TypeScript without external dependencies using discriminated unions: TypeScript type Result<T, E = Error> = | { success: true; data: T } | { success: false; error: E }; // Define discrete, exhaustive error states type PaymentError = | { code: 'INSUFFICIENT_FUNDS'; balance: number } | { code: 'CARD_EXPIRED' } | { code: 'GATEWAY_TIMEOUT' }; async function chargeCard(amount: number): Promise<Result<Transaction, PaymentError>> { if (amount > availableFunds) { return { success: false, error: { code: 'INSUFFICIENT_FUNDS', balance: availableFunds } }; } // ... execute charge return { success: true, data: transaction }; } Why This Changes Your Code Quality: Exhaustive Type Narrowing: Consumers cannot access result.data without explicitly handling if (!result.success). TypeScript will flag unhandled error conditions at build time. Deterministic Control Flow: Exceptions are reserved exclusively for truly unrecoverable anomalies (out-of-memory errors, syntax bugs, database connection drops), while expected business failures remain predictable, first-class values. Decoupled API Contracts: Your HTTP controller can deterministically map every domain error code directly to its respective HTTP status code (e.g., 402 Payment Required, 408 Timeout) via a simple, exhaustive switch block. Stop treating your failure paths as second-class citizens. If a failure can be predicted, it belongs in the return type. Discussion Question In your current backend codebase, do you handle domain-level failures via custom thrown exception hierarchies or explicit Result / Either types—and what was the tipping point for your team? CTA Join Developers & Coding: Connect with senior software engineers, backend developers, and systems architects refining clean code patterns, type safety, and scalable architectures inside the Techawks Developers community. Link in bio/comments.
    0 Commentaires 0 Parts 10 Vue 0 Aperçu
  • Stop Brute-Forcing Context: Why Speculative Decoding & KV-Cache Partitioning Are Replacing Massive Prompt Stuffing
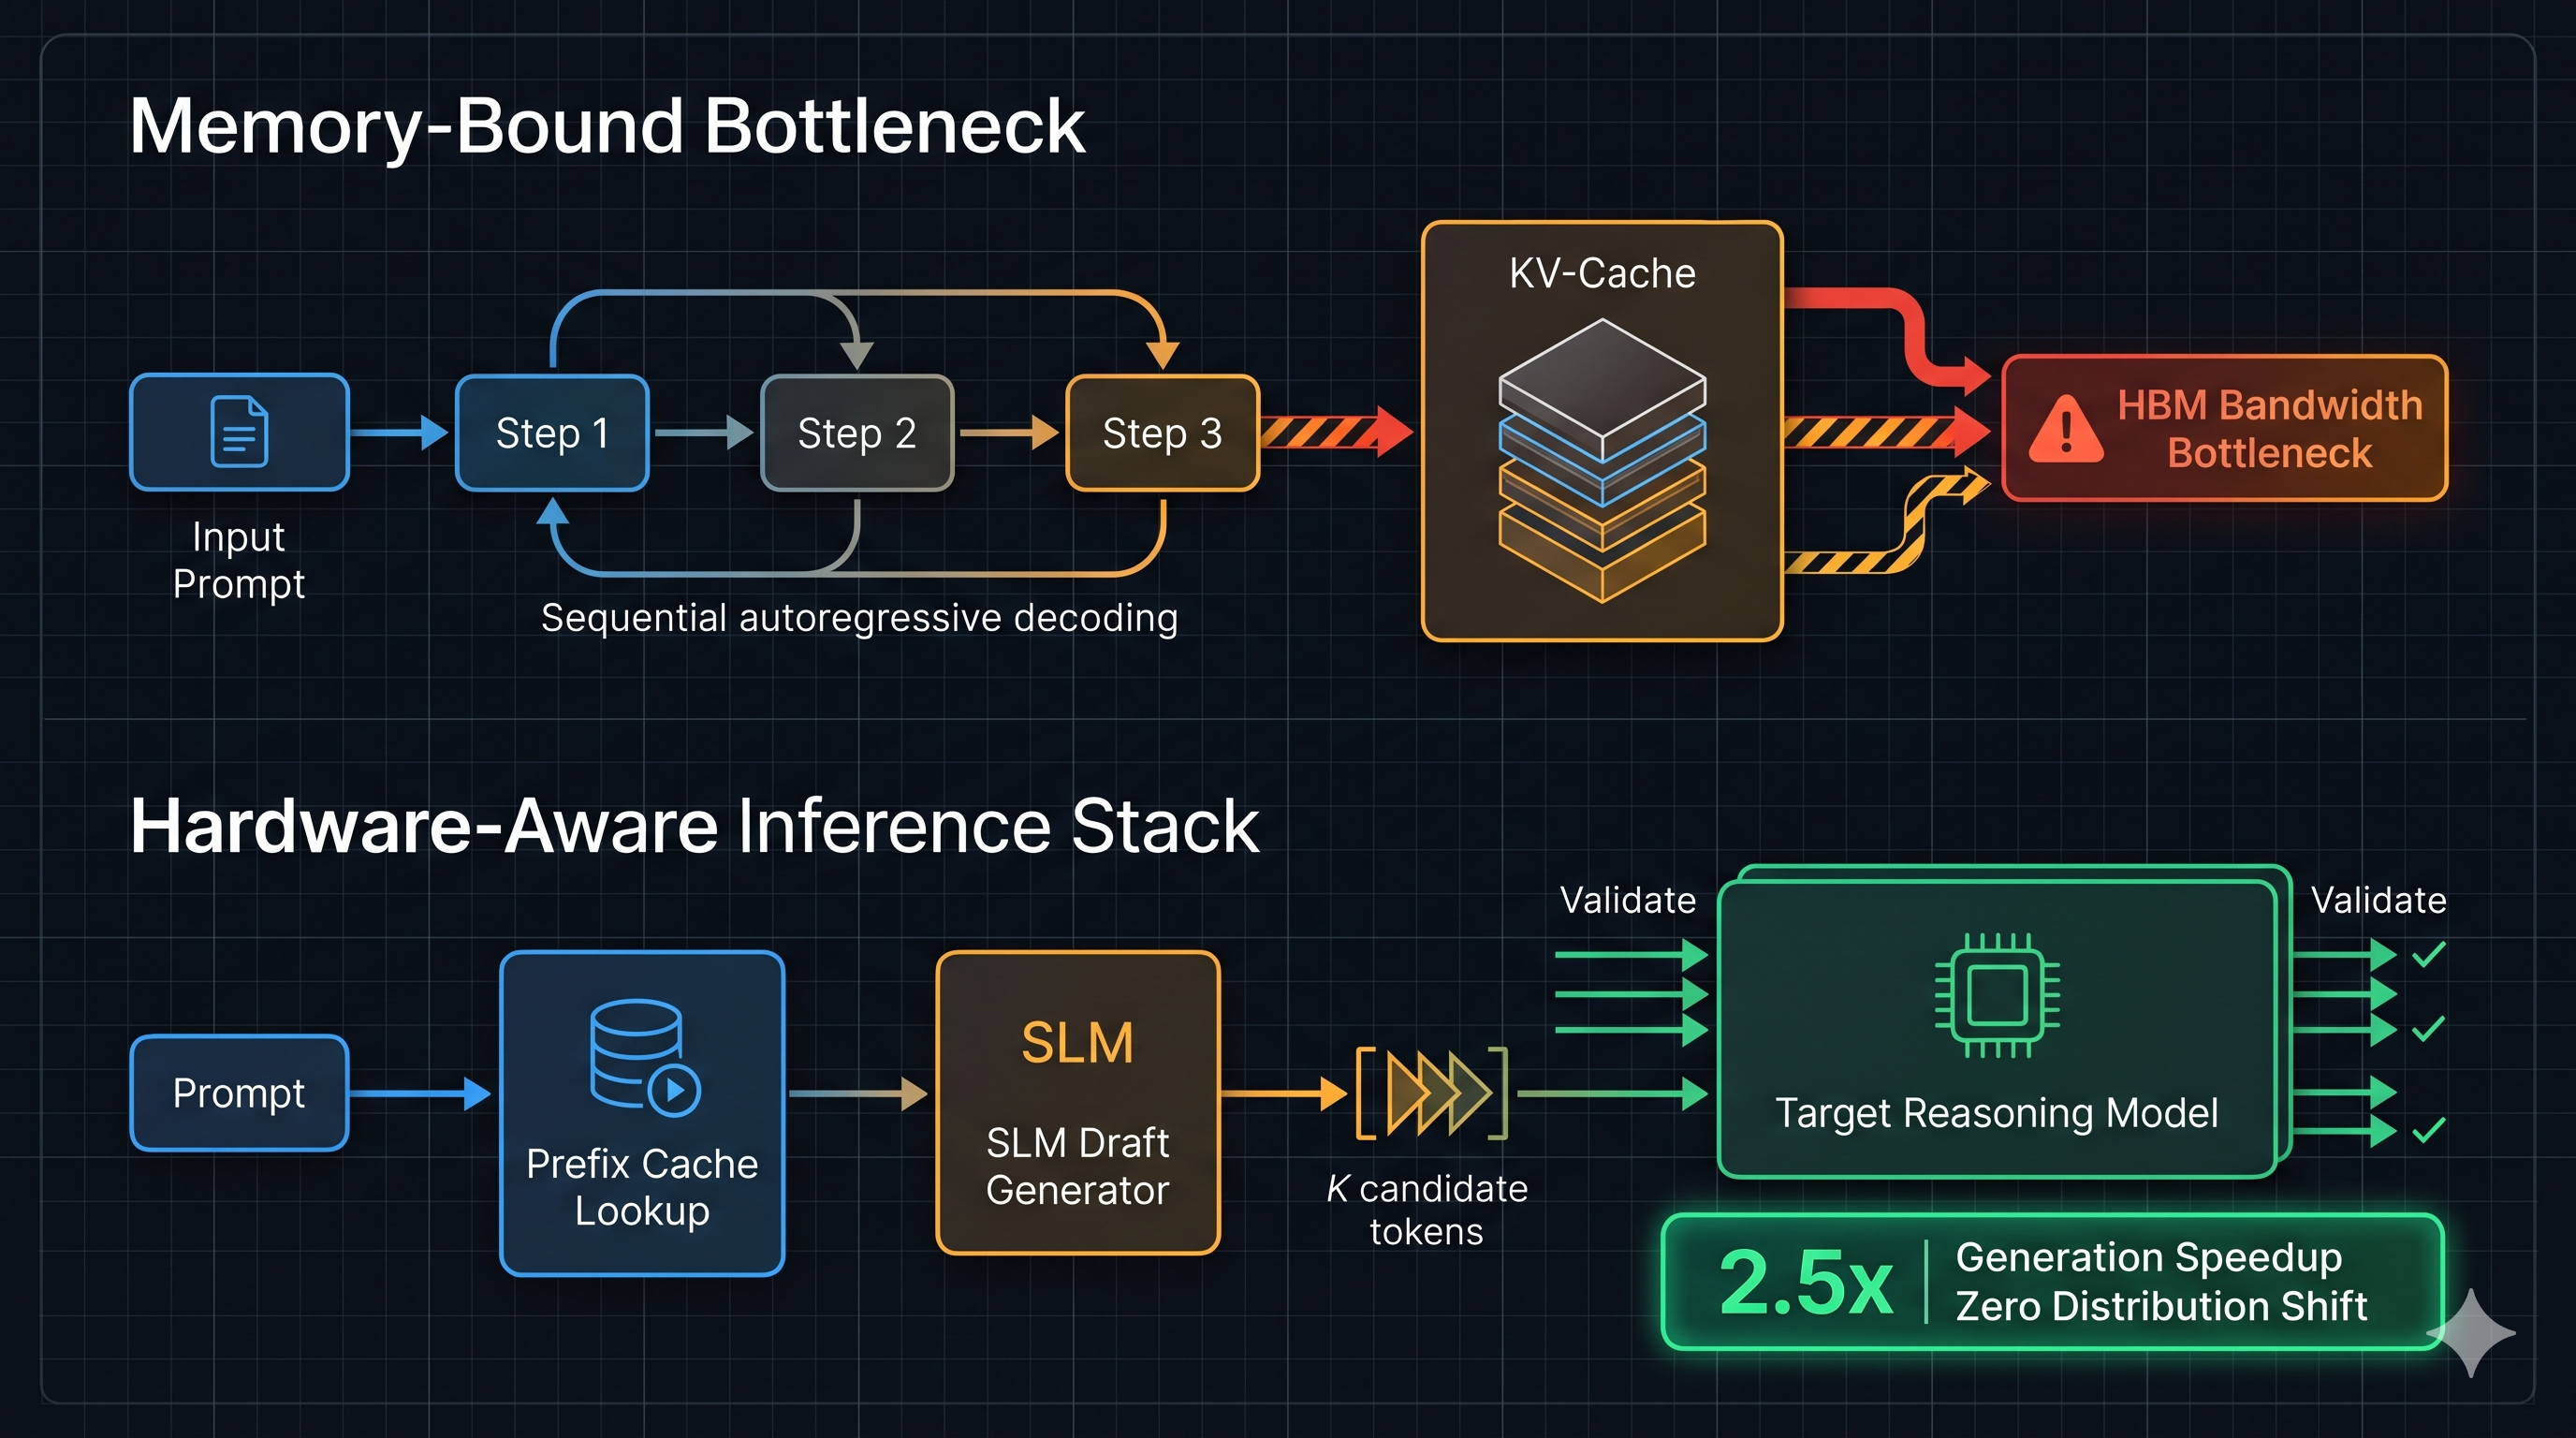
    As frontier reasoning models and agent pipelines scale, the primary production bottleneck is no longer raw FLOPs—it is the memory bus.
    Every autoregressive token generated requires loading hundreds of billions of weights and reading an ever-expanding Key-Value (KV) cache from High Bandwidth Memory (HBM). When your context window balloons, GPU memory throughput stalls out, driving Time-To-First-Token (TTFT) and per-token generation latency into unacceptable SLA territory.
    Building enterprise-grade AI applications requires transitioning from naive prompting to hardware-aware inference engineering:1. Speculative Decoding (Draft-Verify Architecture)Instead of forcing a 70B+ target model to sequentially compute predictable syntax, punctuation, and structural boilerplate, deploy a lightweight colocated draft model (e.g., 3B–7B).The small model drafts $K$ candidate tokens in parallel.
    The large target model evaluates all $K$ tokens in a single forward pass.
    Verified tokens are accepted; rejected tokens branch back without quality loss.
    The payoff: High acceptance rates ($\alpha > 80\%$) in structured JSON generation, code synthesis, and retrieval-augmented workflows—effectively doubling generation speed without changing output distributions.2. Tiered KV-Cache Management & Prefix CachingDynamic agent loops often re-send identical system instructions, schema toolsets, and few-shot exemplars across multi-turn conversations.
    Prefix Caching: Hash common system prefixes so downstream turns read pre-computed KV tensors directly from GPU cache rather than recomputing prompt attention.
    Cache Eviction Strategies: Ditch sliding windows. Implement attention-guided retention (pruning tokens with historically low cumulative attention weights) to cap HBM usage on long-running worker loops.3. Shift from Retrieval "Dumping" to Structured Context HydrationDo not treat the context window as a bottomless database. Route routine structural checks through edge small language models (SLMs) and feed the central reasoning engine only validated, high-signal state diffs.
    Optimizing your system boundaries yields bigger performance and cost dividends than simply upgrading your base model tier.
    Discussion Question
    For teams running high-throughput production LLM pipelines: have you benchmarked Speculative Decoding or dynamic KV-cache eviction against native continuous batching, and what acceptance rate ($\alpha$) threshold justified the added orchestrator complexity in your stack?
    CTA
    Join AI Builders & Enthusiasts: Dive deep into low-latency inference patterns, LLM system architecture, and production deployment designs with fellow engineers inside the Techawks AI community. Link in bio/comments.
    Stop Brute-Forcing Context: Why Speculative Decoding & KV-Cache Partitioning Are Replacing Massive Prompt Stuffing As frontier reasoning models and agent pipelines scale, the primary production bottleneck is no longer raw FLOPs—it is the memory bus. Every autoregressive token generated requires loading hundreds of billions of weights and reading an ever-expanding Key-Value (KV) cache from High Bandwidth Memory (HBM). When your context window balloons, GPU memory throughput stalls out, driving Time-To-First-Token (TTFT) and per-token generation latency into unacceptable SLA territory. Building enterprise-grade AI applications requires transitioning from naive prompting to hardware-aware inference engineering:1. Speculative Decoding (Draft-Verify Architecture)Instead of forcing a 70B+ target model to sequentially compute predictable syntax, punctuation, and structural boilerplate, deploy a lightweight colocated draft model (e.g., 3B–7B).The small model drafts $K$ candidate tokens in parallel. The large target model evaluates all $K$ tokens in a single forward pass. Verified tokens are accepted; rejected tokens branch back without quality loss. The payoff: High acceptance rates ($\alpha > 80\%$) in structured JSON generation, code synthesis, and retrieval-augmented workflows—effectively doubling generation speed without changing output distributions.2. Tiered KV-Cache Management & Prefix CachingDynamic agent loops often re-send identical system instructions, schema toolsets, and few-shot exemplars across multi-turn conversations. Prefix Caching: Hash common system prefixes so downstream turns read pre-computed KV tensors directly from GPU cache rather than recomputing prompt attention. Cache Eviction Strategies: Ditch sliding windows. Implement attention-guided retention (pruning tokens with historically low cumulative attention weights) to cap HBM usage on long-running worker loops.3. Shift from Retrieval "Dumping" to Structured Context HydrationDo not treat the context window as a bottomless database. Route routine structural checks through edge small language models (SLMs) and feed the central reasoning engine only validated, high-signal state diffs. Optimizing your system boundaries yields bigger performance and cost dividends than simply upgrading your base model tier. Discussion Question For teams running high-throughput production LLM pipelines: have you benchmarked Speculative Decoding or dynamic KV-cache eviction against native continuous batching, and what acceptance rate ($\alpha$) threshold justified the added orchestrator complexity in your stack? CTA Join AI Builders & Enthusiasts: Dive deep into low-latency inference patterns, LLM system architecture, and production deployment designs with fellow engineers inside the Techawks AI community. Link in bio/comments.
    0 Commentaires 0 Parts 11 Vue 0 Aperçu
  • The Agentic Reality Check: Why 40% of Autonomous AI Deployments Fail Before Scaling
    Industry data indicates that while over 38% of enterprise engineering teams are running AI agent pilots, barely 11% have successfully transitioned them into production. Gartner projects that nearly 40% of agentic workflows will fail before 2027.


    The failure is not LLM reasoning quality; it is software system architecture.


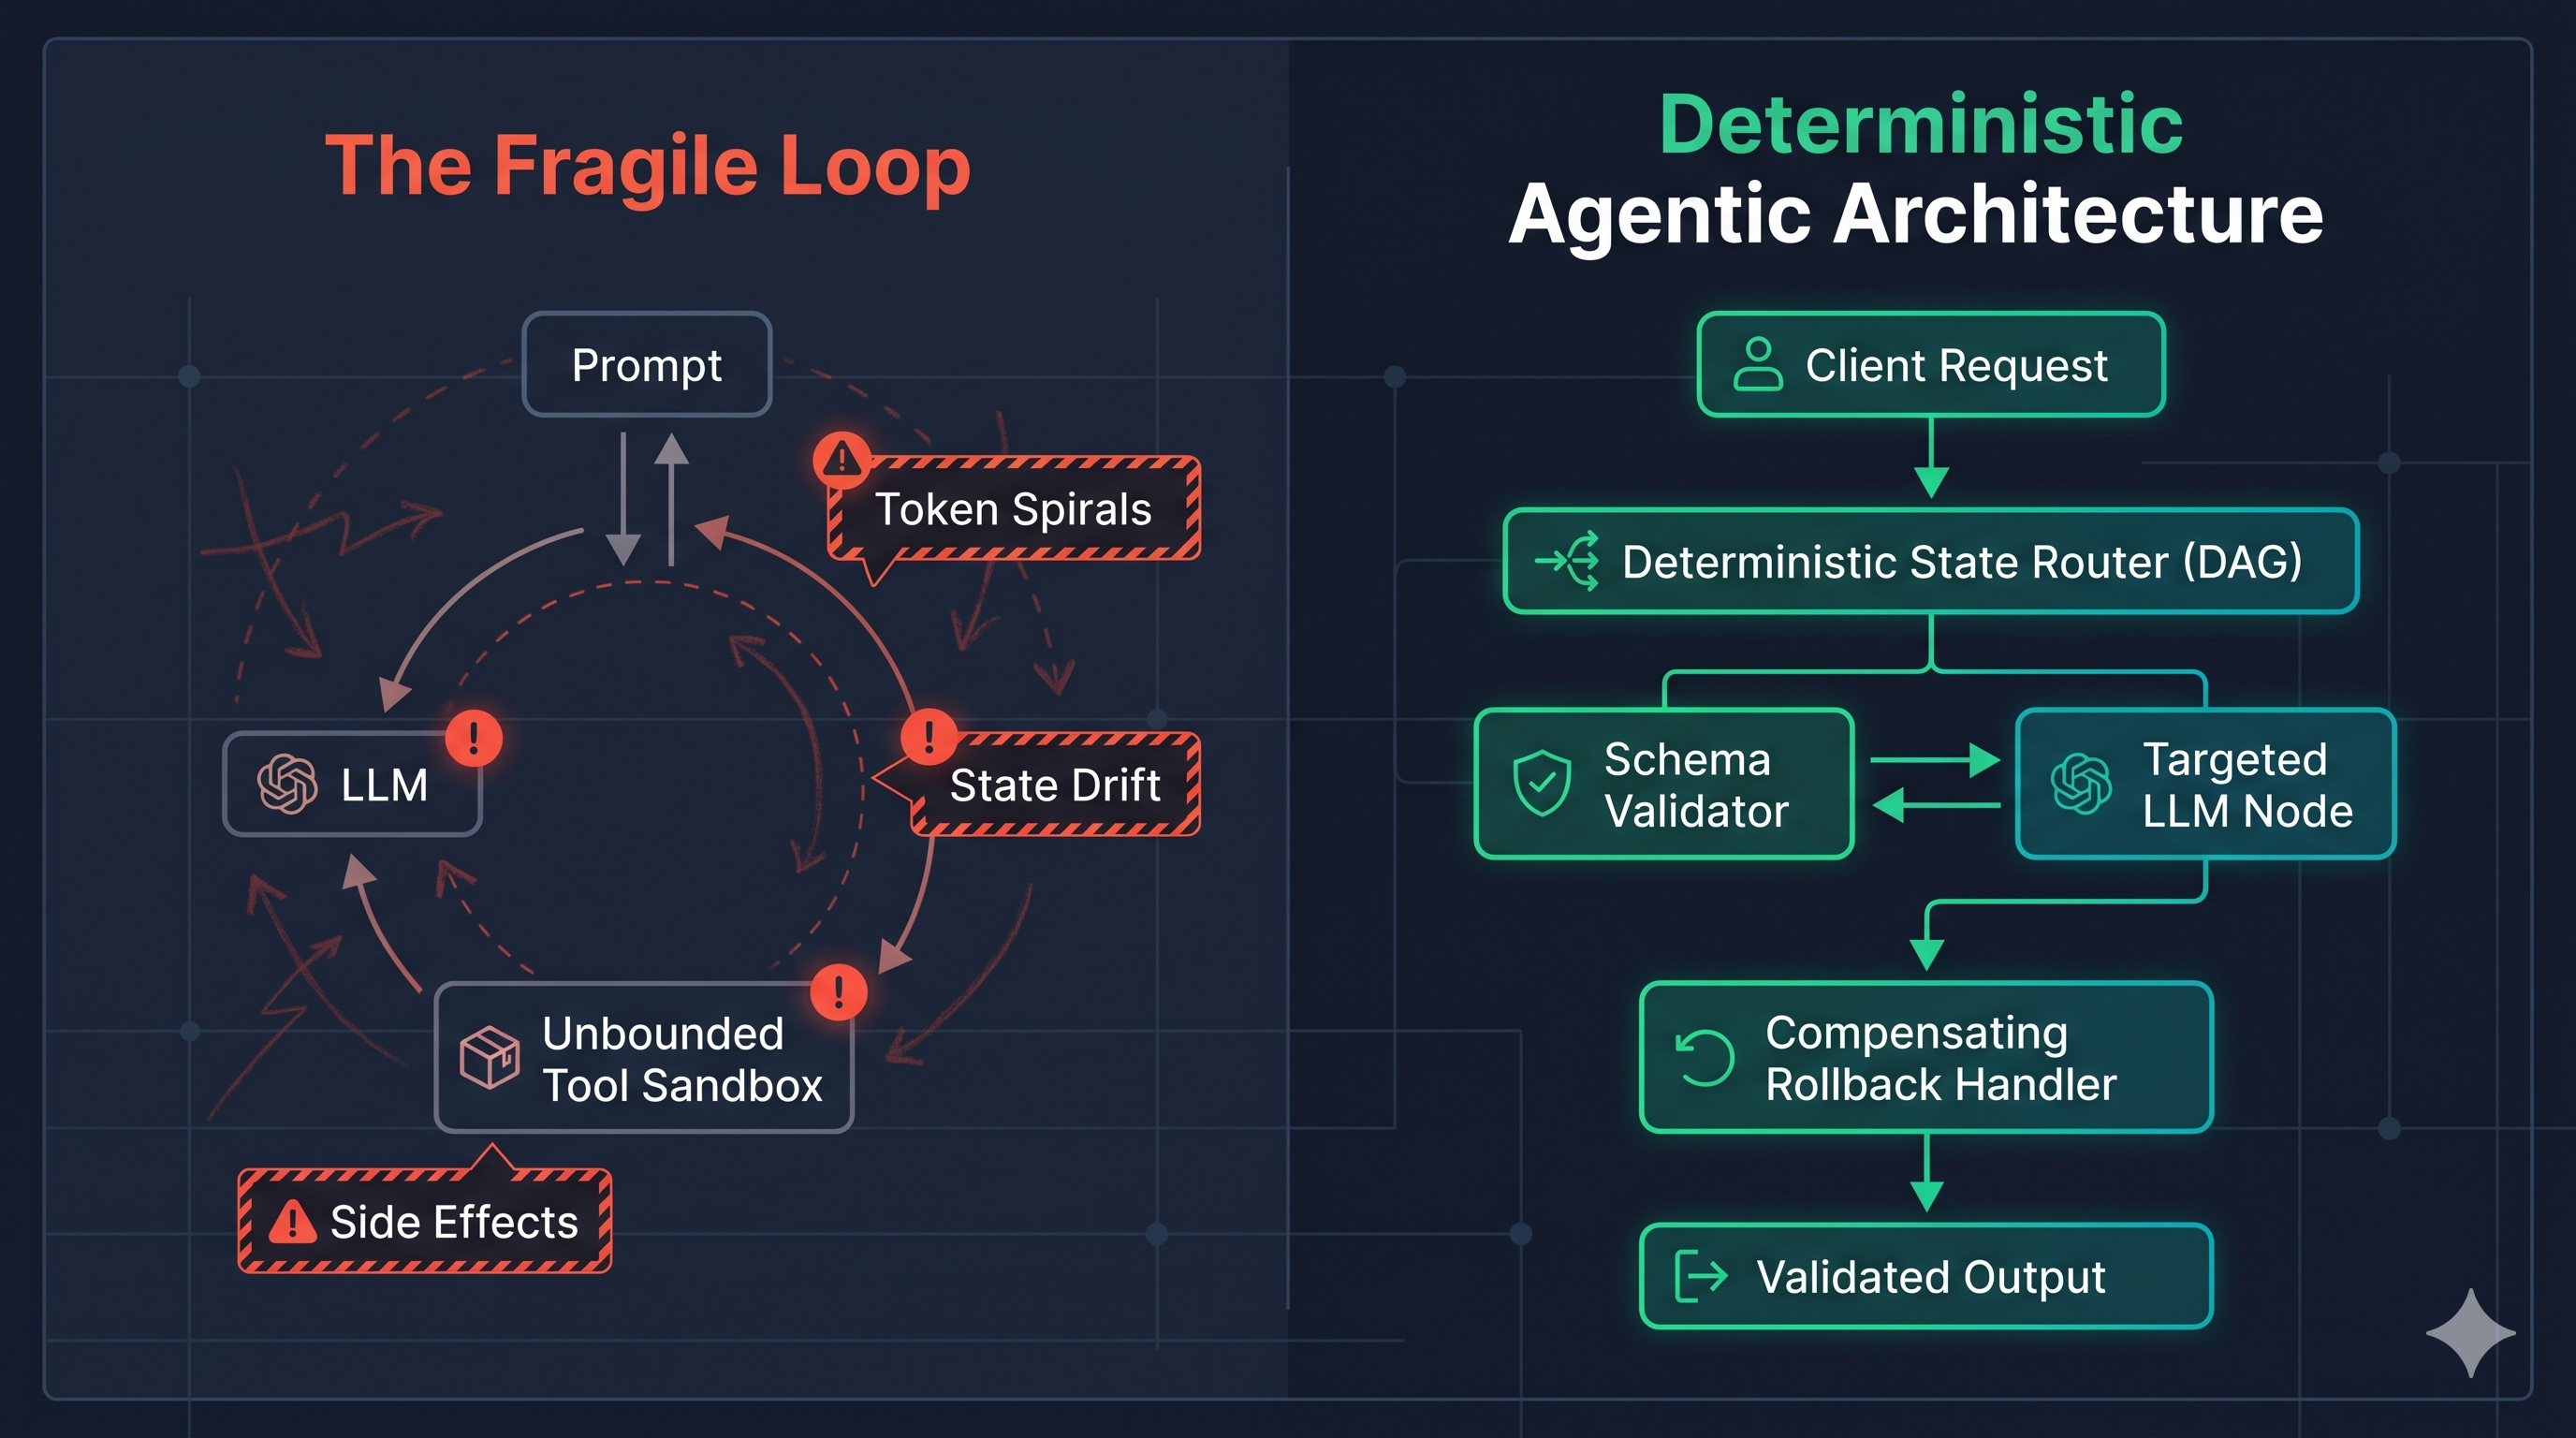
    Most teams assemble agents around an uncontrolled loop:Input -> LLM Call -> Tool Execution -> Loop until solved


    In a toy environment, this looks magical. In enterprise production, this naive pattern triggers three fatal failure modes:


    Compounding Non-Determinism: If an individual step has a 90% success probability, a 6-step recursive chain yields barely a 53% chance of reaching the desired terminal state without hallucinating parameters or misfiring APIs.


    Infinite Token Leaks: Without bounded state machines, edge-case network timeouts or malformed tool outputs force agents into self-correcting retry spirals that drain compute budgets.


    Missing Telemetry & Rollback States: If an agent executes a destructive downstream API call (e.g., database mutation, payment trigger) mid-chain, standard retry loops cannot cleanly roll back partial writes.


    The Architectural Fix: Directed Acyclic Graphs (DAGs) + Deterministic State Gates
    Production-grade agentic design requires treating the LLM as an untrusted computation engine within a deterministic orchestrator, rather than an autonomous decision-maker:


    Explicit State Hydration: Never maintain persistent unbounded chat histories. Pass only structured schema payloads (JSON-enforced) between explicit state nodes.


    Deterministic Guardrails: Every tool invocation must validate schemas both before execution (preventing malformed parameters) and after execution (verifying the returned output matches expected contracts before handing control back to the model).


    Compensating Transactions (Sagas): Model long-running agent workflows as distributed sagas. If Node 4 fails validation after 2 retries, trigger deterministic rollback handlers rather than allowing the model to hallucinate workarounds.


    If you are automating a broken, brittle manual process with autonomous agency, you don't get automation—you get automated technical debt. Redesign your system boundaries first.


    Discussion Question
    When deploying multi-step autonomous agents in your stack, where do you draw the line between deterministic rules (code/DAGs) and dynamic model autonomy?


    CTA
    Join Techawks General Community: Connect with system architects, DevOps leads, and backend engineers discussing resilient architectures and real-world system designs. Link in bio/comments.
    The Agentic Reality Check: Why 40% of Autonomous AI Deployments Fail Before Scaling Industry data indicates that while over 38% of enterprise engineering teams are running AI agent pilots, barely 11% have successfully transitioned them into production. Gartner projects that nearly 40% of agentic workflows will fail before 2027. The failure is not LLM reasoning quality; it is software system architecture. Most teams assemble agents around an uncontrolled loop:Input -> LLM Call -> Tool Execution -> Loop until solved In a toy environment, this looks magical. In enterprise production, this naive pattern triggers three fatal failure modes: Compounding Non-Determinism: If an individual step has a 90% success probability, a 6-step recursive chain yields barely a 53% chance of reaching the desired terminal state without hallucinating parameters or misfiring APIs. Infinite Token Leaks: Without bounded state machines, edge-case network timeouts or malformed tool outputs force agents into self-correcting retry spirals that drain compute budgets. Missing Telemetry & Rollback States: If an agent executes a destructive downstream API call (e.g., database mutation, payment trigger) mid-chain, standard retry loops cannot cleanly roll back partial writes. The Architectural Fix: Directed Acyclic Graphs (DAGs) + Deterministic State Gates Production-grade agentic design requires treating the LLM as an untrusted computation engine within a deterministic orchestrator, rather than an autonomous decision-maker: Explicit State Hydration: Never maintain persistent unbounded chat histories. Pass only structured schema payloads (JSON-enforced) between explicit state nodes. Deterministic Guardrails: Every tool invocation must validate schemas both before execution (preventing malformed parameters) and after execution (verifying the returned output matches expected contracts before handing control back to the model). Compensating Transactions (Sagas): Model long-running agent workflows as distributed sagas. If Node 4 fails validation after 2 retries, trigger deterministic rollback handlers rather than allowing the model to hallucinate workarounds. If you are automating a broken, brittle manual process with autonomous agency, you don't get automation—you get automated technical debt. Redesign your system boundaries first. Discussion Question When deploying multi-step autonomous agents in your stack, where do you draw the line between deterministic rules (code/DAGs) and dynamic model autonomy? CTA Join Techawks General Community: Connect with system architects, DevOps leads, and backend engineers discussing resilient architectures and real-world system designs. Link in bio/comments.
    0 Commentaires 0 Parts 9 Vue 0 Aperçu
  • Beyond Cross-Border Latency: How Canadian Engineering Teams Must Architect Sovereign Data Boundaries and Failover Under PIPEDA and OSFI E-21
    Across the Canadian enterprise tech landscape—from financial hubs in Toronto to AI clusters in Montreal and Vancouver—engineering teams routinely manage hybrid cloud footprints.


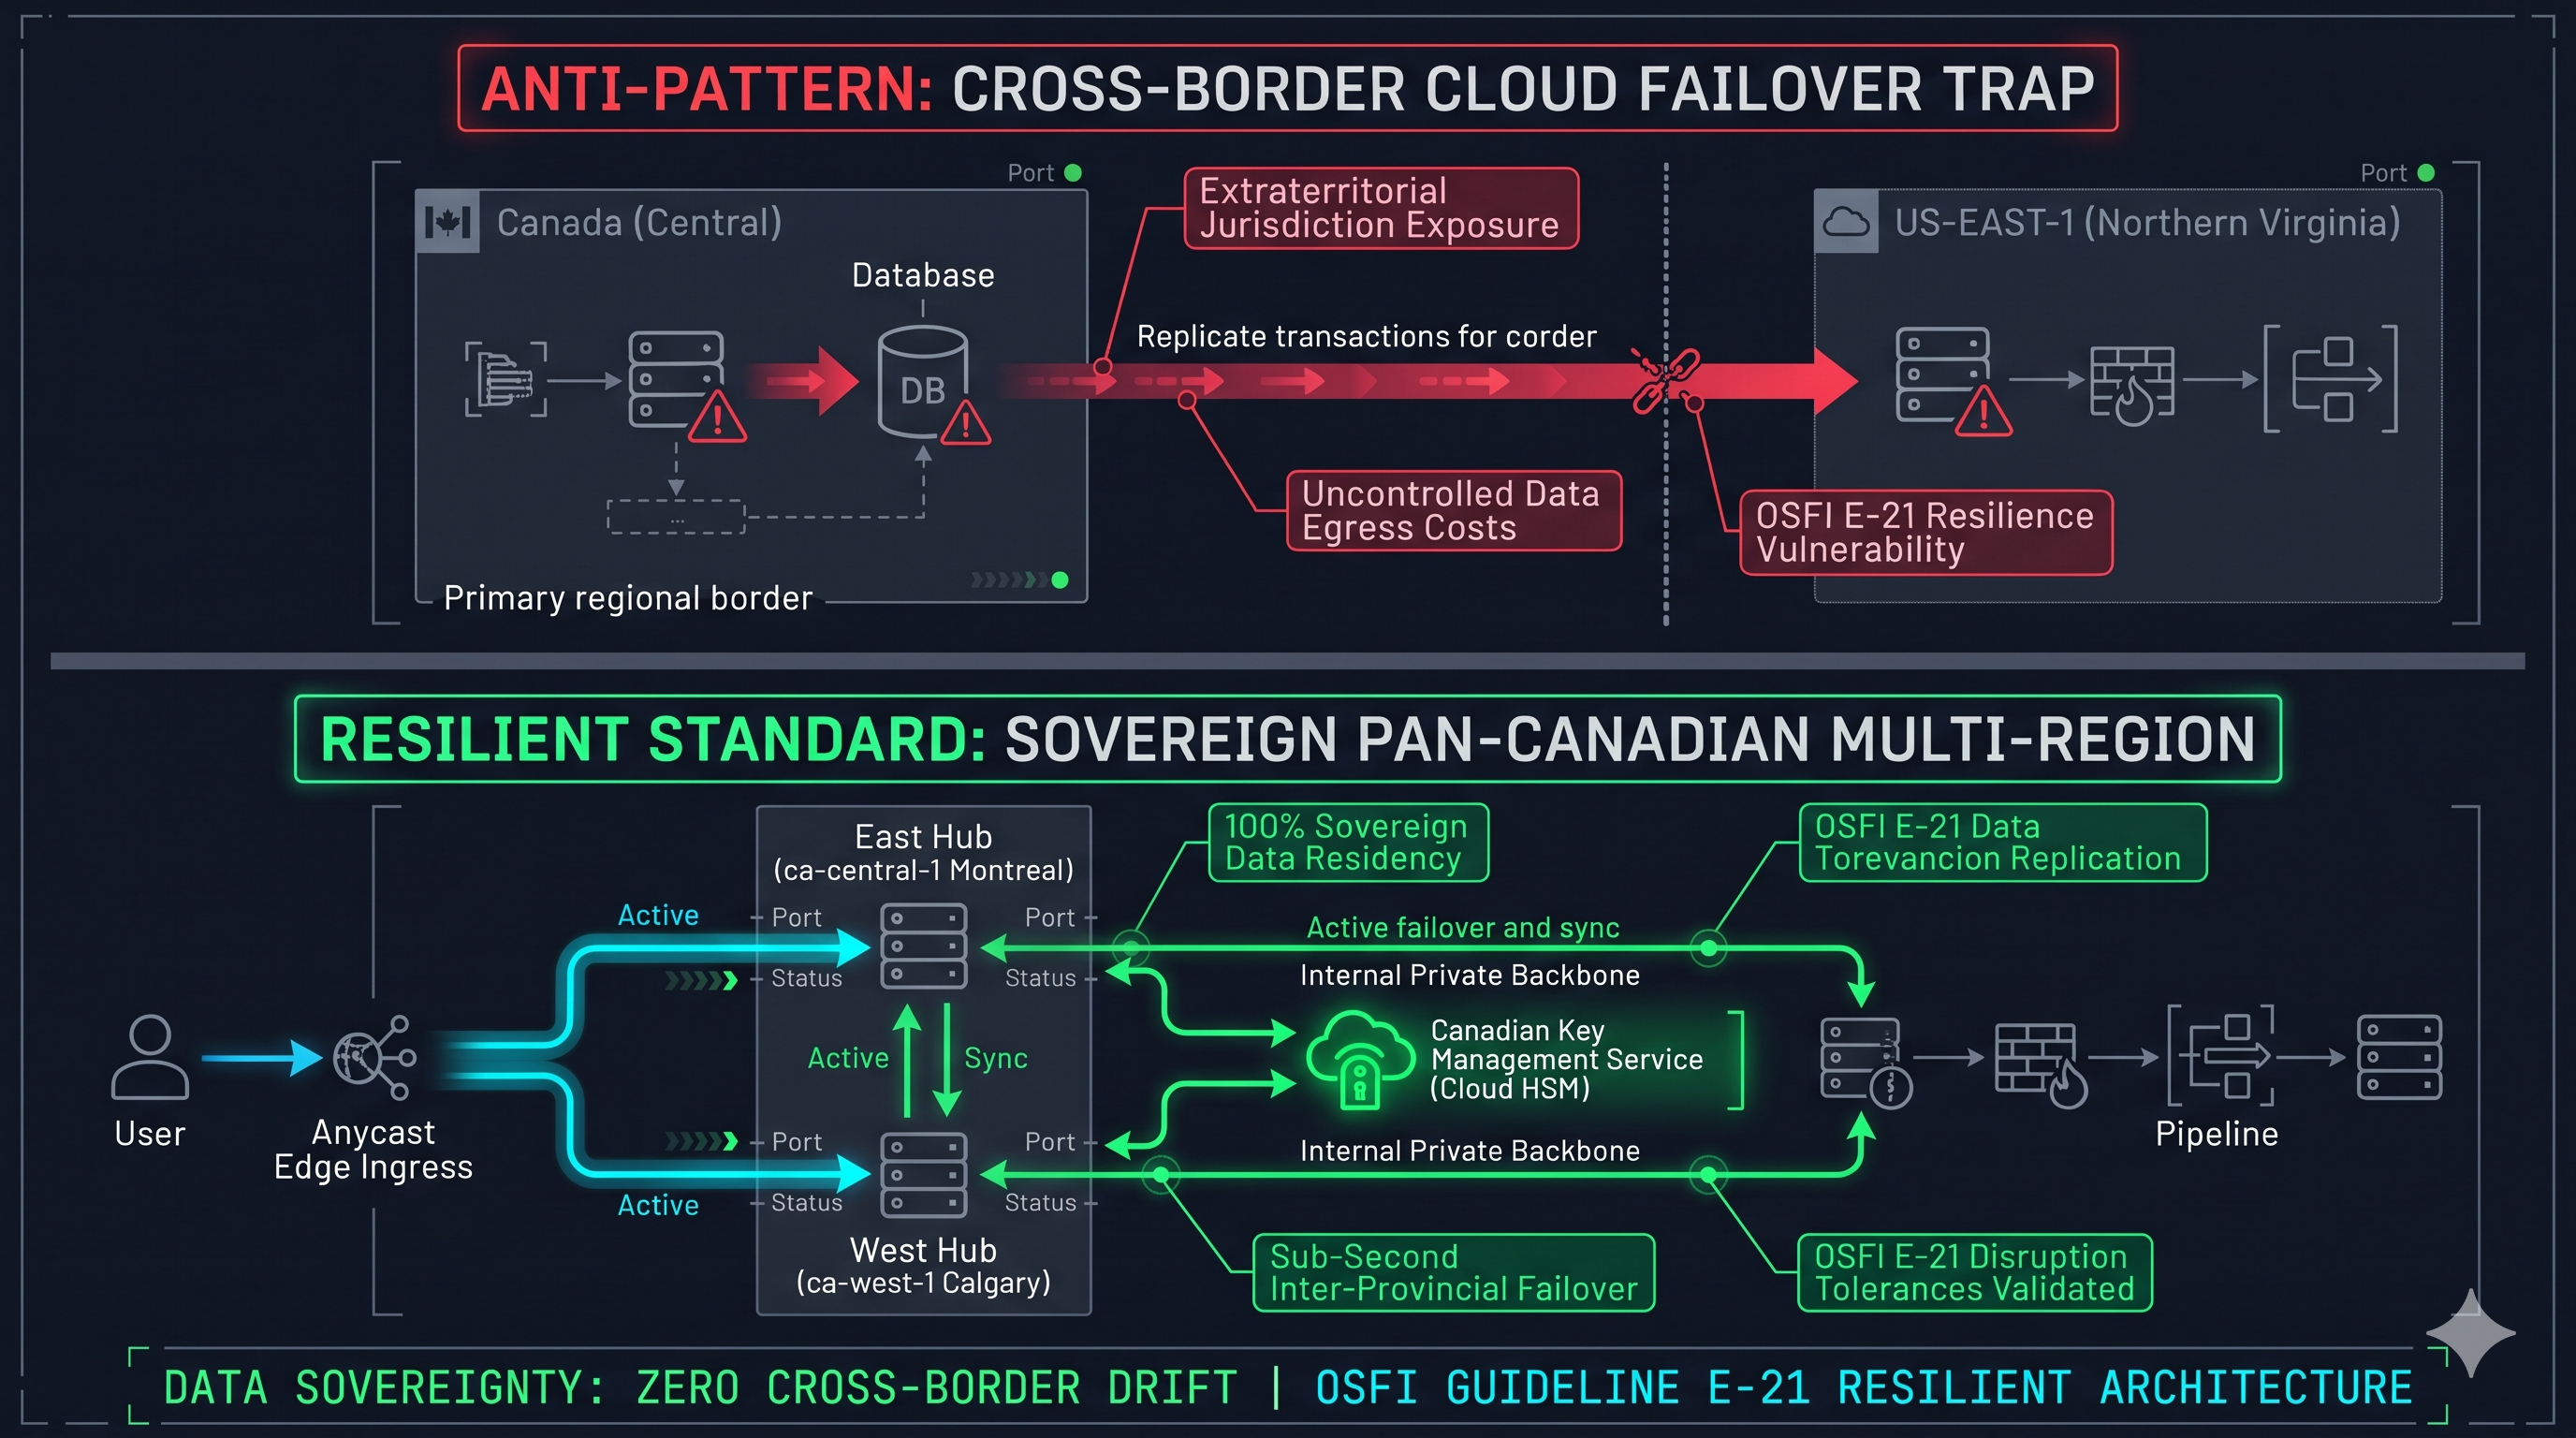
    A recurring anti-pattern is Cross-Border Multi-Region Coupling: hosting primary workloads in ca-central-1 (Central Canada) while configuring disaster recovery (DR) or asynchronous pipeline failovers into US availability zones (such as us-east-1).


    Under the Office of the Superintendent of Financial Institutions (OSFI Guideline E-21 on Operational Resilience) and federal privacy frameworks (PIPEDA / Quebec Law 25), this architecture introduces severe compliance and operational blind spots:


    Extraterritorial Jurisdiction Exposure: Replicating unencrypted or transient customer payloads across the border exposes Canadian user data to foreign legal discovery requests without explicit customer disclosure.


    Fragile Cross-Border Network Partitions: Routing active-passive database failover through international WAN trunks creates latency spikes and synchronization bottlenecks during severe transit disruptions.


    [❌ The Anti-Pattern: Cross-Border Cloud Failover Trap]
    Canadian User ──> Primary Ingress (ca-central-1: Montreal)
    │ (Cross-Border Replication Trunk)
    ▼
    Secondary DR (us-east-1: Virginia)
    Result: Foreign regulatory discovery exposure; cross-border WAN egress fees; E-21 resilience breach.


    [✅ The Sovereign Pan-Canadian Dual-Region Architecture]
    Canadian User ──> Anycast Edge Ingress (Canadian POPs)
    │
    ┌───────────────┴───────────────┐
    ▼ ▼
    [Primary Zone: ca-central-1] [Secondary Zone: ca-west-1]
    (Eastern Canada: Montreal) (Western Canada: Calgary)
    │ │
    └───────────────┬───────────────┘
    ▼
    [Envelope-Encrypted KMS: Sovereign Canadian HSM (AES-256)]
    [Automated OSFI E-21 Disruption Tolerance Telemetry Engine]
    To engineer resilient, sovereign cloud architectures in Canada, implement this 3-tier production pattern:


    1. Architect Inter-Provincial Sovereign Geo-Redundancy
    Stop relying on US border regions for disaster recovery.


    Establish dual-region topologies anchored entirely within domestic borders by pairing Eastern Canadian regions (ca-central-1 / Montreal) with Western Canadian regions (ca-west-1 / Calgary).


    Enforce VPC Service Endpoints and private interconnection backbones (Direct Connect / ExpressRoute) to ensure replication traffic never traverses public transit routes or international exchange points.


    2. Enforce Customer-Managed Keys (CMK) via In-Country Hardware Security Modules
    To satisfy statutory accountability principles under PIPEDA and Quebec Law 25:


    Isolate all cryptographic root keys within sovereign, dedicated Cloud HSMs provisioned exclusively within Canadian borders.


    3. Instrument Continuous Scenario Testing for Critical Operations (OSFI E-21)
    Operational resilience is no longer evaluated through static DR audit checklists:


    Under OSFI E-21, map every Information and Communication Technology (ICT) dependency directly to your organization’s named Critical Operations.


    Define concrete Tolerances for Disruption (e.g., maximum acceptable customer transaction disruption window).


    Run automated chaos injections: simulate the complete partition of trans-Canadian fiber routes and prove that application state fails over between Calgary and Montreal without exceeding your documented impact limits.


    Building modern software in Canada means recognizing that data sovereignty and operational resilience are inseparable architectural requirements.


    Discussion Question
    For Canadian platform teams: have you migrated your disaster recovery configurations to domestic inter-provincial regions (Montreal/Calgary), or does your infrastructure still depend on cross-border US regions for secondary failover?


    CTA
    Join Techawks Canada to discuss cloud infrastructure patterns, Canadian regulatory engineering, and distributed systems architecture with developers and technology leaders nationwide.
    Beyond Cross-Border Latency: How Canadian Engineering Teams Must Architect Sovereign Data Boundaries and Failover Under PIPEDA and OSFI E-21 Across the Canadian enterprise tech landscape—from financial hubs in Toronto to AI clusters in Montreal and Vancouver—engineering teams routinely manage hybrid cloud footprints. A recurring anti-pattern is Cross-Border Multi-Region Coupling: hosting primary workloads in ca-central-1 (Central Canada) while configuring disaster recovery (DR) or asynchronous pipeline failovers into US availability zones (such as us-east-1). Under the Office of the Superintendent of Financial Institutions (OSFI Guideline E-21 on Operational Resilience) and federal privacy frameworks (PIPEDA / Quebec Law 25), this architecture introduces severe compliance and operational blind spots: Extraterritorial Jurisdiction Exposure: Replicating unencrypted or transient customer payloads across the border exposes Canadian user data to foreign legal discovery requests without explicit customer disclosure. Fragile Cross-Border Network Partitions: Routing active-passive database failover through international WAN trunks creates latency spikes and synchronization bottlenecks during severe transit disruptions. [❌ The Anti-Pattern: Cross-Border Cloud Failover Trap] Canadian User ──> Primary Ingress (ca-central-1: Montreal) │ (Cross-Border Replication Trunk) ▼ Secondary DR (us-east-1: Virginia) Result: Foreign regulatory discovery exposure; cross-border WAN egress fees; E-21 resilience breach. [✅ The Sovereign Pan-Canadian Dual-Region Architecture] Canadian User ──> Anycast Edge Ingress (Canadian POPs) │ ┌───────────────┴───────────────┐ ▼ ▼ [Primary Zone: ca-central-1] [Secondary Zone: ca-west-1] (Eastern Canada: Montreal) (Western Canada: Calgary) │ │ └───────────────┬───────────────┘ ▼ [Envelope-Encrypted KMS: Sovereign Canadian HSM (AES-256)] [Automated OSFI E-21 Disruption Tolerance Telemetry Engine] To engineer resilient, sovereign cloud architectures in Canada, implement this 3-tier production pattern: 1. Architect Inter-Provincial Sovereign Geo-Redundancy Stop relying on US border regions for disaster recovery. Establish dual-region topologies anchored entirely within domestic borders by pairing Eastern Canadian regions (ca-central-1 / Montreal) with Western Canadian regions (ca-west-1 / Calgary). Enforce VPC Service Endpoints and private interconnection backbones (Direct Connect / ExpressRoute) to ensure replication traffic never traverses public transit routes or international exchange points. 2. Enforce Customer-Managed Keys (CMK) via In-Country Hardware Security Modules To satisfy statutory accountability principles under PIPEDA and Quebec Law 25: Isolate all cryptographic root keys within sovereign, dedicated Cloud HSMs provisioned exclusively within Canadian borders. 3. Instrument Continuous Scenario Testing for Critical Operations (OSFI E-21) Operational resilience is no longer evaluated through static DR audit checklists: Under OSFI E-21, map every Information and Communication Technology (ICT) dependency directly to your organization’s named Critical Operations. Define concrete Tolerances for Disruption (e.g., maximum acceptable customer transaction disruption window). Run automated chaos injections: simulate the complete partition of trans-Canadian fiber routes and prove that application state fails over between Calgary and Montreal without exceeding your documented impact limits. Building modern software in Canada means recognizing that data sovereignty and operational resilience are inseparable architectural requirements. Discussion Question For Canadian platform teams: have you migrated your disaster recovery configurations to domestic inter-provincial regions (Montreal/Calgary), or does your infrastructure still depend on cross-border US regions for secondary failover? CTA Join Techawks Canada to discuss cloud infrastructure patterns, Canadian regulatory engineering, and distributed systems architecture with developers and technology leaders nationwide.
    0 Commentaires 0 Parts 297 Vue 0 Aperçu
  • Architecting Sovereign AI in the UAE: How to Enforce In-Country Data Residency Across LLM Inference Pipelines
    As the UAE cements its position as a global capital for artificial intelligence, regulatory frameworks—specifically Federal Decree-Law No. 45 of 2021 on Personal Data Protection (PDPL) and the UAE Cyber Security Council National Cloud Security Policy—strictly enforce sovereign data residency and cross-border transfer controls.


    The critical engineering failure in AI adoption is treating foundational models as geographically agnostic APIs.


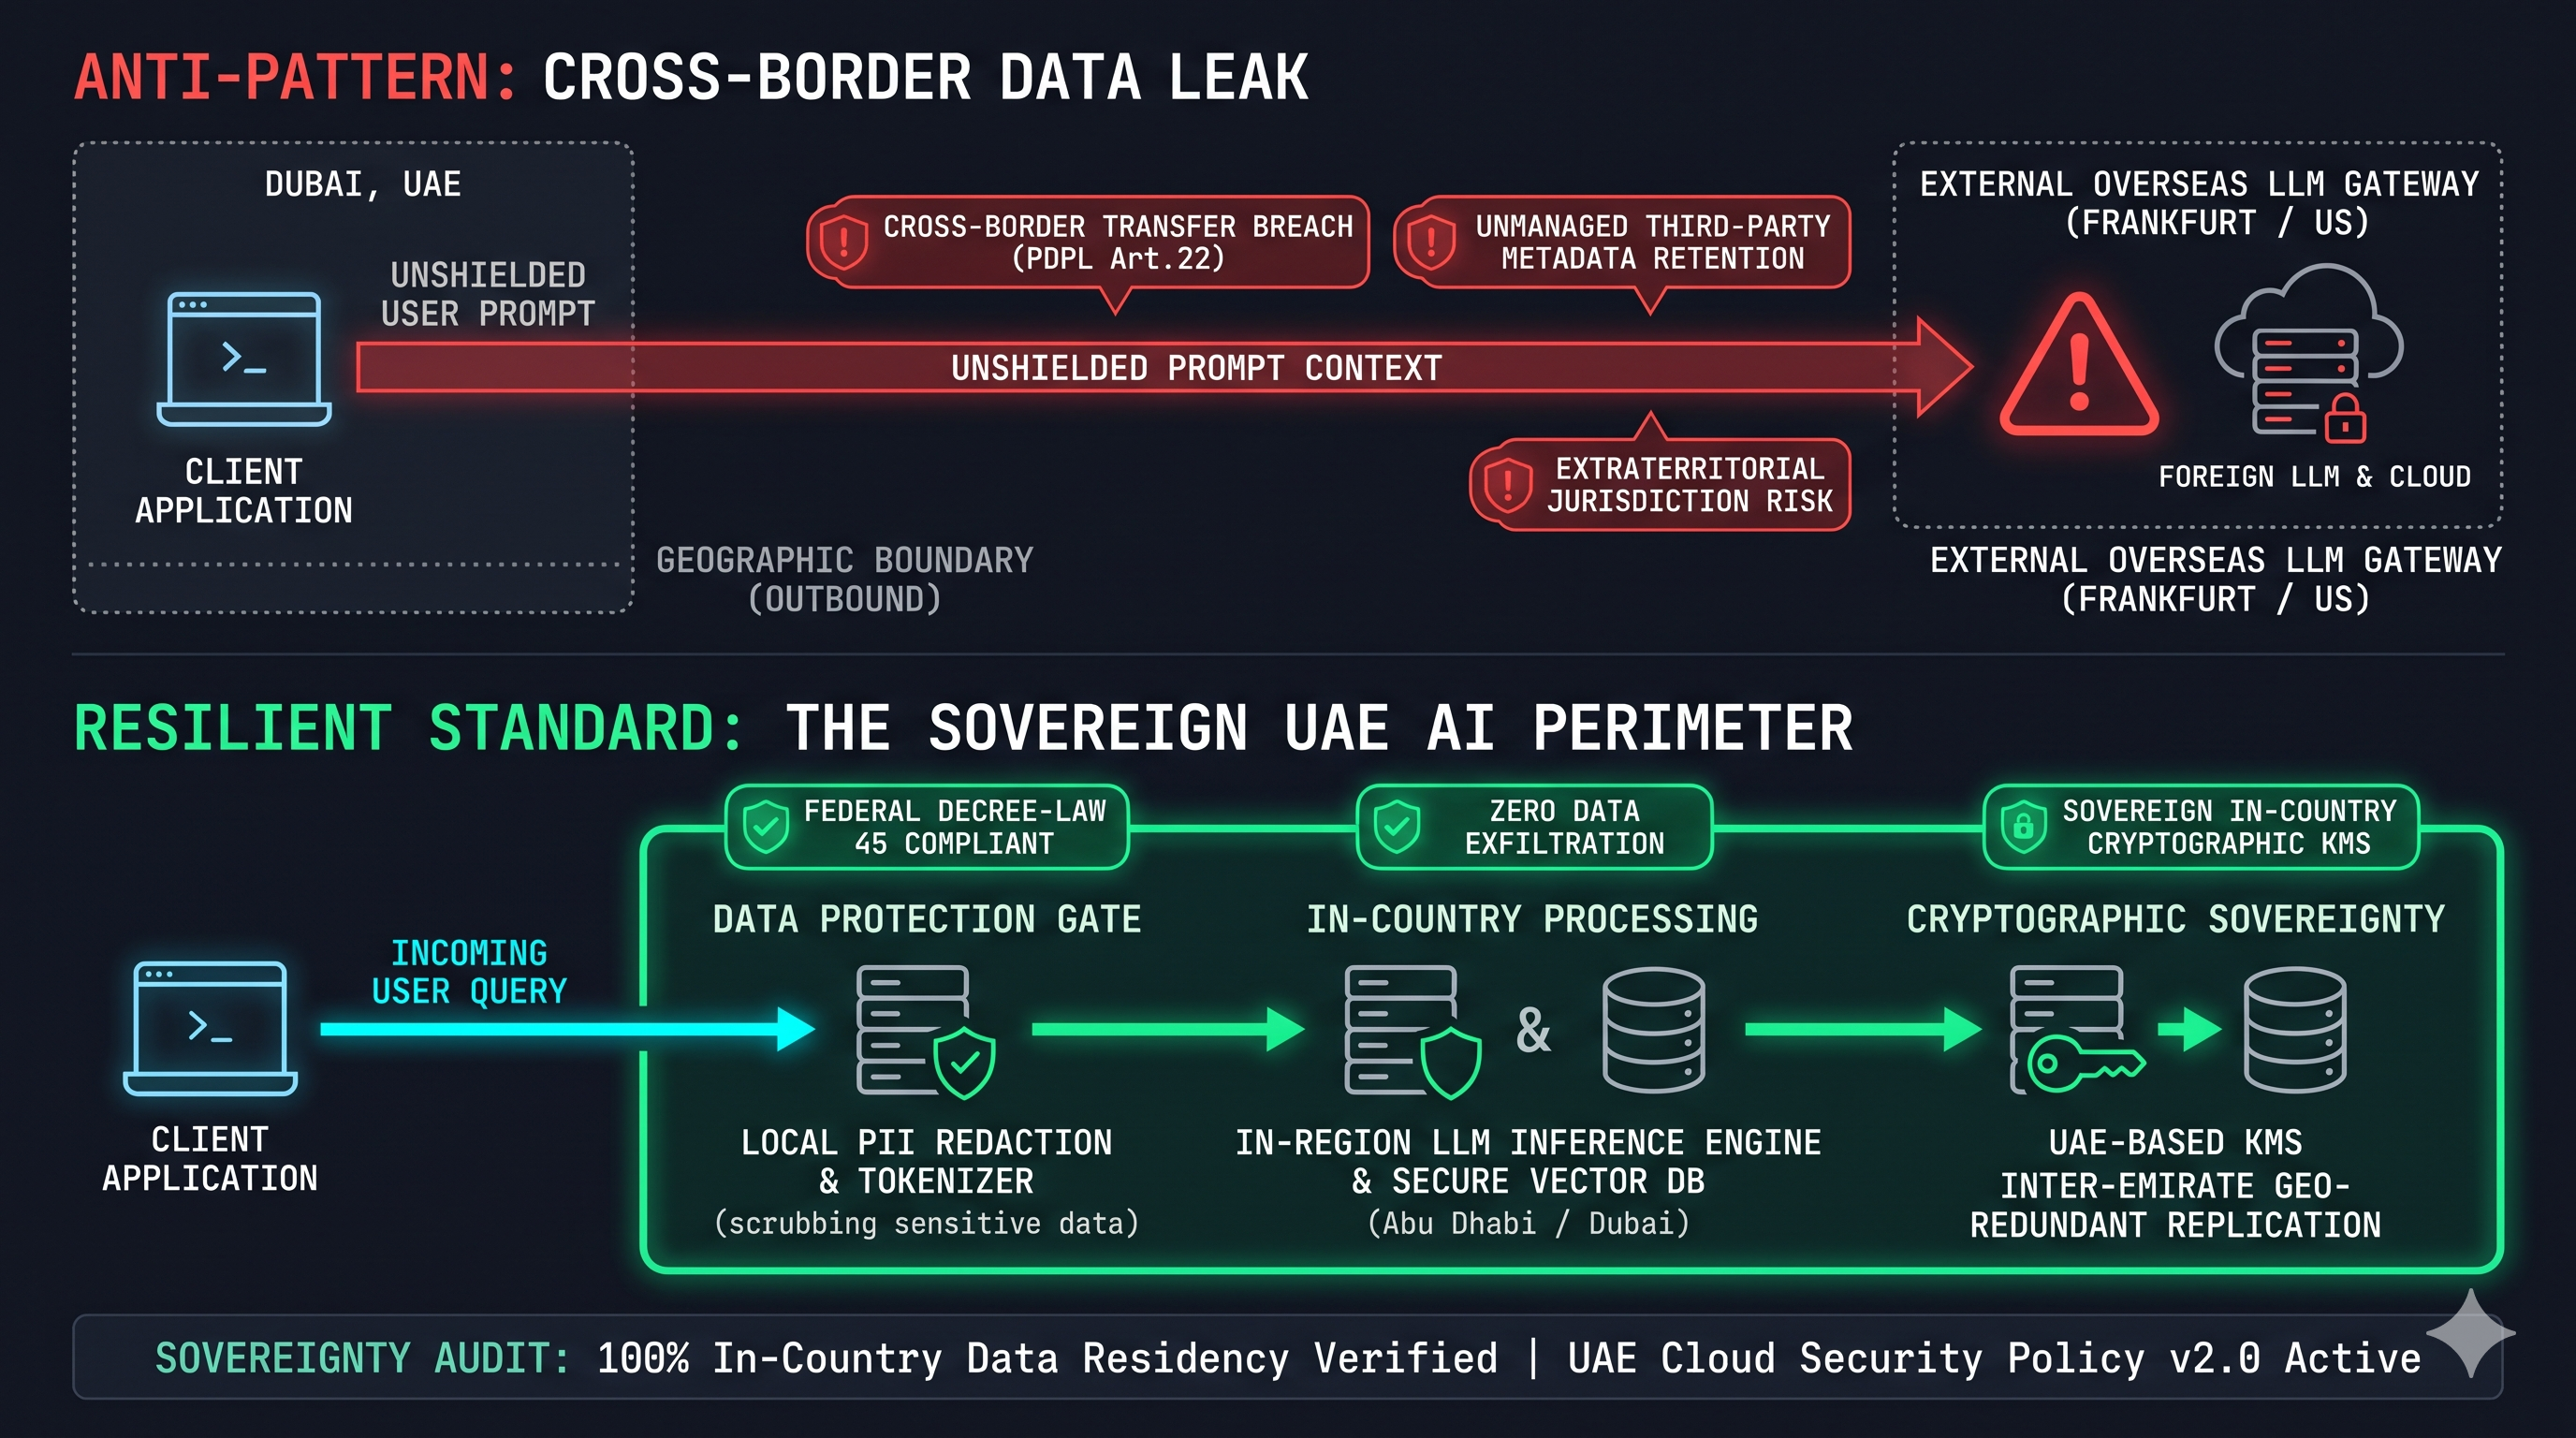
    When building Retrieval-Augmented Generation (RAG) or agentic loops, developers frequently send unstructured user context across international borders for external embedding generation and token completion. In regulated sectors (banking, government entities, critical infrastructure, and healthcare), this architecture breaches statutory compliance and risks heavy regulatory penalties.


    [❌ The Non-Compliant Cross-Border Anti-Pattern]
    UAE Client (Dubai/AD) ──> Web App ──(Unsanitized Prompt)──> External LLM Gateway (Frankfurt/US)
    │
    (Exfiltrates PII & Metadata)
    ▼
    Result: Direct violation of UAE PDPL Art. 22/23 & Sovereign Cloud Policy.


    [✅ The Sovereign UAE In-Country AI Architecture]
    UAE Client ──> In-Country API Gateway (Dubai / Abu Dhabi Cloud Region)
    │
    ▼
    [PII Redaction & Tokenization Guardrail]
    │
    ┌─────────────┴─────────────┐
    ▼ ▼
    [In-Country Vector DB] [Locally Hosted / Sovereign LLM]
    (AES-256 with UAE KMS) (In-Region Inference: UAE VPC)
    │ │
    └─────────────┬─────────────┘
    ▼
    [Encrypted In-Country Storage & Inter-Emirate Replica]
    To build compliant, enterprise-grade AI systems in the UAE, implement this 3-tier sovereign architecture:


    1. Pin Model Inference and Storage to Domestic Cloud Infrastructure
    Under the National Cloud Security Policy and PDPL, data and associated consumer metadata must remain under domestic UAE jurisdiction.


    Deploy model weights and vector indexes strictly within domestic cloud regions (e.g., UAE hyperscaler availability zones in Dubai and Abu Dhabi or sovereign infrastructure partners).


    Ensure all disaster recovery replication is configured as Inter-Emirate Geo-Redundancy (e.g., primary cluster in Dubai with hot/warm standby in Abu Dhabi), avoiding failovers that silently replicate customer databases outside sovereign borders.


    2. Implement Client-Side PII Masking and Deterministic Redaction
    Before any user input reaches downstream reasoning pipelines, route payloads through an automated preprocessing guardrail:


    Detect and tokenize sensitive national identifiers (Emirates ID numbers, passport strings, biometric tokens, contact records) using regex patterns and local named-entity recognition (NER) models.


    Replace sensitive fields with synthetic surrogate tokens (<EID_TOKEN_UUID>), maintaining an encrypted local vault to map variables back on the response path.


    3. Enforce In-Country Key Management (KMS Bring Your Own Key)
    Cloud security standards mandate that foreign entities cannot be compelled to expose data via extraterritorial access requests.


    Encrypt all persistent data at rest (database volumes, prompt logs, Parquet historical stores) using AES-256 with Customer-Managed Keys (CMK) managed inside UAE-resident Hardware Security Modules (HSMs).


    Enforce strict IAM policies ensuring encryption keys never leave UAE borders and foreign cloud operators cannot decrypt stored context payloads.


    Achieving enterprise AI scale in the UAE requires pairing frontier reasoning capabilities with strict sovereign isolation, ensuring your infrastructure is fully compliant with federal data protection laws.


    Discussion Question
    How is your engineering team solving the trade-off between accessing bleeding-edge frontier models and maintaining strict in-country data residency for regulated UAE workloads?


    CTA
    Join Techawks UAE to explore sovereign cloud engineering, regional AI architectures, and enterprise compliance patterns with builders and technology leaders across the UAE.
    Architecting Sovereign AI in the UAE: How to Enforce In-Country Data Residency Across LLM Inference Pipelines As the UAE cements its position as a global capital for artificial intelligence, regulatory frameworks—specifically Federal Decree-Law No. 45 of 2021 on Personal Data Protection (PDPL) and the UAE Cyber Security Council National Cloud Security Policy—strictly enforce sovereign data residency and cross-border transfer controls. The critical engineering failure in AI adoption is treating foundational models as geographically agnostic APIs. When building Retrieval-Augmented Generation (RAG) or agentic loops, developers frequently send unstructured user context across international borders for external embedding generation and token completion. In regulated sectors (banking, government entities, critical infrastructure, and healthcare), this architecture breaches statutory compliance and risks heavy regulatory penalties. [❌ The Non-Compliant Cross-Border Anti-Pattern] UAE Client (Dubai/AD) ──> Web App ──(Unsanitized Prompt)──> External LLM Gateway (Frankfurt/US) │ (Exfiltrates PII & Metadata) ▼ Result: Direct violation of UAE PDPL Art. 22/23 & Sovereign Cloud Policy. [✅ The Sovereign UAE In-Country AI Architecture] UAE Client ──> In-Country API Gateway (Dubai / Abu Dhabi Cloud Region) │ ▼ [PII Redaction & Tokenization Guardrail] │ ┌─────────────┴─────────────┐ ▼ ▼ [In-Country Vector DB] [Locally Hosted / Sovereign LLM] (AES-256 with UAE KMS) (In-Region Inference: UAE VPC) │ │ └─────────────┬─────────────┘ ▼ [Encrypted In-Country Storage & Inter-Emirate Replica] To build compliant, enterprise-grade AI systems in the UAE, implement this 3-tier sovereign architecture: 1. Pin Model Inference and Storage to Domestic Cloud Infrastructure Under the National Cloud Security Policy and PDPL, data and associated consumer metadata must remain under domestic UAE jurisdiction. Deploy model weights and vector indexes strictly within domestic cloud regions (e.g., UAE hyperscaler availability zones in Dubai and Abu Dhabi or sovereign infrastructure partners). Ensure all disaster recovery replication is configured as Inter-Emirate Geo-Redundancy (e.g., primary cluster in Dubai with hot/warm standby in Abu Dhabi), avoiding failovers that silently replicate customer databases outside sovereign borders. 2. Implement Client-Side PII Masking and Deterministic Redaction Before any user input reaches downstream reasoning pipelines, route payloads through an automated preprocessing guardrail: Detect and tokenize sensitive national identifiers (Emirates ID numbers, passport strings, biometric tokens, contact records) using regex patterns and local named-entity recognition (NER) models. Replace sensitive fields with synthetic surrogate tokens (<EID_TOKEN_UUID>), maintaining an encrypted local vault to map variables back on the response path. 3. Enforce In-Country Key Management (KMS Bring Your Own Key) Cloud security standards mandate that foreign entities cannot be compelled to expose data via extraterritorial access requests. Encrypt all persistent data at rest (database volumes, prompt logs, Parquet historical stores) using AES-256 with Customer-Managed Keys (CMK) managed inside UAE-resident Hardware Security Modules (HSMs). Enforce strict IAM policies ensuring encryption keys never leave UAE borders and foreign cloud operators cannot decrypt stored context payloads. Achieving enterprise AI scale in the UAE requires pairing frontier reasoning capabilities with strict sovereign isolation, ensuring your infrastructure is fully compliant with federal data protection laws. Discussion Question How is your engineering team solving the trade-off between accessing bleeding-edge frontier models and maintaining strict in-country data residency for regulated UAE workloads? CTA Join Techawks UAE to explore sovereign cloud engineering, regional AI architectures, and enterprise compliance patterns with builders and technology leaders across the UAE.
    0 Commentaires 0 Parts 290 Vue 0 Aperçu
  • Beyond Static Uptime: How UK Engineering Teams Must Architect Impact Tolerances for FCA & PRA Operational Resilience
    Under supervisory oversight across UK financial services and digital infrastructure (governed by the Bank of England, PRA, and FCA operational resilience supervisory regimes), engineering teams are audited not on theoretical uptime, but on whether critical services can remain within strict Impact Tolerances during severe, plausible disruptions.


    Traditional disaster recovery focuses on infrastructure-level Recovery Point Objective (RPO) and Recovery Time Objective (RTO).


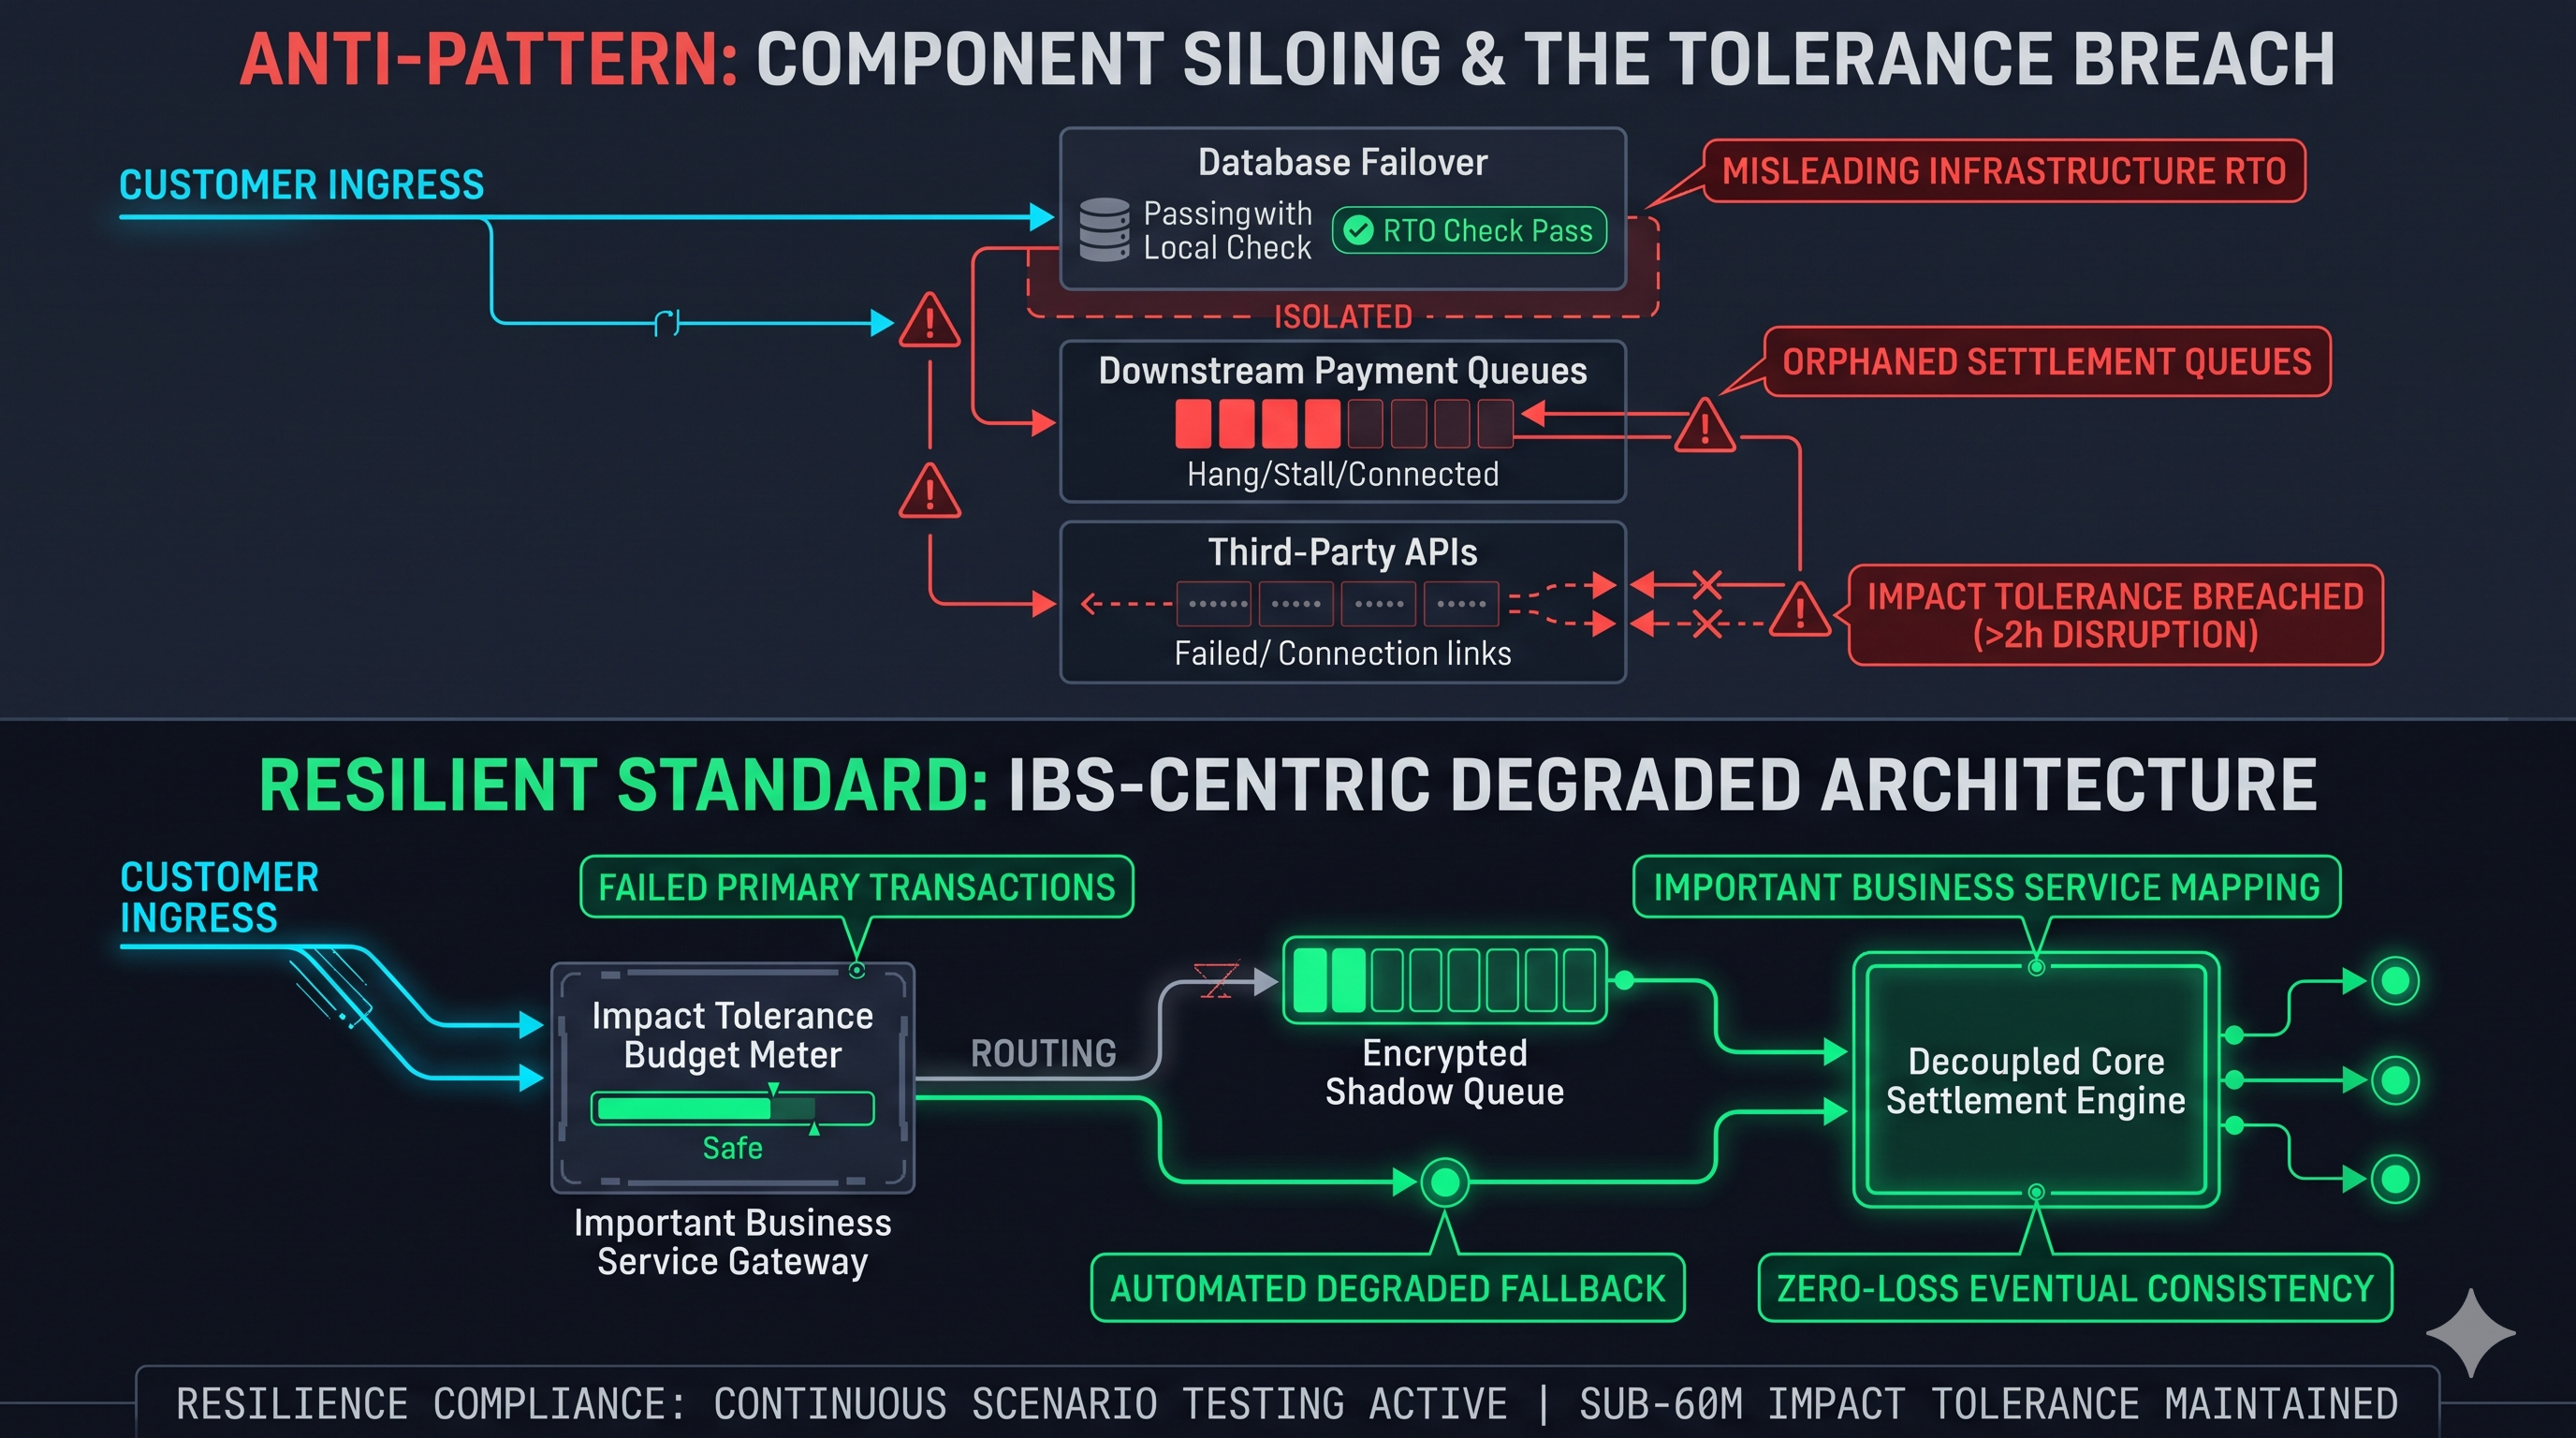
    The systemic flaw in this approach is Component Siloing: an engineering team might restore an Amazon RDS cluster in 15 minutes, but downstream third-party identity providers, clearing house webhooks, and asynchronous reconciliation queues can remain broken for hours, causing intolerable harm to end consumers.


    [❌ The Legacy Disaster Recovery Anti-Pattern: Component Siloing]
    Failure: Primary AWS eu-west-2 Database Outage
    DevOps Action: Restore DB snapshot in isolation (RTO met: 15m).
    Hidden Reality: Payment settlement queue hung; Open Banking API rate-limited; IBS remains down.
    Audit Finding: Impact Tolerance breached (Customer funds locked > 2h).


    [✅ The Production UK Operational Resilience Architecture: IBS Mapping & Circuit Breakers]
    Customer Ingress (Faster Payments / Open Banking)
    │
    ▼
    [IBS Gateway: Active Impact Tolerance Budget Meter]
    │
    ┌───────────────┴───────────────┐
    ▼ ▼
    [Primary Rails (eu-west-2)] [Warm Fallback / Degraded Mode]
    │ (Partition / Lag) │
    ▼ ▼
    [Circuit Breaker Trips] ──> [Deterministic Shadow Ledger (In-Memory)]
    │
    (Syncs within 45m Impact Cap)
    ▼
    [Asynchronous Core Settlement]
    To structure your UK cloud architectures around resilient service delivery rather than component uptime, implement this 3-tier engineering blueprint:


    1. Map Dependencies Directly to Important Business Services (IBS)
    Stop building dependency graphs grouped arbitrarily by microservice repositories.


    Group systems around discrete, customer-facing business outcomes (e.g., "Same-Day Faster Payment Initiation" or "Mortgage Decisioning").


    Tag every supporting asset: infrastructure, data stores, internal microservices, and external third-party SaaS vendors (BaaS providers, identity verification APIs).


    Identify single points of failure (SPOFs) where an unannounced cloud region degradation or upstream vendor rate limit cascades across the entire customer journey.


    2. Implement Automated Degradation Modes with Synthetic Shadow Queues
    When a core clearing switch or database cluster fails, avoid returning generic HTTP 500 errors to customers.


    Configure your edge gateways to trip into a Degraded Execution State the moment latency threatens the defined impact tolerance window (e.g., maximum allowable disruption of 60 minutes).


    Once primary backing services recover, an automated reconciliation worker drains the buffer sequentially with zero data loss.


    3. Transition from Passive DR Drills to Chaos Scenario Testing
    Static runbooks and annual DR PDF reports are dead documents. Supervisory guidelines expect firms to run automated chaos experiments simulating severe but plausible events:


    Simulate the complete sudden loss of an entire UK cloud availability zone alongside a concurrent third-party authentication API outage.


    Validate that your distributed state machines automatically reconcile data without exceeding your end-to-end tolerance threshold.


    Designing for operational resilience in the UK means accepting that individual microservices will experience outages—and engineering decoupled failover pathways that preserve customer outcomes under severe stress.


    Discussion Question
    How does your team define the technical boundary between an acceptable degraded mode and an official impact tolerance breach during third-party dependency outages?


    CTA
    Join Techawks UK to explore resilient systems engineering, cloud architecture patterns, and technical governance strategies with developers and platform leaders across the UK.
    Beyond Static Uptime: How UK Engineering Teams Must Architect Impact Tolerances for FCA & PRA Operational Resilience Under supervisory oversight across UK financial services and digital infrastructure (governed by the Bank of England, PRA, and FCA operational resilience supervisory regimes), engineering teams are audited not on theoretical uptime, but on whether critical services can remain within strict Impact Tolerances during severe, plausible disruptions. Traditional disaster recovery focuses on infrastructure-level Recovery Point Objective (RPO) and Recovery Time Objective (RTO). The systemic flaw in this approach is Component Siloing: an engineering team might restore an Amazon RDS cluster in 15 minutes, but downstream third-party identity providers, clearing house webhooks, and asynchronous reconciliation queues can remain broken for hours, causing intolerable harm to end consumers. [❌ The Legacy Disaster Recovery Anti-Pattern: Component Siloing] Failure: Primary AWS eu-west-2 Database Outage DevOps Action: Restore DB snapshot in isolation (RTO met: 15m). Hidden Reality: Payment settlement queue hung; Open Banking API rate-limited; IBS remains down. Audit Finding: Impact Tolerance breached (Customer funds locked > 2h). [✅ The Production UK Operational Resilience Architecture: IBS Mapping & Circuit Breakers] Customer Ingress (Faster Payments / Open Banking) │ ▼ [IBS Gateway: Active Impact Tolerance Budget Meter] │ ┌───────────────┴───────────────┐ ▼ ▼ [Primary Rails (eu-west-2)] [Warm Fallback / Degraded Mode] │ (Partition / Lag) │ ▼ ▼ [Circuit Breaker Trips] ──> [Deterministic Shadow Ledger (In-Memory)] │ (Syncs within 45m Impact Cap) ▼ [Asynchronous Core Settlement] To structure your UK cloud architectures around resilient service delivery rather than component uptime, implement this 3-tier engineering blueprint: 1. Map Dependencies Directly to Important Business Services (IBS) Stop building dependency graphs grouped arbitrarily by microservice repositories. Group systems around discrete, customer-facing business outcomes (e.g., "Same-Day Faster Payment Initiation" or "Mortgage Decisioning"). Tag every supporting asset: infrastructure, data stores, internal microservices, and external third-party SaaS vendors (BaaS providers, identity verification APIs). Identify single points of failure (SPOFs) where an unannounced cloud region degradation or upstream vendor rate limit cascades across the entire customer journey. 2. Implement Automated Degradation Modes with Synthetic Shadow Queues When a core clearing switch or database cluster fails, avoid returning generic HTTP 500 errors to customers. Configure your edge gateways to trip into a Degraded Execution State the moment latency threatens the defined impact tolerance window (e.g., maximum allowable disruption of 60 minutes). Once primary backing services recover, an automated reconciliation worker drains the buffer sequentially with zero data loss. 3. Transition from Passive DR Drills to Chaos Scenario Testing Static runbooks and annual DR PDF reports are dead documents. Supervisory guidelines expect firms to run automated chaos experiments simulating severe but plausible events: Simulate the complete sudden loss of an entire UK cloud availability zone alongside a concurrent third-party authentication API outage. Validate that your distributed state machines automatically reconcile data without exceeding your end-to-end tolerance threshold. Designing for operational resilience in the UK means accepting that individual microservices will experience outages—and engineering decoupled failover pathways that preserve customer outcomes under severe stress. Discussion Question How does your team define the technical boundary between an acceptable degraded mode and an official impact tolerance breach during third-party dependency outages? CTA Join Techawks UK to explore resilient systems engineering, cloud architecture patterns, and technical governance strategies with developers and platform leaders across the UK.
    0 Commentaires 0 Parts 213 Vue 0 Aperçu
Plus de résultats